This is the full developer documentation for Xberg
# Xberg
> The ultra-fast content intelligence engine. Turn any document, URL, code file, or audio clip into clean, structured data — text, tables, entities, and embeddings — ready to use.
## Why Xberg
[Section titled “Why Xberg”](#why-xberg)
One engine for everything
Feed documents, URLs, code, images, audio, and archives into one API and get clean Markdown, entities, code structure, and embeddings back — no stitching libraries together.
Fastest, most precise — open source
Native-Rust extraction and PDF-to-Markdown, benchmarked against Docling, MinerU, Unstructured, and more on both quality and speed. [See the benchmarks](https://xberg.io/benchmarks).
Any document type — 107 formats
PDFs, Office files, images, email, e-books, and academic papers all come out as clean Markdown or one of five other formats, with no per-format setup.
Text from images and audio, automatically
Scanned pages become searchable text via OCR, and audio and video tracks are transcribed with Whisper — both with confidence scores, language detection, and backend fallback.
Fetch and crawl the web
Point Xberg at an `http(s)` URL and it fetches and extracts the document, or crawls and follows links — Auto, Document, and Crawl modes via the crawlberg engine.
Traverse nested archives
Recursively extract documents from inside `.zip`, `.tar`, `.gz`, and `.7z` archives, guarded by zip-bomb, compression-ratio, and nesting-depth limits.
Structured data without custom prompting
Pull entities and JSON that matches your schema straight from any document, using a local or hosted LLM — no prompt engineering.
Understand code across 371 languages
Extract functions, classes, imports, and symbols from source, then turn any content into embeddings for search and RAG.
Use your language, native performance
Call Xberg from Python, TypeScript, Rust, Go, Java, C#, Ruby, PHP, Elixir, and more — plus a CLI, REST API, MCP server, Docker, and WASM.
[See all features →](/features/)
## Language support
[Section titled “Language support”](#language-support)
| Language | Package | Docs |
| --------------------- | ---------------------------------------------- | ----------------------------------------------- |
| **Python** | `pip install xberg` | [API Reference](/reference/api-python/) |
| **TypeScript / Node** | `npm install @xberg-io/xberg` | [API Reference](/reference/api-typescript/) |
| **WebAssembly** | `npm install @xberg-io/xberg-wasm` | [API Reference](/reference/api-wasm/) |
| **Rust** | `cargo add xberg` | [API Reference](/reference/api-rust/) |
| **Go** | `go get github.com/xberg-io/xberg/packages/go` | [API Reference](/reference/api-go/) |
| **Java / Kotlin JVM** | Maven Central `io.xberg:xberg` | [API Reference](/reference/api-java/) |
| **Kotlin (Android)** | Maven Central `io.xberg:xberg-android` | [API Reference](/reference/api-kotlin-android/) |
| **C#** | `dotnet add package XbergIo.Xberg` | [API Reference](/reference/api-csharp/) |
| **Ruby** | `gem install xberg` | [API Reference](/reference/api-ruby/) |
| **PHP** | `composer require xberg-io/xberg` | [API Reference](/reference/api-php/) |
| **Elixir** | `{:xberg, "~> 1.0"}` | [API Reference](/reference/api-elixir/) |
| **Dart / Flutter** | `dart pub add xberg` | [API Reference](/reference/api-dart/) |
| **Swift** | Swift Package Manager | [API Reference](/reference/api-swift/) |
| **Zig** | `zig fetch --save` from GitHub | [API Reference](/reference/api-zig/) |
| **C (FFI)** | Shared library + header | [API Reference](/reference/api-c/) |
| **CLI** | `brew install xberg-io/tap/xberg` | [CLI Guide](/cli/usage/) |
| **Docker** | `ghcr.io/xberg-io/xberg` | [Docker Guide](/guides/docker/) |
Choosing between TypeScript packages
**`@xberg-io/xberg`** — Native NAPI-RS bindings. Use for Node.js servers and CLI tools. Full feature set at native performance.
**`@xberg-io/xberg-wasm`** — Pure WebAssembly. Use for browsers, Cloudflare Workers, Deno, Bun, and serverless environments (cross-platform, 60–80% of native speed).
## Quick example
[Section titled “Quick example”](#quick-example)
* Python
main.py
```python
from xberg import ExtractInput, extract
output = await extract(ExtractInput(kind="uri", uri="document.pdf"))
print(output.results[0].content)
```
* TypeScript
index.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
});
console.log(output.results[0].content);
```
* Rust
src/main.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
let config = ExtractionConfig::default();
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
println!("{}", output.results[0].content);
```
## Part of Xberg.io
[Section titled “Part of Xberg.io”](#part-of-xbergio)
[Xberg](https://github.com/xberg-io/xberg)Open-source content intelligence for 107 formats, with OCR, transcription, and code intelligence.
[Xberg Pro](https://xberg.io)Self-hosted content intelligence in a single container.
[Xberg Enterprise](https://xberg.io)Distributed content intelligence on Kubernetes with governance and support.
[crawlberg](https://github.com/xberg-io/crawlberg)Web crawling and scraping with HTML→Markdown and headless-Chrome fallback.
[html-to-markdown](https://github.com/xberg-io/html-to-markdown)Fast, lossless HTML→Markdown engine.
[liter-llm](https://github.com/xberg-io/liter-llm)Universal LLM API client with native bindings for 14 languages and 165 providers.
[tree-sitter-language-pack](https://github.com/xberg-io/tree-sitter-language-pack)Tree-sitter grammars and code-intelligence primitives.
[alef](https://github.com/xberg-io/alef)The polyglot binding generator that produces every per-language binding across the 5 polyglot repos.
## Explore the docs
[Section titled “Explore the docs”](#explore-the-docs)
[Get Started](/getting-started/quickstart/)Install Xberg and extract your first document in minutes.
[Guides](/guides/extraction/)Configuration, OCR setup, Docker deployment, plugins, and more.
[Concepts](/concepts/architecture/)Architecture, the extraction pipeline, MIME detection, and the plugin system.
[Reference](/reference/api-python/)Per-language API docs, the configuration schema, type catalogue, and error matrix.
[CLI & Servers](/cli/usage/)The Xberg CLI, REST API server, and MCP server for AI agents.
[Migration](/migration/from-unstructured/)Migrate from Unstructured or other document extraction libraries.
## Getting help
[Section titled “Getting help”](#getting-help)
* **Bugs & feature requests** — [Open an issue on GitHub](https://github.com/xberg-io/xberg/issues)
* **Community chat** — [Join the Discord](https://discord.gg/xt9WY3GnKR)
* **Reddit** — [Join r/xberg](https://www.reddit.com/r/xberg/)
* **Contributing** — [Read the contributor guide](/contributing/)
# Changelog
All notable changes to this project will be documented in this file.
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.0.0/), and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
***
## \[1.1.6] - 2026-09-10
[Section titled “\[1.1.6\] - 2026-09-10”](#116---2026-09-10)
### Fixed
[Section titled “Fixed”](#fixed)
* PDF no longer deletes text a table’s bounding box covers but its grid leaves out. Suppression of text a table already renders was decided on geometry alone, and a reconstructed grid need not span every printed column inside its own bounding box. On a four-column fault-finding grid reconstructed with two columns, every run in the two omitted columns vanished from the document — not in a cell, not in any element, nowhere. A covered run is now suppressed only when the table actually carries its text (GH#1616).
* PDF no longer cuts a numbered heading that wraps onto a second line. The wrap exemption compared the two lines’ right edges, and a wrap’s last line is short by definition, so it could never fire: the heading kept only its first line and the rest of its title was emitted as body text. A heading’s own continuation is now recognised by its left edge, which is the title’s hanging indent rather than the margin body text returns to. Regression in 1.1.5 (GH#1615).
* An extraction that never requested OCR no longer fails when no OCR backend is registered. `ocr-pipeline` can be enabled without any backend — `ocr` implies `ocr-pipeline`, not the reverse — and in that build the automatic scanned-page trigger aborted an ordinary PDF extraction with `OCR backend 'tesseract' not registered`. Automatic triggers now check availability and skip with a warning; an explicit `force_ocr`, `force_ocr_pages`, `ocr_inline_images` or caller-supplied `ocr` config still fails loudly (GH#1610).
* Legacy binary `.ppt` now reports which slide each embedded picture belongs to. Pictures were read from the OLE `Pictures` stream, which stores blips in save order and names no slide, so every extracted image carried no page number and every image node was emitted after the last slide. A slide whose only content is a picture therefore produced nothing at all on its own number and read as a blank slide, and captions or any other data keyed on an image’s page were filed against the end of the deck. The owning slide is now resolved through the drawing that references the blip; a picture no live shape references is still extracted, without a slide (GH#1620).
* Legacy binary `.ppt` no longer extracts deleted slide revisions or presents slides in the wrong order. The format is append-only across saves, so editing a deck leaves superseded copies in the stream; treating every `Slide` container as a slide produced 190 slides for a 96-slide presentation, numbered by byte order. Live slides and their order now come from the persist chain (`Current User` → `UserEditAtom` → `PersistDirectoryAtom`) and the document’s slide list, falling back to the previous behaviour if the chain cannot be read in full. Slide numbers are the page every element and chunk of a deck is cited by, so both defects reached consumers as wrong page numbers (GH#1614).
* PDF de-hyphenation no longer welds a compound whose own hyphen falls on a line break. Two sites decide whether a trailing hyphen survives; only one consulted the lexical evidence, so `long-term`, `cost-effective` and `antigen-presenting` came out as `longterm`, `costeffective` and `antigenpresenting` — tokens that do not exist, and so unreachable by any lexical search. The assembly site now asks the same question the paragraph site already asked, weighing both the static compound list and the witnesses collected from the document itself. A hyphen the wrap genuinely inserted is still removed (GH#1613).
* Legacy binary `.ppt` no longer loses slide titles. PowerPoint keeps a slide’s text in two places, and the extractor read only one: titles held in the document-level outline collection (`SlideListWithText`) landed in the loose-text bucket, which is discarded whenever any slide exists, so they were absent from the output entirely. Outline text is now attributed to its slide by persist order and merged in, skipping any line the slide’s own drawing already carries so a title drawn on the canvas is not duplicated (GH#1612).
* The documented install versions for Java, Kotlin Android, Swift, Zig and the spring-ai integration no longer lag the release. These snippets sit outside `task version:sync`, which covers the generated API-reference badges but not hand-authored install directives, so they had been telling users to install 1.1.3 (GH#1593 covers the same class of staleness in `test_apps`, which is still open).
## \[1.1.5] - 2026-09-10
[Section titled “\[1.1.5\] - 2026-09-10”](#115---2026-09-10)
### Fixed
[Section titled “Fixed”](#fixed-1)
* The Java binding compiles again. A method returning `Option>` — `Registry.sampleBytes` is the only one today — was generated declaring `Optional` while returning a bare `byte[]`, which javac rejects. 1.1.4 therefore published no Java artifact at all, and the spring-ai integration was blocked waiting on it. Fixed upstream in alef 0.85.12; this release regenerates on it.
## \[1.1.4] - 2026-09-09
[Section titled “\[1.1.4\] - 2026-09-09”](#114---2026-09-09)
### Changed
[Section titled “Changed”](#changed)
* **BREAKING (Ruby):** `FormatMetadata` reaches Ruby as a flat hash. It previously arrived as `{format_type:, _0: {...}}`, where `_0` was the name serde invents for an unnamed tuple field; it now arrives as `{format_type: 'excel', sheet_count: 2, ...}`, the canonical wire the core declares. Code reading `metadata.format[:_0][:sheet_count]` must read `metadata.format[:sheet_count]`. This shipped unannounced in 1.1.4 and is recorded here retroactively; no other binding’s shape changed (GH#1594).
### Fixed
[Section titled “Fixed”](#fixed-2)
* PDF reading order no longer tears a subscript off the symbol it names. Spans were ordered by the top of their bounding box, but a subscript is drawn 35-40% smaller than its base, so its top sits several points lower even though its baseline is a fraction of a point away. An unrelated span from the next column could sort between a base run and its own subscript, and the symbol the subscript names no longer existed anywhere in the output. Ordering now quantises the baseline into row bands before comparing horizontally, which is what every other caller of that comparator already did (GH#1600).
* PDF table detection no longer bridges two separate tables across the graphics-free gap between them. A cell was built from intersection points alone, so a section heading printed in that gap was absorbed into one of the tables as a single-cell row. A candidate cell now also requires a drawn vertical rule spanning its own Y-range on both sides. The span tolerance is load-bearing: at the tighter X-axis value, rows of a table whose rules are inset by a few points are dropped (GH#1601).
* PDF two-column detection no longer loses the page’s split to a hanging-number indent. When any span straddled a correctly detected gutter, the split was replaced outright by the midpoint of the widest whole-page whitespace corridor — on a hanging-number layout, the indent between the numbers and the text. The reorder then hoisted every clause number out of its clause. A relocation is now rejected when it would move the split more than a quarter of the page width, which leaves every legitimate corridor move in the corpus intact (GH#1603).
* PDF paragraph grouping no longer splits a numbered heading that wraps onto a shorter second line. The wrap exemption compared the two lines’ right edges, but a heading fills its column on its FIRST line and the continuation is whatever is left over, so the metric was anti-correlated with the answer. The pair is now also exempt when the continuation opens lowercase AND the heading line reaches within a tolerance of the width of what would be merged onto it — the “fills its column” half the original rule stated but never measured. The lowercase test alone is not sufficient: body prose beginning lowercase under a complete numbered heading has the same signature (GH#1605).
* PDF paragraph grouping now recognises a numbered heading whose line arrives as more than one text span. The break terms tested the predicate against a single span, so a heading set with a hanging section number — `3.1.7` in one span, its title in the next, on one baseline — never looked like a numbered heading and was left to the ordinary paragraph-gap rule. That rule needs a gap wider than ordinary line pitch, so every such heading whose body starts on the next line was welded into it. The line’s spans are now re-joined before the predicate runs, which is what the continuation-merge pass already did (GH#1609).
* PDF paragraph grouping now recognises a heading whose number is not its first token — `ARTIKEL 1.`, `Chapter 1`, `Appendix 1`, `Annex III`, `Exhibit A`. The numbered-heading predicate is the only boundary signal available when a heading shares font, size, weight and leading with its neighbour, so a heading it could not see was welded onto the line above it, and a run of such headings collapsed into a single element. Recognition is by shape, not by a keyword list: one capitalised word standing in front of an enumerator. Prose that opens the same way — `Artikel 12 van de wet is van toepassing.` — stays prose, because behind a keyword the text after the enumerator must still be capitalised (GH#1608).
* PDF heading detection no longer skips a numbered heading that is only two words long. Promotion of a bold, body-size line to a heading required more than two words — a floor that keeps short bold fragments out — and a numbered section title such as `3. PRIJZEN` or `1. INTRODUCTION` falls below it. Those lines stayed plain bold paragraphs, and a run of them was then coalesced into a single bold line in the rendered output, while the element stream still reported them separately. A numbered section heading is now exempt from the word-count floor; everything else still has to clear it (GH#1611).
* OCR no longer adopts a markdown table rebuild that loses content. The rebuilt page replaced the original whenever it was merely non-empty, so a rebuild that dropped text still won. The rebuild is now rejected, with a warning naming both word counts, when it retains fewer words than the content it would replace (GH#1599).
* PaddleOCR’s default `model_tier` of `mobile` now resolves to the pp-ocrv6 `small` detection model (9.9 MB) rather than `medium` (62 MB). A tier named `mobile` silently loading the largest available model made a 21-page document take over ten minutes. `small` and `medium` share the same 18,708-character dictionary, so recognition coverage is unchanged. The documented model sizes were also wrong and have been corrected (GH#1602).
* The PHP extension now loads on Debian 12 and other distributions built against GCC 12. The Linux publish runners ship GCC 13+, and the extension picked up a `GLIBCXX_3.4.31` symbol from their libstdc++ while Debian 12 provides at most `GLIBCXX_3.4.30`. libstdc++ is now linked statically; the highest glibc requirement was already below Debian 12’s (GH#1606).
## \[1.1.3] - 2026-09-08
[Section titled “\[1.1.3\] - 2026-09-08”](#113---2026-09-08)
### Added
[Section titled “Added”](#added)
* `Table.cell_styles` and `GridCell.heading_level` / `GridCell.style_name` expose the paragraph style a DOCX table cell carries. A heading styled `Heading1`..`Heading6` inside a `w:tc` — the banner row forms, questionnaires and datasheets use as a section title, and what Word’s navigation pane and a `TOC` field treat as the document outline — previously reached every consumer as anonymous cell text. Cell text is deliberately unchanged: prefixing it with `#` would put a markdown heading inside a table cell. The style travels beside the text instead, so a caller can decide whether a `heading 2` in a banner row is a section title or a column label. `cell_styles` is sparse and omitted entirely for tables whose cells carry no style, so ordinary tables serialise exactly as before (GH#1587).
### Fixed
[Section titled “Fixed”](#fixed-3)
* PDF text repair no longer welds two complete words into one. `repair_ligature_spaces` removes the space in `…f` + ``+ `i|l|f…` to undo a real artefact — some PDFs decompose a ligature glyph and leave a spurious gap, so `first` arrives as `f irst` — but the same character pattern is an ordinary word boundary whenever a word ends in `f` and the next begins with `i`, `l` or `f`. The only guard was a hard-coded list of 33 short English words tested against the left token, so everything outside it welded, English included: `relief for` became `relieffor` and `itself infringes` became `itselfinfringes`. The space is now kept when either fragment is independently attested as a standalone word elsewhere in the same document, reusing the witness mechanism dehyphenation already applies. A fragment appearing only as one half of a candidate pair does not witness itself (GH#1591).
* DOCX page counting no longer collapses a table onto one page. Word writes `` (`null`/`None`/absent in the bindings) and defaults to unset rather than to 3. This fixes supplying a `TesseractConfig` at all acting as a hidden behaviour switch: because several code paths keyed on the struct being absent, a caller who set one unrelated field — table detection, a preprocessing knob — silently lost the whole-image PSM 11, the vertical-language PSM 5, the layout-region PSM 6, and the sparse-text retry, and got Tesseract’s PSM 3 instead. `TesseractConfig()` with default fields is now a no-op: the pipeline applies exactly the same automatic PSM it would with no `TesseractConfig`. An explicitly set `psm` is still honoured. Bindings that model `psm` as a plain integer expose a companion presence check (for example `xberg_tesseract_config_has_psm` in the C API), since a bare integer cannot distinguish “unset” from a real `0`.
### Fixed
[Section titled “Fixed”](#fixed-4)
* Fixed a numbered or bulleted list on a scanned page being reconstructed as a table, replacing the list text with a mangled grid. A candidate region whose first column is list markers (`1.`, `a)`, `•`) end to end — the header cell included — is now rejected on the OCR routes. A genuine numbered table is unaffected: its first column carries a header label (`Line`, `Item`) above the numbers, which is what separates the two.
* Fixed a table detected on a scanned page having its text returned twice — once as paragraphs, once as table cells — in the document content and element tree. This affected every `output_format`; `"plain"` only appeared to avoid it.
* Fixed `PdfConfig.top_margin_fraction` / `bottom_margin_fraction` defaulting to 0.06/0.05 (6%/5%) since 1.1.0, which silently dropped OCR text — page titles included — in the top and bottom bands of every default-config scanned PDF page with no warning. Both now default to 0.0 (disabled); set them explicitly to filter header/footer content. The nonzero defaults also forced every default-config OCR page onto the lossy per-page route instead of a document-capable backend’s whole-document path; that routing is restored too.
* Fixed rendered PDF pages losing the Tesseract backend’s own `ProcessingWarning`s (including the dictionary-filter removal notice) and OCR metadata (`psm`, `language`, `tesseract_dict_invalid_word_ratio`), both of which reached the caller for a standalone image but were silently dropped for the same page rendered from a PDF.
* Fixed `OcrConfig.language` being discarded whenever a `TesseractConfig` was supplied, so a German document was OCR’d in English. One precedence rule now governs both Tesseract backends and the vertical-language check.
* Fixed supplying any `ImageExtractionConfig` suppressing document-level OCR on scanned PDFs, which returned empty pages with only a debug log.
* Fixed rendered PDF pages ignoring the configured render DPI. `target_dpi`, `min_dpi`, `max_dpi`, and `auto_adjust_dpi` are now honoured. With no configuration the default stays at 150 DPI, unchanged.
* Fixed suspended hyphens being welded during text assembly, turning `onderhouds- en` into `onderhoudsen`. A hyphen is now joined only across a genuine visual line break, matching the rule the pipeline layer already applied.
* Fixed an unruled full-width band in a ruled table being cut at column positions no rule gives it, splitting headings mid-word. A column boundary now counts only where a vertical edge actually spans the band.
* Fixed every non-header table cell having its em-dashes, en-dashes and minus signs rewritten to an ASCII hyphen, the spaces around a hyphen collapsed, `E-`/`E+` lowercased to `e-`/`e+`, and any cell consisting solely of a dash emptied. That normalisation is correct for a numeric column (an em-dash means nil, `1.5E-05` is an exponent, `- 3` is `-3`) but corrupted prose tables, turning `Functionaliteit—12` into `Functionaliteit-12` and a part code `HRE - HReco` into `HRe-HReco`. It is now applied only to columns whose data cells are predominantly numeric ([#1582](https://github.com/xberg-io/xberg/issues/1582)).
* Fixed the Windows PHP extension archives failing to publish at all. `vendor-windows-native-closure.ps1` repacks a `.zip` with `Compress-Archive`, which runs no native command and so never sets `$LASTEXITCODE`; the release workflow gated on it, and an unset `$LASTEXITCODE` compares as non-zero, so every Windows archive was rejected immediately after being vendored successfully. Combined with an all-or-nothing matrix gate that withheld the release’s PHP assets whenever any single leg failed, this left v1.1.0 and v1.1.1 with no PHP binaries at all. Both are fixed: the script now sets its exit contract explicitly, matching its sibling scripts, and the upload job now ships the archives from the legs that succeeded ([#1585](https://github.com/xberg-io/xberg/issues/1585)).
## \[1.1.1] - 2026-09-07
[Section titled “\[1.1.1\] - 2026-09-07”](#111---2026-09-07)
> **This release contains a breaking public API change.** `OutputFormat::Structured` is renamed to `OutputFormat::DocTags`. Update any config, CLI invocation, or binding call using `output_format = "structured"` to `"doctags"`.
### Changed
[Section titled “Changed”](#changed-2)
* **Breaking:** renamed `OutputFormat::Structured` to `OutputFormat::DocTags` across every binding and the `output_format` config field. The rename shipped in 1.1.0 but was only alluded to there, with no entry describing it; the variant was renamed, not removed, and is available as `"doctags"`. An `output_format` of `"structured"` is not rejected — it resolves to a custom renderer of that name, which is not registered.
* **Breaking:** the TypeScript and WebAssembly `OutputFormat` type is a string union again (`"plain" | "markdown" | "djot" | "html" | "json" | "doctags" | ...`), matching the serde wire format shared with the CLI, REST, MCP, config-file, and Go surfaces. 1.1.0 briefly published an object union (`{ type: "markdown" }`) for these two bindings only.
### Fixed
[Section titled “Fixed”](#fixed-5)
* Fixed PHP extension packaging, which produced no PIE archives for 1.1.0.
* Fixed HEIC and AVIF decoding on the Linux (glibc) Node binding, which shipped a `libheif` built with no HEVC or AV1 decoder at all — every `.heic` and `.avif` input failed to decode while the `heic` feature still reported as present. The Elixir `linux-gnu` NIF carries the same working codec closure.
* Fixed Elixir NIF publishing for `linux-gnu` and Windows, which produced no artifacts for 1.1.0 and left the Hex package at 1.0.14. The `linux-gnu` NIF is now built against the glibc 2.28 floor it claims to support; the artifacts published for 1.0.14 bundled HEIF codec libraries that required a newer glibc.
* Fixed the Windows Hex package, which declared the `x86_64-pc-windows-gnu` target while CI built and published `x86_64-pc-windows-msvc`. `RustlerPrecompiled` resolves the msvc triple on Windows and rejects any triple the package does not declare, so `mix deps.get` failed with “precompiled NIF is not available for this target” even though the artifact existed. Windows users had to compile the NIF from source.
### Security
[Section titled “Security”](#security)
* The Linux binding images now verify a pinned SHA-256 for every vendored native dependency (`libde265`, `libheif`, ONNX Runtime) before building it, instead of trusting the download. These libraries are linked into the published Node and Elixir artifacts.
## \[1.1.0] - 2026-09-06
[Section titled “\[1.1.0\] - 2026-09-06”](#110---2026-09-06)
> **This release contains breaking public API changes.** Entries prefixed **Breaking:** below remove or change public API — notably `OutputFormat::Structured`, the `ElementId` wrapper, `ExtractedDocument.formatted_content` in the language bindings, and the `core::batch_mode`, `core::formats`, and `core::io` modules — and configuration deserialization now rejects unknown fields rather than ignoring them. Review them before upgrading.
### Added
[Section titled “Added”](#added-1)
* Added per-page OCR confidence to `PageContent.ocr_confidence`, reported as a `PageOcrConfidence { score, word_count, backend }` ([#1568](https://github.com/xberg-io/xberg/issues/1568)). The field is absent for pages that were not OCR’d. `score` is populated only for backends whose confidence is a calibrated legibility scale (normalised to `0.0..=1.0`) and is `None` for uncalibrated ones, so a page OCR’d without a comparable score is still distinguishable from a page nobody scored. It is reported alongside `word_count` because noise filtering runs before the score is computed: a high score over very few surviving words does not mean the page read well.
* Added HWPX (Hangul Word Processor XML) extraction to the WebAssembly package. `unhwp` target-gates its ZIP reader to a deflate-only, LZMA-free build under `wasm32`, so the native-C dependency that previously kept `hwpx` off `wasm-target` does not apply there.
* Added diagram recovery from flat OpenDocument drawings (`.fodg`), including content-based detection of the `application/vnd.oasis.opendocument.graphics-flat-xml` MIME type. Connectors name their endpoints outright, so the recovered graph is exact rather than inferred from geometry (#1545 corpus fixture).
* Added structural extraction for MyST Markdown syntax and MyST text notebooks, including saved inline `{eval}` values in Jupyter markdown cells ([#1538](https://github.com/xberg-io/xberg/issues/1538)).
* Added extraction of Jupytext percent- and light-format notebook scripts, including `text/x-python`, `text/x-r-source`, and `text/x-julia` MIME aliases ([#1538](https://github.com/xberg-io/xberg/issues/1538)).
* Added bounded, cancellable SQLite and GeoPackage table extraction with schema-based GeoPackage detection, `.sqlite3` and `.gpkx` filename support, and defensive handling for untrusted databases (#1510).
* Added configurable MIME inference policies for preferring content signatures, trusting supported filename extensions, or ignoring extensions, with per-input overrides (#1509).
* Added native KML and GeoJSON extraction with canonical MIME routing (#1508).
* Added Rust `SUPPORTED_FORMAT_COUNT` and `SUPPORTED_EXTENSION_COUNT` constants derived from the MIME registry, plus automated synchronization for published format-count claims (#1511).
* Added reusable Rust PDF render sessions for querying page counts and rendering multiple pages without reopening the document (#1485).
* Added cooperative cancellation for single and batch extraction (#1476).
* Added dynamic system linking for Tesseract and Leptonica through the `tesseract-dynamic` feature (#1407).
* Added managed Azure AD, Google Vertex AI, and AWS STS credential providers, with credential values redacted from debug output.
* Added reasoning-effort, provider-specific request-body, and Bedrock configuration for LLM extraction.
* Added `xberg doctor` and the Rust `doctor()` API for validating configuration and probing every compiled OCR, VLM, layout, table, formula-recognition, and cache capability without downloading models or contacting remote providers. `xberg doctor --clean` removes stray files only from Xberg-owned caches (#1347).
* Added the Sceptre EasyOCR Gen2 backend for desktop, mobile, and WebAssembly.
* Added sparse and late-interaction embeddings to chunk output.
* Added a Prometheus `/metrics` endpoint to the API server (#1391).
* Added explicit CSV delimiters and comment-line prefixes through `CsvOptions`.
* Added `xberg tree-sitter` commands for downloading, listing, and cleaning language assets, with optional configuration-file loading.
* Added VLM extraction for complex PDF regions and LaTeX formula extraction from VLM OCR.
* Added structural AsciiDoc and WebVTT extraction.
* Added Docling DocTags input and output, including tables and page geometry (#1383).
* Added formula recognition for rasterized pages and exposed formulas consistently across extracted formats (#1385).
* Added JATS, EPUB, ODT, and ODP MathML-to-LaTeX conversion.
* Added deterministic diagram recovery from SVG and PDF sources with Graphviz DOT output (#579).
* Added `SecurityLimits.max_pages` for PDF, presentations, Keynote, and multi-frame TIFF documents (#1451).
* Added explicit PDF backend selection through `PdfConfig.backend` and `--pdf-backend` (#1448).
* Added musllinux Python wheels and a Windows x86\_64 Ruby gem.
* Added PDF and HTML extraction plus layout and transcription types to the WebAssembly package.
* Added `--ocr-no-cache` to bypass the Tesseract result cache.
* Added `ContentFilterConfig.include_footnotes` for retaining footnotes classified as page furniture.
* Added a public `render_heading_breadcrumb` helper for retrieval-oriented chunk content (#1393).
* Added structured-output merge, citation, and vision-fallback helpers for Rust embedders.
* Added a Tower-compatible extraction service, request type, and builder for Rust applications.
* Added typed configuration for TrOCR, PaddleOCR-VL, GLM-OCR, and DeepSeek-OCR backends.
* Added `classify_chunks_owned` for classifying and returning an owned document.
* Exposed chunk-classification and LLM concurrency, provider, cache, budget, and rate-limit configuration types at the Rust crate root.
* Added `OcrConfig::security_limits`. `ExtractionConfig::security_limits` is now threaded through to every OCR route — embedded images, Tesseract, PaddleOCR, and scanned PDF pages — instead of each route decoding images under a hardcoded `SecurityLimits::default()` ([#1554](https://github.com/xberg-io/xberg/issues/1554)).
* Added `detected_language_confidences`, carrying each detected language’s confidence, proportion, script, and reliability alongside the existing `detected_languages` codes, so a document that is 95% English and 5% French is distinguishable from an even mix ([#261](https://github.com/xberg-io/xberg/issues/261)). The existing field keeps its type and ordering.
* DOCX reviewer comments now emit their own `NodeContent::Comment` node instead of riding the footnote reference and definition machinery, so consumers can tell a comment from a footnote.
* PDF annotations now preserve their subtype (Ink, Square, Circle, Polygon, PolyLine, Line, Squiggly, Caret, FileAttachment, Sound, Movie) instead of collapsing to `Other`, carry author, modification date, colour, subject, and QuadPoints, recover the text a Highlight marks, and are emitted by the Markdown, Djot, plain, HTML, and JSON renderers — previously no renderer emitted annotations at all ([#63](https://github.com/xberg-io/xberg/issues/63)).
* PDF extraction now reads image alt text from the structure tree, falls back to XMP for title, author, and subject when the Info dictionary is empty, surfaces `/PageLabels` (roman-numeral front matter, per-section numbering) through `metadata.additional`, excludes content on optional-content layers that are off by default, and renders filled AcroForm values. Unencodable images, annotation failures, and form failures now emit a `ProcessingWarning` instead of being dropped at log level ([#62](https://github.com/xberg-io/xberg/issues/62), [#71](https://github.com/xberg-io/xberg/issues/71)).
* The OOXML `DocSecurity` bit field is decoded into named protection flags on `Metadata.additional` for DOCX, XLSX, and PPTX, so a password-protected or read-only-recommended document is distinguishable from an unrestricted one.
* Added PaddleOCR on the tract backend, so classical PaddleOCR (DBNet, CRNN, AngleNet) is available on `wasm32` and the Android x86\_64 emulator, where ONNX Runtime cannot link.
* Added `top_p`, `stop`, `seed`, `presence_penalty`, and `frequency_penalty` to `LlmConfig`, validated and applied to every outgoing request. They were previously accepted by every config file and language binding and then dropped before reaching a provider.
* Added `LlmConfig.max_concurrency` to bound VLM OCR and image-captioning requests in flight independently of `ConcurrencyConfig.max_threads`, which represents local CPU capacity ([#1453](https://github.com/xberg-io/xberg/issues/1453)).
* Every error variant now carries a stable FFI error code, so typed error handling works in the C-ABI bindings; `errors.Is(err, ErrOcr)` in Go, Java’s `checkLastError` switch, and Zig’s error set previously collapsed all variants to a single unknown constant.
* Exposed `html_to_markdown_rs::ConversionOptions` at the Rust crate root, so callers configuring `ExtractionConfig::html_options` no longer need a direct dependency on the upstream crate, and made `DocumentNode`’s text and node-type accessors public so `DocumentStructure.nodes` can be read as documented.
* Added `FormatMetadata::html()`, returning the HTML metadata when the variant is `Html`, matching the accessors already exposed for the other formats.
* Added an opt-in Pdfium PDF extraction backend behind the `pdf-pdfium` feature, selectable with `PdfConfig.backend` or `--pdf-backend pdfium`, providing page count, per-page text, and Info dictionary metadata. Its scope is deliberately narrower than the native engine — no table detection, layout integration, form fields, or OCR fallback — and every result carries a `ProcessingWarning` naming the gap. The feature is not part of `full`, so it reaches source builders only.
* Added a Scoop manifest published to the `xberg-io/scoop-bucket` on release, so the Windows CLI can be installed with `scoop install xberg`.
* Extraction now reports a `ProcessingWarning` when a document decodes lossily or degrades silently. Decode provenance is captured before mojibake cleanup strips the replacement characters that used to be the only evidence, and archive, AsciiDoc, WebVTT, XML, and plain-text extraction warn on replaced characters. Unresolved ODT image hrefs, unparseable `styles.xml`, collapsed repeated table cells, skipped LaTeX, Typst, RST, and Org includes, OPML without a body, links past the per-document URI cap, truncated XML, and words Tesseract failed to extract now warn instead of failing silently ([#171](https://github.com/xberg-io/xberg/issues/171), [#133](https://github.com/xberg-io/xberg/issues/133)).
* A PDF page whose raster render comes back blank now falls back to OCR’ing the page’s embedded image XObjects, and that recovery preserves the tables, formulas, LLM usage records, and image preprocessing metadata the backend produced instead of keeping only the text, with every recovered payload accounted against `security_limits`.
### Changed
[Section titled “Changed”](#changed-3)
* **Breaking (Python binding):** `ExtractionConfig` and `DoctorReport` are now frozen dataclasses rather than `TypedDict`s, matching the 121 option types that were already dataclasses. Passing a plain `dict` or a JSON string as `config` still works — `extract()` coerces both — but an `ExtractionConfig` *object* no longer supports mapping operations, so `config.get("chunking")` and `config["chunking"] = ...` now raise `AttributeError`/`TypeError`, and the instance is immutable. Build a modified config with `dataclasses.replace(config, chunking=...)`.
* PDF parsing no longer reports recoverable input at WARN. A missing embedded font, an object outside the xref table, an unreadable CFF version, and a reading-order fallback are ordinary properties of real PDFs rather than conditions an operator can act on; they are now TRACE (or DEBUG for strategy fallbacks), and each document emits a single DEBUG summary on the `xberg_native_pdf::recovery` target carrying the totals instead of one event per occurrence. Measured over a 4,000-document corpus this removed 4,012,488 of 4,014,206 log events, against which 44 genuine parse failures had been sitting at a ratio of about 1 in 91,000. ERROR behaviour is unchanged — it already corresponded one to one with documents that failed ([#1547](https://github.com/xberg-io/xberg/issues/1547)).
* **Breaking (Rust source):** `validate_mime_type` no longer accepts any value with an `image/` prefix. It now parses the MIME type and requires exact membership in the supported-format registry, so unregistered vendor image subtypes such as `image/x-custom-format` are rejected as `UnsupportedFormat` instead of validating (#1511).
* Per-page OCR recognition-noise detail (fragmented-word ratio, word count, mean confidence) now reaches the page accept/reject decision and is emitted at `DEBUG` instead of being discarded one frame earlier. No threshold is gated on it yet; the blended stage score alone cannot discriminate noise pages.
* **Breaking (Rust source):** `ExtractionConfig` adds `apply_notebook_cell_tags`. Notebook extraction now honors MyST and Jupyter Book remove/hide cell tags by default; set the field to `false` to retain all saved cell content ([#1538](https://github.com/xberg-io/xberg/issues/1538)).
* **Breaking (Rust source):** `OcrQualityThresholds` adds `discard_suspected_ocr_noise`; exhaustive struct literals must set the field or use `..Default::default()`.
* **Breaking:** configuration deserialization now rejects unknown fields in nested Xberg configuration tables instead of silently ignoring misspelled settings.
* **Breaking:** PDF backend configuration now uses `"native"` and `PdfBackend::Native` instead of `"pdf_oxide"` and `PdfBackend::PdfOxide`. Update explicit configuration values; the default is unchanged.
* **Breaking:** `EmbeddingModelType::Llm` and `RerankerModelType::Llm` now carry their model name in the enum variant.
* **Breaking:** `Formula.bbox` and `Formula.page` are optional so formulas from formats without page geometry can be represented.
* **Breaking:** unknown multipart fields on extraction endpoints now return an error instead of being ignored.
* Chunk `content` now contains the exact source span; heading breadcrumbs are available separately.
* The CLI `all` feature now includes audio transcription.
* `security_limits.max_pages` now applies to presentations, Keynote, and multi-frame TIFF as well as PDF.
* `create_client_with_credential_provider` now returns `ManagedClient`, and an LLM concurrency limit of zero is rejected.
* Native PDF pages now expose their final per-page reading order.
* WebVTT cue timing is optional for blocks without a timing line.
* OpenDocument packages without `content.xml` now return an extraction error.
* CLI text output now includes the extraction envelope with warnings, timings, and metadata.
* CLI JSON output now reports peak resident memory.
* Windows builds now include the same supported feature set as other desktop builds.
* **Breaking:** Rust element identifiers now use `String` directly; the `ElementId` wrapper has been removed.
* **Breaking:** Public tuple fields for ranges, coordinates, dimensions, links, code blocks, and attributes now use named Rust structs and serialize as JSON objects. Legacy positional JSON arrays are still accepted when parsing, so payloads written by 1.0.x keep deserializing, but they are no longer emitted.
* **Breaking:** removed the duplicate `xberg::llm::region_extractor::RegionKind`; import `xberg::RegionKind` instead.
* Parsing and configuration deserialization now reject invalid region, redaction, and reranker values.
* Corrected and expanded installation, CLI, configuration, extraction, migration, integration, and cross-language API documentation.
* Corrected canonical MIME and extension routing for DBF, YAML, reStructuredText, Org, Typst, XHTML, Djot, JPEG 2000, HEIC/HEIF, MP4, and MPEG inputs.
* GeoJSON extraction now returns a bounded aggregate summary by default, including feature, geometry, property-key, position, and bounds metadata. Set `geojson.include_full_coordinates = true` to retain the complete document and coordinate arrays.
* `quality_score` now explicitly measures the cleanliness and readability of retained text, not extraction completeness; inspect `processing_warnings` for known partial or degraded results.
* The default `security_limits.max_table_cells` remains 100,000 aggregate cells per document; limit errors now explain how to raise it for trusted inputs or reduce the source table.
* `TesseractConfig.language_model_ngram_on` now defaults to `true` on both the PDF and standalone image OCR paths. Tesseract previously applied no penalty to output that does not look like a word of the target language, the dominant failure mode on scanned line art. Set the field to `false` to restore the previous behaviour.
* Tesseract Markdown-format OCR now drops hOCR lines whose dictionary-checkable words are more than 60% invalid, removing recognition noise such as `OWATS DNDEVET` while keeping labels like `EXHIBIT` and `LEGEND`. A line needs at least two checkable words to be scored, and the removed-line count is reported as a `ProcessingWarning`.
* Undecodable-text OCR routing is now decided per page rather than for the whole document, so a single unreadable page no longer sends every page of a PDF through OCR and discards good native text. The previous document-wide fallback still applies when page boundaries are unavailable or inconsistent.
* With `max_threads` unset the thread budget is `min(num_cpus, 8)` and now ceilings Rayon, ONNX Runtime intra-op threads, and batch workers alike. A cgroup CPU quota is honoured in place of the hardcoded 8 where one exists, and a host with more than 8 cores and no `max_threads` is warned once per process ([#1392](https://github.com/xberg-io/xberg/issues/1392)).
* PaddleOCR inference now uses the resolved thread budget instead of a hardcoded single thread. The session is serialized behind a mutex, so exactly one worker runs and can claim the whole budget without oversubscribing.
### Removed
[Section titled “Removed”](#removed)
* **Breaking:** removed the inert `ChunkingConfig::prepend_heading_context`, `breadcrumb_target`, `BreadcrumbTarget`, and corresponding CLI and environment options; use chunk metadata or `render_heading_breadcrumb` when a retrieval index needs headings inline.
* **Breaking:** removed `OutputFormat::Structured`; use `Plain` for unrendered content or `Json` for a structured content tree.
* **Breaking:** removed `ExtractedDocument.formatted_content` from language bindings; use `content` or select the desired output format during extraction.
* Removed advertised support for troff, mdoc, POD, and DokuWiki because they did not have structural extractors.
* Removed fabricated OCR `script_name` and `script_confidence` values.
* Removed the unused public `LanguageRegistry`, `BatchProcessor`, object-pooling APIs, and unused tree-sitter re-exports.
* Removed the nonfunctional `wasm-threads` feature.
* Removed PDF writing, editing, building, and XFA conversion APIs from the native PDF crate; read-only XFA analysis remains available.
* **Breaking:** removed the inert `Engine` structured-policy, preset-resolver, LLM-client, and model-provider injection methods.
* **Breaking:** removed the inert transcription field from `EnrichmentConfig`; configure transcription during extraction instead.
* **Breaking:** embedding, reranking, sparse-embedding, late-interaction, and preset APIs are now exposed only when their required features are enabled.
* **Breaking:** `core::batch_mode`, `core::formats`, and `core::io` are now crate-private, and the public `DocumentStructureBuilder` has been removed.
### Fixed
[Section titled “Fixed”](#fixed-6)
* Fixed the Windows Ruby gem failing to build. `xberg-libwpd`’s build script chose its zlib by operating system alone, so the gem’s MinGW/UCRT toolchain was handed vcpkg’s MSVC-built `x64-windows-static-md` archive and the link died with `corrupt .drectve`/`ld returned 5`. The vcpkg path is now taken only for genuinely MSVC targets; every other target links the static zlib `libz-sys` already builds from source.
* Fixed `XbergLoader` ignoring chunking and per-page splitting whenever the LangChain integration was given an `ExtractionConfig` object. Both settings were read only when the config was a `dict`, so after `ExtractionConfig` became a frozen dataclass the documented `ExtractionConfig(pages=PageConfig(extract_pages=True))` and `chunking=ChunkingConfig(...)` forms silently produced one Document per file instead of one per page or chunk. The config is now read as an object or a mapping.
* Fixed a ruled troubleshooting page collapsing into one table, taking its section headings down with it as cell text. `split_rows_by_text_positions` subdivides a producer-drawn row band by the Y positions of the text inside it, and since the #1555 fix a candidate split was accepted only when EVERY resulting Y-cluster carried text in at least two columns, with the rejection all-or-nothing for the band. A band that mixes multi-column data rows with single-column lines – a section heading, a lead-in, a wrapped continuation – can never satisfy that, so one such line vetoed the split for the whole band and every line inside it became cell text. On one 56-page installation manual, six \~20 pt row bands became a single 522 pt table, the document went from 808 elements to 759, and four numbered headings disappeared from the outline. The band is now split once at least two of its clusters are independently evidenced, and each deficient cluster is resolved on its own terms: it folds into the cluster above only when it introduces no column that cluster left empty, which is the signature of a wrapped continuation. Anything else – a heading, a lead-in – stays a row of its own, one cell wide, which is what such a line inside a ruled band actually is. Two independently evidenced clusters are required rather than one because a single evidenced cluster can be coincidence, which is precisely the #1555 case ([#1565](https://github.com/xberg-io/xberg/issues/1565)).
* Fixed a word split across two touching PDF spans being rejoined with a space, so `prijs` extracted as `pri js`. The gap between the two spans measures 0.069 pt – 0.008 em at 9 pt, against a 2.5 pt space glyph – on an identical baseline at an identical font size, so no gap threshold produced the space: `segments_need_space` reached one of its unconditional `return true` branches first. `SegmentData` keeps only `is_bold`/`is_italic`/`is_monospace` and drops `font_name`, so a mid-word switch between two embedded subset fonts whose `/FontDescriptor`s disagree on `ForceBold`, `ItalicAngle` or `FixedPitch` reads as a style change carrying no geometric signal at all. That is why the defect never reproduced against base-14 Helvetica, and why widening the gap to 2 pt changed nothing. A touching-spans guard now runs before those branches: two segments on the same baseline, at the same font size, with alphanumeric characters on both sides of the boundary and a gap under 0.025 em are one word and are concatenated. The guard can only join, never split, and it never fires across an explicitly drawn space. The table path needed the same test one stage earlier, in `segments_to_words`, because `HocrWord` is integer-rounded and cannot represent a sub-point gap by the time cell text is joined. Affects ordinary prose, not just tables: of 18 confirmed cases, 14 were `NarrativeText`, 3 `ListItem` and 3 `Table` ([#1566](https://github.com/xberg-io/xberg/issues/1566)).
* Fixed PDF table reconstruction dropping early rows when data-start inference classified more than two leading rows as headers. The two-row header cap is retained, but surplus inferred header rows are now demoted to data in source order instead of being discarded ([#1558](https://github.com/xberg-io/xberg/issues/1558)).
* Fixed native PDF top-to-bottom reading order splitting one visual table row at an absolute 3-point coordinate-band boundary, which could move an article number before its position and fuse the two identifiers. Visual rows now use an anchored, font-scaled tolerance, reconstructed lines restore left-to-right fragment order, and narrative assembly preserves a separator after a severe geometric backtrack ([#1560](https://github.com/xberg-io/xberg/issues/1560)).
* Fixed PDF dehyphenation treating inline run/style boundaries as visual line wraps. Suspended hyphens such as `vracht- en verzendkosten` are now preserved, while compounds genuinely split across different baselines are still rejoined ([#1561](https://github.com/xberg-io/xberg/issues/1561)).
* Fixed DOCX page attribution staying permanently low after Word omitted a rendered-page marker between vertically stacked inline images. The parser now conservatively infers missing breaks from each section’s usable page height, including documents with different section geometries ([#1559](https://github.com/xberg-io/xberg/issues/1559)).
* Fixed DOCX DrawingML and VML text boxes dropping XML and numeric character references such as `&` and `€` from extracted text ([#1562](https://github.com/xberg-io/xberg/issues/1562)).
* Fixed OCR image decoding ignoring the caller’s configured `security_limits`. Every OCR route — embedded images, Tesseract, PaddleOCR, and scanned PDF pages — decoded raw image bytes under a hardcoded `SecurityLimits::default()`, so raising `ExtractionConfig::security_limits` to accept a large scan still had it rejected at the OCR decode step. The configured limits now reach all four routes, and PaddleOCR also honors a per-call `backend_options["security_limits"]` override ([#1554](https://github.com/xberg-io/xberg/issues/1554)).
* Fixed a drawn PDF table row with a wrapped cell being shattered into extra rows. Splitting a row band by text Y-position now requires at least two columns to have independent text evidence for every candidate row before splitting; a band where only one column wraps to a second line now stays a single row ([#1555](https://github.com/xberg-io/xberg/issues/1555)).
* Fixed monospace font detection matching any font name containing “mono”, misclassifying foundry names such as “Monotype Corsiva” as a monospace font and skewing the word-spacing heuristic and code-block detection that depend on it. “Monotype” is now excluded from the substring match, and the PDF text run buffer’s separate ad hoc monospace check was replaced with the same shared helper.
* Fixed a standalone multi-line monospace paragraph not being recognized as a code block unless it had a consecutive monospace neighbor paragraph. A lone paragraph that already carries two or more monospace lines is now fenced as a code block on its own ([#1557](https://github.com/xberg-io/xberg/issues/1557)).
* Fixed PDF text extraction silently corrupting ordinary text. A contextual ligature-repair pass rewrote `:` to `ti` and an uppercase `M` between lowercase letters to `tti` on every element of every document, mangling identifiers, ratios, times, URLs, and units such as `nM` (for example `aMb` became `attib`). The repair was introduced for European PDFs that encode ligature glyphs at ASCII code points, but it was gated at the time on a per-font broken-CMap signal from pdfium’s `has_unicode_map_error()`. That gate was lost when pdfium was removed as a backend and was never ported to pdf\_oxide, leaving the rewrite running unconditionally. Both substitutions are removed; they can only return alongside a real document-level evidence gate ([#1556](https://github.com/xberg-io/xberg/issues/1556)).
* Fixed optional fields in the Python and PHP bindings rejecting payloads that omit them. The generated mirror structs lost their `#[serde(default)]` attributes, so deserializing a document whose JSON left an optional field out failed instead of falling back to the default.
* Fixed legacy `.doc` headings being guessed from line length rather than read from the document’s own styles. A paragraph styled `heading 1`..`heading 9` — directly or through a custom style derived from one, such as `TOC Heading` — now becomes a `Heading` at that level, instead of every detected heading being a level 2. Documents that apply no heading style keep the previous shape-based detection, because roughly half the test corpus styles its headings as bold `Normal` and would otherwise lose every one; the choice is made per document, not per paragraph. A heading-styled paragraph that is also list-bound stays a `ListItem`, matching how the DOCX path treats `w:numPr` ([#1553](https://github.com/xberg-io/xberg/issues/1553)).
* Fixed legacy `.doc` automatic list numbering being dropped entirely: a paragraph Word numbers through its list tables arrived as prose, indistinguishable from an unnumbered sentence, while the DOCX path emitted a `ListItem` for the same construct. Auto-numbered paragraphs now arrive as `ListItem`s inside an ordered or bulleted list container, with their nesting depth, matching the DOCX path. The number Word paints (`1.1`, `a.`) is still not rendered — recovering it needs list-table counter state — so a document mixing automatic and hand-typed numbering shows the typed numbers as text and the automatic ones as list structure ([#1550](https://github.com/xberg-io/xberg/issues/1550)).
* Fixed legacy `.doc` elements being split on blank lines rather than on Word’s paragraph marks, which merged every pair of consecutive paragraphs not separated by a blank line into a single element. One corpus letter returned its entire ten-paragraph body as one element. Word97 and later documents now emit one element per Word paragraph, matching what the DOCX path does with `w:p`. **This changes element boundaries, counts and indices for most `.doc` documents**, and alters `content` line spacing accordingly; consumers keying on element position will see the difference. Word 6/95 documents and those falling back to contiguous text extraction keep the previous blank-line behaviour, because they carry no paragraph properties to use.
* Fixed legacy `.doc` extraction reading `fcClx` from `FibRgFcLcb97` pair 66 — an obsolete field Word writes as zero — instead of pair 33, so the piece table was never walked for any document and extraction always fell back to reading `reserved5`/`reserved6`, bytes \[MS-DOC] requires a reader to ignore. Where those bytes disagreed with the real text start, whole documents were decoded as UTF-16LE and returned as glued CJK-looking code points; multi-piece and fast-saved documents could not be assembled at all. Footnote, header/footer, comment, and text-box subdocument text now also reaches the output for these files ([#1551](https://github.com/xberg-io/xberg/issues/1551)).
* Fixed the Elixir NIF’s vendored `Cargo.lock`, shipped in the Hex package, pinning `tree-sitter-language-pack` 1.15.12 while the crate requires 1.16.1 — a source build of the NIF with `--locked` could not resolve. This affects anyone whose platform has no precompiled artifact and therefore builds from source.
* Fixed a DOCX table cell spanning several grid columns (`w:gridSpan`) or rows (`w:vMerge`) being returned once per covered column and again for every covered row, so a cell merged across 4 columns and 3 rows came back 12 times in `result.tables[].cells`, `result.tables[].markdown`, and `result.content` alike — a 39 KB document could extract to 232 KB. A merged/spanned cell’s text is now written once, at its origin, with the columns and rows it covers left blank. This also fixes a DOCX header or footer table with a merged cell shifting every following cell one column to the left ([#1549](https://github.com/xberg-io/xberg/issues/1549)).
* Fixed PDF render diagnostics matching a captured engine warning against a hardcoded message substring to decide whether it meant a glyph actually failed to paint. The message it was built to exclude no longer reaches this capture at all (it moved to TRACE under #1547), so the match could only ever misfire: a future warning whose text happened to share that substring would have been silently dropped instead of surfacing as a `ProcessingWarning`. Every captured warning is now reported ([#1548](https://github.com/xberg-io/xberg/issues/1548)).
* Fixed a PDF page that places a statistics table beside a prose column being emitted in full-width Y order, which spliced the prose apart mid-sentence (`more likely to be aged 35Female 51.5 ...`) and welded the table’s two label/value panels together on every row. The table region is now emitted whole, in row order, ahead of the prose column, and a repeated panel is emitted panel by panel ([#1545](https://github.com/xberg-io/xberg/issues/1545)).
* Fixed PDF text coming back scrambled when a short `Tj` run sat between two `TJ` arrays: the run was emitted at an earlier run’s stale position and sorted into the wrong place, so `within a period ... after conclusion` extracted as `wincthin a period ... after co lusion`. Every text-showing boundary operator closed the pending run except `TJ` ([#1544](https://github.com/xberg-io/xberg/issues/1544)).
* Fixed every image in a DOCX reporting `page_number` 1 regardless of the page it sits on. The page was resolved by searching rendered Markdown for a per-image placeholder that is never written – every drawing renders to the same link target – so the lookup always missed. Page numbers now come from the parsed element order ([#1546](https://github.com/xberg-io/xberg/issues/1546)).
* Fixed an author’s hyphen being deleted when it fell at a line break, so `price-` + `determining` joined as `pricedetermining`. A hyphen written mid-line elsewhere in the same document is now treated as evidence that the compound is real and its hyphen is kept. Compounds that appear only broken, with no such occurrence anywhere in the document, are still joined without the hyphen ([#1543](https://github.com/xberg-io/xberg/issues/1543)).
* Fixed OCR backends registered through `register_ocr_backend` being rejected before extraction started: configuration validation checked the backend name against the built-in list only, which made every custom plugin OCR backend unusable once validation was wired into `extract` and `extract_batch`.
* Fixed the native C FFI library shipping without eleven features the crate advertises, so the Java, Go, C#, Swift, Zig, and C bindings had no summarization, translation, analysis, HEIC, captioning, ML redaction, or static-embedding support. The desktop dependency hand-maintained a feature list that had drifted from `full`; a regression test now fails on any future omission.
* Fixed HTML pages fetched over HTTP(S) losing every format-specific metadata field: results were reported as `text/html` while `metadata.format` stayed empty, because the extraction ran over the crawler’s pre-rendered Markdown and never reached the HTML extractor. Title, headings, Open Graph, Twitter card, links, and structured data are now recovered from the page HTML.
* Fixed `pdf_options.hierarchy.enabled` silently producing no hierarchy: headings were detected and then discarded unless the caller also set the unrelated `pages.extract_pages`. Requesting the heading hierarchy now enables the per-page tracking it requires.
* Fixed the bundled Tesseract build failing to configure on Windows when the MSVC developer environment is not present, which broke building Xberg from source with the default OCR features.
* Fixed URL extraction reporting internally converted HTML pages as `text/markdown`; results now retain a validated, canonical source MIME type.
* Fixed `clear_post_processors` stopping at the first failed shutdown hook and permanently removing enabled built-ins; it now attempts every shutdown, returns the first error, and restores built-ins before the next post-processed extraction while custom processors remain cleared.
* Fixed VLM concurrency limits increasing concurrent local OCR work and raster memory use (#1465).
* Fixed structured extraction forcing every caller schema to JSON Schema Draft 2020-12; validation now honors the schema’s declared draft while keeping external reference resolution offline ([#1539](https://github.com/xberg-io/xberg/issues/1539)).
* Fixed hybrid PDF OCR dropping surrounding prose when a table-bearing bare-text page was restructured alongside geometry-backed pages.
* Fixed automatic PDF OCR fallback reporting an empty success when OCR failed and no native text remained; recoverable failures still return available native text with a warning.
* Fixed degraded VLM fallback output replacing denser OCR text, while abstaining from the density comparison for short text and non-space-delimited CJK or kana content.
* Fixed Windows source and Ruby package builds failing on stable Rust while validating the identity of staged Tesseract source directories.
* Fixed GCC 12+ WordPerfect builds by adding the standard header that declares `size_t` before compiling the pinned libwpd source.
* Fixed Ruby source-package installation by aligning the Gemfile and lockfile with the gemspec’s supported `rb_sys` range.
* Fixed generated Ruby development commands so Bundler and its tools use the active Ruby interpreter, avoiding native-extension ABI conflicts on systems with multiple Ruby versions.
* Fixed generated Python optional constructor arguments so Pyrefly receives precise keyword types without unused helper declarations.
* Fixed generated Dart tests for nested tagged unions, nullable payloads, and Flutter Rust Bridge tuple accessors; added e2e analyzer coverage and refreshed the Dart lock file to the generated Flutter Rust Bridge version.
* Fixed compressed image inputs with oversized declared dimensions exhausting memory during OCR, layout and QR detection, image classification, re-encoding, HEIF conversion, or structured-image rasterization; decoded allocations now obey `security_limits.max_content_size` and are rejected from the image header before pixel decode.
* Fixed PDF OCR fallback being suppressed for image-only pages when dot leaders or other non-textual native content pushed the document below the alphanumeric-ratio threshold.
* Fixed process-global native PDF font-cache collisions that made glyph spacing, geometry, and batch output depend on document order and concurrency when fonts used indirect width tables.
* Fixed Markdown OCR metadata so word counts and confidence statistics describe only text retained after dictionary filtering; fully filtered output now reports zero words and omits confidence quantiles.
* Fixed repeated bold PDF presenter labels and same-row legend keys being promoted to headings, which could invert document hierarchy and fragment retrieval chunks.
* Fixed PDF OCR so fragmented, low-confidence, and dictionary-suspect non-empty text is retained with a processing warning by default instead of silently emptying pages. Set `ocr.quality_thresholds.discard_suspected_ocr_noise = true` (or the equivalent pipeline quality threshold) to opt into the previous destructive filtering behavior.
* Fixed runtime crashes in system-linked Tesseract OCR builds by linking the required native exception-safety shim.
* Fixed `xberg batch` so mixed-success runs emit every successful document and every attributed per-input error before returning a nonzero status; JSON and TOON timing slots remain aligned with inputs, and TOON now uses the documented batch envelope.
* Fixed `xberg extract --ocr false` so it authoritatively disables implicit OCR fallback, overrides conflicting loaded OCR routing, and rejects contradictory OCR flags.
* Fixed Tesseract preprocessing so deskew, denoise, contrast enhancement, and Otsu, adaptive, and Sauvola binarization settings transform the OCR raster on native and WebAssembly backends; `none` (with `off` as an alias) preserves unthresholded grayscale when deskew is disabled, sparse receipt-image fallback and faint colored text no longer lose content to global thresholding, dark labels over bright map fills still receive Otsu preprocessing without isolated or clustered dark artifacts triggering it, and WebAssembly Tesseract now rejects images exceeding 4096 × 4096 pixels before decoding.
* Fixed OCR measurement tooling so line-filter comparisons score the intended ground-truth lines and report filtering regressions accurately.
* Fixed the OpenAPI document’s dangling Djot attribute reference so schema validators and client generators can resolve every advertised component (#1505).
* XML and JSON content with unsupported specialized extensions now routes through the supported generic extractor instead of failing MIME validation (#1507).
* File extraction now falls back to bounded content sniffing when a path has an unknown or missing extension (#1506).
* Explicit `application/octet-stream` hints now trigger configured MIME detection instead of being treated as an authoritative document type.
* Fixed documentation-snippet fixtures that named non-existent result fields, which made the generated snippets silently drop the affected presentation block: element `content` is now `text`, table `rows` is now `cells`, and the result paths `keywords`, `structured_data`, and `document_structure` are now `extracted_keywords`, `structured_output`, and `document`.
* Fixed EPUB extraction for `text/html` spine items, named entities, declared non-UTF-8 encodings, navigation documents, SVG fallbacks, nested tables, MathML, headings, images, and malformed HTML (#1486, #1488-#1494).
* EPUB extraction now preserves usable chapters when another spine item fails and reports per-item warnings instead of failing the whole document (#1491).
* Fixed EPUB metadata, EPUB 2/3 cover selection, DRM detection, and font-obfuscation handling (#1492, #1494).
* Fixed PDF OCR and rendering for highly compressed scans, CCITT images, CFF fonts, maximum-size font tables, malformed embedded fonts, rotated content, missing glyph warnings, and concurrent Pdfium extraction.
* Fixed native PDF tracing so corrupt optional content is reported as a recoverable warning, while mandatory cross-reference failures emit a single operation-boundary error without changing the returned error type.
* Fixed annotation-only PDFs so visible FreeText content is recovered into page-aware document text, including when OCR replaces the page text, without exposing hidden, transparent, cropped, or disabled annotations when annotation extraction is off.
* Fixed the Swift package manifest so SwiftPM no longer warns about a nonexistent target-relative license file.
* Fixed scanned PDF extraction so CCITT parameters align with their filter in multi-filter streams, referenced JBIG2 image masks are available to OCR, and stencil-mask polarity renders text as opaque.
* Fixed PDF reading order for dense two-column layouts, hanging clause numbers, split list markers, and modest font-size changes on one baseline.
* Fixed PDF heading recovery for repeated bold section titles set at body font size while retaining short bold labels, presenter attributions, and calendar legends as body text (#1513).
* Fixed PDF table extraction so multi-word cells, rule-less prose regions, OCR-derived tables, and page-local table failures are handled correctly (#688, #1358, #1542).
* Fixed PDF Markdown and Djot output so native text is retained when structured conversion is incomplete.
* Fixed PDF configuration so metadata suppression and header/footer settings are honored by every backend; invalid or unsupported PDF and OCR settings now return configuration errors.
* Fixed OCR-backed PDFs so filtering, confidence thresholds, hierarchy, tables, formulas, lists, bounding boxes, page boundaries, and partial page results are preserved consistently across output formats and OCR backends (#1444).
* Fixed Tesseract caching, configuration, preprocessing, page segmentation, and font-size extraction.
* Tesseract Markdown extraction now reports a `ProcessingWarning` when dictionary filtering removes physical text lines, including the number removed.
* OCR element hierarchy output now honors `build_hierarchy` and contains only resolvable parent references.
* Fixed Sceptre and PaddleOCR line grouping, region ordering, per-page resizing, table validation, and font-size reporting.
* Fixed DOCX extraction for nested tables, VML images, text boxes, comments, fields, headings, hyperlinks, headers, footers, table-of-contents entries, nested lists, and page attribution; element output now preserves explicit page breaks and single-page documents report page metadata consistently (#1452, #1460, #1503).
* Fixed PPTX extraction for malformed relationships, nested image paths, equations, fallback shapes, comments, metadata, and security limits.
* Fixed spreadsheet extraction for hyperlinks, formulas, names, comments, hidden state, dates, and OpenDocument metadata.
* Fixed ODT, ODP, iWork, HWP, DBF, RTF, email, and PST extraction across nested content, metadata, binary data, folder traversal, and repeated text.
* Fixed Markdown, MDX, RST, HTML, DocBook, JATS, FictionBook, Djot, Org, YAML frontmatter, and Jupyter extraction so supported structure and content are retained.
* Fixed `result.elements` so headings report their level (`metadata.additional["heading_level"]`) instead of every `##`-`######` heading collapsing into indistinguishable `Heading` elements with empty metadata; `result.document.nodes` already carried the level correctly (#1504).
* Fixed CSV parsing for stray quotes and archive extraction order.
* Fixed MIME routing so HTML is detected before the generic XML fallback and supported-format lists reflect the active extractor registry.
* Fixed post-processing, chunking, enrichment, translation, NER, QR codes, captions, and caching so extracted structure is preserved consistently.
* Fixed chunking presets so standalone and pipeline APIs apply the documented size and overlap while preserving unrelated chunking settings.
* Fixed extraction timeout handling so timed-out work is cancelled.
* Fixed configuration merging so changing one CLI option no longer erases sibling settings.
* Fixed multipart API extraction to accept `json` and `doctags` values for `output_format`.
* Fixed cache keys to reflect only settings that affect the corresponding extraction or OCR result.
* Fixed model caching so OCR, embedding, and reranking settings no longer reuse incompatible models.
* Fixed Node.js native-library loading, Swift iOS resolution, Windows DirectML packaging, and `cargo install xberg-cli` (#1456).
* Fixed Docker image builds and reduced the CLI image to runtime dependencies.
* Fixed API and packaging defects in the Python, PHP, Dart, Go, Java, C#, Kotlin, Elixir, Ruby, Zig, and C packages.
* Fixed Windows wheel and gem packaging, manylinux compatibility, musl smoke tests, and dynamic Tesseract builds (#1495, #1497).
* Fixed archive and ZIP validation for small compressed entries and impossible declared sizes (#1496).
* Fixed batch extraction so configured caches are used and progress callbacks report completed items.
* Fixed extraction configuration validation so invalid nested values, including OCR quality and scanned-page thresholds, are rejected consistently by every public entry point.
* Fixed error classification so callers can distinguish all documented extraction failure categories.
* Built-in path and byte extraction now always reports a recognized `extraction_method`; custom extractors retain explicit provenance and otherwise leave it unspecified.
* Fixed owned document classification so detected labels are written back to the returned document.
* Fixed `ContentFilterConfig.include_watermarks` so enabling it retains watermark content.
* Fixed `JsonExtractionConfig.flatten_nested_objects` so disabling it preserves nested objects instead of flattening them.
* Fixed standalone-image and OCR-backed PDF results so preprocessing scale, dimensions, and DPI are retained.
* Fixed Candle OCR configuration so supported backend options are validated and applied.
* Fixed PaddleOCR-VL so the task selected when constructing the backend is honored unless a request explicitly overrides it.
* Fixed keyword extraction so invalid n-gram ranges return an error instead of silently producing empty results.
* Fixed builds that enable only the `api` or `mcp` feature.
* Fixed the `excel-wasm` feature so spreadsheet extraction builds for WebAssembly.
* Fixed WebAssembly configuration so unsupported managed credential providers are rejected explicitly.
* Fixed the Swift package failing to link on Linux. `Package.swift` linked `libxberg_ffi.a` alongside `libxberg_swift.a`, but the Swift static library already folds the entire compiled `xberg-ffi` crate in, so every Rust core, std, and alloc symbol existed twice and the linker reported hundreds of duplicate symbols. It also never asked for ONNX Runtime, leaving `OrtGetApiBase` undefined.
* Fixed the public `clear_ocr_backends()` and `clear_renderers()` leaving their process-global registries permanently empty. After `clear_ocr_backends()` every later extraction failed with “No available OCR backends”; after `clear_renderers()` the `Custom` output-format path silently downgraded DOT renders to plain text for the life of the process. Both now re-seed the built-ins non-destructively, keeping user-registered entries.
* Fixed nested lists rendering as flat, blank-line-separated bullets in `pages[N].content`: container list markers are never page-tagged, so a page subset dropped them and every item was rewrapped in its own single-item list. Also fixed figure alt text being dropped whenever a caption was present, the VLM OCR probe reporting availability without checking credentials, and the PDF margin filter judging rotated text runs by baseline origin.
* Fixed HEIC-enabled builds requiring a libheif newer than current stable distributions ship. The prebuilt artifacts link libheif dynamically and were built against 1.21 APIs, so the PHP extension failed to load on Debian 13 with `undefined symbol: heif_image_get_plane_readonly2`. The floor is now 1.19, with version-gated fallbacks ([#1541](https://github.com/xberg-io/xberg/issues/1541)).
* Fixed PDF text collapsing on itself when a font’s `/Widths` array declares 0 for an ordinary glyph. Extraction now falls back to the embedded font’s own advance for such codes, while an explicit `TJ` displacement stays authoritative and genuine zero-width combining marks remain overlays.
* Fixed automatic PDF OCR replacing a page’s native text with a substantially poorer recognition. OCR output for a page whose native text was independently judged healthy is now rejected when it retains under half that page’s alphanumeric characters.
* Fixed OCR of a single detached page image being attributed to page 1. Local image indices were used as document page numbers, so warnings named the wrong page and the rejected-page filter discarded OCR elements, tables, and formulas belonging to a different page than the one rejected.
* Fixed XML extraction narrowing element depth to `u8` before clamping, so an element nested more than 255 levels deep wrapped to a low heading level in release builds and panicked in debug builds, before the configured `max_xml_depth` limit ever applied ([#1474](https://github.com/xberg-io/xberg/issues/1474)).
* Fixed PDF XMP metadata losing text fragments split around an entity boundary: named and numeric XML references in XMP scalar and sequence values are preserved instead of the surrounding text being truncated ([#1475](https://github.com/xberg-io/xberg/issues/1475)).
* Fixed image-level OCR running again over a page-sized PDF XObject on a page whose native text had already been extracted, which duplicated the page’s content and paid for a second OCR pass ([#1479](https://github.com/xberg-io/xberg/issues/1479)).
* Fixed the musl (Alpine) native artifacts failing to load. The published Java, C#, Zig, C, and Elixir artifacts shipped without ONNX Runtime’s transitive closure — libprotobuf-lite, the `libabsl_*` set, libre2, and libicu. Both musl images now vendor the full `ldd` closure and hard-fail the build if anything is unresolved. A host runtime that links libstdc++ itself still needs libstdc++ 15 or newer in the process, because a bundled copy cannot win once the soname is already mapped.
* Fixed a DOCX or PPTX relationship targeting `../media/image1.png` — the ordinary OPC shape for an image at the package root — being rejected by the traversal check and dropped, so the image went missing from extraction. Container-relative names now resolve boundary-relative.
* Fixed OCR of rendered PDF pages assuming a 72 DPI raster when pages render at 150 DPI, so DPI normalisation computed a 2.48x upscale, hit the dimension clamp, and reported a resolution hint of 179 for what was really a 372 DPI image. Also fixed image DPI normalisation being skipped entirely in candle-backend and VLM-only builds.
* Fixed layout detection marking real figure and drawing text as page furniture, which the renderer then discarded, so labels such as `SITE PLAN` and `LEGEND` disappeared from scanned documents. A `Picture` hint now means a figure was detected, not that the text is decoration, and furniture hints only match short text.
* Fixed the Docling-compatible endpoint discarding OpenWebUI’s extraction parameters. OpenWebUI sends one form field per key rather than a JSON blob, so settings made in its admin UI produced identical output with or without them ([#1462](https://github.com/xberg-io/xberg/issues/1462)).
* Fixed CLI flags being silently discarded. `--ocr-backend`, `--ocr-language`, `--ocr-auto-rotate`, and `--ocr-backend-options` were dropped unless `--ocr true` was also passed, so `--ocr-scanned-pages --ocr-backend sceptre` ran Tesseract with no error; `--ocr-scanned-pages` alone returned an empty document at exit status 0; and `--chunk-size` was a no-op without `--chunk true`.
* Fixed legacy `.doc` extraction emitting every field’s instruction — its URL, switches, and screen-tips — verbatim as prose, and the non-breaking hyphen being dropped with the other control characters, fusing `twenty-one` into `twentyone`.
* Fixed paragraph grouping only breaking when a line starts a numbered section and never when the previous line was one, so a subsection heading followed by unnumbered lines at the same size and weight was merged into the following prose ([#1467](https://github.com/xberg-io/xberg/issues/1467)). Consecutive numbered headings are likewise no longer welded into a single paragraph ([#1386](https://github.com/xberg-io/xberg/issues/1386)).
* Fixed the PDF pipeline stripping a list item’s printed marker and discarding it, leaving renderers to synthesize a position, so a document whose clauses are cross-referenced by their printed label was renumbered — `B.` rendering as `1.` and `(a)` as `1.`.
* Fixed `candle-trocr` accepting a whole page and returning invented text. TrOCR is trained on single cropped lines and force-resizes any input, so a multi-page document exited successfully with text appearing nowhere in it. Input taller than a plausible line crop is now rejected.
* Fixed inline `` elements being discarded during HTML extraction even with `extract_images` enabled ([#745](https://github.com/xberg-io/xberg/issues/745)).
* Fixed an explicitly requested GPU execution provider silently running on CPU. `is_available()` reports only compile-time support and ORT’s session builder defaults to not erroring on failure, so an explicit CUDA, TensorRT, or CoreML request that failed to load was swallowed. Explicit requests now fail; `Auto` keeps its silent fallback.
* Fixed DOCX documents with legacy VML picture markup being rejected as `NestingTooDeep`, and the inverse hole where content inside drawings, table property helpers, the table grid, and streaming section properties was never measured against the depth cap at all. A flat 600-row table of real depth 8 previously leaked over a thousand levels and was rejected outright ([#1395](https://github.com/xberg-io/xberg/issues/1395)).
* Fixed `XBERG_LLM_API_KEY` and `XBERG_LLM_BASE_URL` fabricating a structured-extraction config with an empty model and schema, so any deployment that merely had an LLM key in its environment ran the post-processor on every document and failed every one ([#1421](https://github.com/xberg-io/xberg/issues/1421)).
* Fixed two PDF paths aborting or failing the whole request: a `/ModDate` whose raw bytes decode to a replacement character sliced a `str` off a char boundary and panicked, which across the Go FFI boundary aborts the process before any `catch_unwind` frame is consulted; and a rasterizer panic on a page with damaged content streams unwound through the async boundary and lost every other page’s text ([#1422](https://github.com/xberg-io/xberg/issues/1422), [#1408](https://github.com/xberg-io/xberg/issues/1408)).
* Fixed keyword extraction panicking on a language hint whose first character is multi-byte.
* Fixed legacy `.ppt` slide numbering and image extraction. Slide numbers were the ordinal of a text block in a joined string, so a trailing paragraph mark cut one slide into several; they now come from the slide containers in persist order. The OLE `/Pictures` stream was never opened, so `.ppt` extraction never produced an image ([#1418](https://github.com/xberg-io/xberg/issues/1418), [#1417](https://github.com/xberg-io/xberg/issues/1417)).
* Fixed PPTX slides without a title losing their page number ([#1413](https://github.com/xberg-io/xberg/issues/1413)).
* Fixed URL extraction reporting no crawled URLs, because the result field is no longer populated upstream. The URLs are now derived from the crawled pages, deduped in first-seen order.
* Fixed PDF page-number stripping deleting real table data. The decision was made from one paragraph’s text, so any short numeric cell matched; it now requires a margin band, a stable horizontal slot across pages, and a progressive sequence to agree ([#1411](https://github.com/xberg-io/xberg/issues/1411)).
* Fixed PDF paragraph breaks never being detected on a normally-set page, so a whole memo — date, salutation, body, sign-off — came back as one line. The vertical advance is now compared against the body leading, which is scale-free.
* Fixed detected PDF tables being injected on top of native text that already contained them, so the same content was rendered twice.
* Fixed non-HTML raw blocks being written verbatim into styled HTML output. ODP speaker notes and master-page text, Org source, script and style bodies, and Djot raw blocks all reached the page unescaped, so any `<` in them corrupted the document structure.
* Fixed the PyPI `xberg-cli` wheels shipping without their native libraries. The build hook force-included siblings with a macOS-only glob, so every Linux shared object staged beside the binary was dropped, and the musl wheel shipped only the launcher script. An incomplete platform payload now fails the build instead of publishing a wheel that installs and cannot run.
* Fixed OCR’d PDF pages reporting bounding boxes in raster pixels while digital pages report PDF points, with nothing in the response distinguishing the two spaces. Node, hierarchy block, chunk page span, and table bounding boxes are now converted to page points with a bottom-left origin ([#1423](https://github.com/xberg-io/xberg/issues/1423)).
* Fixed OCR on pages carrying a `/Rotate` entry. Backends now declare how they cope with a rotated raster, so a backend that requires an upright page is handed one with its geometry mapped back, and PaddleOCR receives the page rotation as a sort key. Auto-rotation composes with the page hint instead of double-correcting it.
* Fixed PDF text and tables on rotated pages. Rotated-text repair reconstructs the reading frame but only when rotated spans are at least 20% of a page’s characters, so a single rotated caption no longer costs the upright majority of the page its whitespace structure, and heuristic table reconstruction clusters cells on the table’s own axes rather than raw page space ([#1358](https://github.com/xberg-io/xberg/issues/1358)).
* Fixed the OpenAPI document omitting types that client generators need: second-order nested component schemas are now registered, along with the PDF, office, and transcription schema groups and the `415` and `429` responses the extraction endpoints can return ([#1424](https://github.com/xberg-io/xberg/issues/1424)).
* Fixed `code_intelligence` being hardcoded to `None`, so the documented metrics, imports and exports, comments, docstrings, symbols, and diagnostics never reached callers ([#259](https://github.com/xberg-io/xberg/issues/259)).
* Fixed Whisper timestamp tokens leaking into transcripts as literal text. They are not marked special in the tokenizer vocabulary, so they survived decoding; they are now paired into segments, emitting one paragraph per segment with start and end times.
* Fixed `cargo add xberg --features full` failing to link on Windows MSVC, where a transitive build script forces `/MT` while Rust defaults to `/MD`, killing the build with `LNK2038` ([#1389](https://github.com/xberg-io/xberg/issues/1389)).
* Fixed `show_download_progress` having no readers anywhere on the embedding, sparse-embedding, reranker, and late-interaction model configs, so the documented option did nothing.
* Fixed `split_and_extract` rebuilding each segment from a handful of fields, dropping keywords, entities, summaries, chunks, warnings, and the rest of the enrichment that extraction produced, and an off-by-one in the chunk image-index remap that pointed chunks at the wrong image.
* Fixed `target_dpi`, `max_image_dimension`, `auto_adjust_dpi`, `min_dpi`, and `max_dpi` having no readers: every preprocessing config was built with defaults, so these settings were dropped ([#209](https://github.com/xberg-io/xberg/issues/209)).
* Fixed declared telemetry that never emitted. The cache-hit, cache-miss, and batch instruments were declared but never recorded, and the pipeline and batch operations, five of the eight pipeline stage spans, and the extractor-priority and batch attributes were likewise never recorded, so filtering on them returned nothing ([#332](https://github.com/xberg-io/xberg/issues/332), [#282](https://github.com/xberg-io/xberg/issues/282)).
* Fixed an injected cache backend never being consulted and `ProgressSink::emit` having no caller on single extraction; `extract_batch` was already correct. A bytes-input cache hit now short-circuits extraction and coarse start, complete, error, and cache-hit events are emitted.
* Fixed renderer output completeness: JSON silently dropped page breaks, footnote references and definitions, citations, slides, definition terms, admonitions, raw blocks, and metadata blocks through a catch-all arm; styled HTML opened a section for each slide that was never closed and never rendered the slide title; and formulas rendered as preformatted code, which KaTeX and MathJax cannot pick up, and are now delimited display math.
* Fixed footnote definitions never appearing in JSON output, and a definition present in the document but never referenced being dropped from rendered output entirely ([#68](https://github.com/xberg-io/xberg/issues/68)).
* Fixed plugin-produced documents losing content at the bridge. The conversion into the internal document dropped `uris`, `children`, `annotations`, `processing_warnings`, `llm_usage`, `pages`, and `ocr_elements`; native renderers reached through the public entry point emitted an empty shell; and `pre_rendered_content` was ignored for HTML and JSON output.
* Fixed CRLF documents collapsing into a single paragraph. Ten call sites split paragraphs on a bare double newline without normalising line endings first, affecting email and PST bodies, OCR backend output, plain text, and Djot conversion ([#227](https://github.com/xberg-io/xberg/issues/227)).
* Fixed MIME aliases that were advertised as supported and then failed as `UnsupportedFormat`, because the registry looks up by exact string with no alias resolution. `application/wordperfect`, `application/x-quarto`, and four audio and video transcription aliases now route to the same extractor as their canonical type.
* Fixed three internal OCR plumbing keys being copied into user-visible document metadata.
### Security
[Section titled “Security”](#security-1)
* Bounded DOCX image and iWork archive member reads by the member’s declared uncompressed size instead of trusting that declaration. A crafted document could forge a small declared size in the ZIP central directory while carrying a deflate stream that inflated to multiple gigabytes, exhausting memory during DOCX image extraction (`images.extract_images`) or `.pages`/`.numbers`/ `.key` extraction. Reported by Syed Anas Mohiuddin ([GHSA-85w9-wqcq-x48r](https://github.com/xberg-io/xberg/security/advisories/GHSA-85w9-wqcq-x48r)).
* Pinned downloaded Tesseract, Leptonica, and English tessdata inputs to immutable revisions with verified sizes and SHA-256 digests, race-safe content-addressed caches, private build directories, and bounded fail-closed archive extraction.
* Structured extraction now resolves caller-provided JSON Schemas strictly offline and rejects external HTTP and file references without performing I/O.
* REST and MCP requests can no longer override LLM credentials, provider registrations, or other server-controlled settings.
* Hardened ZIP accounting against overflow, impossible sizes, and compression-ratio bypasses.
* Hardened DOCX, PPTX, and EPUB relationship resolution against container traversal, malformed UTF-8, NUL bytes, drive-letter paths, UNC paths, and symlink escapes.
* Added bounded EPUB traversal and retained-content accounting to prevent resource-limit bypasses.
* Cache namespaces are validated before directories are created.
* Redaction now reports only content that was actually removed, never exposes pre-redaction element text, and rejects invalid strategies instead of silently falling back to masking.
* Hardened the native PDF engine against crafted documents that abort or hang the host process. A self-referencing `/Names /EmbeddedFiles` tree and deeply nested array or dictionary brackets each recursed until the stack overflowed, which is an abort no `catch_unwind` can contain; a negative `/W` element in an xref stream, a reversed `bfrange`, a non-hex `ToUnicode` destination, an all-NaN font-size set, and unchecked `/Width`x`/Height`, `/N`, and `/VerticesPerRow` products each panicked or allocated without bound; and `decode_stream_with_params`, the entry point every production call site uses, applied no ratio or size guard at all. All were reachable from `extract_bytes` under default configuration.
* Bounded every ZIP, TAR, and 7z member read against `SecurityLimits` rather than against the size the archive declares for itself, since a declared uncompressed size is not a bound and the aggregate check previously ran only after the member was fully resident. Covers generic archives, ODT, ODP, EPUB, HWPX, PPTX, XLSX, and OOXML embedded objects, and adds the compression-ratio and aggregate-size validation that PPTX, XLSX, and DOCX were missing. A nested ZIP no longer overflows the stack.
* Clamped or rejected document-declared counts that reached an allocation or a slice unchecked: HWP table row and column counts, HTML and EPUB `colspan`/`rowspan`, DOCX `w:ilvl`, `w:gridSpan`, and `w:outlineLvl`, PPTX `a:pPr lvl`, RST simple-table column ranges, JATS `date-type`, EPUB link-label offsets, PPTX relationship targets, and the hOCR parser’s and annotated-text renderer’s byte-offset slices. Each was an out-of-bounds or char-boundary panic, or an allocation abort, on ordinary untrusted input.
* `security_limits.max_files_in_archive` is now enforced by every OOXML container. XLSX never checked it, DOCX enforced a hardcoded 10,000-entry cap instead of the configured one, PPTX had no entry check at all, and embedded-object extraction walked embeddings uncapped ([#1449](https://github.com/xberg-io/xberg/issues/1449)).
* EPUB packaging XML now counts real OPF nesting depth against the configured limit and accepts legacy DTD declarations without resolving external or amplified entities, so a crafted package can neither bypass the depth budget nor pull in outside content ([#1477](https://github.com/xberg-io/xberg/issues/1477), [#1478](https://github.com/xberg-io/xberg/issues/1478)).
* Native PDF tracing no longer carries document content. Decoded page text was emitted verbatim at TRACE, embedded font names appeared in trace events and in the glyph-drop `ProcessingWarning` message, and parser, xref, and recovery failures were logged by formatting the underlying error string. Failure paths now emit a structured `error_code` with an optional byte `error_offset`, and font names are redacted in the warning text.
* Bounded the native PDF reader’s internal caches so a malformed or hostile document cannot grow them without limit: the object-stream cache evicts to a byte budget and rejects oversized entries, font identity hashing stops at a byte budget and a reference-depth cap (both recorded in the hash so distinct fonts stay distinct), and the xref recovery-marker set is capped.
## \[1.0.14] - 2026-08-04
[Section titled “\[1.0.14\] - 2026-08-04”](#1014---2026-08-04)
### Fixed
[Section titled “Fixed”](#fixed-7)
* OpenWebUI-compatible endpoints (`PUT /process` and `POST /v1/convert/file`) now honor extraction configuration. They previously cloned the server default, forced Markdown output, and ignored all inbound parameters, so configuration passed through OpenWebUI had no effect. They now use the server’s configured defaults as the base and merge a per-request config — a multipart `config`/`parameters` field, or the `X-Config` header — matching the `/extract` endpoint, keeping Markdown as the default only when neither the server config nor the request selects a format.
* Image captioning is now included in the official Docker images (`--features all`), and the server emits a `ProcessingWarning` when a `captioning` config is supplied but the feature is compiled out, instead of silently doing nothing (#1382).
* Release builds no longer check out the `test_documents` benchmark submodule, so a benchmark-only submodule update can no longer fail every publish build and ship a release with no assets (#1380).
### Changed
[Section titled “Changed”](#changed-4)
* Embedded-image captioning now runs with bounded concurrency (mirroring the image-OCR path) instead of one VLM request at a time, reducing wall-clock time on image-heavy documents (#1378).
## \[1.0.13] - 2026-08-04
[Section titled “\[1.0.13\] - 2026-08-04”](#1013---2026-08-04)
### Fixed
[Section titled “Fixed”](#fixed-8)
* OCR-backed PDF extraction now keeps consecutive Tesseract paragraphs grouped within their shared hOCR text area instead of splitting them, including pages replaced by mixed native/OCR extraction. This is paragraph/block grouping only; font-clustering headings and list-marker detection for OCR-backed pages are tracked separately (see Unreleased).
* PDF table reconstruction now rejects sparse, short-wide contact blocks that were previously misclassified as tables.
* Standalone-image Tesseract OCR now defaults to sparse-text segmentation, while cropped layout regions use single-block segmentation and explicit user settings remain unchanged. Vertical language packs such as Japanese (`jpn_vert`) use vertical-block segmentation.
* Standalone image extraction now reports successful OCR through `metadata.ocr_used` and the OCR extraction method, including layout-aware OCR results.
* Tesseract now applies its default image preprocessing only to clean, near-white document pages; shadowed receipts and photographic images keep their source pixels, avoiding quality loss from destructive DPI upscaling, background normalization, sharpening, and grayscale conversion.
* Sparse, low-confidence standalone Tesseract results now retry the previous automatic page segmentation with explicit preprocessing and use it only when word confidence is consistently strong, recovering difficult receipts and scene text without replacing reliable sparse output.
* CSV and TSV plaintext now use the canonical table renderer instead of lossy `Row N` and header-value prose.
* Extracted EML and MSG attachment text is now included in the parent document while the structured attachment children remain available.
* DOCX extraction now emits a tab character for an in-run `Beta` was extracted as `AlphaBeta`). Tab-stop definitions remain invisible. (#1377)
* The Swift package builds and publishes again. The cross-compiled desktop `xberg-ffi` dependency no longer pulls in HEIC (`libheif-sys`, which has no cross-compile support) or the Candle OCR backends, which had broken Swift package publishing in 1.0.12.
* The NuGet runtime packages for macOS and Linux (`osx-x64`, `osx-arm64`, `linux-x64`, `linux-arm64`) now publish at the current version instead of being stuck at an older one; previously only the Windows runtime package was updated. (#1375)
* The public in-browser (WASM) demo now attributes its file-size limit to the browser sandbox and points to the CLI and API for large or multi-page documents, instead of implying the document itself is at fault. (#1376)
## \[1.0.12] - 2026-08-03
[Section titled “\[1.0.12\] - 2026-08-03”](#1012---2026-08-03)
### Fixed
[Section titled “Fixed”](#fixed-9)
* The `xberg mcp` `extract` and `extract_batch` tools no longer emit structured output that fails their own declared output schema. The schema required `errors` and the `crawl_*` fields, but a normal extraction omits them when empty, so MCP clients (e.g. Claude Code) rejected the result. Those fields are now optional in the schema, matching the serialized output. (#1372)
* The `install.sh` script no longer creates a self-referential `xberg` symlink that shadowed the installed binary, and it now selects the glibc (`-gnu`) build on standard Linux distributions instead of always downloading the musl build — which failed to run on glibc systems such as Ubuntu. musl systems (e.g. Alpine) still get the musl build. (#1371)
* CSV header inference no longer misclassifies all-text tables as headerless. A first row such as `Name,City` is now treated as the header (the dominant CSV convention) instead of rendering a broken blank header row with the real header pushed down into the data. A numeric-looking first row is still treated as data. (#1369)
## \[1.0.11] - 2026-08-03
[Section titled “\[1.0.11\] - 2026-08-03”](#1011---2026-08-03)
### Fixed
[Section titled “Fixed”](#fixed-10)
* The extraction HTTP server now bounds in-flight request concurrency so a burst of large uploads can no longer exhaust memory and OOM-kill the process in memory-limited containers. The limit defaults to `2 × CPU count` clamped to `[4, 32]`; override it with `XBERG_MAX_CONCURRENT_REQUESTS` (set `0` to disable). (#1368)
* PaddleOCR output now keeps consecutive visual text lines in the same Markdown paragraph instead of turning every detected line into a separate paragraph.
* PaddleOCR and Tesseract automatic image rotation now use the document-orientation model’s RGB input and existing probability output correctly, and recover sparse edge-aligned text that the model’s standard center crop omitted.
## \[1.0.10] - 2026-08-02
[Section titled “\[1.0.10\] - 2026-08-02”](#1010---2026-08-02)
### Fixed
[Section titled “Fixed”](#fixed-11)
* `cargo install xberg-cli` now succeeds on a stock Windows toolchain. HEIC/HEIF decoding links native `libheif`, which has no default build path on Windows, so it is no longer part of the CLI’s default features and the install no longer fails building `libheif-sys`. Enable HEIC with `--features heic`; the prebuilt release binaries, Docker `all` image, and Homebrew bottle continue to ship it. (#1361)
* The `cargo binstall xberg-cli` static musl builds now compile. The #1355 image-fallback OCR helpers were gated on the `ocr` feature but are reachable under the `ocr-pipeline`-only `binstall` profile, which failed to build both musl targets in the 1.0.9 release.
* `brew install xberg-io/tap/xberg` installs a working binary again instead of an empty bottle; the 1.0.9 bottle rebuild had been skipped when the CLI asset upload cascaded from the failed binstall build. (#1356)
* The hosted demo page (docs.xberg.io/demo.html) no longer 404s its toolbar and file-picker icons. (#1360)
* Dart native-library loading now propagates download, filesystem, and checksum failures instead of silently falling back to an unverified default library resolution path.
* PaddleOCR concurrent cold starts now run off async worker threads and share one engine initialization per model and accelerator, with distinct cache entries for different GPU device IDs.
* Benchmark text F1 now segments CJK around embedded Latin and numeric text while ignoring OCR line wrapping, preventing mixed-script output formatting from distorting quality comparisons.
## \[1.0.9] - 2026-08-02
[Section titled “\[1.0.9\] - 2026-08-02”](#109---2026-08-02)
### Added
[Section titled “Added”](#added-2)
* `cargo binstall xberg-cli` now installs a self-contained, fully static musl CLI binary with no ONNX/Tesseract/libheif runtime dependencies. The `x86_64-unknown-linux-musl` build additionally bundles the pure-Rust Candle VLM OCR backends (TrOCR and PaddleOCR-VL); `aarch64-unknown-linux-musl` ships extraction-only. ONNX/Tesseract/HEIC OCR remain available via Homebrew and the bundled per-target release tarballs.
### Changed
[Section titled “Changed”](#changed-5)
* PaddleOCR now exposes the `PaddleOcrEngine` name and detailed word-level quadrilaterals; the former `OcrLite` name remains available as a deprecated compatibility alias.
* Dense XLSX extraction now scans worksheet bounds without cloning every cell before normal range parsing, while oversized sparse sheets materialize their cells only once.
* Layout-enabled image table recognition now shares its decoded RGB raster with the TATR worker, avoiding one full image allocation and pixel-buffer copy per qualifying image.
* Multi-stage PDF OCR now shares rendered page rasters across pipeline tasks instead of copying each pixel buffer, reducing peak memory by roughly one RGB raster per concurrent page.
* Batch DOCX extraction reuses one owned input buffer and avoids rebuilding discarded document structure, reducing memory copies and structure-processing overhead for large files.
### Fixed
[Section titled “Fixed”](#fixed-12)
* Canonical PaddleOCR benchmark presets no longer force optional whole-image auto-rotation, avoiding confident but incorrect 180-degree rotations that suppressed scene-text quality.
* PaddleOCR now preserves native resolution for 1024-pixel images by default, improving scene-text accuracy while retaining explicit detector-size overrides.
* Layout-enabled image OCR now reuses successful single-frame whole-image text when structured assembly is unavailable, avoiding repeated region OCR and redundant Tesseract table analysis.
* PaddleOCR-only CLI builds no longer compile PDF Markdown layout reuse code when layout detection is disabled.
* The prebuilt macOS CLI tarballs (`aarch64-apple-darwin`, `x86_64-apple-darwin`) now bundle the full libheif dynamic-library closure beside the `xberg` binary and rewrite its load commands to `@loader_path`, so the binary no longer fails with a `libheif.1.dylib` not-loaded error on machines that lack Homebrew’s libheif at the baked-in path (#1357).
* PaddleOCR layout and table consumers now use projected CTC word boxes while preserving line-level semantic text and caller-requested element granularity, avoiding mixed-level duplicate table text.
* PaddleOCR detection now honors its configured DB threshold and matches upstream dilation, perspective-crop, and visual-line ordering behavior, improving small, skewed, and jittered text.
* Apple Keynote packages containing only slide archives now route to the Keynote extractor, and Numbers extraction reconstructs tables instead of emitting raw protobuf fragments.
* AsciiDoc, NXML/JATS, and WebVTT files now route through their registered text or JATS extractors instead of being reported as unsupported.
* Standalone `excel` and `excel-wasm` feature builds now include the XML parsing and table-capacity support required by XLSX extraction.
* Org-mode extraction now distinguishes separator-defined table headers from headerless tables, preserving every data row in rendered Markdown.
* EPUB extraction now resolves `epub:switch` branches per output renderer, preserving supported XHTML and MathML cases while retaining readable plain-text fallbacks.
* Typst extraction now emits marker-free headings and distinguishes explicit table headers from bare table rows, preserving correct Markdown structure.
* MSG extraction now reads the canonical binary `PidTagHtml` stream with the Internet codepage, preserving HTML-only message bodies alongside attachments.
* TATR table reconstruction now assigns each selected OCR word exactly once, using the nearest cell when predicted cells do not overlap, preventing both duplicated and silently dropped text.
* Layout-enabled image extraction now recognizes TATR table structure from cached OCR elements while preserving non-table line structure and requiring complete OCR token retention before accepting the reconstructed layout.
* Layout-enabled OCR now preserves detected image headings without losing or reordering fallback text, and regroups adjacent PDF OCR lines without collapsing distant paragraphs or separate layout regions.
* Rotated PDF OCR now avoids reusing display-coordinate Markdown layout rasters and reruns layout on inverse-`/Rotate`-normalized images, keeping OCR upright without desynchronizing detections.
* Benchmark text F1 treats OCR-inserted line breaks within CJK text as layout whitespace, preventing semantically identical Chinese, Japanese, and Korean output from scoring zero.
* Pipeline quality benchmarks allow forced OCR inference enough time to finish instead of recording slow but valid OCR documents as zero-quality timeout failures.
* Benchmark fixture validation now accepts descriptor filenames without an explicit parent path.
* Pipeline benchmarks now preserve exact ordered cohort fixture paths, use explicit PP-OCR model identities and fixture OCR languages, and score structural image ground truth.
* PaddleOCR now reports processed image dimensions and applied orientation corrections, keeping OCR geometry aligned with optional layout detection on rotated documents.
* PaddleOCR now selects the Japanese model for vertical Japanese and prefers Korean or Japanese recognition for mixed Latin-script requests those models can cover.
* PP-OCRv6 requests containing Korean now use PaddleOCR’s script-specific Korean recognizer, recovering Hangul text that the unified recognition model omitted.
* PaddleOCR now preserves the right-to-left column order and contiguous text of traditional vertical Chinese and Japanese documents.
* Image OCR now preserves blank-line paragraph boundaries instead of flattening every recognized text block into one paragraph.
* Tesseract vertical CJK OCR now removes artificial spaces between adjacent script characters while preserving Latin-word and paragraph whitespace.
* Jupyter notebook paths retain `application/x-ipynb+json` routing when generic JSON content detection runs, and extracted notebook content no longer exposes diagnostic cell/output markers; cell identity, execution, tag, output-type, and MIME details remain available as structured metadata.
## \[1.0.7] - 2026-07-31
[Section titled “\[1.0.7\] - 2026-07-31”](#107---2026-07-31)
### Added
[Section titled “Added”](#added-3)
* **Candle VLM OCR backends now ship in the published packages.** The pure-Rust Candle OCR backends — TrOCR, PaddleOCR-VL, GLM-OCR, and DeepSeek-OCR — are compiled into the published packages by default (Python, Node, Go, Java, C#, Ruby, PHP, Elixir, Kotlin/JVM, Zig, and the CLI / Docker image) on Linux, macOS, and Windows. Select one with `ocr.backend = "candle-glm-ocr"` (or `candle-trocr` / `candle-paddleocr-vl` / `candle-deepseek-ocr`); model weights download from Hugging Face on first use. Previously these backends were excluded from the `full` feature and reachable only via a custom source build. Not available on WebAssembly, Android, iOS, Dart, or Swift.
### Fixed
[Section titled “Fixed”](#fixed-13)
* **#1355 — `force_ocr` no longer emits a silently blank page** when the PDF rasterizer cannot draw an image XObject. When a `force_ocr` page renders blank but carries image XObjects, OCR is retried directly on the embedded image bytes (decoded pixels, or the raw JPEG/JP2 stream) and a processing warning is recorded, so the page content is recovered instead of dropped without notice.
* **Swift artifact-bundle cross-compile**: the cross-compiled Swift binary bundle builds again — the HEIC path (which shells out to `pkg-config` and cannot cross-compile) is dropped from the Swift / Intel-macOS cross-build feature set (`full-no-heic`), restoring the `x86_64-apple-darwin` and Linux Swift builds. The native C FFI distribution keeps HEIC.
* **XLSX extraction on Windows**: the `excel` feature is enabled in the Windows feature set, so `.xlsx` files extract on Windows instead of returning `UnsupportedFormat` for a format the registry advertises as supported.
* Benchmark CI validates ground truth for every format family plus the exact 101-cell workflow matrix and harness contracts before expensive jobs, and the local benchmark task now delegates to the same run wrapper.
* Benchmark quality rankings and Pareto SF1 multiply successful-extraction medians by accountable coverage exactly once, so partial framework failures cannot retain a perfect rank while harness and setup failures remain excluded.
* Benchmark runs abort instead of dropping task errors, verify exact eligible-document cardinality before writing artifacts, reject contradictory failure states and unknown pipeline names, and report extension success rates with the same accountable-failure semantics as the aggregate.
* Benchmark CI invalidates its prebuilt harness cache for harness build scripts, workspace and toolchain configuration, compiler/codegen environment, and every transitive workspace crate, preventing stale binaries. Release tokens now default to the current repository installation.
* Present best-effort benchmark artifacts receive the same provenance, supported-format cardinality, failure-accounting, and aggregate integrity validation as required artifacts; only absence and framework-accountable extraction failures remain optional. Consolidated provenance, metadata, failure summaries, and rankings are cross-checked against validated groups and rows, with ranking optionality derived from the active cohort rather than a global framework union.
* Subprocess benchmark results record the framework’s declared supported extensions, preserving the capability context needed to interpret historical multi-format aggregates.
* Benchmark quality guardrails fail on missing contracted documents or pipeline results instead of reporting a vacuous pass, and reject unknown pipelines, empty predicates, and invalid thresholds before execution.
* Unstructured benchmark cells advertise only their supported plaintext output, and pipeline benchmarks reject unknown sort metrics instead of silently falling back to SF1.
* Benchmark fixtures reject document and ground-truth paths that escape the repository or standalone fixture trust boundary, including symlink escapes, and derive repository boundaries from runtime fixture locations so cached binaries remain portable across CI runners. Artifact provenance hashing uses the same validated path resolution.
* Benchmark CI records declared per-framework format support, validates partial-run thresholds before execution, evaluates them independently per framework, and excludes harness/setup errors from framework success rates while retaining strict extraction coverage for every xberg pipeline.
* Benchmark comparisons include formats with text-only ground truth, report structural scores as unavailable instead of zero when Markdown ground truth is absent, and identify guardrails by file type so same-named fixtures cannot be matched across formats. Guardrails are rebased against the active corpus, removing retired PDF contracts and covering every actionable current result.
* Image layout extraction reuses safely positioned whole-image OCR elements, falls back when region-based OCR drops substantial text or quality, and preserves warnings without redundant OCR retries.
* EPUB extraction removes duplicated serialized MathML and embedded-media fallback content, and avoids emitting a cover image twice when the spine already references it.
* Email extraction preserves sender display names alongside addresses, and asynchronous attachment and nested-message extraction reuses the initial parse instead of parsing messages twice.
* FB2 and DocBook files with generic XML signatures retain their extension-specific MIME types, so they route through the semantic FictionBook and DocBook extractors instead of the generic XML fallback.
* Nested objects and arrays in JSON documents render as structured Markdown headings and lists instead of opaque compact-JSON strings, preserving readable nested keys and values.
## \[1.0.6] - 2026-07-31
[Section titled “\[1.0.6\] - 2026-07-31”](#106---2026-07-31)
### Fixed
[Section titled “Fixed”](#fixed-14)
* **libwpd (Windows/MSVC)**: link the vcpkg-provided static zlib so librevenge’s `inflate*` symbols resolve at the final link. Windows binding builds previously failed with `undefined symbol: inflate` because the MSVC path emitted no usable zlib link directive.
* **#1344 follow-up**: Automatic PDF layout inference retries once on CPU only for runtime inference failures, keeps explicitly selected non-Auto providers and recognized `XBERG_ORT_EP` values authoritative, ignores blank or unrecognized environment values, and propagates the effective or recovered CPU provider to downstream TATR and OCR table reconstruction.
* Side-by-side PDF TATR tables match source words that narrowly cross a detected outer edge to the outermost cell without changing the inference crop or center seam, preserving financial-table row prefixes that previously fell just outside the recognized cell bounds.
### Changed
[Section titled “Changed”](#changed-6)
* Upgrade sibling dependencies: `crawlberg` 1.0.11 → 1.1.0, `html-to-markdown-rs` 3.9 → 3.10, `liter-llm` 1.11 → 1.12. `liter-llm` 1.12 makes `tracing` an always-on dependency and removed its `tracing` Cargo feature, so it is dropped from the dependency declaration (no behavior change — liter-llm spans are always emitted now).
* The `otel` feature now forwards to `crawlberg` and `liter-llm` (weak, `crawlberg?/otel` / `liter-llm?/otel`), so enabling `xberg/otel` compiles those siblings’ direct OpenTelemetry integration (crawlberg’s semconv/propagation, liter-llm’s `gen_ai.*` metrics); their spans and metrics are exported by the host’s provider (e.g. xberg-enterprise). `html-to-markdown-rs` and `tree-sitter-language-pack` are pure `tracing` emitters with no `otel` feature — their spans reach the collector through the consumer’s `tracing-opentelemetry` layer, so nothing is forwarded to them.
## \[1.0.5] - 2026-07-30
[Section titled “\[1.0.5\] - 2026-07-30”](#105---2026-07-30)
### Fixed
[Section titled “Fixed”](#fixed-15)
* **`xberg-libwpd` Windows build**: the WordPerfect extractor now compiles and links on `x86_64-pc-windows-msvc`, unblocking the full-feature Windows binary of downstream consumers. Two first-ship gaps in the vendored C++ build are fixed: (1) zlib (needed by librevenge’s `RVNGZipStream`) is now built from source via `libz-sys` on Windows too — as it already was on Linux/macOS — instead of relying on a vcpkg-installed zlib that CI did not reliably provide (`fatal error C1083: Cannot open include file: 'zlib.h'`); and (2) a narrowing `std::make_shared(…, m_streamData.size())` call in `WP6GeneralTextPacket.cpp` — a 64-bit `size()` into a 32-bit `const unsigned` param — is patched to cast `(unsigned)` (matching every sibling subdocument site), which the newest MSVC toolchain (14.5x) otherwise rejects as a hard error. The vcpkg zlib probing in `build.rs` is removed.
* **#1345**: Sparse native two-column PDFs preserve column-block reading order instead of interleaving their four text lines row-by-row across the gutter.
* **#1346**: PaddleOCR emits a `ProcessingWarning` when requested languages are not covered by the single selected recognition model (previously their text was silently dropped), and OCR metadata now reports the recognition model actually used instead of joining every requested language.
* **#1344**: Layout inference no longer silently degrades to no-layout output when a hardware execution provider fails. macOS `auto` acceleration resolves RT-DETR to CPU up front (its current export cannot execute under CoreML), so the common path never attempts a failing provider. When an *explicit* accelerated provider does fail at inference (for example a CoreML `ExecuteKernel` error), both the markdown and OCR layout paths retry once on the always-available CPU provider and recover the layout, and either way surface a `ProcessingWarning` (recovered-on-CPU, or lost entirely if CPU also fails) instead of returning byte-identical no-layout output with empty `processing_warnings`.
* **#1349**: Successful TATR table reconstruction no longer writes source cell content and coordinates to stderr; the debug output is removed.
* **#1350**: The Markdown hierarchy no longer merges a distant header and footer into one block — paragraph continuation now rejects merges across a large vertical baseline gap and recomputes the merged block’s bounding box.
* **#1351**: The published Node package ships the alef-generated `index.d.ts` (clean, consistent types) rather than the raw `napi build` output, which emitted references to undefined `Js*` types.
* **#1353**: The install script copies nested runtime library directories (for example `lib/libheif`) with `cp -R`, instead of failing with `cp: -r not specified; omitting directory` on Linux musl installs.
### Changed
[Section titled “Changed”](#changed-7)
* Raw `println!`/`eprintln!`/`print!`/`eprint!`/`dbg!` are now denied in production code across the whole workspace (clippy `print_stdout`/`print_stderr`/`dbg_macro`); `tracing` is the sole diagnostic surface. The CLI’s machine-readable result output to stdout opts back in per call site (`#[expect(clippy::print_stdout)]`), and the regenerated language bindings route their FFI-bridge diagnostics through `tracing` instead of `eprintln!`.
* Internal diagnostics that previously wrote to stderr via `eprintln!` (per-page OCR gate decisions, GLM-OCR debug tensor stats, the CLI `--output-format` deprecation notice) now emit through `tracing` at the appropriate level, so verbosity is controlled with `RUST_LOG` / `--log-level` instead of ad-hoc `XBERG_DEBUG_OCR` / `XBERG_GLM_DEBUG` environment variables.
* Repeated per-page and per-backend warnings from external dependencies (OCR engines, layout models) are now de-duplicated by `(source, message)`, so an N-page document surfaces one warning per distinct problem rather than N copies. The paddle-ocr uncovered-language warning is also logged.
## \[1.0.4] - 2026-07-30
[Section titled “\[1.0.4\] - 2026-07-30”](#104---2026-07-30)
### Added
[Section titled “Added”](#added-4)
* MCP clients can run `extract`, `extract_batch`, and `cache_warm` as cancellable SEP-2663 tasks when they advertise task support; synchronous clients remain compatible.
* MCP `cache_clear` and `cache_warm` return typed structured results with cleared-file totals and model availability separated from confirmed cache-hit and download status.
### Changed
[Section titled “Changed”](#changed-8)
* Dependency bumps: `crawlberg` 1.0.11, `tree-sitter-language-pack` 1.13.6, `base64` 0.23 (xberg-jni).
### Fixed
[Section titled “Fixed”](#fixed-16)
* **#1338**: Default `OcrStrategy::Auto` extraction OCRs scanned PDFs with no native text layer instead of returning empty content; explicit OCR disablement remains authoritative.
* **#1341**: Synthesized VLM fallback pipelines run for mixed native/OCR PDFs, preserve skipped and failed-stage diagnostics, and retain the last non-empty fallback when every stage scores below threshold.
* **#1340**: PDF images and generated captions render at bounding-box-aware reading-order positions, remain within the correct layout column, preserve source order, and stay consistent through chunking, translation, and redaction.
* **#1343**: Archive extraction skips macOS/tooling metadata entries (`__MACOSX/`, AppleDouble `._*`, `.DS_Store`, `Thumbs.db`, `desktop.ini`, `__pycache__/`, `.pyc`/`.pyo`) instead of emitting them as `text/plain` children, and unsniffable extensionless members default to `application/octet-stream`; a single aggregated warning records what was filtered.
* Per-file OCR language overrides now also apply to explicit Tesseract pipeline stages, preserving override precedence.
* PDF plain-text extraction repairs detached subscripts, phone suffixes, and final glyphs while preserving RTL, rotated, vertical-writing, and mathematical span order.
* PDF Markdown atomically replaces adjacent native side-by-side table cohorts with validated layout table cohorts, avoiding mixed grids and dropped financial-table structure.
* OCR Markdown applies layout hints to line-local geometry while preserving soft-wrapped body paragraphs and merging multi-line headings, code, pictures, and wrapped list items by hint.
* Tesseract OCR Markdown aligns layout hints and table-cell matching with DPI-normalized and auto-rotated image coordinates, restoring semantic structure on scanned PDFs.
* OCR Markdown recovers missing ordered-list successors only when an existing numeric list item anchors a complete, bounded three-item sequence across pages.
* PDF Markdown preserves strong native headings when a lower-confidence layout Code hint lacks structured code evidence.
* OCR Markdown recovers a title from a guarded first-block logo/title pattern when the layout model emits no semantic heading region.
* PDF Markdown preserves native heading, list, code, and formula semantics while using layout geometry for reading order, grouping, and tables, tolerates minor crop jitter in side-by-side cohorts, merges sparse currency-affix columns without dropping markers, and folds wrapped financial-table lines into logical records; table-dominant pages also discard bbox-confirmed crop spill while retaining surrounding prose and annotations.
* PDF Markdown reconstructs paired wrapped financial tables as semantic three-column grids and repairs consistently merged numeric columns from native PDF table detection.
* **#1342**: PDF table reconstruction retains short numeric grids when a small number of inferred columns make the principal data row nearly complete instead of fully populated.
* PDF Markdown recognizes repeated large-font heading tiers across sparse multi-page documents while retaining the single-page sparse-document safeguard against display-text false positives.
## \[1.0.3] - 2026-07-29
[Section titled “\[1.0.3\] - 2026-07-29”](#103---2026-07-29)
### Added
[Section titled “Added”](#added-5)
* PDF benchmark fixtures can pin Tesseract OCR languages. The benchmark harness validates language codes, checks required packs before timed extraction, and preserves the effective OCR backend and cache settings when applying per-file batch overrides.
### Changed
[Section titled “Changed”](#changed-9)
* Upgraded `rmcp` to 3.0.0 and migrated the MCP server to its 3.0 API (schema output, the new cache-scope/result-type/TTL list-result fields, and the `GetPromptResponse`/`ReadResourceResponse` handler enums). The exposed tools, prompts, and resources are unchanged.
* OCR now emits `tracing` logs when it materializes a Tesseract language pack at runtime: an info line naming the language, destination, and source before the download, one per candidate URL as it is tried, and one on success. Previously a runtime language-pack download was silent, making a first-use OCR stall on a missing pack hard to diagnose. English is unaffected on builds with the `bundle-tessdata-eng` feature (embedded, no download).
* Dependency bumps: `liter-llm` 1.11.4, `toml` 1.1.4.
### Fixed
[Section titled “Fixed”](#fixed-17)
* **#1333**: A sparse continuation row no longer dilutes the numeric ratio used to classify a grid, so numeric line-item tables with a trailing partial row are kept as tables instead of being flattened to prose.
* **#1336**: Tesseract no longer creates OCR cache directories when caching is disabled; the cache directory is created lazily, only when a result is written.
* **#1337**: Light-text-on-dark-background scans are auto-inverted before OCR via mean-luminance polarity detection, and the previously-dead `invert_colors` config is honored as an explicit override (`Some` forces, `None` auto-detects).
* **#1338**: NER and summarization processors are now compiled into the container and CLI builds — they were feature-gated out, so `ner`/`summarization` config was silently dropped. Under `OcrStrategy::ScannedPages`, a whole-document text failure now OCRs every page instead of discarding the signal.
* **#1339**: VLM OCR forwards `XBERG_LLM_*` env credentials to `ocr.vlm_config` when a custom `base_url` is set, normalizes openai.com model names, routes bare images through the OCR pipeline so `vlm_fallback` `on_low_quality` fires, and surfaces per-stage OCR failures as processing warnings.
* Linux builds without CUDA or TensorRT no longer fail under strict warning settings because of an unused ONNX Runtime execution-provider trait import.
* Per-file OCR language overrides (CLI and benchmark) now reach nested Tesseract configurations.
* PDF plain-text extraction repairs detached text spans so words are no longer split mid-token.
* PDF plain-text extraction retains table assets without rendering native table text twice.
* PDF extraction recovers and stitches label-heavy financial tables without merging independent aligned tables.
* PDF Markdown preserves explicit word boundaries and changelog heading hierarchy.
* OCR Markdown prefers validated semantic layout hints over broad text regions at comparable overlap.
## \[1.0.2] - 2026-07-28
[Section titled “\[1.0.2\] - 2026-07-28”](#102---2026-07-28)
1.0.2 is a packaging release. It completes the 1.0.1 rollout — the PHP/Packagist binding failed to build for 1.0.1 — and adds a first-party coding-agent plugin. No core extraction behavior changed.
### Added
[Section titled “Added”](#added-6)
* **Coding-agent plugin.** A first-party xberg plugin for Claude Code, Codex, Cursor, and OpenCode, with a Hermes variant, ships extraction skills (batch extraction, chunking, OCR, tables, keywords, format selection) that drive xberg through its MCP/CLI surface. Published as `@xberg-io/opencode-xberg` (npm) and `xberg-hermes-plugin` (PyPI).
### Fixed
[Section titled “Fixed”](#fixed-18)
* The PHP binding now builds against `ort` 2.0.0-rc.13. rc.13 moved the CoreML/CUDA/TensorRT execution-provider types behind matching Cargo features; a fresh dependency resolution (as on the PHP build) picked up rc.13 and failed to compile. Those EP features are now enabled unconditionally — a compile-time `#[cfg]` unlock only, with no SDK dependency or runtime change — so the PHP/Packagist package publishes again.
### Packaging
[Section titled “Packaging”](#packaging)
* Drops the Node `@xberg-io/xberg-win32-arm64-msvc` sub-package. It was declared as an optional platform dependency but never built — no xberg binding targets Windows on ARM64 — leaving an unresolvable optional dependency. The target is removed from the package manifest and loader for parity with the other bindings.
* Republishes every binding at 1.0.2 to close the 1.0.1 gaps (notably PHP/Packagist).
## \[1.0.1] - 2026-07-28
[Section titled “\[1.0.1\] - 2026-07-28”](#101---2026-07-28)
### Fixed
[Section titled “Fixed”](#fixed-19)
* **#1321**: Borderless, text-heavy tables are recovered on pages that also contain an ML-detected table. The geometric-table fallback now runs per region instead of per page, so a single ML `Table` hint no longer suppresses borderless-grid recovery across the rest of the page; words already inside an existing table hint are excluded so regions are not detected twice.
* **#1326**: RTF hex byte escapes now decode through the active font’s `\fcharsetN` charset (mapped to a Windows codepage), falling back to `\ansicpgNNNN` and then Windows-1252. Documents that declare a Cyrillic or other non-ANSI font in the font table now decode as readable text instead of Windows-1252 mojibake, and font switches mid-document are tracked across nested groups.
* **#1328**: Page markers now appear verbatim in Markdown and Djot output. Flat documents no longer backslash-escape the marker (`\<\!-- PAGE 1 --\>`), and structured native documents no longer drop it entirely.
* **#1323**: RTF hex byte escapes now honor `\ansicpgNNNN` via the shared Windows-codepage table, so CP1251 Cyrillic and other non-1252 ANSI byte runs decode as readable text instead of Windows-1252 mojibake; adjacent escapes decode as one multi-byte run, surviving line wraps, and formatting spans stay aligned with the decoded text.
### Added
[Section titled “Added”](#added-7)
* `LayoutStrategy` enum on `LayoutDetectionConfig` (`strategy` field, default `always`). `auto` pre-screens each PDF page with cheap geometry signals and runs the layout model only on pages likely to benefit; existing configs keep the every-page behavior bit-for-bit. On the OCR path only inference is skipped, since OCR consumes the layout pass’s rasters. Skipped pages are auditable via `metadata.format.layout_gated_pages` and `layout_gate_reasons`, and the CLI gains `--layout-strategy` ([#1322](https://github.com/xberg-io/xberg/issues/1322)).
### Packaging
[Section titled “Packaging”](#packaging-1)
* Republishes `xberg-libwpd` with the static zlib link fix so `xberg-cli` links against a working release. The 1.0.0 `xberg-libwpd` crate was published before the fix and left the librevenge `inflateInit2_`/`inflate`/`inflateEnd` symbols undefined at final link, breaking `xberg-cli` builds from crates.io. No source API changes.
## \[1.0.0] - 2026-07-27
[Section titled “\[1.0.0\] - 2026-07-27”](#100---2026-07-27)
xberg 1.0.0 is the first stable release of the document-intelligence engine previously developed as **Kreuzberg**. It is the direct successor to Kreuzberg v4.9 and carries the same Rust core and extraction-API lineage forward under the xberg name. The Kreuzberg v4 line continues as LTS at [kreuzberg-dev/kreuzberg-lts](https://github.com/kreuzberg-dev/kreuzberg-lts). This entry summarizes everything that changed relative to Kreuzberg v4.9.
Beyond the rename, 1.0.0 is a large release: the PDF stack moved to a pure-Rust backend, the OCR story grew from a single engine to a family of classical and vision-language models, and whole new capabilities landed — audio/video transcription, named-entity recognition, structured LLM extraction, sparse/late-interaction retrieval, and four new language bindings.
For a step-by-step upgrade, see the [migration guide](/migration/from-kreuzberg-v4/).
### Migration from Kreuzberg v4
[Section titled “Migration from Kreuzberg v4”](#migration-from-kreuzberg-v4)
* Packages are renamed `kreuzberg` → `xberg` across every ecosystem (crates.io, PyPI, npm, Maven, NuGet, Composer, RubyGems, Hex, Go).
* The Rust error type `KreuzbergError` is now `XbergError`.
* Environment variables are re-prefixed `KREUZBERG_*` → `XBERG_*`, and config files are discovered as `xberg.{toml,yaml,yml,json}`.
* **Breaking API changes:** extracted URIs are returned as `ExtractedUri` (formerly `Uri`); document metadata drops the untyped `additional`/serde-flatten bag in favour of typed fields plus a `custom` residual map.
* The **R binding**, the **EasyOCR** backend, and the bundled **pdfium** fork are removed (see Removed). Existing Kreuzberg v4 installs keep working under their original names.
The full identifier mapping is in the [migration guide](/migration/from-kreuzberg-v4/).
### Added
[Section titled “Added”](#added-8)
* **A family of OCR backends.** Alongside Tesseract, 1.0.0 adds a native **PaddleOCR** backend (PP-OCRv6, with `medium`/`small`/`tiny` tiers) and a pure-Rust **Candle** OCR/VLM stack — **TrOCR**, **GLM-OCR**, **GOT-OCR**, **DeepSeek-OCR**, and **PaddleOCR-VL** — that runs without ONNX Runtime or native Tesseract. Model weights are self-hosted on the `xberg-io` Hugging Face org.
* **A second, ONNX-Runtime-free inference path (tract).** CNN classifiers, layout detection (RT-DETR), and auto-rotation run through a pure-Rust `tract` backend on targets without ONNX Runtime — this is what makes in-browser (WASM) and mobile inference possible.
* **Structured (LLM) extraction.** `extract_structured` and `split_and_extract` drive a vision-LLM client with rasterization, chunking, citations, caching, and configurable `CallMode` / `MergeMode` / VLM-fallback policies.
* **Audio and video transcription.** A Whisper ONNX encoder/decoder engine extracts text from `.mp3`, `.wav`, `.m4a`, `.mp4`, and `.webm`.
* **Named-entity recognition.** GLiNER2-based entity extraction, including an in-browser WASM `NerModel` that detects entities locally with no server round-trip.
* **Retrieval building blocks.** Sparse embeddings (SPLADE), ColBERT late-interaction retrieval, and a cross-encoder reranking / semantic-search stage alongside dense embeddings, with self-hosted model presets pinned by sha256 manifests.
* **Text intelligence.** Redaction with reversible rehydration and per-entity erasure, summarization, translation, VLM image captioning, QR-code detection, document diffing (`revisions` on `ExtractionResult`), and page/chunk classification.
* **URL and web ingestion.** `map_url` discovers URLs from sitemaps and a shared crawl engine batches multi-URL extraction, over a URI-based `ExtractInput` / `ExtractionOutput` envelope.
* **New document formats (98 total).** WordPerfect `.wpd`/`.wp`/`.wp5` (via a vendored `xberg-libwpd`), HEIC/HEIF/AVIF images (via a vendored libheif), OpenDocument Presentation `.odp`, Quarto/R Markdown, configurable Jupyter cell rendering, and the audio/video formats above.
* **Four new language bindings.** Dart/Flutter, Swift, Kotlin/Android, and Zig — for 15 language bindings over one engine, with Android/iOS cross-compilation.
* **First-party integrations, consolidated into the monorepo.** LangChain.js, LlamaIndex, an n8n community node, CrewAI, and a Spring AI document reader.
* **Richer chunking and API surface.** Caller-supplied tokenizers, `TableChunkingMode::RepeatHeader`, RAG chunking with heading-path breadcrumbs, multi-label chunk classification, per-page spans with bounding boxes, a `list_supported_formats()` call in every binding, cheap `pdf_page_count`, and a `DELETE /jobs/{job_id}` cancellation endpoint on the API server.
* **Wider code intelligence.** tree-sitter coverage grows from 248 to 306 programming languages.
### Changed
[Section titled “Changed”](#changed-10)
* **PDF backend replaced.** pdfium is gone; `pdf_oxide`, a pure-Rust engine, is now the sole PDF backend — no native pdfium dependency.
* **Layout-aware PDF pipeline.** Reading order is reconstructed with ONNX layout detection (PP-DocLayoutV3 / RT-DETR) and Docling-style predecessor-graph reordering; scanned PDFs are detected and OCR’d selectively per page; AcroForm/XFA form fields and outline-based headings are extracted.
* **Public API stabilized** and frozen for 1.0, with a Rust-only `Engine` and extension seams.
* **Renamed from Kreuzberg to xberg** across packages, namespaces, and the `KreuzbergError` → `XbergError` type (see Migration).
* **Environment variables** use the `XBERG_` prefix; new layout, OCR model-tier, CoreML, and ORT execution-provider variables are available.
* **Config discovery** now also accepts the `.yml` extension (`xberg.{toml,yaml,yml,json}`) with an XDG config-directory fallback.
* **Models and cache** live under the `xberg` cache segment and the `xberg-io` Hugging Face org; the project domain is `xberg.io`.
* **Python support** widens to 3.10–3.14; the SurrealDB connector moves to v3 (dropping `mem://`); the default `extraction_timeout_secs` is 60s.
* **License.** Relative to the Kreuzberg 4.8/4.9 line (Elastic License 2.0), xberg 1.0.0 is **MIT**.
### Fixed
[Section titled “Fixed”](#fixed-20)
More than 150 bugs were resolved during the 1.0 cycle. Highlights by area:
* **PDF text fidelity:** text inside Marked-Content (MCID) blocks is no longer dropped from markdown/HTML output (#917); ligature glyphs no longer map to control characters (#1135); glyph-spaced text no longer extracts one character per line (#962); spurious intra-word spaces in native extraction are fixed (#1291, #1222); JPEG 2000 images no longer render blank and silently break OCR (#1158); XML entity references (`&`/`<`/`>`) are preserved (#1242).
* **Tables:** bordered / graphical-line tables are detected reliably instead of silently skipped (#964, #1097, #1213); rotated full-page tables no longer extract as word salad (#1220, #1221); duplicate table emission and double-counting are fixed (#1288); physically fragmented per-row tables are merged back with their header row (#1290, #1100); borderless and text-heavy grids keep their row associations (#1316, #1319).
* **Reading order & structure:** two-column reading order no longer scrambles headings (#1170); stale page boundaries after reordering no longer panic on multibyte text or drop documents (#1270, #1272); numbered and cover-page headings are classified correctly (#961, #966, #1096, #1098); filled form field values are placed correctly (#1120).
* **OCR:** an explicit PaddleOCR backend no longer silently falls back to Tesseract (#801, #1071, #1088, #1102); scanned-page OCR text and page provenance surface consistently across content, pages, and chunks (#1095, #1110, #1281); spurious auto-OCR on born-digital PDFs is suppressed (#1176); a SIGBUS crash and a NaN-sort panic in the OCR pipeline are fixed (#1057, #1179); the Candle VLM OCR backends are stabilized (#1174, #1175, #1208–#1214); model downloads handle TLS-MITM CAs, IPv6 blackholes, and connect timeouts (#1146, #1249).
* **Chunking & provenance:** chunk `firstPage`/`lastPage` and byte ranges are correct across output formats and long PDFs (#1013, #1074, #1105, #1294); markdown chunks retain markdown (#1073, #1094); split-table chunks keep their header and context (#1100).
* **Bindings & packaging:** fixed Go embed symbols, Java `UnsatisfiedLinkError`, missing C# config types, wrong Node/PHP embedding shapes, Android `.so` loading, macOS wheel floors, and musl/ONNX Runtime runtime deps (#871, #965, #991, #998, #1008, #1055, #1131, #1257, #1304, #1307); plus Homebrew 404s, Docker stop-signal handling, and multi-arch `-core` images (#1081, #1147, #1247, #1315).
* **Formats:** EML HTML `` bodies, DOCX hyperlink/bold overlap and markdown conversion, archived markdown/CSV escaping, and Korean-charset EML detection are fixed (#942, #1086, #1212, #1237, #1278).
* **Config & robustness:** `extraction_timeout_secs` is honoured on every path (#830, #911, #1273); `cancel_token`, custom LLM base URLs, and page-classification config all validate correctly (#937,
\#944, #1076).
### Removed
[Section titled “Removed”](#removed-1)
* **R binding** — the Kreuzberg v4 LTS line is the last to ship it.
* **EasyOCR backend** — the Python/torch-only backend did not survive the Rust rewrite; use Tesseract, PaddleOCR, a Candle backend, or a VLM backend instead.
* **Hunyuan-OCR Candle backend** — ported during development, then dropped before 1.0.0.
* **Bundled `pdfium-render` fork** and its `KREUZBERG_PDFIUM_BUNDLED_PATH` variable, and the standalone `@kreuzberg/core` npm package.
### Performance
[Section titled “Performance”](#performance)
* **OCR memory discipline:** concurrent Tesseract sessions are capped, Leptonica/Pix/page buffers are released early, decoded RGB buffers are reused, and images are resized without copies.
* **Layout inference:** model sessions are pooled, batch inference threads are balanced, and an unnecessary PNG raster round-trip is bypassed.
* **Engine and batch:** bounded batch scheduling, no per-item config clone, single PDF parse per structured rasterization, streamed batch JSON output, and base64 hosted embeddings.
* **PDF and text:** streamed RGB conversion, reused OCR render document, skipped redundant compatibility parses, and a regex→scanner rewrite that removes backtracking from text/quality cleanup.
### Security
[Section titled “Security”](#security-2)
* An untrusted RTF size field in the email extractor could allocate up to 4 GB — now bounded (#1058).
* A redaction path could leak PII across roughly a dozen output fields — fixed (#1223).
* PDF embedded streams are guarded by a decompression-ratio limit and per-embedded-file size caps, and a `SecurityBudget` is wired through the PDF and email extractors.
* Excel DDE / external-call formulas raise warnings during extraction.
* FFI image and attachment buffers now carry explicit lengths so callees never read past the buffer (#1056, #1059), and panics on malformed input are replaced with recoverable errors (#907, #1057,
\#1198).
### Packaging
[Section titled “Packaging”](#packaging-2)
* pdf\_oxide replaces the pdfium native dependency; libheif (LGPL, documented) and `xberg-libwpd` are vendored; retrieval and OCR model presets are self-hosted on `xberg-io` with sha256 manifests.
* Distribution hardening across all 15 targets: ONNX Runtime bundling, glibc/musl floors (musl via Alpine images), NuGet runtime-package size splits, Homebrew bottles, Go module tags, Swift C++ linkage, and Dart/Swift/Kotlin-Android/Zig release matrices. Published to crates.io, PyPI, npm, Maven Central, NuGet, RubyGems, Packagist, Hex, pub.dev, Go, Swift Package Manager, Homebrew, Docker (`ghcr.io/xberg-io/xberg`), and a Helm chart.
# CLI Usage
Command-line access to all Xberg extraction features.
## Installation
[Section titled “Installation”](#installation)
* Install Script (Linux/macOS)
Bash
```bash
curl -fsSL https://raw.githubusercontent.com/xberg-io/xberg/main/scripts/install.sh | bash
```
* Homebrew (macOS/Linux)
Bash
```bash
brew trust xberg-io/tap
brew install xberg-io/tap/xberg
```
* Scoop (Windows)
PowerShell
```powershell
scoop bucket add xberg https://github.com/xberg-io/scoop-bucket
scoop install xberg
```
* Cargo (Cross-platform)
Bash
```bash
cargo install xberg-cli
```
* Docker
Bash
```bash
docker pull ghcr.io/xberg-io/xberg-cli:latest
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg-cli:latest extract /data/document.pdf
```
* Go (SDK)
Bash
```bash
go get github.com/xberg-io/xberg/packages/go@latest
```
Feature Availability
**Homebrew Installation:**
* ✅ Text extraction (PDF, Office, images, 107 formats)
* ✅ OCR with Tesseract
* ✅ HTTP API server (`serve` command)
* ✅ MCP protocol server (`mcp` command)
* ✅ Chunking, quality scoring, language detection
* ❌ **Embeddings** - Not available via CLI flags. Use config file or Docker image.
**Docker Images:**
* All features enabled including embeddings (ONNX Runtime included)
## Global Flags
[Section titled “Global Flags”](#global-flags)
### Log Level
[Section titled “Log Level”](#log-level)
`--log-level` controls log verbosity and overrides `RUST_LOG`.
Terminal
```bash
# Set log level to debug for troubleshooting
xberg --log-level debug extract document.pdf
# Suppress all but error messages
xberg --log-level error batch documents/*.pdf
# Trace-level logging for maximum detail
xberg --log-level trace extract document.pdf
```
Valid levels: `trace`, `debug`, `info` (default), `warn`, `error`.
### Colored Output
[Section titled “Colored Output”](#colored-output)
Output is colored by default. Disable with `NO_COLOR`:
Terminal
```bash
# Disable colored output
NO_COLOR=1 xberg extract document.pdf
```
## Basic Usage
[Section titled “Basic Usage”](#basic-usage)
### Extract from Single File
[Section titled “Extract from Single File”](#extract-from-single-file)
Terminal
```bash
# Extract text content to stdout
xberg extract document.pdf
# Specify MIME type (auto-detected if not provided)
xberg extract document.pdf --mime-type application/pdf
```
### Batch Extract Multiple Files
[Section titled “Batch Extract Multiple Files”](#batch-extract-multiple-files)
Terminal
```bash
# Extract from multiple files
xberg batch doc1.pdf doc2.docx doc3.txt
# Batch extract all PDFs in directory
xberg batch documents/*.pdf
# Batch extract recursively
xberg batch documents/**/*.pdf
```
### Output Formats
[Section titled “Output Formats”](#output-formats)
Terminal
```bash
# Output as plain text (default for extract)
xberg extract document.pdf --format text
# Output as JSON (default for batch)
xberg batch documents/*.pdf --format json
# Extract single file as JSON
xberg extract document.pdf --format json
# Output as TOON wire format (token-efficient alternative to JSON)
xberg extract document.pdf --format toon
```
### Content Output Format
[Section titled “Content Output Format”](#content-output-format)
`--content-format` (alias: `--output-format`) sets the format of extracted text content:
Terminal
```bash
# Extract as plain text (default)
xberg extract document.pdf --content-format plain
# Extract as Markdown
xberg extract document.pdf --content-format markdown
# Extract as Djot markup
xberg extract document.pdf --content-format djot
# Extract as HTML
xberg extract document.pdf --content-format html
# Combine content format with wire format
xberg extract document.pdf --content-format markdown --format toon
```
`--content-format` formats `result.content`; `--format` controls the wire format of the entire response (`text`, `json`, or `toon`).
## OCR Extraction
[Section titled “OCR Extraction”](#ocr-extraction)
### Enable OCR
[Section titled “Enable OCR”](#enable-ocr)
Terminal
```bash
# Enable OCR (overrides config file setting)
xberg extract scanned.pdf --ocr true
# Disable OCR
xberg extract document.pdf --ocr false
```
### Force OCR
[Section titled “Force OCR”](#force-ocr)
Force OCR even for PDFs with text layer:
Terminal
```bash
# Force OCR to run regardless of existing text
xberg extract document.pdf --force-ocr true
```
### OCR Language Selection
[Section titled “OCR Language Selection”](#ocr-language-selection)
`--ocr-language` is backend-agnostic and overrides config-file or default settings.
| Backend | Code format | Examples |
| --------- | ---------------------------- | -------------------------------------------------- |
| Tesseract | ISO 639-3 (three-letter) | `eng`, `fra`, `deu`, `spa`, `jpn` |
| PaddleOCR | short codes / language names | `en`, `ch`, `french`, `korean`, `thai`, `cyrillic` |
Terminal
```bash
# French OCR with Tesseract (default backend)
xberg extract --ocr true --ocr-language fra document.pdf
# Chinese OCR with PaddleOCR
xberg extract --ocr true --ocr-backend paddle-ocr --ocr-language ch document.pdf
# Thai OCR with PaddleOCR
xberg extract --ocr true --ocr-backend paddle-ocr --ocr-language thai document.pdf
# German OCR with Tesseract
xberg extract --ocr true --ocr-language deu document.pdf
# Override config file language with Spanish
xberg extract document.pdf --config xberg.toml --ocr-language spa
```
### OCR Configuration
[Section titled “OCR Configuration”](#ocr-configuration)
OCR options live in the config file; CLI flags override:
Terminal
```bash
xberg extract scanned.pdf --config xberg.toml --ocr true
```
See [Configuration Files](#configuration-files) for backend, language, and Tesseract options.
## Configuration Files
[Section titled “Configuration Files”](#configuration-files)
### Using Config Files
[Section titled “Using Config Files”](#using-config-files)
Xberg auto-discovers `xberg.toml` by walking up from the current directory. For YAML or JSON, pass `--config` explicitly.
Terminal
```bash
xberg extract document.pdf # auto-discovers xberg.toml
```
### Specify Config File
[Section titled “Specify Config File”](#specify-config-file)
Load TOML, YAML (`.yaml`/`.yml`), or JSON via `--config`:
Terminal
```bash
xberg extract document.pdf --config my-config.toml
xberg extract document.pdf --config xberg.yaml
xberg extract document.pdf --config my-config.json
```
### Inline JSON Config
[Section titled “Inline JSON Config”](#inline-json-config)
Inline JSON is merged after config file, before individual flags:
Terminal
```bash
# Inline JSON (applied after config file)
xberg extract document.pdf --config-json '{"ocr":{"backend":"tesseract"},"chunking":{"max_chars":1000}}'
# Base64-encoded JSON (useful in shells where quoting is awkward)
xberg extract document.pdf --config-json-base64 eyJvY3IiOnsiYmFja2VuZCI6InRlc3NlcmFjdCJ9fQ==
```
Both `extract` and `batch` support `--config-json` and `--config-json-base64`.
### Example Config Files
[Section titled “Example Config Files”](#example-config-files)
**xberg.toml:**
OCR configuration
```toml
use_cache = true
enable_quality_processing = true
[ocr]
backend = "tesseract"
language = "eng"
[chunking]
max_characters = 1000
overlap = 100
```
**xberg.yaml:**
xberg.yaml
```yaml
use_cache: true
enable_quality_processing: true
ocr:
backend: tesseract
language: eng
chunking:
max_characters: 1000
overlap: 100
```
**xberg.json:**
xberg.json
```json
{
"use_cache": true,
"enable_quality_processing": true,
"ocr": {
"backend": "tesseract",
"language": "eng"
},
"chunking": {
"max_characters": 1000,
"overlap": 100
}
}
```
## Batch Processing
[Section titled “Batch Processing”](#batch-processing)
Process multiple files with `batch`:
Terminal
```bash
# Extract all PDFs in directory
xberg batch documents/*.pdf
# Extract PDFs recursively from subdirectories
xberg batch documents/**/*.pdf
# Extract multiple file types
xberg batch documents/**/*.{pdf,docx,txt}
```
### Batch with Output Formats
[Section titled “Batch with Output Formats”](#batch-with-output-formats)
Terminal
```bash
# Output as JSON (default for batch command)
xberg batch documents/*.pdf --format json
# Output as plain text
xberg batch documents/*.pdf --format text
```
### Batch with OCR
[Section titled “Batch with OCR”](#batch-with-ocr)
Terminal
```bash
# Batch extract with OCR enabled
xberg batch scanned/*.pdf --ocr true
# Batch extract with force OCR
xberg batch documents/*.pdf --force-ocr true
# Batch extract with quality processing
xberg batch documents/*.pdf --quality true
```
### Batch with Content Format
[Section titled “Batch with Content Format”](#batch-with-content-format)
Terminal
```bash
# Batch extract with djot formatting
xberg batch documents/*.pdf --output-format djot --format json
# Batch extract as Markdown
xberg batch documents/*.pdf --output-format markdown --format json
# Batch extract as HTML
xberg batch documents/*.pdf --output-format html --format json
```
## Advanced Features
[Section titled “Advanced Features”](#advanced-features)
### Language Detection
[Section titled “Language Detection”](#language-detection)
Terminal
```bash
# Extract with automatic language detection
xberg extract document.pdf --detect-language true
# Disable language detection
xberg extract document.pdf --detect-language false
```
### Content Chunking
[Section titled “Content Chunking”](#content-chunking)
Terminal
```bash
# Split content into chunks for LLM processing
xberg extract document.pdf --chunk true
# Specify chunk size and overlap
xberg extract document.pdf --chunk true --chunk-size 1000 --chunk-overlap 100
# Output chunked content as JSON
xberg extract document.pdf --chunk true --format json
```
### Quality Processing
[Section titled “Quality Processing”](#quality-processing)
Terminal
```bash
# Apply quality processing for improved formatting
xberg extract document.pdf --quality true
# Disable quality processing
xberg extract document.pdf --quality false
# Batch extraction with quality processing
xberg batch documents/*.pdf --quality true
```
### Caching
[Section titled “Caching”](#caching)
Terminal
```bash
# Extract with result caching enabled (default)
xberg extract document.pdf
# Extract without caching results
xberg extract document.pdf --no-cache true
# Clear all cached results
xberg cache clear
# View cache statistics
xberg cache stats
```
### Tree-sitter Grammars
[Section titled “Tree-sitter Grammars”](#tree-sitter-grammars)
Manage the grammar cache used for code intelligence. This command is available when the CLI is built with the `tree-sitter` feature.
Terminal
```bash
# Download selected grammars
xberg tree-sitter download python rust go
# Download configured language groups
xberg tree-sitter download --from-config
# Inspect or clear the grammar cache
xberg tree-sitter list --downloaded
xberg tree-sitter cache-dir
xberg tree-sitter clean
```
### Environment Diagnostics
[Section titled “Environment Diagnostics”](#environment-diagnostics)
`doctor` checks whether the backends in your config will actually run on this machine, before the first document. Each check reports pass, warn, fail, or skip with a one-line reason; warnings are actionable but never fail the command, and it exits nonzero only on failures.
Terminal
```bash
# Probe the backends from xberg.toml (or the discovered config)
xberg doctor
# JSON output for bug reports
xberg doctor --format json
# Also remove stray files from xberg-owned cache dirs
xberg doctor --clean
```
Tesseract checks tessdata per configured language, PaddleOCR verifies model checksums, VLM checks the API key and endpoint reachability (no billable call), and layout detection runs one real RT-DETR inference. Models that aren’t downloaded yet report `skip` rather than failing.
When `XBERG_CACHE_DIR` is set, cache inspection and `--clean` are disabled (reported as `skip`): the override is a raw path and xberg cannot verify it owns the directory.
## Extraction Override Flags
[Section titled “Extraction Override Flags”](#extraction-override-flags)
`extract` and `batch` accept the flags below; they take precedence over config-file settings.
### OCR Flags
[Section titled “OCR Flags”](#ocr-flags)
| Flag | Description |
| --------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--ocr ` | Enable or disable OCR. Defaults to tesseract backend when enabled. |
| `--ocr-backend ` | OCR backend: `tesseract`, `paddle-ocr`, `sceptre`, `candle-trocr`, `candle-paddleocr-vl`, `candle-paddleocr-vl-15`, `candle-glm-ocr`, `candle-deepseek-ocr`, or `vlm`. |
| `--ocr-language ` | OCR language code. Sceptre accepts its eight group tokens or ISO aliases such as `eng`, `deu`, `tel`, and `kan`. |
| `--force-ocr ` | Force OCR even if the document has an existing text layer. |
| `--ocr-auto-rotate ` | Automatically rotate images before OCR based on detected orientation. |
| `--disable-ocr ` | Disable OCR entirely, even for images. |
Candle-based backends (`candle-trocr`, `candle-paddleocr-vl`, `candle-paddleocr-vl-15`, `candle-glm-ocr`, `candle-deepseek-ocr`) are pure-Rust VLM and vision-transformer OCR engines. No ONNX Runtime required; GPU-accelerated on Metal (macOS) and CUDA (Linux). They ship compiled into the CLI/Docker image by default — no extra install or feature flag needed. Model weights download automatically from Hugging Face on first use.
Terminal
```bash
xberg extract scanned.pdf --ocr true --ocr-backend paddle-ocr --ocr-language ch
xberg extract document.pdf --force-ocr true --ocr-auto-rotate true
```
### Chunking Flags
[Section titled “Chunking Flags”](#chunking-flags)
| Flag | Description |
| ------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--chunk ` | Enable or disable text chunking. |
| `--chunk-size ` | Maximum chunk size in characters (default: 1000). |
| `--chunk-overlap ` | Overlap between consecutive chunks in characters (default: 200). |
| `--chunking-tokenizer ` | Tokenizer model for token-based chunk sizing (for example `Xenova/gpt-4o`). Implicitly enables chunking. Requires the `chunking-tokenizers` feature. |
Terminal
```bash
xberg extract document.pdf --chunk true --chunk-size 512 --chunk-overlap 50
xberg extract document.pdf --chunking-tokenizer "Xenova/gpt-4o"
```
### Output Flags
[Section titled “Output Flags”](#output-flags)
| Flag | Description |
| ----------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `--content-format ` | Content output format: `plain`, `markdown`, `djot`, `html`, `json`, or `doctags`. Controls how extracted text is formatted. (Deprecated alias: `--output-format`) |
| `--include-structure ` | Include hierarchical document structure in results. |
Terminal
```bash
xberg extract document.pdf --content-format markdown --include-structure true
```
### Layout Detection Flags
[Section titled “Layout Detection Flags”](#layout-detection-flags)
| Flag | Description |
| ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------ |
| `--layout` | Enable layout detection with default settings (RT-DETR v2). Use `--layout false` to explicitly disable. Requires the `layout-detection` feature. |
| `--layout-confidence ` | Layout detection confidence threshold (0.0 - 1.0). |
| `--layout-table-model ` | Table structure model: `tatr` (default), `slanet_wired`, `slanet_wireless`, `slanet_plus`, `slanet_auto`, `disabled`. |
Terminal
```bash
xberg extract document.pdf --layout --layout-confidence 0.7
```
### Acceleration Flags
[Section titled “Acceleration Flags”](#acceleration-flags)
| Flag | Description |
| --------------------------- | ---------------------------------------------------------------------------------------------------- |
| `--acceleration ` | ONNX Runtime execution provider for model inference: `auto`, `cpu`, `coreml`, `cuda`, or `tensorrt`. |
Terminal
```bash
# Use CoreML on macOS for GPU acceleration
xberg extract document.pdf --acceleration coreml
# Use CUDA on Linux with NVIDIA GPU
xberg extract document.pdf --acceleration cuda
```
### Page Flags
[Section titled “Page Flags”](#page-flags)
| Flag | Description |
| ------------------------------- | --------------------------------------------------------- |
| `--extract-pages ` | Extract pages as a separate array in results. |
| `--page-markers ` | Insert page marker comments into the main content string. |
Terminal
```bash
xberg extract document.pdf --extract-pages true --page-markers true --format json
```
### Image Flags
[Section titled “Image Flags”](#image-flags)
| Flag | Description |
| -------------------------------- | ----------------------------------------------- |
| `--extract-images ` | Enable image extraction from documents. |
| `--target-dpi ` | Target DPI for image normalisation (36 - 2400). |
Terminal
```bash
xberg extract document.pdf --extract-images true --target-dpi 300
```
### PDF Flags
[Section titled “PDF Flags”](#pdf-flags)
| Flag | Description |
| -------------------------------------- | ------------------------------------------------------------------------------------ |
| `--pdf-password ` | Password for encrypted PDFs. Can be specified multiple times for multiple passwords. |
| `--pdf-extract-images ` | Extract images embedded in PDF pages. |
| `--pdf-extract-metadata ` | Extract PDF metadata (title, author, etc.). |
Terminal
```bash
xberg extract encrypted.pdf --pdf-password "secret"
xberg extract document.pdf --pdf-extract-images true --pdf-extract-metadata true
```
### Token Reduction Flags
[Section titled “Token Reduction Flags”](#token-reduction-flags)
| Flag | Description |
| --------------------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `--token-reduction ` | Token reduction intensity: `off`, `light`, `moderate`, `aggressive`, or `maximum`. Reduces token count for LLM consumption. |
Terminal
```bash
# Aggressive token reduction for cheaper LLM processing
xberg extract document.pdf --token-reduction aggressive
# Maximum compression (lossy)
xberg extract document.pdf --token-reduction maximum
```
### Quality and Detection Flags
[Section titled “Quality and Detection Flags”](#quality-and-detection-flags)
| Flag | Description |
| --------------------------------- | ------------------------------------------------------- |
| `--quality ` | Enable quality post-processing for improved formatting. |
| `--detect-language ` | Enable automatic language detection on extracted text. |
### Cache Flags
[Section titled “Cache Flags”](#cache-flags)
| Flag | Description |
| ------------------------------- | -------------------------------------------------- |
| `--no-cache ` | Disable extraction result caching. |
| `--cache-namespace ` | Cache namespace for tenant isolation. |
| `--cache-ttl-secs ` | Per-request cache TTL in seconds (0 = skip cache). |
### Concurrency Flags
[Section titled “Concurrency Flags”](#concurrency-flags)
| Flag | Description |
| ---------------------- | ----------------------------------------------------------------------------------------------------------- |
| `--max-concurrent ` | Limit parallel extractions in batch mode. |
| `--max-threads ` | Cap all internal thread pools (Rayon, ONNX intra-op, batch semaphore). Useful for constrained environments. |
Terminal
```bash
xberg batch documents/*.pdf --max-concurrent 4 --max-threads 8
```
### Email Flags
[Section titled “Email Flags”](#email-flags)
| Flag | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- |
| `--msg-codepage ` | Windows codepage fallback for MSG files without codepage metadata. Common values: 1250 (Central European), 1251 (Cyrillic), 1252 (Western). |
Terminal
```bash
xberg extract message.msg --msg-codepage 1251
```
## Output Options
[Section titled “Output Options”](#output-options)
### Standard Output (Text Format)
[Section titled “Standard Output (Text Format)”](#standard-output-text-format)
Terminal
```bash
# Extract and print content to stdout
xberg extract document.pdf
# Extract and redirect output to file
xberg extract document.pdf > output.txt
# Batch extract as text
xberg batch documents/*.pdf --format text
```
### JSON Output
[Section titled “JSON Output”](#json-output)
Terminal
```bash
# Output as JSON
xberg extract document.pdf --format json
# Batch extract as JSON (default format)
xberg batch documents/*.pdf --format json
```
**JSON Output Structure:**
JSON Response
```json
{
"content": "Extracted text content...",
"metadata": {
"mime_type": "application/pdf"
}
}
```
## Error Handling
[Section titled “Error Handling”](#error-handling)
The CLI returns non-zero exit codes on error. Use shell idioms:
Terminal
```bash
# Check for extraction errors
xberg extract document.pdf || echo "Extraction failed"
# Continue processing even if one file fails (bash)
for file in documents/*.pdf; do
xberg batch "$file" || continue
done
```
## Examples
[Section titled “Examples”](#examples)
### Extract Single PDF
[Section titled “Extract Single PDF”](#extract-single-pdf)
Extract text from PDF
```bash
xberg extract document.pdf
```
### Batch Extract All PDFs in Directory
[Section titled “Batch Extract All PDFs in Directory”](#batch-extract-all-pdfs-in-directory)
Extract all PDFs from directory as JSON
```bash
xberg batch documents/*.pdf --format json
```
### OCR Scanned Documents
[Section titled “OCR Scanned Documents”](#ocr-scanned-documents)
OCR extraction from scanned documents
```bash
xberg batch scans/*.pdf --ocr true --format json
```
### Extract with Quality Processing
[Section titled “Extract with Quality Processing”](#extract-with-quality-processing)
Extract with quality processing enabled
```bash
xberg extract document.pdf --quality true --format json
```
### Extract with Chunking
[Section titled “Extract with Chunking”](#extract-with-chunking)
Extract with chunking for LLM processing
```bash
xberg extract document.pdf --config xberg.toml --chunk true --chunk-size 1000 --chunk-overlap 100 --format json
```
### Batch Extract Multiple File Types
[Section titled “Batch Extract Multiple File Types”](#batch-extract-multiple-file-types)
Extract multiple file types in batch
```bash
xberg batch documents/**/*.{pdf,docx,txt} --format json
```
### Extract with Config File
[Section titled “Extract with Config File”](#extract-with-config-file)
Extract using configuration file
```bash
xberg extract document.pdf --config /path/to/xberg.toml
```
### Detect MIME Type
[Section titled “Detect MIME Type”](#detect-mime-type)
Detect file MIME type
```bash
xberg detect document.pdf
```
## Docker Usage
[Section titled “Docker Usage”](#docker-usage)
Use `ghcr.io/xberg-io/xberg-cli:latest` for the CLI image, or `ghcr.io/xberg-io/xberg:latest` for the full image (also includes the CLI).
### Basic Docker
[Section titled “Basic Docker”](#basic-docker)
Terminal
```bash
# Extract document using Docker with mounted directory
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg-cli:latest \
extract /data/document.pdf
# Extract and save output to host directory using shell redirection
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg-cli:latest \
extract /data/document.pdf > output.txt
```
### Docker with OCR
[Section titled “Docker with OCR”](#docker-with-ocr)
Terminal
```bash
# Extract with OCR using Docker
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg-cli:latest \
extract /data/scanned.pdf --ocr true
```
### Docker Compose
[Section titled “Docker Compose”](#docker-compose)
**docker-compose.yaml:**
docker-compose.yaml
```yaml
version: "3.8"
services:
xberg:
image: ghcr.io/xberg-io/xberg-cli:latest
volumes:
- ./documents:/input
command: extract /input/document.pdf --ocr true
```
Run:
Terminal
```bash
docker-compose up
```
## Performance Tips
[Section titled “Performance Tips”](#performance-tips)
### Optimize Extraction Speed
[Section titled “Optimize Extraction Speed”](#optimize-extraction-speed)
Terminal
```bash
# Extract without quality processing for faster speed
xberg extract large.pdf --quality false
# Use batch for processing multiple files
xberg batch large_files/*.pdf --format json
```
### Manage Memory Usage
[Section titled “Manage Memory Usage”](#manage-memory-usage)
Terminal
```bash
# Disable caching to reduce memory footprint
xberg extract large_file.pdf --no-cache true
# Compress output to save disk space
xberg extract document.pdf | gzip > output.txt.gz
```
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
### Check Installation
[Section titled “Check Installation”](#check-installation)
Terminal
```bash
# Display installed version
xberg --version
# Display help for commands
xberg --help
```
### Common Issues
[Section titled “Common Issues”](#common-issues)
**Issue: “Tesseract not found”**
When using OCR, Tesseract must be installed:
Terminal
```bash
# Install Tesseract OCR engine on macOS
brew install tesseract
# Install Tesseract OCR engine on Ubuntu
sudo apt-get install tesseract-ocr
```
**Issue: “File not found”**
Ensure the file path is correct and accessible:
Terminal
```bash
# Check if file exists and is readable
ls -la document.pdf
# Extract with absolute path
xberg extract /absolute/path/to/document.pdf
```
## Server Commands
[Section titled “Server Commands”](#server-commands)
### Start API Server
[Section titled “Start API Server”](#start-api-server)
`serve` starts the HTTP REST API:
Terminal
```bash
# Start server on default host (127.0.0.1) and port (8000)
xberg serve
# Start server on specific host and port (-H / -p are short forms)
xberg serve --host 0.0.0.0 --port 8000
xberg serve -H 0.0.0.0 -p 8000
# Start server with custom configuration file
xberg serve --config xberg.toml --host 0.0.0.0 --port 8000
```
### Server Endpoints
[Section titled “Server Endpoints”](#server-endpoints)
The server provides the following endpoints:
* `POST /extract` - Extract text from uploaded files
* `POST /batch` - Batch extract from multiple files
* `GET /detect` - Detect MIME type of file
* `GET /health` - Health check
* `GET /info` - Server information
* `GET /cache/stats` - Cache statistics
* `POST /cache/clear` - Clear cache
See [API Server Guide](/guides/api-server/) for full API details.
### Start MCP Server
[Section titled “Start MCP Server”](#start-mcp-server)
`mcp` starts a Model Context Protocol server for AI agents:
Terminal
```bash
# Start MCP server with stdio transport (default for Claude Desktop)
xberg mcp
# Start MCP server with HTTP transport
xberg mcp --transport http
# Start MCP server on specific HTTP host and port
xberg mcp --transport http --host 0.0.0.0 --port 8001
# Start MCP server with custom configuration file
xberg mcp --config xberg.toml --transport stdio
```
The MCP server provides tools for AI agents:
* `extract` - Extract text from a file path
* `extract` - Extract text from base64-encoded bytes
* `extract_batch` - Extract from multiple files
See [API Server Guide](/guides/api-server/) for MCP integration details.
## Embeddings
[Section titled “Embeddings”](#embeddings)
Generate vector embeddings using pre-trained models. Input via `--text` or stdin.
Terminal
```bash
# Generate embeddings for a single text
xberg embed --text "hello world" --preset balanced
# Generate embeddings with a specific preset
xberg embed --text "document content" --preset fast
# Batch embed multiple texts
xberg embed --text "first document" --text "second document" --preset quality
# Read from stdin
echo "hello world" | xberg embed --preset balanced
# Output as text instead of JSON
xberg embed --text "hello" --preset balanced --format text
```
Available presets: `fast`, `balanced` (default), `quality`, `multilingual`.
Feature Availability
The `embed` command requires the `embeddings` feature. It is available in Docker images but not in Homebrew installations.
## Chunking Command
[Section titled “Chunking Command”](#chunking-command)
Split text with configurable size and overlap. Input via `--text` or stdin.
Terminal
```bash
# Chunk text with default settings
xberg chunk --text "long text content to be split into chunks..."
# Specify chunk size and overlap
xberg chunk --text "long text..." --chunk-size 512 --chunk-overlap 50
# Use markdown-aware chunking
xberg chunk --text "# Heading\n\nParagraph..." --chunker-type markdown
# Use a tokenizer model for token-based sizing
xberg chunk --text "long text..." --chunking-tokenizer "Xenova/gpt-4o"
# Read from stdin
cat document.txt | xberg chunk --chunk-size 1000
# Output as text instead of JSON
xberg chunk --text "long text..." --format text
# Use a config file for chunking settings
xberg chunk --text "long text..." --config xberg.toml
```
## Shell Completions
[Section titled “Shell Completions”](#shell-completions)
Tab-completion scripts for bash, zsh, and fish:
Terminal
```bash
# Generate bash completions
xberg completions bash
# Generate zsh completions
xberg completions zsh
# Generate fish completions
xberg completions fish
# Install bash completions
eval "$(xberg completions bash)"
# Install zsh completions (add to .zshrc)
eval "$(xberg completions zsh)"
```
## API Utilities
[Section titled “API Utilities”](#api-utilities)
### Dump OpenAPI Schema
[Section titled “Dump OpenAPI Schema”](#dump-openapi-schema)
Output the OpenAPI 3.1 specification — useful for code generation and API client tooling.
Terminal
```bash
# Print OpenAPI schema as JSON
xberg api schema
# Save to file
xberg api schema > openapi.json
```
Feature Availability
The `api` subcommand requires the `api` feature.
## List Supported Formats
[Section titled “List Supported Formats”](#list-supported-formats)
List supported formats with extensions and MIME types:
Terminal
```bash
# List formats as a table
xberg formats
# List formats as JSON
xberg formats --format json
```
## Cache Management
[Section titled “Cache Management”](#cache-management)
### View Cache Statistics
[Section titled “View Cache Statistics”](#view-cache-statistics)
Terminal
```bash
# Display cache usage statistics
xberg cache stats
# Display statistics for specific cache directory
xberg cache stats --cache-dir /path/to/cache
# Output cache statistics as JSON
xberg cache stats --format json
```
### Clear Cache
[Section titled “Clear Cache”](#clear-cache)
Terminal
```bash
# Remove all cached extraction results
xberg cache clear
# Clear specific cache directory
xberg cache clear --cache-dir /path/to/cache
# Clear cache and display removal details
xberg cache clear --format json
```
### Warm Model Cache
[Section titled “Warm Model Cache”](#warm-model-cache)
Pre-download ML models (PaddleOCR, layout detection, embeddings, NER) for offline use — useful for containerized deployments.
Default cache directories:
* **Linux**: `~/.cache/xberg/{module}` (or `$XDG_CACHE_HOME/xberg/{module}`)
* **macOS**: `~/Library/Caches/xberg/{module}`
* **Windows**: `%LOCALAPPDATA%/xberg/{module}`
Override with `XBERG_CACHE_DIR` or `--cache-dir`.
NER warming downloads exported GLiNER artifacts from `xberg-io/gliner-models`, not arbitrary GLiNER source repositories. If that Hugging Face repository is private or not publicly readable, configure credentials supported by `hf-hub` first.
Terminal
```bash
# Download all OCR and layout models eagerly
xberg cache warm
# Download to a specific cache directory
xberg cache warm --cache-dir /path/to/cache
# Also download all 4 embedding model presets (fast, balanced, quality, multilingual)
xberg cache warm --all-embeddings
# Download a specific embedding model preset
xberg cache warm --embedding-model balanced
# Download the default GLiNER NER model alias
xberg cache warm --ner
# Download a specific xberg GLiNER alias or catalog id
xberg cache warm --ner-model fast
# Output download results as JSON
xberg cache warm --format json
```
### Model Manifest
[Section titled “Model Manifest”](#model-manifest)
Manifest of expected model files with SHA256 checksums and sizes — for cache integrity checks or scripted pre-population.
Terminal
```bash
# Output manifest as JSON (default)
xberg cache manifest
# Output manifest as human-readable text
xberg cache manifest --format text
```
## Getting Help
[Section titled “Getting Help”](#getting-help)
### CLI Help
[Section titled “CLI Help”](#cli-help)
Terminal
```bash
# Display general CLI help
xberg --help
# Display command-specific help
xberg extract --help
xberg batch --help
xberg detect --help
xberg formats --help
xberg version --help
xberg embed --help
xberg chunk --help
xberg completions --help
xberg serve --help
xberg mcp --help
xberg cache --help
xberg cache stats --help
xberg cache clear --help
xberg cache warm --help
xberg cache manifest --help
xberg api schema --help
```
### Version Information
[Section titled “Version Information”](#version-information)
Terminal
```bash
# Display version number
xberg --version
# Show version with JSON output
xberg version --format json
```
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [API Server Guide](/guides/api-server/) - API and MCP server setup
* [Chunking](/guides/chunking/) - Split text for RAG
* [Embeddings](/guides/embeddings/) - Semantic vectors for search
* [Language Detection](/guides/language-detection/) - Multilingual document analysis
* [Token Reduction](/guides/token-reduction/) - Optimize for LLMs
* [Quality Processing](/guides/quality-processing/) - Filter low-quality text
* [PDF Form Fields](/guides/pdf-form-fields/) - Extract form data
* [Plugin Development](/guides/plugins/) - Extend Xberg functionality
* [API Reference](/reference/api-python/) - Programmatic access
# Architecture
Xberg is a document extraction library with a Rust core and native bindings for Python, TypeScript, Ruby, and more. The core handles all the expensive work (PDF parsing, OCR, text processing) and exposes it through thin language-specific wrappers. Your code calls directly into compiled Rust. No subprocesses, no serialization, no IPC overhead.
***
## Design Principles
[Section titled “Design Principles”](#design-principles)
Three ideas shape how Xberg is built:
1. **Rust does the heavy lifting.** Every performance-critical operation runs as native Rust code - compiled, optimized, and fast.
2. **Plugins cross language boundaries.** A Python OCR backend can register itself with the Rust core and participate in the extraction pipeline as a first-class citizen.
3. **Minimize data copying.** Data passes across FFI boundaries using zero-copy techniques wherever possible. When a Python plugin receives file bytes, it gets a buffer protocol view into Rust-owned memory, not a copy.
***
## System Layers
[Section titled “System Layers”](#system-layers)
```mermaid
flowchart TB
subgraph your_code ["Your Code"]
Python["Python"]
Node["TypeScript\nNode.js"]
Wasm["TypeScript\nWASM"]
Ruby["Ruby"]
end
subgraph bridges ["FFI Bridges"]
PyO3["PyO3"]
NAPI["NAPI-RS"]
WB["wasm-bindgen"]
Magnus["Magnus"]
end
subgraph engine ["Rust Core"]
Core["xberg\ncrate"]
end
Python --> PyO3
Node --> NAPI
Wasm --> WB
Ruby --> Magnus
PyO3 --> Core
NAPI --> Core
WB --> Core
Magnus --> Core
style Core fill:#e1f5ff,stroke:#0288d1
style PyO3 fill:#ffe1e1,stroke:#c62828
style NAPI fill:#ffe1e1,stroke:#c62828
style WB fill:#fff3e0,stroke:#ef6c00
style Magnus fill:#ffe1e1,stroke:#c62828
```
Your code sits at the top. It calls into a bridge layer that translates types between your language and Rust. The bridge forwards the call to the Rust core, which does the actual extraction, OCR, and text processing. Results come back through the same bridge.
### TypeScript: Native vs Wasm
[Section titled “TypeScript: Native vs Wasm”](#typescript-native-vs-wasm)
There are two TypeScript packages because server and browser environments have fundamentally different constraints:
* **`@xberg-io/xberg`** (native) - compiled via NAPI-RS. Maximum performance on Node.js, Bun, and Deno. Requires a platform-specific native binary.
* **`@xberg-io/xberg-wasm`** (WebAssembly) - compiled via wasm-bindgen. Runs in browsers, Cloudflare Workers, Vercel Edge, and any JavaScript runtime. About 60-80% of native speed, but zero native dependencies.
Rule of thumb: use native on servers, Wasm in browsers and edge runtimes. See the [Installation Guide](/getting-started/installation/#typescript) for setup.
***
## Rust Core Structure
[Section titled “Rust Core Structure”](#rust-core-structure)
The core crate (`crates/xberg`) is organized into modules with clear responsibilities:
```mermaid
flowchart LR
subgraph crate ["xberg crate"]
Core["core/\nOrchestration\nPipeline entry points"]
Plugins["plugins/\nTrait definitions\nRegistries"]
Extractors["extractors/\nMIME → handler\nmapping"]
Extraction["extraction/\nPDF · Excel · Email\nHTML · XML · Text"]
OCR["ocr/\nTesseract\nTable detection"]
Text["text/\nToken reduction\nQuality scoring"]
Types["types/\nExtractionResult · ExtractedDocument\nMetadata · Chunk"]
Error["error/\nXbergError"]
end
Core --> Plugins
Core --> Extractors
Extractors --> Extraction
Extractors --> Plugins
Extraction --> OCR
Extraction --> Text
Core --> Types
Core --> Error
style Core fill:#bbdefb,stroke:#1565c0
style Plugins fill:#c8e6c9,stroke:#2e7d32
style Extraction fill:#fff9c4,stroke:#f9a825
style Extractors fill:#ffccbc,stroke:#d84315
```
| Module | Responsibility |
| --------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **core/** | Main entry points (`extract`, `extract_batch`), MIME detection, config loading, pipeline orchestration |
| **plugins/** | Plugin trait definitions (`DocumentExtractor`, `OcrBackend`, `PostProcessor`, `Validator`, `Renderer`) and the registry system (ExtractorRegistry, OcrRegistry, ValidatorRegistry, ProcessorRegistry, RendererRegistry) |
| **extractors/** | Maps MIME types to the correct extractor implementation and registers them with the plugin system |
| **extraction/** | Format-specific extraction logic - PDF via xberg-native-pdf, Excel via calamine, email parsing, and so on. |
| **ocr/** | OCR orchestration - Tesseract bindings, HOCR parsing, table detection |
| **text/** | Text processing utilities - token reduction, quality scoring, string manipulation |
| **types/** | Shared data structures: `ExtractionResult`, `ExtractedDocument`, `Metadata`, `Chunk`, and friends |
| **error/** | Centralized error handling with the `XbergError` enum |
***
## Rendering Pipeline
[Section titled “Rendering Pipeline”](#rendering-pipeline)
After extraction, the raw internal document representation is passed through the **RendererRegistry** to produce the final output in the requested content format. Xberg uses a comrak-based AST bridge for GFM Markdown and HTML5 rendering, ensuring high-fidelity output with full table, heading, and list support.
```mermaid
flowchart LR
Extractor["Extractor"] --> Result["ExtractedDocument"]
Result --> RR["RendererRegistry"]
RR --> GFM["GFM Markdown"]
RR --> HTML["HTML5"]
RR --> Djot["Djot"]
RR --> Plain["Plain Text"]
RR --> Custom["Custom Renderer"]
style RR fill:#c8e6c9,stroke:#2e7d32
style ID fill:#bbdefb,stroke:#1565c0
```
The RendererRegistry selects the appropriate renderer based on the requested content format (`--content-format`). Built-in renderers cover Markdown (GFM via comrak), HTML5 (also via comrak), Djot, and plain text. Custom renderers can be registered through the plugin system to support additional output formats.
***
## Reranking
[Section titled “Reranking”](#reranking)
Reranking is a query-time operation separate from the extraction pipeline. After retrieving candidate documents (typically from a vector database), reranking uses cross-encoder models to jointly score (query, document) pairs and reorder by relevance.
Reranking is not part of extraction — it sits downstream for RAG workflows. The `rerank()` API accepts a query and list of documents, runs them through a RerankerBackend (preset ONNX model, custom HuggingFace model, LLM API, or plugin), and returns sorted `RerankedDocument` results with scores.
The RerankerRegistry manages backends by name (e.g., `"fast"`, `"my-llama-reranker"`), allowing runtime registration and selection. See [Reranking Concepts](/guides/reranking/) for preset details.
***
## Why Rust?
[Section titled “Why Rust?”](#why-rust)
**Speed.** Rust compiles to native machine code with LLVM optimizations. PDF parsing uses xberg-native-pdf — a pure-Rust library with no system-library overhead. Text processing uses SIMD instructions to handle multiple characters per CPU cycle. Batch extraction runs on all CPU cores through Tokio’s async runtime.
**Safety.** Rust’s type system and ownership model catch entire categories of bugs at compile time. No null pointer exceptions, no data races, no buffer overflows, no use-after-free. If it compiles, those runtime errors can’t happen.
**Real concurrency.** Unlike Python (limited by the GIL), Rust executes on all available cores simultaneously. Tokio’s work-stealing scheduler distributes async tasks efficiently. File I/O is non-blocking, so threads never stall waiting on disk.
For detailed performance analysis, see [Performance](/guides/development/#performance).
***
## Using Xberg from Rust
[Section titled “Using Xberg from Rust”](#using-xberg-from-rust)
The Rust core is a standalone library. You don’t need Python or Node.js to use it:
main.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig::default();
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
if let Some(document) = output.results.first() {
println!("Extracted: {}", document.content);
}
Ok(())
}
```
This makes Xberg a fit for Rust-native applications, command-line tools, high-performance API servers, and embedded systems where Python or Node.js aren’t practical.
***
## What to Read Next
[Section titled “What to Read Next”](#what-to-read-next)
* [Extraction Pipeline](/concepts/extraction-pipeline/) - how files flow through the system stage by stage
* [Plugin System](/concepts/plugin-system/) - extending Xberg with custom extractors, OCR backends, and processors
* [Performance](/guides/development/#performance) - why Rust matters for extraction performance
* [Creating Plugins](/guides/plugins/) - step-by-step plugin development guide
# Extraction Pipeline
Every file Xberg processes follows the same multi-stage pipeline. A PDF, a scanned image, a spreadsheet, an email attachment: they all enter at the top and come out as a structured `ExtractedDocument` inside an `ExtractionResult` envelope. The stages run in a fixed order, but several of them are conditional. Caching can short-circuit the entire flow. OCR only runs when images are present. Post-processing steps only fire if you’ve configured them.
This page walks through each stage in detail so you understand what happens to your file, when, and why.
***
## How the Pipeline Works
[Section titled “How the Pipeline Works”](#how-the-pipeline-works)
```mermaid
flowchart TD
Input(["Input: URI or raw bytes"]):::input
Input --> S1["1. Cache Lookup \nHash file + config, check for stored result"]
S1 -->|Cache hit| FastReturn(["Return cached ExtractedDocument"]):::cached
S1 -->|Cache miss| S2["2. MIME Detection \nResolve file type from extension or explicit param"]
S2 --> S3["3. Registry Lookup \nFind the right DocumentExtractor for this MIME type"]
S3 --> S4["4. Format Extraction \nRun the extractor: PDF, Excel, image, email, etc."]
S4 --> S5{"5. OCR \nImages present\nand OCR enabled?"}
S5 -->|Yes| OCR["Run OCR backend\n(Tesseract / PaddleOCR / Sceptre / VLM)"]
S5 -->|No| S6
OCR --> S6["6. Validators \nCheck result meets requirements"]
S6 --> S7["7. Quality + Chunking \nScore quality, split into chunks"]
S7 --> S8["8. Post-Processors \nTransform result (Early → Middle → Late)"]
S8 --> S9["9. Cache Store \nSave result for future lookups"]
S9 --> Output(["Return ExtractionResult envelope"]):::output
classDef input fill:#e3f2fd,stroke:#1565c0,color:#0d47a1
classDef output fill:#e8f5e9,stroke:#2e7d32,color:#1b5e20
classDef cached fill:#fff8e1,stroke:#f9a825,color:#e65100
```
The diagram above shows every stage in sequence. Let’s break each one down.
***
## 1. Cache Lookup
[Section titled “1. Cache Lookup”](#1-cache-lookup)
When caching is enabled (`cache=True` in your `ExtractionConfig`), the pipeline starts by computing a hash from the file’s content and your configuration. If a result with that exact hash already exists in the cache, it’s returned immediately. No extraction, no OCR, no post-processing. The entire pipeline is skipped.
This is significant for workloads that reprocess the same files. Repeated extractions of the same document go from hundreds of milliseconds to single-digit milliseconds.
Cache keys are content-based, not path-based. If you rename a file but the bytes are identical, the cache still hits. If you change your config (switch OCR backends, adjust chunking), a new cache key is generated so stale results are never returned.
***
## 2. MIME Detection
[Section titled “2. MIME Detection”](#2-mime-detection)
Before Xberg can extract anything, it needs to know what format the file is. It resolves the MIME type through one of two paths:
* **Explicit:** You pass `mime_type="application/pdf"` and Xberg validates it against the list of supported types.
* **Auto-detection:** Xberg reads the file extension (for example, `.pdf` → `application/pdf`) from an internal mapping table.
If the resolved MIME type isn’t in the supported list, the pipeline stops immediately with an `UnsupportedFormat` error. No compute is wasted on files Xberg can’t handle.
For the full details on how extension mapping, normalization, and validation work, see [Format Support](/reference/formats/).
***
## 3. Registry Lookup
[Section titled “3. Registry Lookup”](#3-registry-lookup)
With the MIME type resolved, Xberg queries the extractor registry to find the `DocumentExtractor` that handles this format. The registry is a map from MIME types to extractor implementations, managed by the [plugin system](/concepts/plugin-system/).
If multiple extractors are registered for the same MIME type (for example, you registered a custom PDF extractor alongside the built-in one), the one with the higher `priority()` value is selected. Built-in extractors default to a priority of 50 (0-25 is reserved for fallback/low-quality extractors, 51-100 for premium or specialized ones), so a custom extractor needs a priority above 50 to take precedence over the built-in default.
registry\_lookup.rs
```rust
let registry = get_document_extractor_registry();
let extractor = registry.get("application/pdf")?;
```
***
## 4. Format Extraction
[Section titled “4. Format Extraction”](#4-format-extraction)
This is the core of the pipeline. The selected extractor reads the file and produces an `ExtractedDocument` containing the extracted text, metadata (author, title, creation date), page count, and detected language.
Each file format has a tailored extraction strategy:
| Format | What happens |
| ---------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **PDF** | Text is extracted directly from the PDF text layer using xberg’s native PDF engine (pure Rust). If the PDF contains embedded images (scanned pages, diagrams), those images are collected and passed to the OCR stage. |
| **Excel / Spreadsheets** | Each sheet is parsed individually using calamine. Cell values are assembled into structured Markdown tables, preserving column alignment. |
| **Images** (JPEG, PNG, TIFF, etc.) | The image bytes are loaded into memory and forwarded directly to the OCR backend. There is no text layer to extract from an image. |
| **XML / Plain text** | A streaming parser processes the file incrementally. This keeps memory usage constant even for multi-gigabyte files because the entire file is never loaded at once. |
| **Email** (`.eml`, `.msg`) | The MIME structure is parsed. The email body (plain text or HTML) is extracted as the main content. Attachments are extracted recursively using the same pipeline. |
| **Office** (DOCX, PPTX) | The file is a ZIP archive containing XML. Xberg opens the archive, locates the content XML parts, and parses the document structure into text. |
The extracted document at this point contains raw extracted text. It hasn’t been validated, scored, or chunked yet.
***
## 5. OCR (Conditional)
[Section titled “5. OCR (Conditional)”](#5-ocr-conditional)
OCR runs only when two conditions are true: the file contains images (or is an image itself), and OCR is enabled in the configuration. Even when both conditions are met, Xberg applies a third check: if the format extractor already produced text, OCR is skipped. This avoids redundant processing on PDFs that have a searchable text layer.
You can override this behavior with `force_ocr=True`, which tells Xberg to always run OCR regardless of whether text was already extracted. This is useful for PDFs where the text layer is unreliable or incomplete.
Conversely, `disable_ocr=True` skips OCR entirely. Image files that would normally require OCR return empty content instead of raising a `MissingDependencyError`. This is useful when you want to extract text from non-image formats only and avoid OCR overhead or dependency requirements.
```mermaid
flowchart LR
A{"Images present?"} -->|No| Skip(["Skip OCR"])
A -->|Yes| B{"force_ocr?"}
B -->|Yes| Run["Run OCR backend"]
B -->|No| C{"Text already\nextracted?"}
C -->|Yes| Skip
C -->|No| Run
Run --> Merge["Merge OCR output\nwith extracted text"]
style Skip fill:#f5f5f5,stroke:#bdbdbd
style Run fill:#e8f5e9,stroke:#2e7d32
```
Xberg ships multiple OCR backends:
| Backend | Engine | When to use it |
| ------------- | -------------------- | ---------------------------------------------------------------------------------------- |
| **Tesseract** | Native Rust bindings | Default. Fast, solid accuracy for Latin scripts. Good general-purpose choice. |
| **PaddleOCR** | ONNX Runtime | Best accuracy for Chinese, Japanese, Korean (CJK) scripts. Runs natively without Python. |
| **Sceptre** | ORT or tract | EasyOCR Gen2 CRAFT and CRNN pipeline with structured line geometry and confidence. |
| **VLM OCR** | liter-llm providers | Best for handwriting, poor scans, and complex layouts. Requires a vision-capable model. |
When OCR completes, the OCR output is merged with any text the format extractor already produced. The merged result moves to post-processing.
***
## 6. Validators
[Section titled “6. Validators”](#6-validators)
Validators are the first post-processing step. They inspect the `ExtractedDocument` and decide whether it meets your requirements. If a validator rejects the result, the pipeline stops immediately and the error is returned to the caller. No further processing happens.
This is intentionally strict. Validators exist to catch results that are fundamentally wrong (empty text, garbled output, suspiciously short content) before downstream systems consume them.
example\_validator.py
```python
class MinLengthValidator:
def validate(self, result, config):
if len(result.content) < 100:
raise ValidationError("Extracted text too short")
```
You register validators through the plugin system. See [Plugin System](/concepts/plugin-system/) for details.
***
## 7. Quality Scoring + Chunking
[Section titled “7. Quality Scoring + Chunking”](#7-quality-scoring--chunking)
These two steps run after validation.
**Quality scoring** is optional. When `enable_quality_processing=True`, Xberg analyzes the retained text and assigns a cleanliness/readability score between 0.0 and 1.0. The score penalizes OCR artifacts, embedded script/style noise, and navigation chrome; it rewards sentence and paragraph structure, multiple paragraphs, and punctuation, with an optional metadata bonus. It is not a completeness or recall score: clean text can score highly even when other content was omitted. The result is stored in `result.quality_score`; inspect `result.processing_warnings` separately for known degraded or partial extraction.
**Chunking** is also optional. When you provide a `ChunkingConfig`, the extracted text is split into overlapping fragments with configurable maximum size and overlap. Each chunk records its start and end offset relative to the original text.
chunking\_config.py
```python
config = ExtractionConfig(
chunking=ChunkingConfig(max_chars=1000, max_overlap=100)
)
# result.chunks → list of Chunk objects with .text, .start_offset, .end_offset
```
Chunking is designed for RAG (Retrieval-Augmented Generation) pipelines. The overlap ensures that context at chunk boundaries isn’t lost when chunks are embedded and retrieved independently.
***
## 8. Post-Processors
[Section titled “8. Post-Processors”](#8-post-processors)
Post-processors are the final transformation step. They receive the `ExtractedDocument` and can modify it in any way: clean up text, extract entities, redact sensitive content, reformat output, or add custom metadata.
Post-processors run in three ordered stages so you can control what happens first:
| Stage | Purpose | Examples |
| ---------- | --------------------- | ----------------------------------------------------------------------------------------- |
| **Early** | Raw text cleanup | Strip control characters, fix encoding issues, normalize whitespace |
| **Middle** | Content analysis | NER, summarisation, translation, page classification, image captioning, QR-code detection |
| **Late** | Final transformations | Output formatting, [redaction & anonymisation](/guides/redaction/) |
The seven OSS v5 enrichment processors all register through the shared `register_builtin()` umbrella (`crates/xberg/src/plugins/processor/builtin/mod.rs`) behind their feature gates: `ner`, `redaction`, `summarization`, `translation`, `classification`, `captioning`, `qr-codes`. Each is feature-gated and registered only when its Cargo feature is active.
An important design choice: **post-processor errors do not fail the extraction.** If a post-processor throws an exception, the error is logged and the pipeline continues with the result as-is. This means a buggy post-processor can’t take down your extraction pipeline.
Redaction runs Late by design: it must see the populated `entities`, `summary`, `translation`, and `page_classifications` fields so it can rewrite their textual content before the result leaves Xberg. The original pre-redaction text is dropped at the end of the pipeline; only `ExtractedDocument.redaction_report` carries byte offsets back into the original.
***
## 9. Cache Store + Return
[Section titled “9. Cache Store + Return”](#9-cache-store--return)
If caching is enabled and the extraction completed without errors, the result is written to the cache for future lookups.
Each final `ExtractedDocument` returned in `ExtractionResult.results` contains:
* **`content`** - the fully processed text
* **`metadata`** — format-specific metadata (author, title, creation date, page count, etc.)
* **`chunks`** — optional list of text chunks with offsets (if chunking was configured)
* **`quality_score`** — optional quality assessment (if quality processing was enabled)
* **Processing history** — a trace of which stages ran, useful for debugging
***
## Error Handling Strategy
[Section titled “Error Handling Strategy”](#error-handling-strategy)
The pipeline follows a deliberate error strategy: fail early for things the developer can fix, be resilient for things that are beyond their control.
| Stage | Error type | What happens |
| ----------------- | --------------------------------------------------------- | ------------------------------------------------------------------------------------ |
| MIME detection | `UnsupportedFormat` | Pipeline stops. The file type isn’t supported. |
| Format extraction | `ParsingError` | Pipeline stops. The file is corrupt or the format couldn’t be parsed. |
| Validators | `ValidationError` | Pipeline stops. The result didn’t meet your defined requirements. |
| Post-processors | Non-fatal processor error | Error is logged. Pipeline continues. Result is returned without that transformation. |
| System | I/O failure, out-of-memory, or other system-level failure | Always propagated. These indicate infrastructure problems. |
For the complete error taxonomy, see [Error Handling](/reference/errors/).
***
## Built-in Optimizations
[Section titled “Built-in Optimizations”](#built-in-optimizations)
The pipeline includes several optimizations that run automatically without configuration:
* **Cache short-circuits** bypass every processing stage when a cached result exists
* **Lazy OCR** avoids redundant OCR when the format extractor already produced usable text
* **Streaming parsers** process XML, text, and archive files incrementally with constant memory
* **Parallel batching** with `extract_batch` distributes files across all CPU cores via Tokio
* **Shared async runtime** reuses a single Tokio runtime across calls, avoiding repeated initialization
***
## What to Read Next
[Section titled “What to Read Next”](#what-to-read-next)
* [Architecture](/concepts/architecture/) — how the system is designed
* [Plugin System](/concepts/plugin-system/) — building custom extractors, OCR backends, and processors
* [Format Support](/reference/formats/) — how file types are identified
* [Configuration Guide](/guides/configuration/) — tuning the pipeline
* [OCR Guide](/guides/ocr/) — configuring OCR backends
# Platform Support
This page mirrors [`PLATFORM_SUPPORT.md`](https://github.com/xberg-io/xberg/blob/main/PLATFORM_SUPPORT.md) at the repository root. That file is the canonical source — it is derived from the build matrices in `.github/workflows/publish.yaml`. Update the root file first, then re-sync this page.
Legend: ✅ prebuilt shipped · ❌ not shipped · — not applicable
## Desktop / server
[Section titled “Desktop / server”](#desktop--server)
| Binding (registry) | Linux x64 (glibc) | Linux arm64 (glibc) | Linux x64 (musl) | Linux arm64 (musl) | macOS arm64 | macOS x64 (Intel) | Windows x64 |
| -------------------------------- | ----------------- | ------------------- | ---------------- | ------------------ | ----------- | ----------------- | ----------- |
| **CLI** (standalone + npm proxy) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| **Java** (Maven Central) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| **C#** (NuGet) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| **Elixir** (Hex) | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| **Node** (npm) | ✅ | ✅ | ✅ | ✅ | ✅ | ❌ ¹ | ✅ |
| **Python** (PyPI) | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **Go** (module + C FFI) | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **PHP** (Composer / PIE) ² | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **Dart** (pub.dev) ³ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **C FFI** (GitHub release) | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **Zig** (Zig package) ⁴ | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ✅ |
| **Ruby** (RubyGems) | ✅ | ✅ | ❌ | ❌ | ✅ | ✅ | ❌ |
## Apple / mobile / portable
[Section titled “Apple / mobile / portable”](#apple--mobile--portable)
| Binding (registry) | macOS arm64 | iOS arm64 | Android arm64-v8a | Android x86\_64 | wasm32 |
| -------------------------------------- | ----------- | --------- | ----------------- | --------------- | ------ |
| **Swift** (SwiftPM artifactbundle) ⁵ | ✅ | ✅ | — | — | — |
| **Kotlin / Android** (Maven Central) ⁶ | — | — | ✅ | ✅ | — |
| **WASM** (npm) | — | — | — | — | ✅ ⁷ |
## Known gaps and rationale
[Section titled “Known gaps and rationale”](#known-gaps-and-rationale)
1. **Node - macOS x64 (Intel) - dropped (rc.23).** pyke ships no static x64-mac ORT, and Microsoft’s last x86\_64-macOS ONNX Runtime dylib is 1.23.2 (the CLI vendors that one), so at the time CI provisioned ORT via Homebrew, whose bottle dynamically links a \~252-lib abseil closure at absolute Homebrew paths. The self-containment vendor step (`scripts/ci/vendor-macos-node-dylibs.sh`) correctly rejected the non-portable package, and the Intel-mac node leg was dropped. Intel Mac users run the arm64 binding under Rosetta or use the WASM package. In rc.22 this leg failed (so no node package published at all); the drop lands in rc.23.
2. **PHP** builds against 8.3, 8.4, and 8.5 on every listed platform.
3. **Dart** ships the server-mode native; the full pub.dev package has a known size blocker (all-platform natives exceed the 100 MB cap) tracked separately in the release notes.
4. **Zig** consumes the C FFI GitHub-release artifacts, so its platform coverage equals C FFI’s.
5. **Swift** targets Apple platforms only: macOS (Apple Silicon) and iOS (arm64). Intel-mac and iOS-simulator-x86\_64 are excluded; no Linux or Windows SwiftPM artifact ships.
6. **Kotlin/Android** ships the two Android ABIs: `arm64-v8a` (devices) and `x86_64` (emulator). Both ABIs build with the same ORT-free `android-target` feature set (no PaddleOCR-via-ORT or ONNX Runtime embeddings on either ABI); there is no separate ORT-enabled build for arm64 devices. RT-DETR layout detection, the wired/wireless table classifier, PaddleOCR, and document-orientation detection run on both ABIs through the pure-Rust `tract` engine (see note 8) instead of ORT.
7. **WASM** is a single `wasm32` artifact, portable across any WASM runtime (browser and Node). It uses the `wasm-target` feature set (`ocr-wasm`, `excel-wasm`, `layout-tract`, `auto-rotate-tract`, `ner-candle-wasm`; no native ORT). Tree-sitter code intelligence is **excluded**: the 371-language grammar pack pushes the `.wasm` past the 50 MB per-file limit of public CDNs (jsDelivr), so source files extract as text but are not parsed. Layout detection and document-orientation run through the pure-Rust `tract` engine (see note 8). Named-entity recognition runs in the browser through the pure-Rust candle GLiNER2 backend (see note 9).
8. **Pure-Rust `tract` engine.** Where a target cannot link native ONNX Runtime, xberg’s inference seam can compile select ONNX models against the pure-Rust `tract` engine (`tract-onnx`, no native library, CPU-only) instead. Document-orientation detection (`auto-rotate-tract`) and RT-DETR layout detection (plus the wired/wireless table classifier, with the `pdf` feature) run this way, matching ONNX Runtime within 5e-3 on their outputs. Both are enabled for `android-target` (so the x86\_64 Android emulator detects page orientation and layout for the first time) and for `wasm-target`: the WASM build exposes `detectLayout` / `detectOrientation`, which take the `.onnx` weights as streamed bytes (the JS host fetches them and hands them to the seam). PaddleOCR, TATR, SLANeXT, and PP-DocLayout-V3 remain ONNX Runtime-only.
9. **In-browser entity detection.** The WASM build exposes `NerModel`, which runs GLiNER2 named-entity recognition entirely inside the page — no server round-trip and no ONNX Runtime, through the pure-Rust candle backend (`ner-candle-wasm`, the no-tokio sibling of the native `ner-candle`). Weights are not embedded in the `.wasm`; the host fetches the safetensors, tokenizer, and encoder config and passes the bytes to `NerModel.load`. Unlike the byte-oriented `detectLayout` / `detectOrientation` functions, the model stays resident across calls, so the weights are parsed once. Inference is synchronous CPU work on a single-threaded target — run it in a Web Worker if main-thread responsiveness matters.
## Cross-cutting gaps
[Section titled “Cross-cutting gaps”](#cross-cutting-gaps)
* **musl (Alpine / static Linux):** shipped only by CLI, Java, C#, Elixir, and Node. Python, Ruby, Go, PHP, Dart, C FFI, and Zig ship glibc-only Linux; musl consumers must build from source.
* **Windows:** every desktop binding ships Windows x64 except Ruby (no RubyGems Windows native) and the Apple/mobile/wasm bindings (not applicable).
* **Intel Mac (macOS x64):** shipped by most bindings; not by Node (see gap 1) or Swift.
* **Linux arm64 musl** exists only where full musl is listed (CLI, Java, C#, Elixir, Node).
# Plugin System
Xberg’s extraction pipeline is entirely plugin-driven. Every format extractor, OCR engine, post-processor, validator, and renderer is a plugin that registers itself into a typed registry. The pipeline queries these registries at each stage to find the right handler. You extend Xberg by writing your own plugin and registering it. The pipeline picks it up automatically.
This page explains the six plugin categories, the registry mechanism, the plugin lifecycle, and how plugins work across language boundaries. `RerankerBackend` plugins serve query-time ranking; the other categories participate in extraction.
***
## Overview
[Section titled “Overview”](#overview)
The plugin system has three layers: plugins, registries, and the pipeline. Plugins implement a trait. Registries store them by key (MIME type, name, or processing stage). The pipeline queries the registries during extraction.
```mermaid
flowchart TB
subgraph layer1 ["You write plugins"]
direction LR
E["DocumentExtractor\nHandles a file format "]
O["OcrBackend\nRuns OCR on images "]
RB["RerankerBackend\nScores search results "]
V["Validator\nRejects bad results "]
P["PostProcessor\nTransforms results "]
R["Renderer\nFormats output "]
end
subgraph layer2 ["Registries store them"]
direction LR
ER["Extractor Registry\nMIME type → extractor "]
OR["OCR Registry\nname → backend "]
RBR["Reranker Registry\nname → backend "]
VR["Validator Registry\nname → validator "]
PR["Processor Registry\nstage → processors "]
RR["Renderer Registry\nname → renderer "]
end
subgraph layer3 ["Pipeline uses them"]
direction LR
P1["Format\nextraction"]
P2["OCR"]
P3["Validation"]
P4["Post-\nprocessing"]
P5["Rendering"]
P6["Reranking"]
end
E --> ER
O --> OR
RB --> RBR
V --> VR
P --> PR
R --> RR
ER --> P1
OR --> P2
VR --> P3
PR --> P4
RR --> P5
RBR --> P6
style ER fill:#bbdefb,stroke:#1565c0
style OR fill:#c8e6c9,stroke:#2e7d32
style VR fill:#ffccbc,stroke:#d84315
style RBR fill:#d7ccc8,stroke:#5d4037
style PR fill:#fff9c4,stroke:#f9a825
style RR fill:#e1bee7,stroke:#7b1fa2
```
You register a plugin once. From that point on, the pipeline uses it wherever the MIME type, name, or stage matches. No wiring, no config files, no boilerplate.
***
## The Six Plugin Categories
[Section titled “The Six Plugin Categories”](#the-six-plugin-categories)
### DocumentExtractor
[Section titled “DocumentExtractor”](#documentextractor)
A `DocumentExtractor` teaches Xberg how to extract text from a specific file format. It declares supported MIME types and provides async methods to extract from file paths or raw bytes.
See [`DocumentExtractor`](/reference/types/) for the trait signature.
Xberg ships with built-in extractors for PDF, Excel, images (routed to OCR), XML, plain text, email, and Office formats (DOCX, PPTX).
**Priority resolution.** When two extractors are registered for the same MIME type, the one with the higher `priority()` value wins. Every built-in extractor defaults to a priority of 50. To override the built-in PDF extractor with your own, register yours with a higher priority:
override\_builtin.rs
```rust
impl DocumentExtractor for BetterPDFExtractor {
fn priority(&self) -> i32 { 100 }
// ...
}
```
Now when the pipeline encounters `application/pdf`, it selects `BetterPDFExtractor` instead of the default.
***
### OcrBackend
[Section titled “OcrBackend”](#ocrbackend)
An `OcrBackend` performs optical character recognition on image data. It declares supported languages and provides async methods to process image bytes or files.
See [`OcrBackend`](/reference/types/) for the trait signature.
Multiple backends ship out of the box:
| Backend | Engine | Strengths |
| ------------- | -------------------- | -------------------------------------------------------------------------------- |
| **Tesseract** | Native Rust bindings | Fast, general-purpose, default backend. Good accuracy for Latin scripts. |
| **PaddleOCR** | ONNX Runtime | Best accuracy for CJK (Chinese, Japanese, Korean) scripts. No Python dependency. |
| **Sceptre** | ORT or tract | EasyOCR Gen2 CRAFT and CRNN pipeline with line geometry and confidence. |
| **VLM OCR** | liter-llm providers | Vision-model OCR for handwriting, poor scans, and complex layouts. |
You can register your own OCR backend (for example, a cloud-based API, a custom model) using the same trait.
***
### RerankerBackend
[Section titled “RerankerBackend”](#rerankerbackend)
A `RerankerBackend` scores (query, document) pairs jointly for query-time relevance ranking. It declares a backend name and provides an async method to rank documents.
See [`RerankerBackend`](/reference/types/) for the trait signature.
Four friendly presets ship out of the box, aliasing an underlying catalog of ONNX cross-encoder models:
| Preset | Resolves to | Strengths |
| ---------------- | ------------------------- | ------------------------------------------------------------------------------------- |
| **fast** | jina-reranker-v1-turbo-en | \~37M params, 8192 max-len, low-latency English reranking. |
| **balanced** | ettin-reranker-150m | 150M params, ModernBERT long-context, English, high quality at cross-encoder latency. |
| **quality** | bge-reranker-v2-m3 | 568M params, 100+ languages, 8192 max-len. |
| **multilingual** | bge-reranker-v2-m3 | Same model as `quality` — 568M params, 100+ languages, 8192 max-len. |
The catalog also exposes `bge-reranker-base` (278M params, English/Chinese) and `qwen3-reranker-0.6b` (generative reranker, multilingual) directly by name.
Custom backends can wrap HuggingFace models, LLM APIs (Cohere, Jina, Voyage), or domain-specific rerankers. Unlike extraction, reranking is not part of the extraction pipeline — it’s a query-time operation for RAG workflows to reorder retrieved documents before LLM context.
***
### PostProcessor
[Section titled “PostProcessor”](#postprocessor)
A `PostProcessor` transforms extraction results after the main extraction and OCR stages are complete. Each processor declares a processing stage that determines its execution order.
See [`PostProcessor`](/reference/types/) for the trait signature.
The three stages execute in fixed order:
| Stage | Runs | Purpose | Examples |
| -------- | ------ | -------------------- | --------------------------------------------------------------- |
| `Early` | First | Clean up raw text | Strip control characters, fix encoding, normalize whitespace |
| `Middle` | Second | Analyze content | Extract named entities, detect language, classify document type |
| `Late` | Third | Final output shaping | Format output, generate summaries, redact PII |
**Error handling:** Post-processor errors do not fail the extraction. Errors are logged and the pipeline continues unchanged, ensuring no processor can take down extraction.
***
### Validator
[Section titled “Validator”](#validator)
A `Validator` inspects extraction results and can reject them if they don’t meet requirements. Unlike post-processors, validator errors stop the pipeline immediately — they’re a hard gate.
See [`Validator`](/reference/types/) for the trait signature.
Two common validator patterns:
example\_validators.py
```python
class MinimumLengthValidator:
"""Reject extractions that produce less than 100 characters."""
def validate(self, result, config):
if len(result.content) < 100:
raise ValidationError("Text too short")
class QualityThresholdValidator:
"""Reject extractions with a quality score below 0.5."""
def validate(self, result, config):
if (result.quality_score or 0.0) < 0.5:
raise ValidationError("Quality below threshold")
```
Validators run before post-processors. This means you can catch and reject bad results before any transformation work happens.
***
### Renderer
[Section titled “Renderer”](#renderer)
A `Renderer` converts an extraction result into a specific output format. It declares a name and provides a render method.
```rust
pub trait Renderer: Send + Sync {
fn name(&self) -> &str;
fn render_result(&self, result: &ExtractedDocument) -> Result;
}
```
Xberg ships with four built-in renderers:
| Renderer | Output | Description |
| ------------ | ------------ | ------------------------------------------------------------------------ |
| **Markdown** | GFM Markdown | GitHub Flavored Markdown via comrak AST bridge. Tables, headings, lists. |
| **HTML** | HTML5 | Full HTML5 rendering via comrak. |
| **djot** | Djot | Djot markup format. |
| **plain** | Plain text | Raw text with no markup. |
To register a custom renderer:
custom\_renderer.rs
```rust
use xberg::plugins::registry::get_renderer_registry;
use std::sync::Arc;
let registry = get_renderer_registry();
let mut registry = registry.write().unwrap();
registry.register(Arc::new(MyCustomRenderer))?;
```
Custom renderers participate in the pipeline just like built-in ones. When the user requests your renderer’s name via `--content-format`, the RendererRegistry dispatches to your implementation.
***
## Plugin Lifecycle
[Section titled “Plugin Lifecycle”](#plugin-lifecycle)
Every plugin follows the same lifecycle from creation to shutdown.
```mermaid
stateDiagram-v2
[*] --> Created: new()
Created --> Registered: registry.register()
Registered --> Active: initialize()
Active --> Active: called by pipeline
Active --> [*]: shutdown()
```
See [`Plugin`](/reference/types/) for the base trait signature.
Key behaviors: `initialize()` is called lazily the first time the plugin is used, not at registration. This avoids startup overhead for plugins that may never be invoked. `shutdown()` runs when the plugin is unregistered or on process exit. Both have default no-op implementations — override only if your plugin needs setup or cleanup.
***
## Registering Plugins
[Section titled “Registering Plugins”](#registering-plugins)
Get the appropriate registry for your plugin type and call `register()`. Once registered, the pipeline automatically dispatches to your plugin based on MIME type (extractors), backend name (OCR), processing stage (post-processors), or validator name.
***
## Cross-Language Plugins
[Section titled “Cross-Language Plugins”](#cross-language-plugins)
Plugins written in Python can integrate directly with the Rust extraction pipeline via PyO3 FFI. The bridge layer handles all type conversion automatically.
```mermaid
sequenceDiagram
participant P as Python Plugin
participant B as PyO3 Bridge
participant R as Rust Pipeline
P->>B: register(plugin)
B->>R: Store as Arc
Note over R: During extraction...
R->>B: extract(input, config)
B->>P: Call plugin.extract()
P-->>B: Return result as dict
B-->>R: Convert to ExtractedDocument
```
Type mapping: `Vec` ↔ `bytes`, `String` ↔ `str`, Rust structs ↔ Python dataclasses. Large buffers use Python’s buffer protocol to minimize copying.
***
## Thread Safety
[Section titled “Thread Safety”](#thread-safety)
All plugins must implement `Send + Sync` because the extraction pipeline invokes them concurrently from Tokio’s worker thread pool. For mutable internal state, use `Mutex`, `RwLock`, or atomic types. The compiler will enforce this requirement.
***
## Plugin Discovery
[Section titled “Plugin Discovery”](#plugin-discovery)
Plugins can be registered in two ways:
1. **Built-in** — automatically registered when Xberg initializes. These are the default extractors, OCR backends, and processors. The seven OSS v5 enrichment processors (NER, redaction, summarisation, translation, page classification, image captioning, QR-code detection) all register through the shared `register_builtin()` umbrella in `crates/xberg/src/plugins/processor/builtin/mod.rs`. Each is gated behind its Cargo feature (`ner`, `redaction`, `summarization`, `translation`, `classification`, `captioning`, `qr-codes`) and only joins the registry when the feature is active.
2. **Programmatic** — registered manually via the registry API at runtime.
***
## What to Read Next
[Section titled “What to Read Next”](#what-to-read-next)
* [Creating Plugins](/guides/plugins/) — step-by-step guide to building a custom plugin
* [Extraction Pipeline](/concepts/extraction-pipeline/) — where each plugin type fits in the extraction flow
* [Architecture](/concepts/architecture/) — overall system design
* [API Reference](/reference/api-python/) — plugin API documentation
# Retrieval Modes
Xberg supports four retrieval primitives — dense embeddings, sparse (SPLADE) embeddings, ColBERT late-interaction, and cross-encoder reranking — plus a hybrid mode that fuses the first three with reciprocal rank fusion (RRF). Each primitive is a separate model family with its own trade-offs; pick based on latency budget, index size, and accuracy requirements.
## Dense embeddings
[Section titled “Dense embeddings”](#dense-embeddings)
A single-vector embedding per text, compared by cosine similarity or dot product. This is the fastest retrieval primitive — a vector index (HNSW, IVF, brute-force KNN) scales to millions of documents with sub-millisecond lookups. The cost is that queries and documents are encoded independently, so the model never sees them together.
Configure via `EmbeddingConfig` (`EmbeddingModelType::Preset { name }`):
| Preset | Dimensions | Pooling | Context | Notes |
| ---------------------- | ---------- | ---------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------- |
| `gte-modernbert-base` | 768 | cls | 8192 | Default. General-purpose English RAG with long-context ModernBERT tokenization. |
| `fast` | 384 | mean | — | all-MiniLM-L6-v2 quantized. Prototyping, resource-constrained environments. |
| `balanced` | 768 | cls | — | BGE-base-en-v1.5. General-purpose production RAG. |
| `quality` | 1024 | cls | — | BGE-large-en-v1.5. Maximum accuracy, higher compute. |
| `multilingual` | 768 | mean | — | multilingual-e5-base. 100+ languages. |
| `lightweight` | 256 | mean | — | potion-base-8M (model2vec). Pure-Rust static backend — no ONNX Runtime. Runs on WASM, Android, and other no-ORT targets. |
| `arctic-embed-m-v2.0` | 768 | cls | — | Snowflake Arctic-Embed-M v2.0, multilingual. Asymmetric: queries are auto-prefixed `"query: "`; document text is embedded verbatim. |
| `qwen3-embedding-0.6b` | 1024 | last-token | 32k | Decoder-style model. Highest-quality multilingual/long-context retrieval when compute allows. |
Use `lightweight` when ONNX Runtime is unavailable or undesirable (WASM bundles, Android x86\_64 emulator, minimal-dependency deployments). Use `arctic-embed-m-v2.0` or `qwen3-embedding-0.6b` when query/document roles are known and long-context or multilingual coverage matters more than raw speed. See [Embeddings](/guides/embeddings/).
## Sparse embeddings (SPLADE)
[Section titled “Sparse embeddings (SPLADE)”](#sparse-embeddings-splade)
A high-dimensional, mostly-zero vocabulary-space vector per text, stored as parallel `(indices, values)` arrays. SPLADE learns term expansion and weighting the way a neural model would, while remaining compatible with inverted-index-style sparse retrieval (BM25-like scoring, but learned rather than heuristic). Sparse retrieval complements dense embeddings: it captures exact-term and rare-term matches that a dense encoder can blur.
Configure via `SparseEmbeddingConfig` (`SparseEmbeddingModelType::Preset { name }`):
* `opensearch-v3-distill` — default. OpenSearch’s distilled SPLADE model.
* `Splade_PP_en_v1` — fallback, English-only.
Sparse embeddings pair naturally with dense embeddings in the hybrid arm below — use sparse alone when you need exact keyword recall (product SKUs, error codes, identifiers) without full-text infrastructure.
## ColBERT late-interaction
[Section titled “ColBERT late-interaction”](#colbert-late-interaction)
A *sequence* of per-token vectors per text (one row per input token, including the ColBERT `[Q]`/`[D]` marker), instead of a single pooled vector. Retrieval scores a query against a document with MaxSim: for each query token, take the maximum dot product over all document token rows, then sum across query rows. This preserves token-level interaction — closer to a cross-encoder’s accuracy — while still allowing precomputed document vectors and index-time scoring.
Configure via `LateInteractionConfig` (`LateInteractionModelType::Preset { name }`):
* `gte-moderncolbert` — default, 128-dim per-token vectors.
* `colbert-small-v1` — fallback, 96-dim.
Late-interaction costs more storage than dense (one vector per token, not per document) and more compute per query (MaxSim over all token pairs), but closes much of the accuracy gap to a full cross-encoder without the reranking pass’s per-candidate latency.
## Reranking (cross-encoders)
[Section titled “Reranking (cross-encoders)”](#reranking-cross-encoders)
Dense, sparse, and late-interaction retrieval are first-pass — they narrow millions of documents to a candidate set. Reranking is the second pass: a cross-encoder scores each `(query, document)` pair jointly, attending across both in every transformer layer, for the most accurate relevance judgment at the cost of one forward pass per candidate.
Configure via `RerankerConfig` (`RerankerModelType::Preset { name }`):
* `ettin-reranker-150m` — default. ModernBERT-based cross-encoder, long-context (up to \~8000 tokens), English.
* `qwen3-reranker-0.6b` — generative alternative. A causal LM repurposed as a reranker: relevance is read off the last token’s “yes”/“no” logits, softmaxed into a probability. Higher quality, higher latency than a classic cross-encoder head.
See [Reranking](/guides/reranking/) for the full preset catalog, custom HuggingFace models, and the in-process plugin backend.
## Hybrid retrieval (reciprocal rank fusion)
[Section titled “Hybrid retrieval (reciprocal rank fusion)”](#hybrid-retrieval-reciprocal-rank-fusion)
Xberg has no built-in hybrid retrieval mode. It gives you the arms — dense, sparse, and late-interaction embeddings plus a reranker — and you combine them in your own retrieval layer, alongside whatever full-text index you already run. This section describes the fusion technique; [Retrieval](/guides/retrieval/) shows it implemented by hand.
The usual approach runs up to three arms in parallel — dense vector KNN, full-text/BM25-style search, and sparse SPLADE — then fuses their rankings with Reciprocal Rank Fusion (RRF):
```text
rrf_score(doc) = sum over arms( 1 / (k + rank_in_arm + 1) )
```
Each arm contributes `1 / (k + rank + 1)` to a document’s fused score, where `rank` is that document’s 0-indexed position within the arm’s own result list. Documents missing from an arm simply don’t contribute for that arm — RRF needs no arm-specific score normalization, which is what makes it a robust way to combine dense cosine similarity, BM25-style text scores, and sparse dot products, three otherwise incomparable scales. Results are sorted by fused RRF score descending.
Only the arms you actually run contribute, so a fusion over a full-text index plus `embed_texts` results is as valid as one that also folds in `embed_sparse`. Late-interaction is best kept out of the fusion: `max_sim_score` is a reranking-strength signal over a small candidate set, not a first-pass arm, so run it — or `rerank` — *after* the fusion rather than inside it.
## Choosing a mode
[Section titled “Choosing a mode”](#choosing-a-mode)
| Need | Use |
| ----------------------------------------------------------- | ------------------------------- |
| Fast first-pass retrieval over a large corpus | Dense embeddings |
| Exact-term / rare-term recall (IDs, codes, keywords) | Sparse embeddings |
| Best first-pass accuracy at the cost of storage/compute | ColBERT late-interaction |
| Sharpen a small candidate set before it reaches an LLM | Reranking |
| Combine dense, full-text, and sparse strengths in one query | Fuse the arms yourself with RRF |
# Pure-Rust Inference (tract)
Xberg runs its ML models — layout detection, table classification, document-orientation, OCR — through [ONNX Runtime](https://onnxruntime.ai/) by default. ONNX Runtime is a native library and cannot link on `wasm32` or the Android x86\_64 emulator. On those targets Xberg runs the same models through [`tract`](https://github.com/sonos/tract), Sonos’ pure-Rust ONNX engine, behind a shared inference seam. The `tract` engine loads the identical `.onnx` artifacts (no weight conversion), is CPU-only, and needs no C toolchain.
ONNX Runtime stays the default on every native build. The `tract` engine is selected only where ORT cannot link, and it trades CPU latency for portability — see [Latency](#latency).
## Model coverage
[Section titled “Model coverage”](#model-coverage)
`tract` 0.23.4 does not execute every model Xberg ships. The seam routes each model to whichever engine is active; models tract cannot run stay ONNX Runtime-only and are compiled out of the pure-Rust feature sets (`layout-tract`, `auto-rotate-tract`).
| Model | Role | `tract` |
| ----------------------- | ------------------------------------------------------------- | ---------------------------------- |
| RT-DETR | Layout detection | Runs |
| PP-LCNet | Table classifier, document-orientation, text-line orientation | Runs |
| DBNet / CRNN / AngleNet | PaddleOCR detection / recognition / angle | Runs — see [PaddleOCR](#paddleocr) |
| TATR | Table-structure recognition | ONNX Runtime only |
| PP-DocLayout-V3 | Layout detection | ONNX Runtime only |
| SLANeXt | Table-structure recognition | ONNX Runtime only |
The three ONNX Runtime-only models are blocked by concrete gaps in tract 0.23.4:
* **TATR** is a quantized export. Pinning the input clears the convolution’s symbolic in-channel, but a fused scale constant carries a symbolic batch size the type analyser cannot unify with a concrete `1`.
* **PP-DocLayout-V3** clears its input facts, but tract’s `LayerNormalization` translator then mis-infers the shape of the DETR decoder’s norm layer — an op-translation bug, not a shape-pinning gap.
* **SLANeXt** uses the ONNX `Loop` operator, which tract does not implement.
Revisit each only if a non-quantized export or an upstream tract fix lands.
## Latency
[Section titled “Latency”](#latency)
Measured on Apple Silicon (aarch64), release build, best-of-8 warm inferences. Each engine runs **as Xberg ships it**: ONNX Runtime with its default intra-op thread pool (up to `min(8, cores)` threads), tract single-threaded (the seam configures no tract thread pool). The ratio below is therefore an *as-shipped, wall-clock* comparison — the real cost you pay on a no-ORT build versus native ORT — and an **upper bound** on the pure per-core kernel gap, since part of ORT’s lead is thread parallelism rather than kernel efficiency.
| Model | tract load | ORT load | tract run | ORT run | tract / ORT run |
| ----------------------------- | ---------- | -------- | --------- | ------- | --------------- |
| RT-DETR layout detector | 465 ms | 221 ms | 2637 ms | 137 ms | 19.3× |
| PP-LCNet table classifier | 22 ms | 9 ms | 31.9 ms | 2.2 ms | 14.4× |
| PP-LCNet document-orientation | 22 ms | 8 ms | 31.9 ms | 2.8 ms | 11.5× |
As each engine ships (ORT multi-threaded, tract single-threaded), tract’s pure-Rust CPU path runs roughly 11–19× slower than ONNX Runtime in wall-clock. This is the accepted trade-off: these models run about once per page, and on the targets tract exists for — WASM and the Android x86\_64 emulator, where ONNX Runtime cannot link at all — the alternative is no inference, not ORT. Native builds keep ONNX Runtime, so the regression never reaches native users. RT-DETR’s \~2.6 s per inference is the ceiling to watch for WASM UX; the CNN classifiers at \~32 ms are comfortable.
Reproduce the table with:
```sh
cargo test --release -p xberg --no-default-features --features "layout-detection,auto-rotate,tract" \
--lib inference::tract_backend::tests::tract_vs_ort_latency_report -- --ignored --nocapture
```
## Platform availability
[Section titled “Platform availability”](#platform-availability)
| Target | Engine | Models |
| ------------------------------------------------ | ------------ | ------------------------------------------------------------------------------------------------ |
| Native (desktop, server, Windows, Android arm64) | ONNX Runtime | Full set |
| Android x86\_64 emulator (`android-target`), iOS | tract | RT-DETR layout, table classifier, document-orientation |
| WASM (`wasm-target`) | tract | RT-DETR layout, document-orientation (streamed weights via `detectLayout` / `detectOrientation`) |
## PaddleOCR
[Section titled “PaddleOCR”](#paddleocr)
Shape handling on tract depends on how the plan is built. A plan left symbolic tolerates a new input shape on every call; a plan pinned via `with_input_fact` bakes that exact shape in as a constant and errors on any other. DBNet’s FPN skip connections only optimize when pinned, so DBNet plans are necessarily shape-pinned — and DBNet resizes each page to content-dependent dimensions, so one plan cannot serve every page.
Because a pinned plan corresponds to exactly one shape, padding every page into one fixed square canvas would bound the plan count to one by construction. That is not what Xberg does, and the reason is a measured one: both detection backbones are PP-LCNets carrying `GlobalAveragePool` squeeze-and-excitation blocks (10 in PP-OCRv5 `det/mobile`, 8 in PP-OCRv6 `det/tiny`) which reduce over the **whole** spatial extent. Enlarging the input therefore rescales every channel gate and shifts the probability map across the entire page, not just near the padding seam. On a 791×1024 scan resized to 480×640, padding it into a 640×640 canvas moved the map by up to 0.77 (mean 2.6e-3), flipping 827 of 307 200 pixels across DBNet’s 0.3 binarization threshold and merging two text lines into one region — 59 detected regions became 58, and 29 words were lost end to end.
DBNet plans are therefore pinned to each page’s **own** resized extent and cached by shape (four resident plans, least-recently-used eviction). A document’s pages nearly all resize to the same extent, so the cache is built once and reused; a new extent costs one plan build. With the extents equal, the two engines agree to 5.0e-5 on the probability map and produce identical detection boxes, which is what `xberg`’s `paddle_ocr::tract_parity` suite asserts. CRNN, which batches by content-dependent width, is left symbolic and tolerates varying widths in one plan; AngleNet and the layout CNNs use a fixed resolution and need no special handling either way.
# Contributing Guide
Thank you for your interest in contributing to Xberg! This guide covers everything you need — from picking an issue to getting your pull request merged.
***
## First time contributing?
[Section titled “First time contributing?”](#first-time-contributing)
Welcome! Here’s how to get started:
1. **Pick an issue** that matches your experience level:
* [Good first issue](https://github.com/xberg-io/xberg/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22) — small, well-scoped tasks ideal for newcomers
* [Help wanted](https://github.com/xberg-io/xberg/issues?q=is%3Aissue+is%3Aopen+label%3A%22help+wanted%22) — tasks where we’d especially appreciate community help
2. **Read through the issue** and any existing comments
3. **Leave a comment** letting maintainers know you’d like to work on it
4. **Ask questions** — we’re here to help!
Congratulations — that’s really all it takes to start contributing! Fork, fix, and open a PR. We keep the process simple so you can focus on what matters: the code.
Tip
Start small. A focused contribution you understand well is more valuable than an ambitious one that stalls.
Want to propose a larger change or new feature? [Open an issue](https://github.com/xberg-io/xberg/issues) to discuss it with maintainers first.
***
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
You only need the toolchains for the areas you plan to work on.
**Required for all contributions:**
* [Git](https://git-scm.com/)
* [Task](https://taskfile.dev/installation/) — our task runner for all build and test workflows
* [Rust](https://rustup.rs/) stable (via `rustup`) — required for core and all bindings. The `wasm32-unknown-unknown` target is configured automatically via `rust-toolchain.toml`
**Required for WASM builds:**
* [WASI SDK](https://github.com/WebAssembly/wasi-sdk/releases) — provides a wasm-capable C/C++ compiler needed by tree-sitter and tesseract. Install to `$HOME/wasi-sdk` or set the `WASI_SDK_PATH` environment variable to your install location
**Language-specific toolchains** (only install what you need):
| Language | Version | Tool |
| -------- | ------- | ---------------------------------------- |
| Python | 3.10+ | [`uv`](https://docs.astral.sh/uv/) |
| Node.js | 20+ | [`pnpm`](https://pnpm.io/) |
| Ruby | 3.2+ | `rbenv` or `rvm` |
| Go | 1.26+ | [Official installer](https://go.dev/dl/) |
| Java | 25+ | JDK (via [sdkman](https://sdkman.io/)) |
| .NET | 10+ | `dotnet` |
| PHP | 8.2+ | `composer` |
| Elixir | 1.14+ | `mix` (OTP 25+) |
For platform-specific build dependencies (compilers, OpenSSL, etc.), see the [Installation guide](/getting-started/installation/).
***
## Development setup
[Section titled “Development setup”](#development-setup)
Set up your entire environment with a single command:
Terminal
```bash
task setup
```
This installs all toolchains and dependencies. Safe to re-run anytime.
For building individual language bindings, use the namespace pattern:
Terminal
```bash
task rust:build
task python:build
task node:build
```
***
## Development workflow
[Section titled “Development workflow”](#development-workflow)
### 1. Fork and clone
[Section titled “1. Fork and clone”](#1-fork-and-clone)
Fork the repository on GitHub, then clone your fork:
Terminal
```bash
git clone git@github.com:/xberg.git
cd xberg
git remote add upstream https://github.com/xberg-io/xberg.git
```
### 2. Create a branch
[Section titled “2. Create a branch”](#2-create-a-branch)
Terminal
```bash
git checkout -b feat/your-feature-name main
```
Use a prefix that matches your change type: `feat/`, `fix/`, `docs/`, `perf/`, `chore/`, `test/`.
### 3. Make your changes
[Section titled “3. Make your changes”](#3-make-your-changes)
Keep commits small and focused.
### 4. Run checks
[Section titled “4. Run checks”](#4-run-checks)
Terminal
```bash
task check
```
This runs both linting and formatting checks. For language-specific tests:
Terminal
```bash
task rust:test
task python:e2e
task node:e2e
```
### 5. Commit with conventional messages
[Section titled “5. Commit with conventional messages”](#5-commit-with-conventional-messages)
We use [Conventional Commits](https://www.conventionalcommits.org/). The pre-commit hook validates this.
```text
feat: add PDF table extraction support
fix: handle empty MIME type in archive entries
docs: update Python extraction examples
perf: parallelize layout inference
```
### 6. Update documentation
[Section titled “6. Update documentation”](#6-update-documentation)
When adding user-facing features, update pages under `docs-site/src/content/docs/` and add navigation entries in `docs-site/astro.config.mjs` when needed. Put reusable maintained examples under `docs-site/src/snippets/`; use fixture-backed Alef snippets for shared public APIs.
***
## Issues
[Section titled “Issues”](#issues)
### Finding issues
[Section titled “Finding issues”](#finding-issues)
Browse the [issue tracker](https://github.com/xberg-io/xberg/issues) and filter by labels: `good first issue`, `help wanted`, `bug`, or `enhancement`.
### Reporting a bug
[Section titled “Reporting a bug”](#reporting-a-bug)
Include: what you expected, what happened (with error output), steps to reproduce, your environment (OS, language version, Xberg version), and a minimal sample file if applicable.
### Suggesting improvements
[Section titled “Suggesting improvements”](#suggesting-improvements)
Search for existing issues first. Describe the use case and keep scope focused — break large ideas into smaller, actionable issues.
Filing great issues
Be specific: “PDF tables lose column alignment” is better than “PDF parsing is broken.” Explain impact and link related issues with `#123`.
***
## Submitting a pull request
[Section titled “Submitting a pull request”](#submitting-a-pull-request)
### PR checklist
[Section titled “PR checklist”](#pr-checklist)
Before opening a PR, verify locally:
* [ ] `task check` passes
* [ ] Targeted tests pass
* [ ] Docs updated (if applicable)
* [ ] Commits follow Conventional Commits
### Writing a good PR description
[Section titled “Writing a good PR description”](#writing-a-good-pr-description)
Include **what** changed, **why**, and **how** you tested it. Use `Fixes #123` to auto-close related issues.
Tip
Set your PR to **Draft** while it’s in progress. Maintainers may leave early comments but won’t do a full review until you mark it ready.
### Review and merge
[Section titled “Review and merge”](#review-and-merge)
1. **CI runs** — automated builds and tests across platforms
2. **Maintainers review** — code correctness, style, and design
3. **Feedback rounds** — make requested changes and push
4. **Merge** — once approved with all checks passing
**Merge requirements:** all CI checks pass, at least one maintainer approval, no unresolved conversations, branch up to date with `main`.
Note
Don’t worry about failing CI on your first PR. Maintainers will help you resolve issues.
***
## CI/CD
[Section titled “CI/CD”](#cicd)
Workflows under `.github/workflows/` are split by domain and use path filters, so a pull request runs only the checks relevant to its changes.
| Workflow family | What it verifies |
| ---------------------------------------- | --------------------------------------------------------------------------------- |
| `ci-lint.yaml` | Formatting, linting, governance, generated freshness, and repository policy gates |
| `ci-rust.yaml` | Rust workspace builds and tests on Linux x86\_64, Linux arm64, and macOS |
| `ci-e2e.yaml` | Generated cross-language bindings and end-to-end suites |
| `ci-docs.yaml` | Documentation build and deployment through the shared docs workflow |
| `ci-mobile.yaml`, `ci-gpu.yaml` | Platform-specific mobile and GPU coverage |
| `ci-docker.yaml`, `ci-integrations.yaml` | Container and integration-package coverage |
| `publish*.yaml` | Release preparation and registry-specific publishing |
| `benchmarks.yaml`, `profiling.yaml` | Manually dispatched performance and profiling runs |
### Reading workflow failures
[Section titled “Reading workflow failures”](#reading-workflow-failures)
Note
Please run checks locally before you open a PR. For example `task check` plus tests for any language bindings you touched (see the [Development Workflow](/guides/development/) guide for common commands). That catches most CI failures faster than iterating on GitHub alone.
Open the failing PR’s **Checks** tab and click into the failing job to expand its log. The check name identifies its domain workflow and job. Pushing a fix starts a new path-matched run; for a confirmed flake, use **Re-run failed jobs** on the workflow run page.
If a check is reporting “expected check missing” rather than failing outright, the workflow file probably wasn’t reachable from your branch — rebase on `main` and the check will register on the next push.
***
## Coding standards
[Section titled “Coding standards”](#coding-standards)
* **Rust:** Edition 2024, no `unwrap()` in production paths, document all public items, `SAFETY` comments for `unsafe` blocks
* **Python:** `frozen=True` / `slots=True` dataclasses, function-based pytest, follow Ruff and Mypy rules
* **TypeScript:** Strict types, no `any`, Node.js binding in `crates/xberg-node`
* **Ruby:** No global state outside `Xberg` module, panic-free native bridge, follow RuboCop
* **Go / Java / C#:** Follow standard language conventions and project linters
**Testing:** language-specific tests live in each package; shared E2E behavior belongs in `e2e/` fixtures. When adding features, regenerate with `task e2e::generate`.
***
## Community and support
[Section titled “Community and support”](#community-and-support)
* **Star the repo:** [Give us a star on GitHub](https://github.com/xberg-io/xberg) — it helps others discover Xberg!
* **Discord:** [Join our community](https://discord.gg/xt9WY3GnKR)
* **Reddit:** [r/xberg](https://www.reddit.com/r/xberg/)
* **Issues:** [GitHub Issues](https://github.com/xberg-io/xberg/issues)
* **License:** [MIT License (MIT)](https://github.com/xberg-io/xberg/blob/main/LICENSE)
Thank you for contributing to Xberg!
# Xberg Ecosystem
Xberg is an open-source document-intelligence engine with a Rust core and native bindings for 15 languages. It is part of the Xberg.io product and open-source ecosystem:
* [Xberg](https://github.com/xberg-io/xberg) — the open-source content-intelligence engine: text, tables, and metadata from 107 formats (141 file extensions), with OCR, transcription, and code intelligence. MIT.
* [Xberg Pro](https://xberg.io) — a complete self-hosted content-intelligence backend in a single container. Commercial.
* [Xberg Enterprise](https://xberg.io) — the distributed, governed content-intelligence platform, scaled on Kubernetes with team governance and support. Commercial.
* [crawlberg](https://github.com/xberg-io/crawlberg) — web crawling and scraping with HTML→Markdown and headless-Chrome fallback.
* [html-to-markdown](https://github.com/xberg-io/html-to-markdown) — fast, lossless HTML→Markdown engine.
* [liter-llm](https://github.com/xberg-io/liter-llm) — universal LLM API client with native bindings for 14 languages and 165 providers.
* [tree-sitter-language-pack](https://github.com/xberg-io/tree-sitter-language-pack) — tree-sitter grammars and code-intelligence primitives.
* [alef](https://github.com/xberg-io/alef) — the polyglot binding generator that produces every per-language binding across the 5 polyglot repos.
# Features
A map of what Xberg can do. Each section links to the guide or reference page with configuration details and code examples.
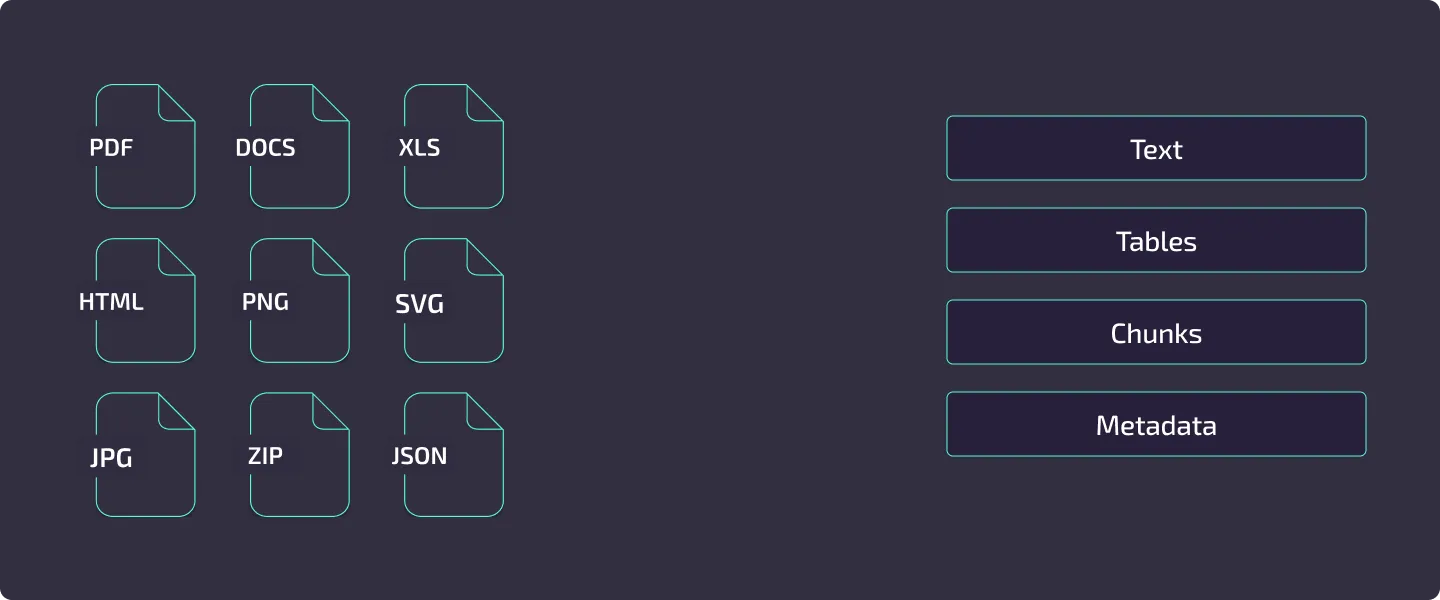
***
## Format Support
[Section titled “Format Support”](#format-support)
107 file formats across 140 unique file extensions, with 53 compatibility MIME aliases, are handled by native Rust extractors — no LibreOffice or other external tools required.
* Documents
PDF `.pdf`Word `.docx .doc`Pages `.pages`PowerPoint `.pptx .ppt .pps`Keynote `.key`OpenDocument `.odt .odp`Plain text `.txt`Markdown `.md`Djot `.djot .dj`MDX `.mdx`RTF `.rtf`reStructuredText `.rst`Org `.org`Hangul `.hwp .hwpx`
* Spreadsheets
Excel `.xlsx .xls .xlsm .xlsb .xltm`Numbers `.numbers`OpenDocument `.ods`CSV `.csv`TSV `.tsv`dBASE `.dbf`
* Images
JPEG `.jpg .jpeg`PNG `.png`GIF `.gif`BMP `.bmp`TIFF `.tiff .tif`WebP `.webp`JPEG 2000 `.jp2 .jpg2 .j2c .j2k .jpc`JBIG2 `.jbig2`PNM `.pnm .pbm .pgm .ppm`HEIC `.heic .heics`HEIF `.heif .heifs .hif`AVIF `.avif`AVCS `.avcs`
HEIF / HEIC / AVIF
Pixel decoding for HEIF-family containers requires the `heic` Cargo feature (included in `full`) and the system `libheif` library at build and runtime. Native targets only — not available on `wasm-target` or `android-target`. EXIF metadata extraction from HEIC / AVIF works on every target via the pure-Rust `nom-exif` integration. See the [installation guide](/getting-started/installation/#heif--heic--avif-support).
libheif license (LGPL)
`libheif` is licensed under the GNU **LGPL**. Xberg links it **dynamically** (via `pkg-config`/system shared library) and never statically — the `heic` feature is optional and is omitted from the standalone CLI release binaries. Container images redistribute the unmodified upstream `libheif` as a separate shared object (`libheif.so`), which you may replace with your own build to satisfy LGPL §6. See [`THIRD_PARTY_LICENSES.md`](https://github.com/xberg-io/xberg/blob/main/THIRD_PARTY_LICENSES.md) for the full notice and source pointer.
* Audio and Video
MP3 `.mp3 .mpga`M4A `.m4a`WAV `.wav`WebM audio `.webm`MP4 audio track `.mp4 .mpg4 .mp4v .m4v`MPEG audio track `.mpeg .mpg .mpe .m1v .m2v`WebM audio track `.webm`
Enable the `transcription` feature and set a `transcription` config block to extract Whisper ONNX transcripts from audio files and video audio tracks. See [Audio and Video Transcription](/guides/transcription/).
* Email
EML `.eml`MSG `.msg`
* Web and Markup
HTML `.html .htm`XHTML `.xhtml .xht`XML `.xml`SVG `.svg`
* Structured Data
JSON `.json`GeoJSON `.geojson`KML `.kml`YAML `.yaml`TOML `.toml`SQLite `.sqlite .sqlite3 .db`GeoPackage `.gpkg .gpkx`
* Archives
ZIP `.zip`TAR `.tar .tgz`GZIP `.gz`7-Zip `.7z`
Archives are traversed recursively — Xberg extracts every document inside, including archives nested within archives, and extracts each with the appropriate format extractor. Traversal is bounded by configurable security limits (archive size, compression ratio, file count, and nesting depth) with zip-bomb detection. See [Extraction Basics](/guides/extraction/) and the [security limits reference](/reference/configuration/).
* Academic
EPUB `.epub`BibTeX `.bib`RIS `.ris`CSL JSON `MIME only`LaTeX `.tex`Typst `.typ .typst`JATS `.jats`DocBook `.docbook`OPML `.opml`
For the full format matrix with MIME types, extraction methods, and special capabilities, see the [Format Support Reference](/reference/formats/).
***
## Extraction Pipeline
[Section titled “Extraction Pipeline”](#extraction-pipeline)
Every file flows through the same multi-stage pipeline:
```mermaid
flowchart LR
A[Input File] --> B[MIME Detection]
B --> C[Format Extractor]
C --> D{OCR Needed?}
D -->|Yes| E[OCR Engine]
D -->|No| F[Post-Processing]
E --> F
F --> G[ExtractedDocument]
```
1. **MIME detection** – Xberg prefers bounded content inspection, then falls back to a supported filename extension. Unknown or missing extensions are sniffed rather than rejected. Configure `mime_detection_policy` to trust a supported extension or ignore extensions when your input boundary requires different behavior.
2. **Format extraction** – The extractor pulls text, tables, metadata, and optionally images from the file. PDF extraction uses xberg-native-pdf (pure Rust); Office formats use native XML or OLE/CFB parsers; images pass directly to OCR.
3. **OCR** – When the extractor finds no text layer (or `force_ocr` is set), the file is routed to the configured OCR backend. The OCR result replaces or supplements the extracted text.
4. **Post-processing** – Validators, quality processing, chunking, embeddings, keyword extraction, and any registered post-processor plugins run in sequence.
5. **Caching** – If caching is enabled, results are stored keyed by a content hash so repeated extractions skip the entire pipeline.
For a deep dive into each stage, see [Extraction Pipeline](/concepts/extraction-pipeline/).
### Output Formats
[Section titled “Output Formats”](#output-formats)
Xberg supports six built-in output formats: **Plain text**, **Markdown**, **Djot**, **HTML**, **JSON**, and **DocTags**. Registered renderers can add custom formats such as Graphviz DOT. The HTML renderer uses semantic `kb-*` CSS classes, five built-in themes, and CSS custom properties. See [Output Formats](/guides/output-formats/) for details.
***
## OCR Engines
[Section titled “OCR Engines”](#ocr-engines)
OCR backends are usable individually or chained into a quality-driven fallback pipeline.
### Backend Comparison
[Section titled “Backend Comparison”](#backend-comparison)
| | Tesseract | PaddleOCR | Sceptre |
| ------------- | ---------------------------------------- | ----------------------------------- | ------------------------------------------------------------------------------- |
| **Languages** | 100+ | 80+ (11 script families) | 8 EasyOCR Gen2 groups |
| **Best for** | General purpose, broad language coverage | CJK, complex scripts, high accuracy | CRAFT scene/document text with line geometry |
| **Platform** | Native and WASM targets | Native ONNX Runtime builds | ORT desktop/server; tract Android/iOS; opt-in Sceptre worker API on WASM |
| **Install** | System package (`tesseract-ocr`) | Cargo feature `paddle-ocr` | `sceptre-ocr` or `sceptre-ocr-tract` |
| **Runtime** | C library (Tesseract 4.0+) | ONNX Runtime | ONNX Runtime or tract; CPU-only |
| **Models** | OS language packs | Downloaded on first use | Desktop cache; required mobile asset paths; verified caller-supplied WASM bytes |
### Multi-Backend Pipeline
[Section titled “Multi-Backend Pipeline”](#multi-backend-pipeline)
When the `paddle-ocr` feature is enabled, Xberg automatically constructs a fallback pipeline: Tesseract runs first, and if the output falls below configurable quality thresholds (16 tunable parameters), PaddleOCR takes over. You can also define a custom ordering across supported backends.
The pipeline supports auto-rotate for page orientation detection (0/90/180/270 degrees) and per-stage language and backend-specific settings.
```mermaid
flowchart TD
A[Image / Scanned Page] --> B[Primary Backend]
B --> C{Quality Above Threshold?}
C -->|Yes| D[Return Result]
C -->|No| E[Fallback Backend]
E --> F{Quality Above Threshold?}
F -->|Yes| D
F -->|No| G[Return Best Result]
```
### Document-Level Optimization
[Section titled “Document-Level Optimization”](#document-level-optimization)
Some OCR backends support **document-level processing**. When a file path is provided, the extractor can bypass the expensive page-by-page rendering stage and delegate the entire document to the OCR engine. This significantly reduces memory overhead and improves throughput for large PDFs and multi-page images.
For backend configuration, language selection, and PSM/OEM modes, see the [OCR Guide](/guides/ocr/).
### Candle GLM-OCR
[Section titled “Candle GLM-OCR”](#candle-glm-ocr)
Pure-Rust VLM OCR wrapping the zai-org/GLM-OCR 0.9B-param vision-language model running natively through the candle transformer framework. No ONNX Runtime dependency. Ships compiled in by default in the published packages (Python, Node, Go, Java, C#, Ruby, PHP, Elixir, Kotlin/JVM, Zig, CLI/Docker) on Linux, macOS, and Windows — no feature flag needed.
**Rust crate feature flag (for custom builds):** `candle-glm-ocr`
**Implies:** `candle-ocr`, `xberg-candle-ocr/glm-ocr`, `layout-detection`
**Deployment:**
* **CPU & Metal (macOS)** — Full support
* **CUDA (Linux/Windows with NVIDIA GPU)** — Full support
* **WASM, Android, iOS, Dart, Swift** — Excluded (candle not available on these targets)
**Model & performance:**
* Model size: \~3 GB on first download; cached at `~/.cache/huggingface/`
* Default layout mode: `paired` — PP-DocLayout-V3 detects regions, per-region task-specific OCR (ocr/table/formula/chart/caption), outputs merged into reading-order markdown
* Alternative mode: `whole_page` — Single OCR pass over entire page with optional task override
* Metal dtype: F32 (BF16 matmul unavailable in candle 0.10)
Configure via `--ocr-backend candle-glm-ocr` or `ocr.backend = "candle-glm-ocr"` in config. Set layout mode and device via `backend_options`: `{"layout_mode":"paired"}`, `{"layout_mode":"whole_page"}`, `{"device":"metal"}`, `{"device":"cuda"}`.
### Candle DeepSeek-OCR
[Section titled “Candle DeepSeek-OCR”](#candle-deepseek-ocr)
Pure-Rust VLM OCR combining SAM, CLIP, Qwen2, and DeepSeek-V2 MoE architecture. Advanced document understanding with multilingual support. No ONNX Runtime dependency. Ships compiled in by default in the published packages (Python, Node, Go, Java, C#, Ruby, PHP, Elixir, Kotlin/JVM, Zig, CLI/Docker) on Linux, macOS, and Windows — no feature flag needed.
**Rust crate feature flag (for custom builds):** `candle-deepseek-ocr`
**Implies:** `candle-ocr`, `xberg-candle-ocr/deepseek-ocr`
**Deployment:**
* **CPU & Metal (macOS)** — Full support
* **CUDA (Linux/Windows with NVIDIA GPU)** — Full support
* **WASM, Android, iOS, Dart, Swift** — Excluded (candle not available on these targets)
**Model & performance:**
* Model size: \~3 GB+ on first download; cached at `~/.cache/huggingface/`
* Fine-grained layout detection, table region recognition, text extraction with confidence scores
* CPU dtype: F32; CUDA dtype: F16
Configure via `--ocr-backend candle-deepseek-ocr` or `ocr.backend = "candle-deepseek-ocr"` in config. Set device via `backend_options`: `{"device":"metal"}`, `{"device":"cuda"}`.
**Attribution:** Model vendored from [jhqxxx/aha](https://github.com/jhqxxx/aha) (Apache-2.0). See [ATTRIBUTIONS.md](https://github.com/xberg-io/xberg/blob/main/ATTRIBUTIONS.md).
### Candle PaddleOCR-VL 1.5
[Section titled “Candle PaddleOCR-VL 1.5”](#candle-paddleocr-vl-15)
Pure-Rust VLM OCR. PaddleOCR-VL 1.5 vision-language model with SigLIP+Ernie integration. Fast multilingual document OCR with strong CJK support. No ONNX Runtime dependency. Ships compiled in by default in the published packages (Python, Node, Go, Java, C#, Ruby, PHP, Elixir, Kotlin/JVM, Zig, CLI/Docker) on Linux, macOS, and Windows — no feature flag needed.
**Rust crate feature flag (for custom builds):** `candle-paddleocr-vl`
**Implies:** `candle-ocr`, `xberg-candle-ocr/paddleocr-vl`
**Deployment:**
* **CPU & Metal (macOS)** — Full support
* **CUDA (Linux/Windows with NVIDIA GPU)** — Full support
* **WASM, Android, iOS, Dart, Swift** — Excluded (candle not available on these targets)
**Model & performance:**
* Model size: \~1 GB on first download; cached at `~/.cache/huggingface/`
* Lightweight architecture optimized for speed and accuracy on scanned documents
* CPU dtype: F32; CUDA dtype: F16
Configure via `--ocr-backend candle-paddleocr-vl` or `ocr.backend = "candle-paddleocr-vl"` in config. Set device via `backend_options`: `{"device":"metal"}`, `{"device":"cuda"}`.
**Attribution:** Model vendored from [jhqxxx/aha](https://github.com/jhqxxx/aha) (Apache-2.0). See [ATTRIBUTIONS.md](https://github.com/xberg-io/xberg/blob/main/ATTRIBUTIONS.md).
### Candle VLM-OCR Umbrella
[Section titled “Candle VLM-OCR Umbrella”](#candle-vlm-ocr-umbrella)
The `candle-vlm-ocr` feature aggregates all Candle VLM-OCR backends: `candle-deepseek-ocr`, `candle-paddleocr-vl`, `candle-glm-ocr`, and `candle-trocr`. Use this aggregate to enable all pure-Rust vision-language OCR options in a single feature flag.
***
## Processing Features
[Section titled “Processing Features”](#processing-features)
Optional post-extraction steps, each configured independently through `ExtractionConfig`.
### For RAG Pipelines
[Section titled “For RAG Pipelines”](#for-rag-pipelines)
**Content Chunking** – Split extracted text into sized chunks for LLM consumption. Strategies include recursive (paragraph/sentence/word splitting), semantic, and Markdown-aware chunking that preserves heading hierarchy. Chunks can be sized by character count or by token count using any HuggingFace tokenizer.
**Embeddings** – Generate vector embeddings locally using FastEmbed. Choose from preset models (`"fast"`, `"balanced"`, `"quality"`) or any FastEmbed-compatible model. Embeddings are generated in-process with no external API calls.
**Page Tracking** – Extract per-page content with byte-accurate offsets for O(1) page lookups. Chunks are automatically mapped to their source pages, enabling precise citations in retrieval systems. Supported for PDF (byte-accurate), PPTX (slide boundaries), and DOCX (best-effort page breaks). See [Extraction Basics](/guides/extraction/) for usage.
**PDF Hierarchy Detection** – Detect document structure from PDFs using K-means clustering on block characteristics (font size, weight, indentation, position). Blocks are assigned to semantic levels (title, section, subsection, paragraph) without relying on explicit heading tags. See the [Output Formats Guide](/guides/output-formats/#pdf-hierarchy-detection).
**PDF Page Rendering** – Render individual PDF pages as PNG images for thumbnails, vision model input, or custom processing pipelines. Memory-efficient iterator renders one page at a time. Configurable DPI (default 150). Available across all language bindings. See [Extraction Guide](/guides/extraction/#pdf-page-rendering).
### LLM-Powered Intelligence
[Section titled “LLM-Powered Intelligence”](#llm-powered-intelligence)
Xberg integrates with 165 LLM providers including local inference (Ollama, LM Studio, vLLM, llama.cpp) via [liter-llm](https://github.com/xberg-io/liter-llm) to unlock three new capabilities that complement the local extraction pipeline.
**VLM OCR** – Vision language models as an OCR backend
Use OpenAI GPT-4o, Anthropic Claude, Google Gemini, or any vision-capable model as an OCR engine. VLM OCR delivers superior accuracy on low-quality scans, handwriting, Arabic/Farsi scripts, and complex layouts where traditional OCR struggles. Configure via `ocr.backend = "vlm"` with `ocr.vlm_config` in your extraction config or `xberg.toml`.
**Structured Extraction** – Extract typed JSON from documents using a schema
Provide a JSON schema and an optional Jinja2 prompt template in `ExtractionConfig.structured_extraction`; unified `extract` returns conforming structured data in the extraction result. Supports strict mode with automatic `additionalProperties` sanitization for cross-provider compatibility.
```json
{
"type": "object",
"properties": {
"invoice_number": { "type": "string" },
"total": { "type": "number" },
"line_items": {
"type": "array",
"items": {
"type": "object",
"properties": {
"description": { "type": "string" },
"amount": { "type": "number" }
}
}
}
}
}
```
**VLM Embeddings** – Provider-hosted embedding models
Use provider-hosted embedding models (for example, `openai/text-embedding-3-small`, `mistral/mistral-embed`) as an alternative to local ONNX models. Works through the existing `/embed` API endpoint, `embed_text` MCP tool, and `embed` CLI command with `--provider llm`.
**Custom Jinja2 Prompts** – Minijinja template engine for LLM prompts
Customize the prompts sent to LLMs with Minijinja templates. Available variables for structured extraction: `{{ content }}`, `{{ schema }}`, `{{ schema_name }}`, `{{ schema_description }}`. For VLM OCR prompts: `{{ language }}`. Override the default prompt per-request or in configuration.
`LlmConfig` and `StructuredExtractionConfig` are part of the generated binding surface. Use the per-language API reference to confirm representation and package support for your target. Five environment variables (`XBERG_LLM_MODEL`, `XBERG_LLM_API_KEY`, `XBERG_LLM_BASE_URL`, `XBERG_VLM_OCR_MODEL`, `XBERG_VLM_EMBEDDING_MODEL`) provide zero-code configuration.
### Document Enrichment
[Section titled “Document Enrichment”](#document-enrichment)
**Named-Entity Recognition** – Detect people, organisations, locations, dates, money, percentages, emails, phones, URLs, and caller-supplied zero-shot labels via `xberg-gliner` (ONNX artifacts from `xberg-io/gliner-models`) or any liter-llm provider. Results populate `ExtractedDocument.entities`. See the [NER Guide](/guides/ner/).
**Redaction & Anonymisation** – Late-stage post-processor that rewrites `content`, `formatted_content`, chunks, entities, summary, translation, and page classifications. Pattern engine covers emails, phones, SSNs, credit cards, IBANs, IP addresses, SWIFT/BIC, postal codes, dates of birth; pair with NER for PERSON / ORGANIZATION / LOCATION. Strategies: mask, hash, token-replace, drop. Caller can supply literal terms and regex patterns. See the [Redaction Guide](/guides/redaction/).
**Document Summarisation** – Pure-Rust TextRank (extractive, local, deterministic) or any liter-llm provider (abstractive). Result on `ExtractedDocument.summary`. See the [Summarisation Guide](/guides/summarization/).
**Document Translation** – Translate `content`, `formatted_content`, and per-chunk text into a BCP-47 target language with any liter-llm provider. Optional Markdown/HTML preservation. Result on `ExtractedDocument.translation`. See the [Translation Guide](/guides/translation/).
**Page Classification** – Per-page LLM classification against caller-supplied labels. Single-label or multi-label. Result on `ExtractedDocument.page_classifications`. See the [Page Classification Guide](/guides/page-classification/).
**VLM Image Captions** – Describe extracted images with any vision-capable liter-llm provider. Result on `ExtractedImage.caption`. See the [Image Captions Guide](/guides/image-captions/).
**QR-Code Detection** – Pure-Rust `rqrr` decoder runs over extracted images. Result on `ExtractedImage.qr_codes`. Ships in `wasm-target` and `android-target`. See the [QR Codes Guide](/guides/qr-codes/).
### For Search and Indexing
[Section titled “For Search and Indexing”](#for-search-and-indexing)
**Keyword Extraction** – Extract key phrases using YAKE (unsupervised, language-independent) or RAKE (fast statistical method). Configurable n-gram ranges and language-specific stopword filtering. See the [Keyword Extraction Guide](/guides/keywords/).
**Language Detection** – Identify 60+ languages with confidence scoring using fast-langdetect. Supports multi-language detection for documents with mixed content.
**Metadata Extraction** – Pull document properties (title, author, creation date), page/word/character counts, and format-specific metadata (Excel sheet names, PDF annotations).
### For Code
[Section titled “For Code”](#for-code)
**Code Intelligence** – Extract functions, classes, imports, exports, symbols, docstrings, and diagnostics from 371 programming languages via tree-sitter. Results are available in `ExtractedDocument.code_intelligence` as a `ProcessResult`. Code files produce semantic chunks (function/class-aware) that bypass the text-splitter entirely. Configure content mode with `CodeContentMode`: `chunks` (default, semantic TSLP chunks), `raw` (source as-is), or `structure` (headings + docstrings only).
### For Data Quality
[Section titled “For Data Quality”](#for-data-quality)
**Quality Processing** – Unicode normalization (NFC/NFD/NFKC/NFKD), whitespace and line break standardization, encoding detection, and mojibake correction.
**Token Reduction** – Reduce token count while preserving meaning through TF-IDF-based extractive summarization. Three modes: light (\~15% reduction), moderate (\~30%), and aggressive (\~50%).
**Table Extraction** – Structured table data from PDFs, spreadsheets, and Word documents with cell-level row/column indexing, merged cell support, and Markdown or JSON output.
***
## Layout Detection
[Section titled “Layout Detection”](#layout-detection)
Detect and classify document regions using ONNX-based deep learning. Layout detection identifies 17 element types (text, tables, figures, headers, code, forms, captions, and more), enabling accurate region-aware extraction and structured table recovery.
**RT-DETR v2** – The layout detection model that identifies document structure with high precision. Automatically selects and configures separate table structure models (TATR, SLANeXT variants, or SLANet-plus) for cell-level analysis within detected table regions.
**Table Structure Recognition** – When layout detection identifies a table, a configurable table structure model analyzes rows, columns, headers, and spanning cells for HTML recovery with colspan/rowspan support. Choose from:
* **TATR** (30 MB) — General-purpose, fast, default
* **SLANeXT Wired/Wireless/Auto** (365–737 MB) — Optimized for bordered/borderless tables with auto-detection
* **SLANet-plus** (7.78 MB) — Lightweight, resource-constrained environments
GPU acceleration via ONNX Runtime (CUDA, CoreML, TensorRT) significantly reduces inference time. Models are automatically downloaded and cached on first use. The published Docker images are CPU-only — see [GPU Acceleration](/getting-started/installation/#gpu-acceleration) for building with GPU support.
**Availability:** Native builds that include ONNX Runtime, including the full `windows-target` aggregate. RT-DETR layout detection (and the wired/wireless table classifier) also runs off ONNX Runtime through the pure-Rust `tract` engine on `wasm-target` and `android-target` via the `layout-tract` feature; TATR, SLANeXT, and PP-DocLayout-V3 table-structure models stay ONNX Runtime-only.
For configuration and usage, see the [Layout Detection Guide](/guides/layout-detection/).
***
## Plugin System
[Section titled “Plugin System”](#plugin-system)
The extraction pipeline and query-time APIs are extensible through six plugin categories:
```mermaid
flowchart LR
A[File Input] --> B[Document Extractor Plugin]
B --> C[OCR Backend Plugin]
C --> D[Validator Plugin]
D --> E[Post-Processor Plugin]
E --> F[Renderer Plugin]
F --> G[Output]
H[Query + Documents] --> I[Reranker Backend Plugin]
I --> J[Reranked Documents]
```
| Plugin Type | Purpose | Example |
| ----------------------- | -------------------------------------------------------- | ------------------------------ |
| **Document Extractors** | Add support for custom file formats or override defaults | Proprietary format parser |
| **OCR Backends** | Integrate cloud OCR services or custom engines | AWS Textract, Google Vision |
| **Reranker Backends** | Score query/document pairs for search ranking | Cross-encoder or provider API |
| **Validators** | Enforce quality standards on extraction results | Minimum word count check |
| **Post-Processors** | Transform or enrich results after extraction | PII redaction, custom metadata |
| **Renderers** | Convert document structures into output formats | Custom Markdown or HTML writer |
Plugins are registered programmatically through typed registries. Built-in plugins register at initialization when their Cargo feature is active; runtime configuration selects registered backends and processors.
For the architecture overview, see [Plugin System](/concepts/plugin-system/). For implementation guidance, see [Creating Plugins](/guides/plugins/).
***
## Deployment Modes
[Section titled “Deployment Modes”](#deployment-modes)
| Mode | When to Use | Details |
| -------------- | ------------------------------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------- |
| **Library** | Embedding extraction into your application | Import the package in Python, TypeScript, Rust, Go, Java/Kotlin JVM, Kotlin Android, Ruby, C#, PHP, Elixir, Dart, Swift, Zig, C, or Wasm |
| **CLI** | One-off extractions, scripting, CI pipelines | `xberg extract document.pdf --format json` – see [CLI Usage](/cli/usage/) |
| **REST API** | Multi-service architectures, language-agnostic access | `xberg serve --port 8000` – see [API Server Guide](/guides/api-server/) |
| **MCP Server** | AI agent integration (Claude Desktop, Continue.dev) | `xberg mcp` – stdio transport with JSON-RPC 2.0 |
| **Docker** | Reproducible deployments with all dependencies bundled | `ghcr.io/xberg-io/xberg:latest` – see [Docker Guide](/guides/docker/) |
***
## Language Bindings
[Section titled “Language Bindings”](#language-bindings)
Polyglot bindings share the Rust core and expose the same generated types where the target platform supports the underlying feature.
### Binding Tiers
[Section titled “Binding Tiers”](#binding-tiers)
**Full feature parity with async API** – Rust, Python (PyO3), TypeScript/Node.js (NAPI-RS)
**Full features, synchronous API** – Go, Ruby, C#, Java, PHP, Elixir
**Native FFI surfaces** – C, Dart, Swift, Zig, Kotlin Android
**TypeScript: Two flavors**
* **Native** (`@xberg-io/xberg`) — Full speed, complete feature parity (servers, plugins, config file discovery)
* **WASM** (`@xberg-io/xberg-wasm`) — Browser/edge runtime, 60–80% of native speed, no native dependencies required. Excluded features: ORT-dependent inference (`paddle-ocr`, embeddings, reranker, transcription), liter-llm/VLM features, server modes (`api`/`mcp`), CLI binary, tree-sitter code intelligence, and browser filesystem paths. Supported: pure-Rust extraction formats, Tesseract WASM OCR, RT-DETR layout detection and document-orientation through tract, chunking, keywords, language detection, stopwords, redaction, summarization, SVG, and QR-code detection. Sceptre tract OCR is available to source builds through the opt-in `sceptre-wasm` feature and a synchronous byte-fed API that applications run inside their own Web Worker; it is not part of the published default bundle.
Choose Native for server-side Node.js; choose WASM for browser or edge deployments.
### Rust Feature Flags
[Section titled “Rust Feature Flags”](#rust-feature-flags)
Rust builds are modular through Cargo features. The default feature set is `tokio-runtime` plus `simd-utf8`; enable format and analysis features explicitly for the surface you need.
| Category | Features |
| --------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Format extractors** | `pdf`, `excel`, `office`, `hwp`, `hwpx`, `iwork`, `email`, `html`, `xml`, `archives`, `mdx`, `sqlite`, `svg`, `heic` |
| **OCR and ML** | `ocr`, `ocr-wasm`, `paddle-ocr`, `sceptre-ocr`, `sceptre-ocr-tract`, `layout-detection`, `embeddings`, `reranker`, `transcription`, `liter-llm` |
| **Text analysis** | `language-detection`, `chunking`, `quality`, `keywords`, `stopwords`, `diff`, `ner`, `redaction`, `summarization`, `translation`, `classification`, `captioning`, `qr-codes` |
| **Servers** | `api`, `mcp`, `mcp-http`, `otel` |
| **Bundles** | `formats`, `analysis`, `services`, `full`, `server`, `cli`, `wasm-target`, `android-target`, `windows-target` |
### Additional Rust Feature Flags
[Section titled “Additional Rust Feature Flags”](#additional-rust-feature-flags)
The table above covers the main entry points. These are lower-level or opt-in flags not otherwise documented — each enables narrower functionality and carries a specific cost (extra native dependency, platform restriction, or CI-untested status per Cargo.toml’s own comments).
| Feature | Enables | Cost / restriction |
| ------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------- |
| `notebook` | Jupyter `.ipynb` extraction | Pure Rust, no extra deps; already included by `office` |
| `wordperfect` | `.wpd` extraction via vendored libwpd/librevenge | Native C++ dependency (vendors boost); needs vcpkg zlib on Windows; native-only |
| `bedrock` | Forwards to liter-llm’s AWS Bedrock SigV4 model routing | Requires `liter-llm`; adds aws-credential-types + pure-Rust aws-sigv4 (no aws-sdk) |
| `candle-cuda` / `candle-metal` / `candle-accelerate` / `candle-mkl` | GPU/accelerator backend for candle VLM OCR (`candle-ocr` family) | Must be paired with a `candle-*` OCR backend; CPU-only decode of the larger VLM models is impractically slow without one |
| `paddle-ocr-ort` | PaddleOCR via ONNX Runtime (native default engine) | Pulls in `ort` + `ort-bundled` prebuilt runtime download |
| `paddle-ocr-tract` | PaddleOCR via the pure-Rust `tract` engine, no ORT | For no-ORT targets (Android x86\_64 emulator); never enable alongside `paddle-ocr-ort` in the same build |
| `sceptre-ocr-ort` / `sceptre-ocr-tract` | Sceptre OCR’s ORT and pure-Rust tract engine variants | `sceptre-ocr` aliases to `-ort`; the two are additive but only one is needed per target |
| `sceptre-ocr-candle` | Hand-written CRAFT/CRNN forward pass over candle tensors | CPU-only by default (candle-core has default features off) |
| `sceptre-ocr-candle-metal` / `sceptre-ocr-candle-cuda` | Metal / CUDA acceleration for the sceptre candle backend | **UNTESTED** – Cargo.toml notes no CI leg builds or runs either combination |
| `ort-bundled` | Downloads the pyke prebuilt ONNX Runtime at build time | Dev-default strategy; the prebuilt requires glibc >= 2.38 to run |
| `ort-dynamic` | Loads ONNX Runtime dynamically at runtime via `ORT_DYLIB_PATH` | Build-time only, no download; used where no static prebuilt exists (e.g. Intel macOS) |
| `coreml` | Explicit opt-in for the CoreML execution provider | macOS-only; not included in `default`, `full`, or any binding preset |
| `cuda` | Explicit opt-in for the CUDA execution provider | Requires a CUDA-enabled ONNX Runtime build (the plain prebuilt has no CUDA support); not in `default`/`full` |
| `tensorrt` | Explicit opt-in for the TensorRT execution provider | Requires a TensorRT-enabled ONNX Runtime build; not in `default`/`full` |
| `auto-rotate` / `auto-rotate-tract` | PP-LCNet document-orientation detection (ORT and pure-Rust tract variants) | `-tract` is the no-ORT sibling for Android x86\_64/WASM; never enable both together |
| `tract` | Pure-Rust ONNX inference engine underlying every `*-tract` feature | Additive alongside ORT on native targets; the sole inference engine on WASM and Android x86\_64 |
| `chunking-tokenizers` | Token-count-based chunk sizing using any HuggingFace tokenizer | Adds `tokenizers` + `hf-hub`/`reqwest` model download |
| `static-embeddings` | Pure-Rust static (model2vec) dense embeddings, no ORT | The only dense embedder available on WASM/Android; native-only model download |
| `sparse-embeddings` | SPLADE sparse embeddings for hybrid dense+sparse retrieval | ORT-dependent, WASM-incompatible |
| `late-interaction` | ColBERT multi-vector (MaxSim) embeddings | ORT-dependent, WASM-incompatible |
| `enrichment` | Cloud-upstreamed generic overridable extraction defaults | Pure Rust, no deps; no domain-specific logic yet |
| `heuristics` | Hooks for heuristic-based extraction behavior | Pure Rust, no deps; currently a thin placeholder (text-layer-detection heuristics land under a separate future feature) |
| `keywords-yake` / `keywords-rake` | Individual keyword-extraction algorithms (unsupervised YAKE / statistical RAKE) | `keywords` enables both together; use these to pick just one |
| `markdown-footnotes` | Footnote and citation extraction (`FootnoteConfig`, `Citation`, etc.) | Pure Rust, no deps |
| `ner-llm` | Zero-shot NER via any configured liter-llm provider | Requires `liter-llm`; no ORT needed |
| `ner-onnx` | NER via the `xberg-gliner` ONNX backend | ORT-dependent; downloads models from Hugging Face on first use |
| `presets` | Built-in extraction preset format, registry, and resolver | Pure Rust, no native deps |
| `structured` | Enables `ExtractionConfig.structured_extraction` (LLM-driven typed JSON extraction against a caller-supplied schema) | Requires `liter-llm` |
| `redaction-rehydrate` | Encrypted rehydration map capture for reversible PII redaction | Requires `redaction`; adds `aes-gcm`, `scrypt`, `zeroize` |
| `redaction-ml` | Couples NER into redaction for PERSON/ORG/LOC pattern matching | Requires `redaction` + `ner` |
| `summarization-llm` | Abstractive summarization via any liter-llm provider | Requires `summarization` + `liter-llm` (the base `summarization` feature is pure-Rust TextRank only) |
| `url-ingestion` / `url-ingestion-browser` | Fetch and crawl remote URLs as extraction input via `crawlberg` | `-browser` adds `crawlberg/browser` for in-browser fetch (WASM); native `url-ingestion` needs `crawlberg/native-runtime` |
| `prometheus` | Opt-in Prometheus `/metrics` endpoint | Requires both `api` and `otel` explicitly – neither implies the other |
| `mobile` | Deployment preset: `formats` + `analysis` + Tesseract `ocr` + `tree-sitter` + `api-types` | Excludes all ORT-dependent ML (paddle-ocr, layout-detection, embeddings, reranker, transcription, auto-rotate) |
| `macos-intel-target` | Full feature parity on Intel macOS (`full-no-heic` + `ort-dynamic`) | ORT dropped static x86\_64-apple-darwin prebuilts after v2.0.0-rc.11, so this target loads ONNX Runtime dynamically instead |
Skipped as internal plumbing (pure marker/aggregate features with no independent behavior, or types-only subsets already covered by their parent feature above): `paddle-ocr-types`, `layout-types`, `auto-rotate-types`, `transcription-types`, `embedding-presets`, `reranker-presets`, `sparse-embedding-presets`, `late-interaction-presets`, `api-types`, `onnx-runtime`, `ocr-pipeline`, `image-encode`, `url-config-types`, `tower-service`, `no-ort-target`, `formats-no-heic`, `full-no-heic`, `simd-utf8`, `tokio-runtime`, `profiling`, `pool-metrics`.
### Package Installation
[Section titled “Package Installation”](#package-installation)
* Python
```bash
pip install xberg # Core + Tesseract + PaddleOCR
pip install xberg[all] # Everything
```
* TypeScript
```bash
npm install @xberg-io/xberg # Native (Node.js/Bun)
npm install @xberg-io/xberg-wasm # WASM (browser/edge)
```
* Rust
```toml
[dependencies]
xberg = { version = "1", features = ["pdf", "ocr", "chunking"] }
```
* Other
```bash
gem install xberg # Ruby
go get github.com/xberg-io/xberg/packages/go # Go
dotnet add package XbergIo.Xberg # C#
```
For API details per language, see the [API Reference](/reference/api-python/).
***
## Configuration
[Section titled “Configuration”](#configuration)
Four configuration methods, checked in this order:
1. **Programmatic** – Construct `ExtractionConfig` objects in code (all bindings)
2. **TOML** – `xberg.toml`
3. **YAML** – `xberg.yaml`
4. **JSON** – `xberg.json`
Config files are auto-discovered from the current directory, `~/.config/xberg/`, and `/etc/xberg/`. Environment variables (`XBERG_CONFIG_PATH`, `XBERG_CACHE_DIR`, `XBERG_OCR_BACKEND`, `XBERG_OCR_LANGUAGE`) override file-based settings.
For the full configuration schema and examples, see the [Configuration Guide](/guides/configuration/).
***
## AI Coding Assistants
[Section titled “AI Coding Assistants”](#ai-coding-assistants)
Xberg ships with an [Agent Skill](https://agentskills.io) that teaches AI coding assistants the complete API across Python, TypeScript, Rust, and CLI. Install it with:
```bash
npx skills add xberg-io/xberg
```
Compatible with Claude Code, Codex, Gemini CLI, Cursor, VS Code, Amp, Goose, Roo Code, and any tool supporting the Agent Skills standard. See the [AI Coding Assistants Guide](/guides/ai-coding-assistants/).
***
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Installation](/getting-started/installation/) – Install Xberg for your language
* [Quick Start](/getting-started/quickstart/) – Extract your first document in 5 minutes
* [Architecture](/concepts/architecture/) – Understand the Rust core and binding layers
* [Development Workflow](/guides/development/#performance) – Performance benchmarks and optimization guidance
# Installation
> Install Xberg — pick Python, TypeScript, Rust, Go, Java/Kotlin, CLI/Docker, or another supported SDK.
Polyglot SDKs plus a standalone CLI. Most packages ship **prebuilt binaries** for Linux (x86\_64/aarch64), macOS, and Windows — no compile step needed.
## CLI / Docker
[Section titled “CLI / Docker”](#cli--docker)
No SDK, no code — just your terminal.
* Install script
```bash
curl -fsSL https://raw.githubusercontent.com/xberg-io/xberg/main/scripts/install.sh | bash
```
* Homebrew
```bash
brew trust xberg-io/tap
brew install xberg-io/tap/xberg
```
* Scoop (Windows)
```powershell
scoop bucket add xberg https://github.com/xberg-io/scoop-bucket
scoop install xberg
```
* Cargo
```bash
cargo install xberg-cli
```
* Docker (CLI image)
```bash
docker pull ghcr.io/xberg-io/xberg-cli:latest
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg-cli:latest extract /data/document.pdf
```
* Docker (full image)
```bash
docker pull ghcr.io/xberg-io/xberg:latest
```
MCP Server included
Prebuilt binaries (Homebrew, install.sh, Docker full) include the MCP server. If building from source with `cargo install xberg-cli`, add `--features mcp` (or `--features mcp-http` for HTTP transport) to include it.
[CLI Usage](/cli/usage/) [API Server Guide](/guides/api-server/)
x86\_64 CPU — AVX/AVX2 instruction set required
The bundled ONNX Runtime binaries require **AVX/AVX2** CPU instructions. CPUs without AVX support (e.g. Intel Atom, Celeron N5105/Jasper Lake, older pre-2011 processors) will crash with an `invalid opcode` trap when using ONNX-dependent features. The affected features are **PaddleOCR**, **layout detection**, **embeddings**, **reranking**, **auto-rotate**, and **transcription**. All other Xberg functionality (text extraction, Tesseract OCR, chunking, metadata, etc.) works normally on any x86\_64 CPU. ARM platforms (aarch64) are unaffected.
Windows — ONNX Runtime required for Go, Elixir, and C/C++
Go, Elixir, and C/C++ bindings on Windows link against ONNX Runtime dynamically. You must have `onnxruntime.dll` on your `PATH` at runtime. Download it from the [ONNX Runtime releases](https://github.com/microsoft/onnxruntime/releases) (for example `onnxruntime-win-x64-1.24.1.zip`). Python, TypeScript, Java, C#, Ruby, PHP, and Wasm are unaffected.
C# / .NET in a Linux container — publish with a RID and set `LD_LIBRARY_PATH`
The `XbergIo.Xberg` NuGet package ships its native library as a per-RID runtime package (`XbergIo.Xberg.runtime.`) resolved through a `runtime.json` graph, the same pattern as `Microsoft.Data.Sqlite`. Two container gotchas:
1. **Publish with a runtime identifier so the natives deploy.** Use `dotnet publish -r linux-x64` (Aspire’s SDK container publish does this). The RID must be known at **restore** time — a RID-less `dotnet restore` followed by `dotnet publish -r linux-x64 --no-restore` won’t pull the runtime package (you’ll see `NETSDK1047`), and the ONNX Runtime closure never lands next to your app.
2. **Point the dynamic loader at your app directory.** The bundled `libxberg_ffi.so` loads `libonnxruntime.so.1` beside it, but the container’s loader may not resolve it via the library’s `RUNPATH`, surfacing as `DllNotFoundException` on the first extraction. Set `LD_LIBRARY_PATH` to your app directory — `ENV LD_LIBRARY_PATH=/app` in a Dockerfile, or `.WithEnvironment("LD_LIBRARY_PATH", "/app")` in .NET Aspire (`/app` is the working directory in the standard .NET container images).
Intel Macs (x86\_64) — prebuilt binaries are limited
Apple Silicon (arm64) macOS is fully supported across every package. On **Intel Macs (x86\_64)**, prebuilt binaries ship only for the **CLI** (install script, Homebrew, and the release tarball) and the **Python** wheel. The TypeScript/Node, Go, Java, Kotlin, C#, Dart, C/C++, Ruby, PHP, and Elixir packages ship macOS prebuilts for **Apple Silicon only** — on an Intel Mac they fall back to building the native library from source (a Rust toolchain is required). Intel-macOS is a legacy target: GitHub retires its last x86\_64 macOS CI runner in 2027 and the bundled ONNX Runtime has no Intel-macOS build, so Intel support is best-effort and will be removed. Prefer Apple Silicon where you can.
## Choose your language
[Section titled “Choose your language”](#choose-your-language)
* **Python**
***
```bash
pip install xberg
```
[API Reference](/reference/api-python/) [Quick Start](/getting-started/quickstart/)
* **TypeScript (Node.js / Bun)**
***
```bash
npm install @xberg-io/xberg
```
[API Reference](/reference/api-typescript/) [Quick Start](#typescript)
* **TypeScript (Browser / Edge)**
***
```bash
npm install @xberg-io/xberg-wasm
```
[API Reference](/reference/api-wasm/) [Quick Start](#typescript)
* **Rust**
***
```bash
cargo add xberg
```
[API Reference](/reference/api-rust/) [Quick Start](/getting-started/quickstart/)
* **Go**
***
```bash
go get github.com/xberg-io/xberg/packages/go@latest
```
[API Reference](/reference/api-go/) [Quick Start](/getting-started/quickstart/)
* **Java**
***
```groovy
implementation 'io.xberg:xberg:1.1.6'
```
[API Reference](/reference/api-java/) [Quick Start](#java)
* **Kotlin Android**
***
```kotlin
implementation("io.xberg:xberg-android:1.1.6")
```
[API Reference](/reference/api-kotlin-android/) [Quick Start](#kotlin)
* **Ruby**
***
```bash
gem install xberg
```
[API Reference](/reference/api-ruby/) [Quick Start](/getting-started/quickstart/)
* **Swift**
***
```swift
.package(url: "https://github.com/xberg-io/xberg.git", from: "1.1.6")
```
[API Reference](/reference/api-swift/) [Quick Start](#swift)
* **C# / .NET**
***
```bash
dotnet add package XbergIo.Xberg
```
[API Reference](/reference/api-csharp/) [Quick Start](/reference/api-csharp/)
* **PHP**
***
```bash
composer require xberg-io/xberg
```
[API Reference](/reference/api-php/) [Quick Start](/getting-started/quickstart/)
* **Elixir**
***
```elixir
{:xberg, "~> 1.0"}
```
[API Reference](/reference/api-elixir/) [Quick Start](#elixir)
* **C / C++**
***
```bash
cargo build -p xberg-ffi
```
[API Reference](/reference/api-c/) [Quick Start](#c-c)
* **Dart / Flutter**
***
```bash
dart pub add xberg
```
[API Reference](/reference/api-dart/) [Quick Start](#dart)
* **Zig**
***
```bash
zig fetch --save https://github.com/xberg-io/xberg/archive/refs/tags/v1.1.6.tar.gz
```
[API Reference](/reference/api-zig/) [Quick Start](#zig)
***
## Verify your install
[Section titled “Verify your install”](#verify-your-install)
Run one extraction after you install a package. Each example reads `document.pdf` and prints the extracted text. A successful run confirms that the binding finds and loads its native library.
* C
C
```c
#include
#include
#include
#include
int main(void) {
XBERGAlefHandle config = xberg_extraction_config_from_json("{}");
XBERGAlefHandle input = xberg_extract_input_from_uri("document.pdf");
if (input == 0) {
fprintf(stderr, "Failed to create input (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extraction_config_free(config);
return 1;
}
XBERGAlefHandle result = xberg_extract(input, config);
if (result == 0) {
fprintf(stderr, "extraction failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extract_input_free(input);
xberg_extraction_config_free(config);
return 1;
}
char *content = xberg_extraction_result_results(result);
printf("%s\n", content ? content : "(empty)");
xberg_free_string(content);
xberg_extract_input_free(input);
xberg_extraction_result_free(result);
xberg_extraction_config_free(config);
return 0;
}
```
* C#
C#
```csharp
using Xberg;
var config = new ExtractionConfig
{
UseCache = true,
EnableQualityProcessing = true
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
Console.WriteLine(result.Content);
Console.WriteLine($"MIME Type: {result.MimeType}");
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, xberg.ExtractionConfig{})
if err != nil {
log.Fatalf("extract failed: %v", err)
}
fmt.Println("Extracted content:")
if len(result.Results[0].Content) > 200 {
fmt.Println(result.Results[0].Content[:200])
} else {
fmt.Println(result.Results[0].Content)
}
}
```
* Java
Java
```java
import io.xberg.ExtractInput;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.Xberg;
import io.xberg.ExtractionResult;
import io.xberg.XbergRsException;
public class BasicUsage {
public static void main(String[] args) throws XbergRsException {
ExtractInput input = ExtractInput.builder()
.withKind(ExtractInputKind.Uri)
.withUri("document.pdf")
.build();
ExtractionResult output = Xberg.extract(input, ExtractionConfig.builder().build());
ExtractedDocument document = output.results().get(0);
System.out.println("Content:");
System.out.println(document.content());
System.out.println("\nMetadata:");
if (document.metadata().title() != null) {
System.out.println("Title: " + document.metadata().title());
}
if (document.metadata().authors() != null) {
System.out.println("Authors: " + String.join(", ", document.metadata().authors()));
}
System.out.println("\nTables found: " + document.tables().size());
System.out.println("Images found: " + (document.images() == null ? 0 : document.images().size()));
}
}
```
* PHP
PHP
```php
getResults()[0];
echo "Extracted Content:\n";
echo "==================\n";
echo $result->content . "\n\n";
echo "Metadata:\n";
echo "=========\n";
echo "Title: " . ($result->metadata?->title ?? 'N/A') . "\n";
echo "Authors: " . (isset($result->metadata?->authors) ? implode(', ', $result->metadata?->authors) : 'N/A') . "\n";
echo "Pages: " . ($result->metadata?->pdf?->page_count ?? 'N/A') . "\n";
echo "Format: " . $result->mimeType . "\n\n";
if (count($result->tables) > 0) {
echo "Tables Found: " . count($result->tables) . "\n";
foreach ($result->tables as $index => $table) {
echo "\nTable " . ($index + 1) . " (Page {$table->pageNumber}):\n";
echo $table->markdown . "\n";
}
}
```
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig
async def main() -> None:
result = await extract(ExtractInput(uri="document.pdf"), ExtractionConfig())
print(result.results[0].content)
asyncio.run(main())
```
* Ruby
Ruby
```ruby
require 'xberg'
puts "Xberg version: #{Xberg::VERSION}"
puts "FFI bindings loaded successfully"
input = Xberg::ExtractInput.new(uri: 'sample.pdf')
config = Xberg::ExtractionConfig.new
result = Xberg.extract(input, config)
puts "Installation verified! Extracted #{result.results.first.content.length} characters"
```
* Elixir
Elixir
```elixir
# Basic document extraction workflow
# Load file -> extract -> access results
{:ok, output} = Xberg.extract(input: %Xberg.ExtractInput{kind: :uri, uri: "document.pdf"}, config: nil)
result = List.first(output.results)
IO.puts("Extracted Content:")
IO.puts(result.content)
IO.puts("\nMetadata:")
IO.puts("Format: #{inspect(result.metadata.format)}")
IO.puts("Tables found: #{length(result.tables)}")
```
* Wasm
Wasm
```typescript
import init, { WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
await init();
const buffer = await fetch("document.pdf").then((r) => r.arrayBuffer());
const bytes = new Uint8Array(buffer);
const output = await extract({
kind: "bytes",
bytes,
mimeType: "application/pdf",
filename: "document.pdf",
}, undefined);
console.log("Extracted content:");
console.log(output.results[0].content);
console.log("MIME type:", output.results[0].mimeType);
console.log("Metadata:", output.results[0].metadata);
}
main().catch(console.error);
```
***
## System requirements
[Section titled “System requirements”](#system-requirements)
Only relevant if building from source or enabling OCR:
| Dependency | When you need it |
| ---------------------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| AVX/AVX2 CPU instructions | Required for ONNX Runtime features (PaddleOCR, layout detection, embeddings, reranking, auto-rotate, transcription) on x86\_64 |
| Rust toolchain (`rustup`) | Building any native binding from source |
| C/C++ compiler | Building native bindings (Xcode command-line tools / `build-essential` / MSVC) |
| Tesseract OCR | Optional — `brew install tesseract` / `apt install tesseract-ocr` |
| libheif (HEIC / HEIF / AVIF) | Optional — `brew install libheif` / `apt install libheif-dev` / `dnf install libheif-devel` |
PDF extraction uses xberg-native-pdf and has no external PDF runtime dependency.
The Wasm package (`@xberg-io/xberg-wasm`) has **zero** system dependencies.
### HEIF / HEIC / AVIF support
[Section titled “HEIF / HEIC / AVIF support”](#heif--heic--avif-support)
Pixel decoding for Apple HEIC photos, HEIF still images, AVIF, HEIC sequences (`.heics`), HEIF sequences (`.heifs`), `.hif`, and AVCS requires the **`heic` Cargo feature** plus the system `libheif` library (with `libde265` for HEVC and `libaom` for AV1):
* **macOS**: `brew install libheif`
* **Debian / Ubuntu**: `apt install libheif-dev`
* **Fedora**: `dnf install libheif-devel`
* **Windows (vcpkg)**: `vcpkg install libheif[hevc,aom]:x64-windows`
Enable the feature when building from source:
```toml
xberg = { version = "1", features = ["heic", "ocr"] }
```
`heic` is included in the `full` aggregate feature. HEIC pixel decoding is **not available** on `wasm-target` or `android-target` (libheif is a C library with no working WASM/Android build story). EXIF metadata extraction from HEIC / HEIF / AVIF works on **every** target via the pure-Rust `nom-exif` integration.
### GPU Acceleration
[Section titled “GPU Acceleration”](#gpu-acceleration)
Xberg bundles a CPU-only ONNX Runtime — ML features (PaddleOCR, layout detection, embeddings, reranking, auto-rotate, transcription) work out of the box on CPU.
For GPU acceleration, install a GPU-enabled ONNX Runtime and set `ORT_DYLIB_PATH`:
| Platform | Install | Set ORT\_DYLIB\_PATH |
| --------------- | ---------------------------------------------------------------------------------------- | -------------------------------------------------- |
| Linux (CUDA) | Download from [ONNX Runtime releases](https://github.com/microsoft/onnxruntime/releases) | `export ORT_DYLIB_PATH=/path/to/libonnxruntime.so` |
| Python (any OS) | `pip install onnxruntime-gpu` | Point at the pip package’s `capi/` directory |
| macOS (CoreML) | Works with bundled ORT — no extra setup needed | — |
See [AccelerationConfig](/reference/configuration/#accelerationconfig) and [ORT\_DYLIB\_PATH](/reference/environment-variables/#ort_dylib_path) for details.
***
## Language-specific notes
[Section titled “Language-specific notes”](#language-specific-notes)
Edge cases and alternative install methods where they come up.
### TypeScript
[Section titled “TypeScript”](#typescript)
Two npm packages target different runtimes:
| Package | Best for | Performance |
| ---------------------- | ---------------------------------- | --------------- |
| `@xberg-io/xberg` | Node.js, Bun — server-side apps | Native (100%) |
| `@xberg-io/xberg-wasm` | Browsers, Deno, Cloudflare Workers | Wasm (\~60-80%) |
Both work with **pnpm** (`pnpm add`) and **Yarn** (`yarn add`) as well.
pnpm workspaces
In monorepos, add this to your root `.npmrc` so platform-specific optional deps resolve correctly:
```ini
auto-install-peers=true
```
Wasm — Browser usage
```html
{
await init();
const bytes = new Uint8Array(await request.arrayBuffer());
const output = await extract({
kind: ExtractInputKind.Bytes,
bytes,
mimeType: "application/pdf",
});
return Response.json({ content: output.results[0]?.content ?? "" });
},
};
```
**Supported runtimes:** Chrome 74+, Firefox 79+, Safari 14+, Edge 79+, Node.js 22+, Deno 1.35+, Cloudflare Workers.
Wasm — package layout (`web` target only)
`@xberg-io/xberg-wasm` publishes a single wasm-pack **`web`** target — a standard ES module you `import` directly in the browser, over a CDN (jsDelivr/unpkg), in Deno via `npm:`, in Cloudflare Workers, and in Node.js 22+ (ESM). Dedicated `bundler`, Node-CommonJS, and Deno target builds are **not** shipped: each is a full copy of the \~100MB wasm binary, and shipping all four pushed the npm package past jsDelivr’s 150MB per-package CDN limit (which broke the live demo’s CDN load). Modern bundlers (Vite, webpack 5, Rollup, esbuild) consume the `web` target directly. Initialize with the package’s default `init()` export before calling `extract`.
Wasm Platform Limitations
The Wasm binding does not support:
* **PaddleOCR, embeddings, reranking, and transcription inference** (all require ONNX Runtime)
* **LLM/VLM features** (liter-llm is not part of the `wasm-target` feature set)
* **Hardware acceleration config** (single-threaded WASM, no GPU access)
* **Native server features** (`api`, `mcp`, CLI binary)
* **Tree-sitter code intelligence** (the 371-language grammar pack exceeds the 50 MB CDN per-file cap)
* **Browser filesystem paths** (use `kind = "bytes"` for browser file uploads; path APIs require Node/Deno/Bun filesystem access)
* **Email codepage config** (EmailConfig not available)
Layout detection (RT-DETR) and document-orientation detection **do** run in Wasm through the pure-Rust `tract` engine (`layout-tract` + `auto-rotate-tract`): the `detectLayout` / `detectOrientation` exports take the `.onnx` weights as streamed bytes, which the JS host fetches and passes in. Pure-Rust extraction formats, OCR via Tesseract WASM, chunking, metadata, tables, language detection, SVG handling, redaction, summarization, QR-code detection, and image extraction also work in WASM. See the [WASM API Reference](/reference/api-wasm/) for details.
### Java
[Section titled “Java”](#java)
* Maven
```xml
io.xberg
xberg
1.1.6
```
* Gradle
```groovy
implementation 'io.xberg:xberg:1.1.6'
```
Requires Java 25+ (FFM/Panama API). Native libraries are bundled in the JAR.
### Elixir
[Section titled “Elixir”](#elixir)
Add to `mix.exs`:
```elixir
def deps do
[
{:xberg, "~> 1.0"}
]
end
```
```bash
mix deps.get
```
Ships prebuilt NIF binaries via RustlerPrecompiled. Falls back to compiling from source if no prebuilt matches your platform (requires Rust).
Windows
The Windows NIF links against ONNX Runtime dynamically. `onnxruntime.dll` must be on your `PATH` at runtime — see the note at the top of this page.
### Go
[Section titled “Go”](#go)
```bash
go get github.com/xberg-io/xberg/packages/go@latest
```
Not a Go module
The repository root is not a Go module — `go get github.com/xberg-io/xberg` (without the `/packages/go` suffix) fails, resolving against a stale Go module-proxy cache entry. Always target the `/packages/go` subdirectory as shown above.
Windows
The Go binding links against ONNX Runtime dynamically on Windows. `onnxruntime.dll` must be on your `PATH` at runtime — see the note at the top of this page.
Windows feature limitations
The Go and C/C++ bindings on Windows (MinGW/GNU target) do not include ORT-dependent inference features: **PaddleOCR**, **layout detection**, **embeddings**, **reranking**, **auto-rotate**, or **transcription**. Tesseract OCR and non-ORT features work normally. These limitations apply only to Windows; Linux and macOS builds include the full feature set.
### Rust
[Section titled “Rust”](#rust)
Enable features selectively in `Cargo.toml`:
Cargo.toml
```toml
[dependencies]
xberg = { version = "1", features = ["pdf", "ocr", "chunking"] }
# Default features are tokio-runtime + simd-utf8; format and analysis features are opt-in.
```
### C / C++
[Section titled “C / C++”](#c--c)
Build the FFI library from source:
```bash
cargo build --release -p xberg-ffi
```
This produces `libxberg_ffi.a` and a header at `crates/xberg-ffi/xberg.h`. Link into your project:
```makefile
HEADER_DIR = path/to/crates/xberg-ffi
LIBDIR = path/to/target/release
CFLAGS = -Wall -Wextra -I$(HEADER_DIR)
LDFLAGS = -L$(LIBDIR) -lxberg_ffi -lpthread -ldl -lm
my_app: my_app.c
$(CC) $(CFLAGS) -o $@ $< $(LDFLAGS)
```
Platform-specific linker flags
**macOS:** add `-framework CoreFoundation -framework Security`
**Windows:** add `-lws2_32 -luserenv -lbcrypt`
Windows
The Windows FFI library links against ONNX Runtime dynamically. `onnxruntime.dll` must be on your `PATH` at runtime — see the note at the top of this page.
[API Reference →](/reference/api-c/)
### Dart / Flutter
[Section titled “Dart / Flutter”](#dart--flutter)
Pure-Dart and Flutter consumers share the same package. Dart SDK 3.0 or higher is required. Flutter is supported on macOS, iOS, Android, Linux, and Windows; Flutter Web is not supported because the runtime is a native dynamic library delivered via flutter\_rust\_bridge. For Flutter projects use `flutter pub add xberg` instead of `dart pub add xberg`.
### Kotlin
[Section titled “Kotlin”](#kotlin)
Kotlin/JVM consumers use the Java artifact (`io.xberg:xberg`) directly; Kotlin interoperates with the generated Java records and static facade.
Kotlin Android uses the Android AAR (`io.xberg:xberg-android`). It embeds JNI libraries for `arm64-v8a` and `x86_64`, targets Android API 21+, and uses the `android-target` feature set, which excludes most ORT-dependent inference features (PaddleOCR, layout detection, embeddings, reranking, transcription). Document-orientation detection runs through the pure-Rust `tract` engine (`auto-rotate-tract`) instead, so it is available on `x86_64` as well as `arm64-v8a`.
### Swift
[Section titled “Swift”](#swift)
Swift Package Manager from `swift-tools-version: 6.0` upward. `Package.swift` declares macOS 13+ and iOS 16+; SwiftPM has no platform declaration for Linux, so no minimum is stated there. The package pulls a prebuilt static library through a `binaryTarget` (`RustBridgeBinary`), so consuming it needs no local cargo build.
### Zig
[Section titled “Zig”](#zig)
Requires Zig 0.16.0 or higher (declared via `minimum_zig_version` in `build.zig.zon`). The Zig binding consumes the C FFI surface from `xberg-ffi` via `linkSystemLibrary`; the build expects the consumer to provide a search path to the prebuilt `libxberg_ffi` and the C header `xberg.h`. The `zig fetch` command above pins the source archive in `build.zig.zon`; wire it into `build.zig` via `b.dependency("xberg", ...)`.
***
## Development setup
[Section titled “Development setup”](#development-setup)
For working on the Xberg repository itself:
```bash
task setup # installs all language toolchains
task lint # linters across all languages
task dev:test # full test suite
```
See [Contributing](/contributing/) for conventions and expectations.
# Quick Start
Use Xberg’s core API through `extract`, `extract_batch`, `ExtractInput`, and the `ExtractionResult` envelope. Install your binding first: [Installation](/getting-started/installation/).
TypeScript users: `@xberg-io/xberg` for Node.js, `@xberg-io/xberg-wasm` for browsers and edge runtimes — see [Language Support](/#language-support).
## Your First Extraction
[Section titled “Your First Extraction”](#your-first-extraction)
Pass an `ExtractInput` with `kind = "uri"` to extract a local path, `file://` URI, or HTTP(S) URL. `extract` returns an `ExtractionResult` with a `results` list:
* Python
Tests URI extraction API
Python
```python
import asyncio
from xberg import extract, ExtractInput
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
result = await extract(input)
print(result.results[0].content)
asyncio.run(main())
```
* TypeScript / Node.js
Tests URI extraction API
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const result = await extract(input);
console.log(result.results?.[0]?.content);
}
void main();
```
* WebAssembly
Tests URI extraction API
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, undefined);
console.log(result.results[0].content);
}
void main();
```
* Rust
Tests URI extraction API
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config = Default::default();
let result = extract(input, &config).await.expect("call failed");
println!("{:?}", result.results[0].content);
}
```
* Go
Tests URI extraction API
Go
```go
package main
import (
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
fmt.Printf("%+v\n", result.Results[0].Content)
}
```
* Java
Tests URI extraction API
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var result = Xberg.extract(input, ExtractionConfig.builder().build());
System.out.println(result.results().get(0).content());
}
}
```
* Kotlin (Android)
Tests URI extraction API
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val configDefault = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, configDefault)
println(result.results.first().content)
}
```
* C#
Tests URI extraction API
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig());
Console.WriteLine(result.Results[0].Content);
```
* Swift
Tests URI extraction API
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}")
debugPrint(result.results()[0].content())
```
* Ruby
Tests URI extraction API
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'))
puts result.results[0].content.inspect
```
* PHP
Tests URI extraction API
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, null);
var_dump($result->getResults()[0]->content);
```
* Elixir
Tests URI extraction API
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value)
IO.inspect(Enum.at(result.results, 0).content)
```
* Dart
Tests URI extraction API
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result.results[0].content);
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests URI extraction API
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests URI extraction API
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle result = xberg_extract(input_handle, 0);
xberg_extract_input_free(input_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
For the command line:
Bash
```bash
# Extract to stdout
xberg extract document.pdf
# Save to file using shell redirection
xberg extract document.pdf > output.txt
# Extract with JSON format (includes metadata)
xberg extract document.pdf --format json
```
## Handle Errors
[Section titled “Handle Errors”](#handle-errors)
Handle extraction failures through your binding’s typed error surface. This example rejects an unsupported MIME type; missing files, parse failures, and OCR failures use the same language-appropriate error path:
* Python
Error when extracting with unsupported MIME type
Python
```python
import asyncio
from pathlib import Path
from xberg import extract, ExtractInput
from xberg._xberg import ExtractionConfig
from xberg import XbergError
async def main() -> None:
try:
input = ExtractInput.from_json("{\"bytes\":\"text/plain.txt\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}")
config = ExtractionConfig.from_json("{}")
await extract(input, config)
except XbergError as error:
print(f"{type(error).__name__}: {error}")
asyncio.run(main())
```
* TypeScript / Node.js
Error when extracting with unsupported MIME type
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { bytes: await (await import("node:fs/promises")).readFile("text/plain.txt"), config: { }, filename: "plain.txt", kind: ExtractInputKind.Bytes, mimeType: "application/x-nonexistent" };
try {
await extract(input);
} catch (error) {
if (error instanceof Error) {
console.error(`${error.name}: ${error.message}`);
}
}
}
void main();
```
* WebAssembly
Error when extracting with unsupported MIME type
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, WasmFileExtractionConfig, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = await (async () => { const _u0 = WasmExtractInput.default(); _u0.bytes = await (await import("node:fs/promises")).readFile("text/plain.txt"); _u0.config = await (async () => { const _u1 = WasmFileExtractionConfig.default(); return _u1; })(); _u0.filename = "plain.txt"; _u0.kind = WasmExtractInputKind.Bytes; _u0.mimeType = "application/x-nonexistent"; return _u0; })();
try {
await extract(input, { });
} catch (error) {
console.error(String(error));
}
}
void main();
```
* Rust
Error when extracting with unsupported MIME type
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let mut input_json: serde_json::Value = serde_json::from_str(r#"{"bytes":"text/plain.txt","config":{},"filename":"plain.txt","kind":"bytes","mime_type":"application/x-nonexistent"}"#).unwrap();
let input_file_0 = std::fs::read(r#"text/plain.txt"#).expect("file read failed");
*input_json.pointer_mut(r#"/bytes"#).expect("docs file field missing") = serde_json::json!(input_file_0);
let input = serde_json::from_value::(input_json).unwrap();
let config_json: serde_json::Value = serde_json::from_str(r#"{}"#).unwrap();
let config = serde_json::from_value(config_json).unwrap();
let result = extract(input, &config).await;
match result {
Ok(value) => println!("{:?}", value),
Err(error) => println!("{error}"),
}
}
```
* Go
Error when extracting with unsupported MIME type
Go
```go
package main
import (
"errors"
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
"os"
)
func ptr[T any](value T) *T { return &value }
func mustReadFile(path string) []byte {
content, err := os.ReadFile(path)
if err != nil {
panic(err)
}
return content
}
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindBytes),
Bytes: mustReadFile(`text/plain.txt`),
MimeType: ptr(`application/x-nonexistent`),
Filename: ptr(`plain.txt`),
Config: &xberg.FileExtractionConfig{},
}
config := xberg.ExtractionConfig{}
_, err := xberg.Extract(input, config)
var typedError xberg.Error
if errors.As(err, &typedError) {
fmt.Fprintf(os.Stderr, "%T: %v\n", typedError, typedError)
}
}
```
* Java
Error when extracting with unsupported MIME type
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
try {
var inputFile0 = java.util.Base64.getEncoder().encodeToString(
java.nio.file.Files.readAllBytes(java.nio.file.Path.of("text/plain.txt"))
);
var inputJson = "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}";
inputJson = inputJson.replace("__ALEF_DOC_FILE_0__", inputFile0);
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var configJson = "{}";
var config = JsonUtil.fromJson(configJson, ExtractionConfig.class);
var result = Xberg.extract(input, config);
System.out.println(result);
} catch (XbergRsException error) {
System.err.println(error.getClass().getSimpleName() + ": " + error.getMessage());
}
}
}
```
* Kotlin (Android)
Error when extracting with unsupported MIME type
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
try {
val inputFile0 = java.util.Base64.getEncoder().encodeToString(java.nio.file.Files.readAllBytes(java.nio.file.Path.of("text/plain.txt")))
val input = mapper.readValue("{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}".replace("__ALEF_DOC_FILE_0__", inputFile0), ExtractInput::class.java)
val config = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, config)
} catch (error: Exception) {
System.err.println("${error::class.simpleName}: ${error.message}")
}
}
```
* C#
Error when extracting with unsupported MIME type
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
try
{
var result = await XbergConverter.ExtractAsync(new ExtractInput { Bytes = System.IO.File.ReadAllBytes("text/plain.txt"), Config = new FileExtractionConfig(), Filename = "plain.txt", Kind = JsonSerializer.Deserialize("\"bytes\"", ConfigOptions)!, MimeType = "application/x-nonexistent" }, new ExtractionConfig());
}
catch (Exception error)
{
Console.Error.WriteLine($"{error.GetType().Name}: {error.Message}");
}
```
* Swift
Error when extracting with unsupported MIME type
Swift
```swift
import Xberg
do {
_ = try await Xberg.extract("{\"bytes\":\"text/plain.txt\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}", "{}")
} catch {
print("\(type(of: error)): \(error)")
}
```
* Ruby
Error when extracting with unsupported MIME type
Ruby
```ruby
require "xberg"
begin
result = Xberg.extract(Xberg::ExtractInput.new(bytes: File.binread('text/plain.txt').bytes, config: { }, filename: 'plain.txt', kind: 'bytes', mime_type: 'application/x-nonexistent'), { })
rescue StandardError => error
warn "#{error.class}: #{error.message}"
end
```
* PHP
Error when extracting with unsupported MIME type
PHP
```php
"text/plain.txt", "config" => [], "filename" => "plain.txt", "kind" => "bytes", "mimeType" => "application/x-nonexistent"]));
try {
Xberg::extract($input, []);
} catch (Throwable $error) {
echo $error::class . ': ' . $error->getMessage() . "\n";
}
```
* Elixir
Error when extracting with unsupported MIME type
Elixir
```elixir
try do
input_value = %Xberg.ExtractInput{bytes: :binary.bin_to_list(File.read!("text/plain.txt")), config: %{}, filename: "plain.txt", kind: "bytes", mime_type: "application/x-nonexistent"}
result = Xberg.extract_async(input_value, "{}")
rescue
error -> IO.puts(:stderr, "#{inspect(error.__struct__)}: #{Exception.message(error)}")
end
```
* Dart
Error when extracting with unsupported MIME type
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
try {
final input = await createExtractInputFromJson(json: '{"bytes":"text/plain.txt","config":{},"filename":"plain.txt","kind":"bytes","mime_type":"application/x-nonexistent"}');
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result);
} on XbergError catch (error) {
stderr.writeln('${error.runtimeType}: $error');
}
} finally {
RustLib.dispose();
}
}
```
* Zig
Error when extracting with unsupported MIME type
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
var gpa: std.heap.DebugAllocator(.{}) = .init;
defer _ = gpa.deinit();
const allocator = gpa.allocator();
var input_file_0_threaded = std.Io.Threaded.init(allocator, .{});
defer input_file_0_threaded.deinit();
const input_file_0_io = input_file_0_threaded.io();
const input_file_0 = try std.Io.Dir.cwd().readFileAlloc(input_file_0_io, "text/plain.txt", allocator, .unlimited);
defer allocator.free(input_file_0);
const input_file_0_json = try std.json.Stringify.valueAlloc(allocator, input_file_0, .{ .emit_strings_as_arrays = true });
defer allocator.free(input_file_0_json);
const input_json_0 = try std.mem.replaceOwned(u8, allocator, "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}", "\"__ALEF_DOC_FILE_0__\"", input_file_0_json);
defer allocator.free(input_json_0);
if (xberg.extract(input_json_0, "{}")) |_| {
return error.TestUnexpectedResult;
} else |err| { std.debug.print("call failed as expected: {s}\n", .{@errorName(err)}); }
}
```
* C
Error when extracting with unsupported MIME type
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
const char *input_json_base = "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}";
FILE *input_file_0 = fopen("text/plain.txt", "rb");
if (input_file_0 == NULL) return EXIT_FAILURE;
fseek(input_file_0, 0, SEEK_END);
long input_size_0 = ftell(input_file_0);
if (input_size_0 < 0) { fclose(input_file_0); return EXIT_FAILURE; }
rewind(input_file_0);
uint8_t *input_bytes_0 = malloc(input_size_0 > 0 ? (size_t)input_size_0 : 1);
if (input_bytes_0 == NULL) { fclose(input_file_0); return EXIT_FAILURE; }
if (fread(input_bytes_0, 1, (size_t)input_size_0, input_file_0) != (size_t)input_size_0) { free(input_bytes_0); fclose(input_file_0); return EXIT_FAILURE; }
fclose(input_file_0);
char *input_bytes_json_0 = malloc((size_t)input_size_0 * 4 + 3);
if (input_bytes_json_0 == NULL) { free(input_bytes_0); return EXIT_FAILURE; }
size_t input_offset_0 = 0;
input_bytes_json_0[input_offset_0++] = '[';
for (long i = 0; i < input_size_0; ++i) {
input_offset_0 += (size_t)snprintf(input_bytes_json_0 + input_offset_0, 5, "%s%u", i == 0 ? "" : ",", input_bytes_0[i]);
}
input_bytes_json_0[input_offset_0++] = ']';
input_bytes_json_0[input_offset_0] = '\0';
free(input_bytes_0);
const char *input_marker_0 = "\"__ALEF_DOC_FILE_0__\"";
const char *input_position_0 = strstr(input_json_base, input_marker_0);
if (input_position_0 == NULL) { free(input_bytes_json_0); return EXIT_FAILURE; }
size_t input_prefix_0 = (size_t)(input_position_0 - input_json_base);
size_t input_json_size_0 = strlen(input_json_base) - strlen(input_marker_0) + strlen(input_bytes_json_0) + 1;
char *input_json_0 = malloc(input_json_size_0);
if (input_json_0 == NULL) { free(input_bytes_json_0); return EXIT_FAILURE; }
snprintf(input_json_0, input_json_size_0, "%.*s%s%s", (int)input_prefix_0, input_json_base, input_bytes_json_0, input_position_0 + strlen(input_marker_0));
free(input_bytes_json_0);
XBERGAlefHandle input_handle = xberg_extract_input_from_json(input_json_0);
free(input_json_0);
XBERGAlefHandle config_handle = xberg_extraction_config_from_json("{}");
XBERGAlefHandle result = xberg_extract(input_handle, config_handle);
if (result != 0) { return EXIT_FAILURE; }
xberg_extract_input_free(input_handle);
xberg_extraction_config_free(config_handle);
return EXIT_SUCCESS;
}
```
## OCR for Scanned Documents
[Section titled “OCR for Scanned Documents”](#ocr-for-scanned-documents)
Xberg runs OCR automatically when it detects an image or scanned PDF. You can also force OCR on any document:
* C
C
```c
#include "xberg.h"
#include
int main(void) {
const char *config_json = "{"
"\"ocr\": {\"tesseract\": {\"language\": \"eng\"}}"
"}";
XBERGAlefHandle config = xberg_extraction_config_from_json(config_json);
if (config == 0) {
fprintf(stderr, "config parse failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
return 1;
}
XBERGAlefHandle input = xberg_extract_input_from_uri("scanned.png");
if (input == 0) {
fprintf(stderr, "Failed to create input (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extraction_config_free(config);
return 1;
}
XBERGAlefHandle result = xberg_extract(input, config);
if (result != 0) {
char *results = xberg_extraction_result_results(result);
if (results) {
printf("OCR results: %s\n", results);
}
xberg_free_string(results);
} else {
fprintf(stderr, "OCR error (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
}
xberg_extract_input_free(input);
xberg_extraction_result_free(result);
xberg_extraction_config_free(config);
return 0;
}
```
* C#
C#
```csharp
using Xberg;
var config = new ExtractionConfig
{
ForceOcr = true,
Ocr = new OcrConfig
{
Backend = "tesseract",
Language = new List { "eng" },
},
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("scanned.pdf"), config)).Results[0];
Console.WriteLine(result.Content);
Console.WriteLine(result.DetectedLanguages);
```
* Dart
Dart
```dart
import 'package:xberg/xberg.dart';
Future main() async {
// `ExtractionConfig` is a generated data class with no defaults, so build it
// from JSON: every field you omit keeps its Rust-side default value.
final config = await createExtractionConfigFromJson(json: '''
{
"force_ocr": true,
"ocr": {
"backend": "tesseract",
"language": ["eng"]
}
}
''');
const input = ExtractInput(
kind: ExtractInputKind.uri,
uri: 'scanned.pdf',
);
final output = await XbergBridge.extract(input, config: config);
final document = output.results.first;
print(document.content);
}
```
* Go
Go
```go
package main
import (
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
cfg := xberg.ExtractionConfig{
Ocr: &xberg.OcrConfig{
Backend: xberg.Ptr("tesseract"),
Language: []string{"eng"},
},
}
input := xberg.ExtractInputFromURI("scanned.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
log.Fatalf("extract failed: %v", err)
}
log.Println(len(result.Results[0].Content))
}
```
* Java
Java
```java
import io.xberg.ExtractInput;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractionResult;
import io.xberg.OcrConfig;
import io.xberg.Xberg;
import io.xberg.XbergRsException;
import java.util.List;
public class Main {
public static void main(String[] args) {
try {
ExtractionConfig config = ExtractionConfig.builder()
.withForceOcr(true)
.withOcr(OcrConfig.builder()
.withBackend("tesseract")
.withLanguage(List.of("eng"))
.build())
.build();
ExtractInput input = ExtractInput.builder()
.withKind(ExtractInputKind.Uri)
.withUri("scanned.pdf")
.build();
ExtractionResult output = Xberg.extract(input, config);
ExtractedDocument document = output.results().get(0);
System.out.println(document.content());
} catch (XbergRsException e) {
System.err.println("Extraction failed: " + e.getMessage());
}
}
}
```
* Kotlin
Kotlin
```kotlin
import io.xberg.*
private const val DEFAULT_MAX_ARCHIVE_DEPTH = 3L
private const val DEFAULT_EXTRACTION_TIMEOUT_SECS = 600L
private const val DEFAULT_MAX_EMBEDDED_FILE_BYTES = 50L * 1024L * 1024L
fun main() {
val ocr = OcrConfig(backend = "tesseract", language = listOf("eng"))
val config = ExtractionConfig(
ocr = ocr,
extractionTimeoutSecs = DEFAULT_EXTRACTION_TIMEOUT_SECS,
maxEmbeddedFileBytes = DEFAULT_MAX_EMBEDDED_FILE_BYTES,
url = UrlExtractionConfig(crawl = CrawlConfig(ssrf = SsrfPolicy())),
maxArchiveDepth = DEFAULT_MAX_ARCHIVE_DEPTH,
)
val resultOutput = Xberg.extract(
ExtractInput(kind = ExtractInputKind.URI, uri = "scanned.pdf"),
config,
)
val result = resultOutput.results.first()
println(result.content)
}
```
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig, OcrConfig
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
ocr=OcrConfig(backend="tesseract", language=["eng"])
)
result = await extract(ExtractInput(uri="scanned.pdf"), config)
content: str = result.results[0].content
preview: str = content[:100]
total_length: int = len(content)
print(f"Extracted content (preview): {preview}")
print(f"Total characters: {total_length}")
asyncio.run(main())
```
* Ruby
Ruby
```ruby
require 'xberg'
ocr_config = Xberg::OcrConfig.new(
backend: 'tesseract',
language: 'eng'
)
config = Xberg::ExtractionConfig.new(ocr: ocr_config)
input = Xberg::ExtractInput.new(uri: 'scanned.pdf')
result = Xberg.extract(input, config)
puts result.results.first.content
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, OcrConfig};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig {
ocr: Some(OcrConfig {
backend: "tesseract".to_string(),
language: vec!["eng".to_string()],
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("scanned.pdf"), &config).await?;
println!("{}", output.results[0].content);
Ok(())
}
```
* Swift
Swift
```swift
import Foundation
import Xberg
import RustBridge
let configJson = """
{
"ocr": {
"backend": "tesseract",
"language": "eng"
}
}
"""
let config = try extractionConfigFromJson(configJson)
let input = try extractInputFromJson(#"{"kind":"uri","uri":"scanned.pdf"}"#)
let resultOutput = try await extract(input: input, config: config)
let result = resultOutput.results().get(index: 0)!
print(result.content().toString())
```
* Elixir
Elixir
```elixir
alias Xberg.ExtractionConfig
config = %ExtractionConfig{
ocr: %{"enabled" => true, "backend" => "tesseract"}
}
{:ok, output} = Xberg.extract(input: %Xberg.ExtractInput{kind: :uri, uri: "scanned_document.pdf"}, config: config)
result = List.first(output.results)
content = result.content
IO.puts("OCR Extracted content:")
IO.puts(content)
IO.puts("Metadata: #{inspect(result.metadata)}")
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
ocr: {
backend: "tesseract",
language: ["eng"],
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "scanned.pdf" }, config);
console.log(output.results?.[0]?.content);
```
* Wasm
WASM (Browser)
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const fileInput = document.getElementById("file") as HTMLInputElement;
const file = fileInput.files?.[0];
if (file) {
const bytes = new Uint8Array(await file.arrayBuffer());
const result = await extract(
{ kind: "bytes", bytes, mimeType: file.type },
{
ocr: {
enabled: true,
backend: "tesseract",
language: ["eng"],
},
},
);
console.log(result.results[0].content);
}
```
WASM (Node.js / Deno / Bun)
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
// Outside the browser the default `fetch`-based init cannot read a `file://`
// URL: pass the `xberg_wasm_bg.wasm` bytes yourself, either as
// `init({ module_or_path: bytes })` or via the synchronous `initSync({ module: bytes })`.
await init();
const result = await extract(
{ kind: "uri", uri: "./scanned_document.png" },
{
ocr: {
enabled: true,
backend: "tesseract",
language: ["eng"],
},
},
);
console.log(result.results[0].content);
```
* Zig
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
var gpa: std.heap.DebugAllocator(.{}) = .init;
defer _ = gpa.deinit();
const allocator = gpa.allocator();
const config_json =
\\{
\\ "ocr": {
\\ "backend": "tesseract",
\\ "language": "eng"
\\ }
\\}
;
const input_json = "{\"kind\":\"uri\",\"uri\":\"scanned.pdf\"}";
const output_json = try xberg.extract(input_json, config_json);
defer std.heap.c_allocator.free(output_json);
const owned = try allocator.dupe(u8, output_json);
defer allocator.free(owned);
std.debug.print("{s}\n", .{owned});
}
```
* CLI
Bash
```bash
xberg extract scanned.pdf --ocr true
```
## Process Multiple Inputs
[Section titled “Process Multiple Inputs”](#process-multiple-inputs)
Pass a list of document URIs to `extract_batch`. Use `extract_batch_bytes` for in-memory data; `ExtractInput` variants can combine URI and byte inputs when a binding exposes the unified API.
* Python
extract\_batch over URI inputs
Python
```python
import asyncio
from xberg import extract_batch
async def main() -> None:
inputs = [{"kind": "uri", "uri": "https://example.com/pdf/fake_memo.pdf"}, {"kind": "uri", "uri": "https://example.com/text/fake_text.txt"}]
result = await extract_batch(inputs)
for result in result.results:
print(result.content)
asyncio.run(main())
```
* TypeScript / Node.js
extract\_batch over URI inputs
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extractBatch } from "@xberg-io/xberg";
async function main() {
const result = await extractBatch([{ kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" } as ExtractInput, { kind: ExtractInputKind.Uri, uri: "https://example.com/text/fake_text.txt" } as ExtractInput]);
for (const item of result.results ?? []) {
console.log(item.content);
}
}
void main();
```
* WebAssembly
extract\_batch over URI inputs
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extractBatch } from "@xberg-io/xberg-wasm";
async function main() {
const result = await extractBatch([(() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })(), (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/text/fake_text.txt"; return _u0; })()], undefined);
for (const item of result.results) {
console.log(item.content);
}
}
void main();
```
* Rust
extract\_batch over URI inputs
Rust
```rust
use xberg::extract_batch;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let inputs_json: serde_json::Value = serde_json::from_str(r#"[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]"#).unwrap();
let inputs = serde_json::from_value::>(inputs_json).unwrap();
let config = Default::default();
let result = extract_batch(inputs, &config).await.expect("call failed");
for result in result.results.iter() {
println!("{}", result.content);
}
}
```
* Go
extract\_batch over URI inputs
Go
```go
package main
import (
"encoding/json"
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func main() {
var inputs []xberg.ExtractInput
if err := json.Unmarshal([]byte(`[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]`), &inputs); err != nil {
panic(fmt.Sprintf("config parse failed: %v", err))
}
config := xberg.ExtractionConfig{}
result, err := xberg.ExtractBatch(inputs, config)
if err != nil {
panic(err)
}
for _, result := range result.Results {
fmt.Printf("%v\n", result.Content)
}
}
```
* Java
extract\_batch over URI inputs
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var result = Xberg.extractBatch(java.util.Arrays.asList(JsonUtil.fromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput.class), JsonUtil.fromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ExtractInput.class)), ExtractionConfig.builder().build());
for (var item : result.results()) {
System.out.println(item.content());
}
}
}
```
* Kotlin (Android)
extract\_batch over URI inputs
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val configDefault = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extractBatch(listOf(mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java), mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ExtractInput::class.java)), configDefault)
for (result in result.results) {
println(result.content)
}
}
```
* C#
extract\_batch over URI inputs
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractBatchAsync(new List() { JsonSerializer.Deserialize("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ConfigOptions)!, JsonSerializer.Deserialize("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ConfigOptions)! }, new ExtractionConfig());
foreach (var resultItem in result.Results)
{
Console.WriteLine(resultItem.Content);
}
```
* Swift
extract\_batch over URI inputs
Swift
```swift
import Xberg
let _item_inputsArray_0 = try Xberg.extractInputFromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
let _item_inputsArray_1 = try Xberg.extractInputFromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}")
let inputsArray = [_item_inputsArray_0, _item_inputsArray_1]
let configObj = try Xberg.extractionConfigFromJson("{}")
let result = try await Xberg.extractBatch(inputs: inputsArray, config: configObj)
for result in result.results() {
print(result.content())
}
```
* Ruby
extract\_batch over URI inputs
Ruby
```ruby
require "xberg"
result = Xberg.extract_batch([{ 'kind' => 'uri', 'uri' => 'https://example.com/pdf/fake_memo.pdf' }, { 'kind' => 'uri', 'uri' => 'https://example.com/text/fake_text.txt' }])
result.results.each do |result|
puts result.content
end
```
* PHP
extract\_batch over URI inputs
PHP
```php
getResults() as $result) {
echo $result->getContent(), PHP_EOL;
}
```
* Elixir
extract\_batch over URI inputs
Elixir
```elixir
result = Xberg.extract_batch_async([%{"kind" => "uri", "uri" => "https://example.com/pdf/fake_memo.pdf"}, %{"kind" => "uri", "uri" => "https://example.com/text/fake_text.txt"}])
Enum.each(result.results, fn result ->
IO.puts(result.content)
end)
```
* Dart
extract\_batch over URI inputs
Dart
```dart
import 'dart:convert';
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final inputs = await Future.wait((jsonDecode(r'[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]') as List).map((element) => createExtractInputFromJson(json: jsonEncode(element))));
final result = await XbergBridge.extractBatch(inputs);
for (final result in result.results) {
stdout.writeln(result.content);
}
} finally {
RustLib.dispose();
}
}
```
* Zig
extract\_batch over URI inputs
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract_batch("[{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"},{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}]", "{}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
extract\_batch over URI inputs
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle result = xberg_extract_batch("[{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"},{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}]", 0);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
For command-line batches:
Bash
```bash
# Process multiple files
xberg extract doc1.pdf doc2.docx doc3.pptx
# Use glob patterns
xberg extract documents/**/*.pdf
```
## Read Document Metadata
[Section titled “Read Document Metadata”](#read-document-metadata)
Every `ExtractionResult` contains document metadata in `results`. Each `ExtractedDocument` includes format-specific metadata: page count for PDFs, sheet names for Excel, dimensions for images:
* C
C
```c
#include "xberg.h"
#include
int main(void) {
/* A config handle is required — zero is rejected as an invalid handle. */
XBERGAlefHandle config = xberg_extraction_config_from_json("{}");
if (config == 0) {
fprintf(stderr, "config init failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
return 1;
}
XBERGAlefHandle input = xberg_extract_input_from_uri("document.pdf");
if (input == 0) {
fprintf(stderr, "Failed to create input (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extraction_config_free(config);
return 1;
}
XBERGAlefHandle result = xberg_extract(input, config);
if (result == 0) {
fprintf(stderr, "extraction failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extract_input_free(input);
xberg_extraction_config_free(config);
return 1;
}
char *results_json = xberg_extraction_result_results(result);
if (results_json) {
printf("Results: %s\n", results_json);
}
xberg_free_string(results_json);
char *full_json = xberg_extraction_result_to_json(result);
if (full_json) {
printf("Full result: %s\n", full_json);
}
xberg_free_string(full_json);
xberg_extract_input_free(input);
xberg_extraction_result_free(result);
xberg_extraction_config_free(config);
return 0;
}
```
* C#
C#
```csharp
using Xberg;
var config = new ExtractionConfig
{
PdfOptions = new PdfConfig { ExtractMetadata = true }
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
if (result.Metadata?.Format is FormatMetadata.Pdf pdfFormat)
{
var pdfMeta = pdfFormat.Value;
Console.WriteLine($"Pages: {pdfMeta.PageCount}");
Console.WriteLine($"Author: {string.Join(", ", result.Metadata.Authors ?? new List())}");
Console.WriteLine($"Title: {result.Metadata.Title}");
}
var htmlResult = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("page.html"), config)).Results[0];
if (htmlResult.Metadata?.Format is FormatMetadata.Html htmlFormat)
{
var htmlMeta = htmlFormat.Value;
Console.WriteLine($"Title: {htmlMeta.Title}");
Console.WriteLine($"Description: {htmlMeta.Description}");
// Access keywords as array
if (htmlMeta.Keywords != null && htmlMeta.Keywords.Count > 0)
{
Console.WriteLine($"Keywords: {string.Join(", ", htmlMeta.Keywords)}");
}
// Access canonical URL (renamed from canonical)
if (htmlMeta.CanonicalUrl != null)
{
Console.WriteLine($"Canonical URL: {htmlMeta.CanonicalUrl}");
}
// Access Open Graph fields from dictionary
if (htmlMeta.OpenGraph != null && htmlMeta.OpenGraph.Count > 0)
{
if (htmlMeta.OpenGraph.ContainsKey("image"))
Console.WriteLine($"Open Graph Image: {htmlMeta.OpenGraph["image"]}");
if (htmlMeta.OpenGraph.ContainsKey("title"))
Console.WriteLine($"Open Graph Title: {htmlMeta.OpenGraph["title"]}");
if (htmlMeta.OpenGraph.ContainsKey("type"))
Console.WriteLine($"Open Graph Type: {htmlMeta.OpenGraph["type"]}");
}
// Access Twitter Card fields from dictionary
if (htmlMeta.TwitterCard != null && htmlMeta.TwitterCard.Count > 0)
{
if (htmlMeta.TwitterCard.ContainsKey("card"))
Console.WriteLine($"Twitter Card Type: {htmlMeta.TwitterCard["card"]}");
if (htmlMeta.TwitterCard.ContainsKey("creator"))
Console.WriteLine($"Twitter Creator: {htmlMeta.TwitterCard["creator"]}");
}
// Access new fields
if (htmlMeta.Language != null)
Console.WriteLine($"Language: {htmlMeta.Language}");
if (htmlMeta.TextDirection != null)
Console.WriteLine($"Text Direction: {htmlMeta.TextDirection}");
// Access headers
if (htmlMeta.Headers != null && htmlMeta.Headers.Count > 0)
Console.WriteLine($"Headers: {string.Join(", ", htmlMeta.Headers.Select(h => h.Text))}");
// Access links
if (htmlMeta.Links != null && htmlMeta.Links.Count > 0)
{
foreach (var link in htmlMeta.Links)
Console.WriteLine($"Link: {link.Href} ({link.Text})");
}
// Access images
if (htmlMeta.Images != null && htmlMeta.Images.Count > 0)
Console.WriteLine($"Images: {string.Join(", ", htmlMeta.Images.Select(i => i.Src))}");
// Access structured data
if (htmlMeta.StructuredData != null && htmlMeta.StructuredData.Count > 0)
Console.WriteLine($"Structured Data items: {htmlMeta.StructuredData.Count}");
}
```
* Dart
Dart
```dart
import 'package:xberg/xberg.dart';
Future main() async {
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(
const ExtractInput(kind: ExtractInputKind.uri, uri: 'document.pdf'),
config: config,
);
final metadata = result.results.first.metadata;
if (metadata.title != null) {
print('Title: ${metadata.title}');
}
if (metadata.subject != null) {
print('Subject: ${metadata.subject}');
}
if (metadata.authors != null) {
print('Authors: ${metadata.authors!.join(', ')}');
}
if (metadata.keywords != null) {
print('Keywords: ${metadata.keywords!.join(', ')}');
}
if (metadata.language != null) {
print('Language: ${metadata.language}');
}
if (metadata.createdAt != null) {
print('Created: ${metadata.createdAt}');
}
if (metadata.modifiedAt != null) {
print('Modified: ${metadata.modifiedAt}');
}
if (metadata.extractionDurationMs != null) {
print('Extraction took: ${metadata.extractionDurationMs} ms');
}
for (final entry in metadata.additional.entries) {
print('Additional[${entry.key}]: ${entry.value}');
}
}
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"strings"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, xberg.ExtractionConfig{})
if err != nil {
log.Fatalf("extract pdf: %v", err)
}
// Access PDF metadata
if format := result.Results[0].Metadata.Format; format != nil && format.Pdf != nil {
pdf := format.Pdf
if pdf.PageCount != nil {
fmt.Printf("Pages: %d\n", *pdf.PageCount)
}
if len(result.Results[0].Metadata.Authors) > 0 {
fmt.Printf("Authors: %s\n", strings.Join(result.Results[0].Metadata.Authors, ", "))
}
if result.Results[0].Metadata.Title != nil {
fmt.Printf("Title: %s\n", *result.Results[0].Metadata.Title)
}
}
// Access HTML metadata
htmlInput := xberg.ExtractInputFromURI("page.html")
htmlResult, err := xberg.Extract(*htmlInput, xberg.ExtractionConfig{})
if err != nil {
log.Fatalf("extract html: %v", err)
}
if format := htmlResult.Results[0].Metadata.Format; format != nil && format.HTML != nil {
html := format.HTML
if html.Title != nil {
fmt.Printf("Title: %s\n", *html.Title)
}
if html.Description != nil {
fmt.Printf("Description: %s\n", *html.Description)
}
// Access keywords as array
if len(html.Keywords) > 0 {
fmt.Printf("Keywords: %s\n", strings.Join(html.Keywords, ", "))
}
// Access canonical URL (renamed from canonical)
if html.CanonicalURL != nil {
fmt.Printf("Canonical URL: %s\n", *html.CanonicalURL)
}
// Access Open Graph fields from map
if len(html.OpenGraph) > 0 {
if image, ok := html.OpenGraph["image"]; ok {
fmt.Printf("Open Graph Image: %s\n", image)
}
if ogTitle, ok := html.OpenGraph["title"]; ok {
fmt.Printf("Open Graph Title: %s\n", ogTitle)
}
if ogType, ok := html.OpenGraph["type"]; ok {
fmt.Printf("Open Graph Type: %s\n", ogType)
}
}
// Access Twitter Card fields from map
if len(html.TwitterCard) > 0 {
if card, ok := html.TwitterCard["card"]; ok {
fmt.Printf("Twitter Card Type: %s\n", card)
}
if creator, ok := html.TwitterCard["creator"]; ok {
fmt.Printf("Twitter Creator: %s\n", creator)
}
}
// Access new fields
if html.Language != nil {
fmt.Printf("Language: %s\n", *html.Language)
}
if html.TextDirection != nil {
fmt.Printf("Text Direction: %s\n", *html.TextDirection)
}
// Access headers
if len(html.Headers) > 0 {
headers := make([]string, len(html.Headers))
for i, h := range html.Headers {
headers[i] = h.Text
}
fmt.Printf("Headers: %s\n", strings.Join(headers, ", "))
}
// Access links
if len(html.Links) > 0 {
for _, link := range html.Links {
fmt.Printf("Link: %s (%s)\n", link.Href, link.Text)
}
}
// Access images
if len(html.Images) > 0 {
for _, image := range html.Images {
fmt.Printf("Image: %s\n", image.Src)
}
}
// Access structured data
if len(html.StructuredData) > 0 {
fmt.Printf("Structured data items: %d\n", len(html.StructuredData))
}
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractedDocument;
import io.xberg.Metadata;
import io.xberg.XbergRsException;
import java.util.Map;
import java.util.List;
public class Main {
public static void main(String[] args) {
try {
var resultOutput = Xberg.extract(
io.xberg.ExtractInput.builder()
.withKind(io.xberg.ExtractInputKind.Uri)
.withUri("document.pdf")
.build(),
io.xberg.ExtractionConfig.builder().build()
);
ExtractedDocument result = resultOutput.results().get(0);
// Metadata is flat — format-specific fields are at the top level
Metadata metadata = result.metadata();
if (metadata.title() != null) {
System.out.println("Title: " + metadata.title());
}
if (metadata.authors() != null) {
System.out.println("Authors: " + String.join(", ", metadata.authors()));
}
// Format-specific fields are in the additional map
Map extra = metadata.additional();
if (extra != null && extra.get("page_count") != null) {
System.out.println("Pages: " + extra.get("page_count"));
}
// Access HTML metadata
var htmlResultOutput = Xberg.extract(
io.xberg.ExtractInput.builder()
.withKind(io.xberg.ExtractInputKind.Uri)
.withUri("page.html")
.build(),
io.xberg.ExtractionConfig.builder().build()
);
ExtractedDocument htmlResult = htmlResultOutput.results().get(0);
Metadata htmlMeta = htmlResult.metadata();
if (htmlMeta.title() != null) {
System.out.println("Title: " + htmlMeta.title());
}
Map htmlExtra = htmlMeta.additional();
String description = htmlExtra != null ? (String) htmlExtra.get("description") : null;
if (description != null) {
System.out.println("Description: " + description);
}
// Access keywords as array
if (htmlMeta.keywords() != null) {
System.out.println("Keywords: " + htmlMeta.keywords());
}
// Access canonical URL (renamed from canonical)
String canonicalUrl = htmlExtra != null ? (String) htmlExtra.get("canonical_url") : null;
if (canonicalUrl != null) {
System.out.println("Canonical URL: " + canonicalUrl);
}
// Access Open Graph fields from map
@SuppressWarnings("unchecked")
Map openGraph = htmlExtra != null ? (Map) htmlExtra.get("open_graph") : null;
if (openGraph != null) {
System.out.println("Open Graph Image: " + openGraph.get("image"));
System.out.println("Open Graph Title: " + openGraph.get("title"));
System.out.println("Open Graph Type: " + openGraph.get("type"));
}
// Access Twitter Card fields from map
@SuppressWarnings("unchecked")
Map twitterCard = htmlExtra != null ? (Map) htmlExtra.get("twitter_card") : null;
if (twitterCard != null) {
System.out.println("Twitter Card Type: " + twitterCard.get("card"));
System.out.println("Twitter Creator: " + twitterCard.get("creator"));
}
// Access new fields
if (htmlMeta.language() != null) {
System.out.println("Language: " + htmlMeta.language());
}
String textDirection = htmlExtra != null ? (String) htmlExtra.get("text_direction") : null;
if (textDirection != null) {
System.out.println("Text Direction: " + textDirection);
}
// Access headers
@SuppressWarnings("unchecked")
List> headers = htmlExtra != null ? (List>) htmlExtra.get("headers") : null;
if (headers != null) {
headers.stream()
.map(h -> h.get("text"))
.forEach(text -> System.out.print(text + ", "));
System.out.println();
}
// Access links
@SuppressWarnings("unchecked")
List> links = htmlExtra != null ? (List>) htmlExtra.get("links") : null;
if (links != null) {
for (Map link : links) {
System.out.println("Link: " + link.get("href") + " (" + link.get("text") + ")");
}
}
// Access images
@SuppressWarnings("unchecked")
List> images = htmlExtra != null ? (List>) htmlExtra.get("images") : null;
if (images != null) {
for (Map image : images) {
System.out.println("Image: " + image.get("src"));
}
}
// Access structured data
@SuppressWarnings("unchecked")
List> structuredData = htmlExtra != null ? (List>) htmlExtra.get("structured_data") : null;
if (structuredData != null) {
System.out.println("Structured data items: " + structuredData.size());
}
} catch (XbergRsException e) {
System.err.println("Extraction failed: " + e.getMessage());
}
}
}
```
* Kotlin
Kotlin
```kotlin
import io.xberg.*
private const val DEFAULT_MAX_ARCHIVE_DEPTH = 3L
private const val DEFAULT_EXTRACTION_TIMEOUT_SECS = 600L
private const val DEFAULT_MAX_EMBEDDED_FILE_BYTES = 50L * 1024L * 1024L
fun main() {
val config = ExtractionConfig(
extractionTimeoutSecs = DEFAULT_EXTRACTION_TIMEOUT_SECS,
maxEmbeddedFileBytes = DEFAULT_MAX_EMBEDDED_FILE_BYTES,
url = UrlExtractionConfig(crawl = CrawlConfig(ssrf = SsrfPolicy())),
maxArchiveDepth = DEFAULT_MAX_ARCHIVE_DEPTH,
)
val resultOutput = Xberg.extract(
ExtractInput(kind = ExtractInputKind.URI, uri = "document.pdf"),
config,
)
val result = resultOutput.results.first()
val metadata = result.metadata
metadata.title?.let { println("Title: $it") }
metadata.authors?.let { println("Authors: ${it.joinToString(", ")}") }
when (val format = metadata.format) {
is FormatMetadata.Pdf -> {
format.metadata.pageCount?.let { println("Pages: $it") }
format.metadata.producer?.let { println("Producer: $it") }
format.metadata.pdfVersion?.let { println("PDF Version: $it") }
}
else -> Unit
}
val htmlResultOutput = Xberg.extract(
ExtractInput(kind = ExtractInputKind.URI, uri = "page.html"),
config,
)
val htmlResult = htmlResultOutput.results.first()
when (val format = htmlResult.metadata.format) {
is FormatMetadata.Html -> {
val html = format.metadata
html.title?.let { println("Title: $it") }
html.description?.let { println("Description: $it") }
html.canonicalUrl?.let { println("Canonical URL: $it") }
html.language?.let { println("Language: $it") }
println("Keywords: ${html.keywords}")
html.openGraph["image"]?.let { println("Open Graph Image: $it") }
html.openGraph["title"]?.let { println("Open Graph Title: $it") }
html.twitterCard["card"]?.let { println("Twitter Card Type: $it") }
for (header in html.headers) {
println("Header (level ${header.level}): ${header.text}")
}
for (link in html.links) {
println("Link: ${link.href} (${link.text})")
}
for (image in html.images) {
println("Image: ${image.src}")
}
if (html.structuredData.isNotEmpty()) {
println("Structured data items: ${html.structuredData.size}")
}
}
else -> Unit
}
}
```
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig
async def main() -> None:
result = await extract(ExtractInput(uri="document.pdf"), ExtractionConfig())
# Common fields live directly on Metadata
metadata = result.results[0].metadata
pdf_metadata = metadata.format.pdf if metadata.format else None
if pdf_metadata and pdf_metadata.page_count:
print(f"Pages: {pdf_metadata.page_count}")
if metadata.title:
print(f"Title: {metadata.title}")
if metadata.authors:
print(f"Authors: {', '.join(metadata.authors)}")
html_result = await extract(ExtractInput(uri="page.html"), ExtractionConfig())
html_metadata = html_result.results[0].metadata
html_format = html_metadata.format.html if html_metadata.format else None
if html_format:
if html_format.title:
print(f"Title: {html_format.title}")
if html_format.description:
print(f"Description: {html_format.description}")
# Access keywords as array
if html_format.keywords:
print(f"Keywords: {', '.join(html_format.keywords)}")
# Access canonical URL
if html_format.canonical_url:
print(f"Canonical URL: {html_format.canonical_url}")
# Access Open Graph fields from map
if html_format.open_graph:
if "image" in html_format.open_graph:
print(f"Open Graph Image: {html_format.open_graph['image']}")
if "title" in html_format.open_graph:
print(f"Open Graph Title: {html_format.open_graph['title']}")
if "type" in html_format.open_graph:
print(f"Open Graph Type: {html_format.open_graph['type']}")
# Access Twitter Card fields from map
if html_format.twitter_card:
if "card" in html_format.twitter_card:
print(f"Twitter Card Type: {html_format.twitter_card['card']}")
if "creator" in html_format.twitter_card:
print(f"Twitter Creator: {html_format.twitter_card['creator']}")
if html_format.language:
print(f"Language: {html_format.language}")
if html_format.text_direction:
print(f"Text Direction: {html_format.text_direction}")
# Access headers
if html_format.headers:
print(f"Headers: {', '.join(h.text for h in html_format.headers)}")
# Access links
if html_format.links:
for link in html_format.links:
print(f"Link: {link.href} ({link.text})")
# Access images
if html_format.images:
for image in html_format.images:
print(f"Image: {image}")
# Access structured data
if html_format.structured_data:
print(f"Structured data items: {len(html_format.structured_data)}")
asyncio.run(main())
```
* Ruby
Ruby
```ruby
require 'xberg'
input = Xberg::ExtractInput.new(uri: 'document.pdf')
config = Xberg::ExtractionConfig.new
result = Xberg.extract(input, config)
# Metadata is flat — format-specific fields are at the top level
metadata = result.results.first.metadata
if metadata['page_count']
puts "Pages: #{metadata['page_count']}"
end
if metadata['title']
puts "Title: #{metadata['title']}"
end
if metadata['authors']
puts "Authors: #{metadata['authors'].join(', ')}"
end
# Access HTML metadata
html_input = Xberg::ExtractInput.new(uri: 'page.html')
html_result = Xberg.extract(html_input, Xberg::ExtractionConfig.new)
metadata = html_result.results.first.metadata
if metadata['title']
puts "Title: #{metadata['title']}"
end
if metadata['description']
puts "Description: #{metadata['description']}"
end
# Access keywords as array
if metadata['keywords']
puts "Keywords: #{metadata['keywords'].join(', ')}"
end
# Access canonical URL (renamed from canonical)
puts "Canonical URL: #{metadata['canonical_url']}" if metadata['canonical_url']
# Access Open Graph fields from map
open_graph = metadata['open_graph'] || {}
puts "Open Graph Image: #{open_graph['image']}" if open_graph['image']
puts "Open Graph Title: #{open_graph['title']}" if open_graph['title']
puts "Open Graph Type: #{open_graph['type']}" if open_graph['type']
# Access Twitter Card fields from map
twitter_card = metadata['twitter_card'] || {}
puts "Twitter Card Type: #{twitter_card['card']}" if twitter_card['card']
puts "Twitter Creator: #{twitter_card['creator']}" if twitter_card['creator']
# Access new fields
puts "Language: #{metadata['language']}" if metadata['language']
puts "Text Direction: #{metadata['text_direction']}" if metadata['text_direction']
# Access headers
if metadata['headers']
puts "Headers: #{metadata['headers'].map { |h| h['text'] }.join(', ')}"
end
# Access links
if metadata['links']
metadata['links'].each do |link|
puts "Link: #{link['href']} (#{link['text']})"
end
end
# Access images
if metadata['images']
metadata['images'].each do |image|
puts "Image: #{image['src']}"
end
end
# Access structured data
if metadata['structured_data']
puts "Structured data items: #{metadata['structured_data'].length}"
end
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, FormatMetadata};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let output = extract(ExtractInput::from_uri("document.pdf"), &ExtractionConfig::default()).await?;
let result = &output.results[0];
// Common bibliographic fields live on `Metadata` directly.
if let Some(title) = &result.metadata.title {
println!("Title: {}", title);
}
if let Some(authors) = &result.metadata.authors {
println!("Author: {}", authors.join(", "));
}
// Format-specific fields are behind the `FormatMetadata` discriminated union.
if let Some(FormatMetadata::Pdf(pdf_meta)) = &result.metadata.format {
if let Some(pages) = pdf_meta.page_count {
println!("Pages: {}", pages);
}
}
let html_output = extract(ExtractInput::from_uri("page.html"), &ExtractionConfig::default()).await?;
let html_result = &html_output.results[0];
if let Some(FormatMetadata::Html(html_meta)) = &html_result.metadata.format {
if let Some(title) = &html_meta.title {
println!("Title: {}", title);
}
if let Some(desc) = &html_meta.description {
println!("Description: {}", desc);
}
// Access keywords array
println!("Keywords: {:?}", html_meta.keywords);
// Access canonical URL (renamed from canonical)
if let Some(canonical) = &html_meta.canonical_url {
println!("Canonical URL: {}", canonical);
}
// Access Open Graph fields as a map
if let Some(og_image) = html_meta.open_graph.get("image") {
println!("Open Graph Image: {}", og_image);
}
if let Some(og_title) = html_meta.open_graph.get("title") {
println!("Open Graph Title: {}", og_title);
}
// Access Twitter Card fields as a map
if let Some(twitter_card) = html_meta.twitter_card.get("card") {
println!("Twitter Card Type: {}", twitter_card);
}
// Access new fields
if let Some(lang) = &html_meta.language {
println!("Language: {}", lang);
}
// Access headers
if !html_meta.headers.is_empty() {
for header in &html_meta.headers {
println!("Header (level {}): {}", header.level, header.text);
}
}
// Access links
if !html_meta.links.is_empty() {
for link in &html_meta.links {
println!("Link: {} ({})", link.href, link.text);
}
}
// Access images
if !html_meta.images.is_empty() {
for image in &html_meta.images {
println!("Image: {}", image.src);
}
}
// Access structured data
if !html_meta.structured_data.is_empty() {
println!("Structured data items: {}", html_meta.structured_data.len());
}
}
Ok(())
}
```
* Swift
Swift
```swift
import Foundation
import Xberg
import RustBridge
let config = try extractionConfigFromJson("{}")
let input = try extractInputFromJson(#"{"kind":"uri","uri":"document.pdf"}"#)
let resultOutput = try await extract(input: input, config: config)
let result = resultOutput.results().get(index: 0)!
let metadata = result.metadata()
if let title = metadata.title() {
print("Title: \(title.toString())")
}
if let subject = metadata.subject() {
print("Subject: \(subject.toString())")
}
if let language = metadata.language() {
print("Language: \(language.toString())")
}
if let createdAt = metadata.createdAt() {
print("Created at: \(createdAt.toString())")
}
if let modifiedAt = metadata.modifiedAt() {
print("Modified at: \(modifiedAt.toString())")
}
if let createdBy = metadata.createdBy() {
print("Created by: \(createdBy.toString())")
}
// List-valued metadata crosses the bridge as a JSON array string.
print("Authors: \(metadata.authors().toString())")
print("Keywords: \(metadata.keywords().toString())")
if let duration = metadata.extractionDurationMs() {
print("Extraction duration (ms): \(duration)")
}
if let pages = metadata.pages() {
print("Page count: \(pages.totalCount())")
}
```
* Elixir
Elixir
```elixir
{:ok, output} = Xberg.extract(input: %Xberg.ExtractInput{kind: :uri, uri: "document.pdf"}, config: nil)
result = List.first(output.results)
# Metadata is flat — format-specific fields are at the top level
metadata = result.metadata
IO.puts("MIME type: #{result.mime_type}")
IO.puts("All metadata keys: #{inspect(Map.keys(metadata))}")
# Access PDF metadata directly from the flat map
page_count = metadata["page_count"]
if page_count, do: IO.puts("Page count: #{page_count}")
authors = metadata["authors"] || []
if authors != [], do: IO.puts("Authors: #{Enum.join(authors, ", ")}")
title = metadata["title"]
if title, do: IO.puts("Title: #{title}")
# Access HTML metadata directly from the flat map
{:ok, html_output} = Xberg.extract(input: %Xberg.ExtractInput{kind: :uri, uri: "page.html"}, config: nil)
html_result = List.first(html_output.results)
html_meta = html_result.metadata
keywords = html_meta["keywords"] || []
if keywords != [], do: IO.puts("Keywords: #{Enum.join(keywords, ", ")}")
description = html_meta["description"]
if description, do: IO.puts("Description: #{description}")
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
});
const result = output.results?.[0];
console.log(`Metadata: ${JSON.stringify(result?.metadata)}`);
if (result?.metadata?.pages?.totalCount) {
console.log(`Pages: ${result.metadata.pages.totalCount}`);
}
const htmlOutput = await extract({
kind: ExtractInputKind.Uri,
uri: "page.html",
});
const htmlResult = htmlOutput.results?.[0];
console.log(`HTML Metadata: ${JSON.stringify(htmlResult?.metadata)}`);
const htmlFormat = htmlResult?.metadata?.format;
const htmlMeta = htmlFormat?.format_type === "html" ? htmlFormat.html : undefined;
if (htmlMeta?.title) {
console.log(`Title: ${htmlMeta.title}`);
}
// Access keywords as array
if (htmlMeta?.keywords && htmlMeta.keywords.length > 0) {
console.log(`Keywords: ${htmlMeta.keywords.join(", ")}`);
}
// Access canonical URL (renamed from canonical)
if (htmlMeta?.canonicalUrl) {
console.log(`Canonical URL: ${htmlMeta.canonicalUrl}`);
}
// Access Open Graph fields from map
if (htmlMeta?.openGraph) {
if (htmlMeta.openGraph["image"]) {
console.log(`Open Graph Image: ${htmlMeta.openGraph["image"]}`);
}
if (htmlMeta.openGraph["title"]) {
console.log(`Open Graph Title: ${htmlMeta.openGraph["title"]}`);
}
if (htmlMeta.openGraph["type"]) {
console.log(`Open Graph Type: ${htmlMeta.openGraph["type"]}`);
}
}
// Access Twitter Card fields from map
if (htmlMeta?.twitterCard) {
if (htmlMeta.twitterCard["card"]) {
console.log(`Twitter Card Type: ${htmlMeta.twitterCard["card"]}`);
}
if (htmlMeta.twitterCard["creator"]) {
console.log(`Twitter Creator: ${htmlMeta.twitterCard["creator"]}`);
}
}
// Access new fields
if (htmlMeta?.language) {
console.log(`Language: ${htmlMeta.language}`);
}
if (htmlMeta?.textDirection) {
console.log(`Text Direction: ${htmlMeta.textDirection}`);
}
// Access headers
if (htmlMeta?.headers && htmlMeta.headers.length > 0) {
console.log(`Headers: ${htmlMeta.headers.map((h) => h.text).join(", ")}`);
}
// Access links
if (htmlMeta?.links && htmlMeta.links.length > 0) {
htmlMeta.links.forEach((link) => {
console.log(`Link: ${link.href} (${link.text})`);
});
}
// Access images
if (htmlMeta?.images && htmlMeta.images.length > 0) {
htmlMeta.images.forEach((image) => {
console.log(`Image: ${image.src}`);
});
}
// Access structured data
if (htmlMeta?.structuredData && htmlMeta.structuredData.length > 0) {
console.log(`Structured data items: ${htmlMeta.structuredData.length}`);
}
```
* Wasm
WASM
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const fileInput = document.getElementById("file") as HTMLInputElement;
const file = fileInput.files?.[0];
if (file) {
const bytes = new Uint8Array(await file.arrayBuffer());
const result = await extract({ kind: "bytes", bytes, mimeType: file.type || "application/octet-stream" }, undefined);
console.log(`Metadata: ${JSON.stringify(result.results[0].metadata)}`);
// Access common metadata fields
if (result.results[0].metadata.title) {
console.log(`Title: ${result.results[0].metadata.title}`);
}
// Access format-specific metadata
const metadata = result.results[0].metadata;
// For HTML files
if (metadata.format?.format_type === "html") {
const htmlMeta = metadata.format;
console.log(`HTML Title: ${htmlMeta.title}`);
console.log(`Description: ${htmlMeta.description}`);
// Access keywords as array
if (htmlMeta.keywords && htmlMeta.keywords.length > 0) {
console.log(`Keywords: ${htmlMeta.keywords.join(", ")}`);
}
// Access canonical URL
if (htmlMeta.canonical_url) {
console.log(`Canonical URL: ${htmlMeta.canonical_url}`);
}
// Access Open Graph fields
if (htmlMeta.open_graph) {
if (htmlMeta.open_graph["title"]) {
console.log(`OG Title: ${htmlMeta.open_graph["title"]}`);
}
if (htmlMeta.open_graph["image"]) {
console.log(`OG Image: ${htmlMeta.open_graph["image"]}`);
}
}
// Access Twitter Card fields
if (htmlMeta.twitter_card && htmlMeta.twitter_card["card"]) {
console.log(`Twitter Card Type: ${htmlMeta.twitter_card["card"]}`);
}
// Access headers
if (htmlMeta.headers && htmlMeta.headers.length > 0) {
console.log(`Headers: ${htmlMeta.headers.map((h: any) => h.text).join(", ")}`);
}
// Access links
if (htmlMeta.links && htmlMeta.links.length > 0) {
htmlMeta.links.forEach((link: any) => {
console.log(`Link: ${link.href} (${link.text})`);
});
}
// Access images
if (htmlMeta.images && htmlMeta.images.length > 0) {
htmlMeta.images.forEach((image: any) => {
console.log(`Image: ${image.src}`);
});
}
// Access structured data
if (htmlMeta.structured_data && htmlMeta.structured_data.length > 0) {
console.log(`Structured data items: ${htmlMeta.structured_data.length}`);
}
}
// PDF-specific fields are at the top level of metadata
if (metadata.pages) {
console.log(`Pages: ${metadata.pages.totalCount}`);
}
if (metadata.authors && metadata.authors.length > 0) {
console.log(`Authors: ${metadata.authors.join(", ")}`);
}
}
```
* Zig
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
var gpa: std.heap.DebugAllocator(.{}) = .init;
defer _ = gpa.deinit();
const allocator = gpa.allocator();
const config_json = "{}";
const input_json = "{\"kind\":\"uri\",\"uri\":\"document.pdf\"}";
const output_json = try xberg.extract(input_json, config_json);
defer std.heap.c_allocator.free(output_json);
var parsed = try std.json.parseFromSlice(std.json.Value, allocator, output_json, .{});
defer parsed.deinit();
const output = parsed.value;
if (output != .object) return;
const results_val = output.object.get("results") orelse return;
if (results_val != .array or results_val.array.items.len == 0) return;
const root = results_val.array.items[0];
if (root != .object) return;
if (root.object.get("metadata")) |metadata_val| {
if (metadata_val != .object) return;
const metadata = metadata_val.object;
if (metadata.get("title")) |title_val| {
if (title_val == .string) {
std.debug.print("Title: {s}\n", .{title_val.string});
}
}
if (metadata.get("authors")) |authors_val| {
if (authors_val == .array) {
for (authors_val.array.items) |author| {
if (author == .string) {
std.debug.print("Author: {s}\n", .{author.string});
}
}
}
}
if (metadata.get("language")) |language_val| {
if (language_val == .string) {
std.debug.print("Language: {s}\n", .{language_val.string});
}
}
if (metadata.get("created_at")) |created_val| {
if (created_val == .string) {
std.debug.print("Created: {s}\n", .{created_val.string});
}
}
if (metadata.get("pages")) |pages_val| {
if (pages_val == .object) {
if (pages_val.object.get("total_count")) |total_val| {
if (total_val == .integer) {
std.debug.print("Pages: {d}\n", .{total_val.integer});
}
}
}
}
}
}
```
* CLI
Extract and parse metadata using JSON output:
Terminal
```bash
# Extract with metadata (JSON format includes metadata automatically)
xberg extract document.pdf --format json
# Save to file and parse metadata
xberg extract document.pdf --format json > result.json
# Print all metadata fields
cat result.json | jq '.metadata'
# Extract HTML metadata
xberg extract page.html --format json | jq '.metadata'
# Get specific fields
xberg extract document.pdf --format json | \
jq '.metadata | {page_count, authors, title}'
# Process multiple files
xberg batch documents/*.pdf --format json > all_metadata.json
```
**JSON Output Structure:**
JSON
```json
{
"results": [
{
"content": "Extracted text...",
"mime_type": "application/pdf",
"metadata": {
"title": "Document Title",
"authors": ["John Doe"],
"created_by": "LaTeX with hyperref package",
"format_type": "pdf",
"page_count": 10
},
"tables": []
}
],
"errors": [],
"summary": {
"inputs": 1,
"results": 1,
"errors": 0
}
}
```
Xberg extracts format-specific metadata for:
* **PDF**: page count, title, authors (list), creation date, modification date
* **HTML**: SEO tags, Open Graph, Twitter Card, structured data, headers, links, images
* **Excel**: sheet count, sheet names
* **Email**: from, to, CC, BCC, message ID, attachments
* **PowerPoint**: title, author, description, fonts
* **Images**: dimensions, format, EXIF data
* **Archives**: format, file count, file list, sizes
* **XML**: element count, unique elements
* **Text/Markdown**: word count, line count, headers, links
See [Types Reference](/reference/types/) for complete metadata reference.
## Extract Tables
[Section titled “Extract Tables”](#extract-tables)
Tables come back as both structured cells and Markdown. Xberg extracts them from PDFs, spreadsheets, and HTML:
* C
C
```c
#include "xberg.h"
#include
int main(void) {
/* A config handle is required — zero is rejected as an invalid handle. */
XBERGAlefHandle config = xberg_extraction_config_from_json("{}");
if (config == 0) {
fprintf(stderr, "config init failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
return 1;
}
XBERGAlefHandle input = xberg_extract_input_from_uri("spreadsheet.xlsx");
if (input == 0) {
fprintf(stderr, "Failed to create input (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extraction_config_free(config);
return 1;
}
XBERGAlefHandle result = xberg_extract(input, config);
if (result == 0) {
fprintf(stderr, "extraction failed (code %d): %s\n",
xberg_last_error_code(),
xberg_last_error_context());
xberg_extract_input_free(input);
xberg_extraction_config_free(config);
return 1;
}
char *result_json = xberg_extraction_result_to_json(result);
if (result_json) {
printf("Extraction result (JSON): %s\n", result_json);
} else {
printf("No extraction result available\n");
}
xberg_free_string(result_json);
xberg_extract_input_free(input);
xberg_extraction_result_free(result);
xberg_extraction_config_free(config);
return 0;
}
```
* C#
C#
```csharp
using Xberg;
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), new ExtractionConfig())).Results[0];
foreach (var table in result.Tables)
{
Console.WriteLine($"Table with {table.Cells.Count} rows");
Console.WriteLine(table.Markdown);
foreach (var row in table.Cells)
{
Console.WriteLine(string.Join(" | ", row));
}
}
```
* Dart
Dart
```dart
import 'package:xberg/xberg.dart';
Future main() async {
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(
const ExtractInput(kind: ExtractInputKind.uri, uri: 'document.pdf'),
config: config,
);
for (final table in result.results[0].tables) {
print('Table on page ${table.pageNumber} with ${table.cells.length} rows');
print(table.markdown);
for (final row in table.cells) {
print(row);
}
if (table.boundingBox != null) {
print('Bounding box: ${table.boundingBox}');
}
}
}
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, xberg.ExtractionConfig{})
if err != nil {
log.Fatalf("extract failed: %v", err)
}
// Iterate over tables
for _, table := range result.Results[0].Tables {
fmt.Printf("Table with %d rows\n", len(table.Cells))
fmt.Println(table.Markdown) // Markdown representation
// Access cells
for _, row := range table.Cells {
fmt.Println(row)
}
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.XbergRsException;
import io.xberg.ExtractInput;
import io.xberg.ExtractionConfig;
import io.xberg.Table;
import java.util.List;
public class Main {
public static void main(String[] args) {
try {
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("document.pdf").build(),
ExtractionConfig.builder().build()
);
ExtractedDocument result = output.results().get(0);
for (Table table : result.tables()) {
System.out.println("Table with " + table.cells().size() + " rows");
System.out.println(table.markdown());
for (List row : table.cells()) {
System.out.println(row);
}
}
} catch (XbergRsException e) {
System.err.println("Extraction failed: " + e.getMessage());
}
}
}
```
* Kotlin
Kotlin
```kotlin
import io.xberg.*
private const val DEFAULT_MAX_ARCHIVE_DEPTH = 3L
private const val DEFAULT_EXTRACTION_TIMEOUT_SECS = 600L
private const val DEFAULT_MAX_EMBEDDED_FILE_BYTES = 50L * 1024L * 1024L
fun main() {
val config = ExtractionConfig(
extractionTimeoutSecs = DEFAULT_EXTRACTION_TIMEOUT_SECS,
maxEmbeddedFileBytes = DEFAULT_MAX_EMBEDDED_FILE_BYTES,
url = UrlExtractionConfig(crawl = CrawlConfig(ssrf = SsrfPolicy())),
maxArchiveDepth = DEFAULT_MAX_ARCHIVE_DEPTH,
)
val resultOutput = Xberg.extract(
ExtractInput(kind = ExtractInputKind.URI, uri = "document.pdf"),
config,
)
val result = resultOutput.results.first()
val tables = result.tables
for (table in tables) {
println("Table on page ${table.pageNumber} with ${table.cells.size} rows")
println(table.markdown)
for (row in table.cells) {
println(row)
}
}
}
```
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig
async def main() -> None:
result = await extract(ExtractInput(uri="document.pdf"), ExtractionConfig())
for table in result.results[0].tables:
row_count: int = len(table.cells)
print(f"Table with {row_count} rows")
print(table.markdown)
for row in table.cells:
print(row)
asyncio.run(main())
```
* Ruby
Ruby
```ruby
require 'xberg'
input = Xberg::ExtractInput.new(uri: 'document.pdf')
config = Xberg::ExtractionConfig.new
result = Xberg.extract(input, config)
# Iterate over tables
result.results.first.tables.each do |table|
puts "Table with #{table['cells'].length} rows"
puts table['markdown'] # Markdown representation
# Access cells
table['cells'].each do |row|
puts row
end
end
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let output = extract(ExtractInput::from_uri("document.pdf"), &ExtractionConfig::default()).await?;
let result = &output.results[0];
for table in &result.tables {
println!("Table with {} rows", table.cells.len());
println!("{}", table.markdown);
for row in &table.cells {
println!("{:?}", row);
}
}
Ok(())
}
```
* Swift
Swift
```swift
import Foundation
import Xberg
import RustBridge
let config = try extractionConfigFromJson("{}")
let input = try extractInputFromJson(#"{"kind":"uri","uri":"document.pdf"}"#)
let resultOutput = try await extract(input: input, config: config)
let result = resultOutput.results().get(index: 0)!
let tables = result.tables()
print("Tables: \(tables.count)")
for (index, table) in tables.enumerated() {
print("Table \(index) on page \(table.pageNumber())")
print(table.markdown().toString())
if let bbox = table.boundingBox() {
print(" Bounding box: \(bbox.x0()), \(bbox.y0()), \(bbox.x1()), \(bbox.y1())")
}
}
```
* Elixir
Elixir
```elixir
{:ok, output} = Xberg.extract(input: %Xberg.ExtractInput{kind: :uri, uri: "document.pdf"}, config: nil)
result = List.first(output.results)
tables = result.tables
IO.puts("Total tables found: #{length(tables)}")
Enum.with_index(tables, 1) |> Enum.each(fn {table, index} ->
IO.puts("\n--- Table #{index} ---")
# Access table cells
cells = table["cells"] || []
IO.puts("Rows: #{length(cells)}")
# Access table markdown representation
markdown = table["markdown"]
IO.puts("Markdown representation:")
IO.puts(markdown)
end)
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
});
const [first] = output.results ?? [];
first?.tables?.forEach((table) => {
console.log(`Table with ${table.cells?.length ?? 0} rows`);
console.log(table.markdown);
table.cells?.forEach((row) => console.log(row.join(" | ")));
});
```
* Wasm
WASM
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const fileInput = document.getElementById("file") as HTMLInputElement;
const file = fileInput.files?.[0];
if (file) {
const bytes = new Uint8Array(await file.arrayBuffer());
const result = await extract({ kind: "bytes", bytes, mimeType: file.type || "application/pdf" }, undefined);
result.results[0].tables?.forEach((table) => {
console.log(`Table with ${table.cells?.length ?? 0} rows`);
if (table.markdown) {
console.log(table.markdown);
}
table.cells?.forEach((row: string[]) => console.log(row.join(" | ")));
});
}
```
* Zig
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
var gpa: std.heap.DebugAllocator(.{}) = .init;
defer _ = gpa.deinit();
const allocator = gpa.allocator();
const config_json = "{}";
const input_json = "{\"kind\":\"uri\",\"uri\":\"document.pdf\"}";
const output_json = try xberg.extract(input_json, config_json);
defer std.heap.c_allocator.free(output_json);
var parsed = try std.json.parseFromSlice(std.json.Value, allocator, output_json, .{});
defer parsed.deinit();
const output = parsed.value;
if (output != .object) return;
const results_val = output.object.get("results") orelse return;
if (results_val != .array or results_val.array.items.len == 0) return;
const root = results_val.array.items[0];
if (root != .object) return;
const tables_val = root.object.get("tables") orelse return;
if (tables_val != .array) return;
for (tables_val.array.items) |table| {
if (table != .object) continue;
if (table.object.get("cells")) |cells_val| {
if (cells_val == .array) {
std.debug.print("Table with {d} rows\n", .{cells_val.array.items.len});
for (cells_val.array.items) |row_val| {
if (row_val != .array) continue;
std.debug.print(" Row:", .{});
for (row_val.array.items) |cell_val| {
if (cell_val == .string) {
std.debug.print(" [{s}]", .{cell_val.string});
}
}
std.debug.print("\n", .{});
}
}
}
if (table.object.get("markdown")) |markdown_val| {
if (markdown_val == .string) {
std.debug.print("{s}\n", .{markdown_val.string});
}
}
if (table.object.get("page_number")) |page_val| {
if (page_val == .integer) {
std.debug.print("Page: {d}\n", .{page_val.integer});
}
}
}
}
```
* CLI
Extract and process tables from documents:
Terminal
```bash
# Extract with JSON format (includes tables when detected)
xberg extract document.pdf --format json
# Save tables to JSON
xberg extract spreadsheet.xlsx --format json > tables.json
# Extract and parse table markdown
xberg extract document.pdf --format json | \
jq '.tables[]? | .markdown'
# Get table cells
xberg extract document.pdf --format json | \
jq '.tables[]? | .cells'
# Batch extract tables from multiple files
xberg batch documents/**/*.pdf --format json > all_tables.json
```
**JSON Table Structure:**
JSON
```json
{
"results": [
{
"content": "...",
"tables": [
{
"cells": [
["Name", "Age", "City"],
["Alice", "30", "New York"],
["Bob", "25", "Los Angeles"]
],
"markdown": "| Name | Age | City |\\n|------|-----|--------|\\n| Alice | 30 | New York |\\n| Bob | 25 | Los Angeles |"
}
]
}
],
"errors": [],
"summary": {
"inputs": 1,
"results": 1,
"errors": 0
}
}
```
## Going Async
[Section titled “Going Async”](#going-async)
Async-capable bindings expose extraction as an awaitable operation for web servers and background workers. Synchronous bindings expose the same input and result contract directly:
* Python
Tests URI extraction API
Python
```python
import asyncio
from xberg import extract, ExtractInput
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
result = await extract(input)
print(result.results[0].content)
asyncio.run(main())
```
* TypeScript / Node.js
Tests URI extraction API
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const result = await extract(input);
console.log(result.results?.[0]?.content);
}
void main();
```
* WebAssembly
Tests URI extraction API
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, undefined);
console.log(result.results[0].content);
}
void main();
```
* Rust
Tests URI extraction API
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config = Default::default();
let result = extract(input, &config).await.expect("call failed");
println!("{:?}", result.results[0].content);
}
```
* Go
Tests URI extraction API
Go
```go
package main
import (
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
fmt.Printf("%+v\n", result.Results[0].Content)
}
```
* Java
Tests URI extraction API
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var result = Xberg.extract(input, ExtractionConfig.builder().build());
System.out.println(result.results().get(0).content());
}
}
```
* Kotlin (Android)
Tests URI extraction API
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val configDefault = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, configDefault)
println(result.results.first().content)
}
```
* C#
Tests URI extraction API
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig());
Console.WriteLine(result.Results[0].Content);
```
* Swift
Tests URI extraction API
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}")
debugPrint(result.results()[0].content())
```
* Ruby
Tests URI extraction API
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'))
puts result.results[0].content.inspect
```
* PHP
Tests URI extraction API
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, null);
var_dump($result->getResults()[0]->content);
```
* Elixir
Tests URI extraction API
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value)
IO.inspect(Enum.at(result.results, 0).content)
```
* Dart
Tests URI extraction API
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result.results[0].content);
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests URI extraction API
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests URI extraction API
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle result = xberg_extract(input_handle, 0);
xberg_extract_input_free(input_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
## Next Steps
[Section titled “Next Steps”](#next-steps)
You’ve covered the core API. Go deeper:
* **[Configuration Guide](/guides/configuration/)** — OCR backends, chunking, language detection, config files
* **[Extract from Bytes](/reference/api-python/#extract)** — Use `ExtractInput(kind="bytes")`
* **[OCR Setup](/guides/ocr/)** — Tesseract, PaddleOCR, Sceptre, Candle, and VLM backends
* **[Types Reference](/reference/types/)** — Full metadata fields for every format
* **[Docker Deployment](/guides/docker/)** — Run Xberg in containers
* **[API Reference](/reference/api-python/)** — Complete API documentation
# AI Coding Assistants
Get your AI coding assistant writing correct Xberg code on the first try — right function signatures, right config field names, right per-language conventions — instead of hallucinated APIs you have to fix.
The Xberg plugin teaches your assistant how to use the library, covering extraction, configuration, OCR, chunking, embeddings, batch processing, error handling, and plugins across Python, Node.js/TypeScript, Rust, and CLI.
## Installing
[Section titled “Installing”](#installing)
Install the Xberg plugin from the [`xberg-io/xberg`](https://github.com/xberg-io/xberg) marketplace. It ships the Xberg agent skills (extraction APIs, OCR backends, configuration, language conventions) and works with every major coding agent — expand your harness below.
**Claude Code**
```text
/plugin marketplace add xberg-io/xberg
/plugin install xberg@xberg
```
**Codex CLI**
```text
/plugins add https://github.com/xberg-io/xberg
```
Then search for `xberg` and select **Install Plugin**.
**Cursor**
Settings → Plugins → Add from URL → `https://github.com/xberg-io/xberg`, then select **Xberg**.
**Gemini CLI**
```text
gemini extensions install https://github.com/xberg-io/xberg
```
**Factory Droid**
```text
droid plugin marketplace add https://github.com/xberg-io/xberg
droid plugin install xberg@xberg
```
**GitHub Copilot CLI**
```text
copilot plugin marketplace add https://github.com/xberg-io/xberg
copilot plugin install xberg@xberg
```
**opencode**
Add the package to `opencode.json`:
```json
{
"$schema": "https://opencode.ai/config.json",
"plugin": ["@xberg-io/opencode-xberg"]
}
```
**Hermes**
Install the Hermes plugin from PyPI — Hermes auto-discovers it via entry points, so no extra configuration is needed:
```bash
pip install xberg-hermes-plugin
```
Prefer a raw MCP server?
The plugin also bundles an Xberg MCP server, so a harness that speaks [Model Context Protocol](https://modelcontextprotocol.io/) gets the extraction tools without installing the plugin. See [MCP Integration](/guides/mcp-integration/) for the standalone server and direct-CLI configs.
## What the Skill Provides
[Section titled “What the Skill Provides”](#what-the-skill-provides)
When your AI coding assistant discovers the skill, it knows:
* All extraction functions and their correct signatures across languages
* Configuration field names (for example, `max_chars` not `max_characters` in Python)
* Rust feature gates (for example, `tokio-runtime` for sync functions)
* Language-specific conventions (snake\_case in Python/Rust, camelCase in Node.js)
* Error handling patterns for each language
## Quick Examples
[Section titled “Quick Examples”](#quick-examples)
* Python
```python
from xberg import ExtractInput, ExtractionConfig, OcrConfig, extract
output = await extract(ExtractInput(kind="uri", uri="document.pdf"))
print(output.results[0].content)
config = ExtractionConfig(
ocr=OcrConfig(backend="tesseract", language=["eng"]),
output_format="markdown",
)
output = await extract(ExtractInput(kind="uri", uri="document.pdf"), config=config)
```
* Node.js
```typescript
import { ExtractInputKind, extract } from '@xberg-io/xberg';
const output = await extract({
kind: ExtractInputKind.Uri,
uri: 'document.pdf',
});
console.log(output.results[0].content);
```
* Rust
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
let config = ExtractionConfig::default();
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
```
* CLI
```bash
xberg extract document.pdf
xberg extract document.pdf --format json --output-format markdown
```
## Further Reading
[Section titled “Further Reading”](#further-reading)
* [Plugin marketplace](https://github.com/xberg-io/xberg) — install the plugin in every supported harness
* [MCP Integration](/guides/mcp-integration/) — run Xberg as a standalone MCP server for any MCP-capable agent
* [Extraction Basics](/guides/extraction/) — core extraction API
* [Configuration](/guides/configuration/) — all configuration options
* [Chunking](/guides/chunking/) — split text for RAG
* [Embeddings](/guides/embeddings/) — semantic vectors for search
* [Language Detection](/guides/language-detection/) — multilingual document analysis
* [Plugin System](/guides/plugins/) — custom plugins
# API Server
Xberg runs as an HTTP REST API server (`xberg serve`) or as an MCP server (`xberg mcp`) for AI agent integration.
## HTTP REST API
[Section titled “HTTP REST API”](#http-rest-api)
### Start
[Section titled “Start”](#start)
* CLI
Bash
```bash
# Default: http://127.0.0.1:8000
xberg serve
# Custom host and port
xberg serve -H 0.0.0.0 -p 3000
# With configuration file
xberg serve --config xberg.toml
```
* Docker
Bash
```bash
# Run server on port 8000
docker run -d \n -p 8000:8000 \n ghcr.io/xberg-io/xberg:latest \n serve -H 0.0.0.0 -p 8000
# With environment variables
docker run -d \n -e XBERG_CORS_ORIGINS="https://myapp.com" \n -e XBERG_MAX_MULTIPART_FIELD_BYTES=209715200 \n -p 8000:8000 \n ghcr.io/xberg-io/xberg:latest \n serve -H 0.0.0.0 -p 8000
```
* Python
Python
```python
# Start server
import subprocess
subprocess.Popen(["python", "-m", "xberg", "serve", "-H", "0.0.0.0", "-p", "8000"])
```
* Rust
Rust
```rust
use xberg::{ExtractionConfig, api::serve_with_config};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig::discover()?.unwrap_or_default();
serve_with_config("0.0.0.0", 8000, config).await?;
Ok(())
}
```
* Go
Go
```go
package main
import (
"log"
"os/exec"
)
func main() {
cmd := exec.Command("xberg", "serve", "-H", "0.0.0.0", "-p", "8000")
cmd.Stdout = log.Writer()
cmd.Stderr = log.Writer()
if err := cmd.Run(); err != nil {
log.Fatalf("failed to start server: %v", err)
}
}
```
* Java
Java
```java
import java.io.IOException;
public class ApiServer {
public static void main(String[] args) {
try {
ProcessBuilder pb = new ProcessBuilder(
"xberg", "serve", "-H", "0.0.0.0", "-p", "8000"
);
pb.inheritIO();
Process process = pb.start();
process.waitFor();
} catch (IOException | InterruptedException e) {
System.err.println("Failed to start server: " + e.getMessage());
}
}
}
```
* C#
C#
```csharp
using System;
using System.Diagnostics;
class ApiServer
{
static void Main()
{
var processInfo = new ProcessStartInfo
{
FileName = "xberg",
Arguments = "serve -H 0.0.0.0 -p 8000",
UseShellExecute = false,
RedirectStandardOutput = true,
RedirectStandardError = true
};
using (var process = Process.Start(processInfo))
{
process?.WaitForExit();
}
}
}
```
### Endpoints
[Section titled “Endpoints”](#endpoints)
#### POST /extract
[Section titled “POST /extract”](#post-extract)
Extract text from uploaded files via multipart form data.
| Field | Required | Description |
| --------------- | ---------------- | ------------------------------------------------------------------- |
| `files` | Yes (repeatable) | Files to extract |
| `config` | No | JSON config overrides |
| `output_format` | No | `plain` (default), `markdown`, `djot`, `html`, `json`, or `doctags` |
Terminal
```bash
# Single file
curl -F "files=@document.pdf" http://localhost:8000/extract
# Multiple files
curl -F "files=@doc1.pdf" -F "files=@doc2.docx" http://localhost:8000/extract
# With config overrides
curl -F "files=@scanned.pdf" \
-F 'config={"ocr":{"language":"eng"},"force_ocr":true}' \
http://localhost:8000/extract
```
Response
```json
{
"results": [
{
"content": "Extracted text...",
"mime_type": "application/pdf",
"metadata": { "page_count": 10, "author": "John Doe" },
"tables": [],
"detected_languages": ["eng"],
"chunks": null,
"images": null
}
],
"errors": [],
"summary": {
"inputs": 1,
"results": 1,
"errors": 0
}
}
```
#### POST /extract-async
[Section titled “POST /extract-async”](#post-extract-async)
Queue an extraction job and return immediately. Accepts the same multipart form data or JSON body as `/extract`. Returns `202 Accepted` with a job identifier. Returns `429 Too Many Requests` when the concurrent job limit is reached.
Terminal
```bash
curl -F "files=@document.pdf" http://localhost:8000/extract-async
```
Response (202)
```json
{ "job_id": "550e8400-e29b-41d4-a716-446655440000" }
```
#### GET `/jobs/{job_id}`
[Section titled “GET /jobs/{job\_id}”](#get-jobsjob_id)
Poll the status of an async job. `state` is one of `pending`, `running`, `completed`, or `failed`. The `result` field is present only when `state == completed`; the `error` field only when `state == failed`. Jobs expire after 5 minutes and return `404` once evicted.
Terminal
```bash
curl http://localhost:8000/jobs/550e8400-e29b-41d4-a716-446655440000
```
Response
```json
{
"job_id": "550e8400-e29b-41d4-a716-446655440000",
"state": "completed",
"created_at": "2026-07-07T12:00:00Z",
"updated_at": "2026-07-07T12:00:03Z",
"result": { "results": [], "errors": [], "summary": {} }
}
```
#### Other Endpoints
[Section titled “Other Endpoints”](#other-endpoints)
| Endpoint | Method | Description |
| ----------------- | ------ | ---------------------------------------------------- |
| `/health` | GET | `{"status":"healthy","version":""}` |
| `/version` | GET | `{"version":""}` |
| `/detect` | POST | MIME type detection (multipart) |
| `/formats` | GET | List supported formats |
| `/cache/stats` | GET | Cache statistics |
| `/cache/warm` | POST | Pre-download models |
| `/cache/manifest` | GET | Model manifest with checksums |
| `/cache/clear` | DELETE | Clear all cached files |
| `/info` | GET | `{"version":"...","rust_backend":true}` |
| `/openapi.json` | GET | OpenAPI 3.1 schema |
### Client Examples
[Section titled “Client Examples”](#client-examples)
* Python
Python
```python
import asyncio
import json
import httpx
async def main() -> None:
async with httpx.AsyncClient() as client, open("document.pdf", "rb") as f:
response = await client.post(
"http://localhost:8000/extract",
files={"files": f},
)
data = response.json()
print(json.dumps(data, indent=2))
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
// Using fetch API
const fileInput = document.getElementById("file") as HTMLInputElement;
const file = fileInput.files?.[0];
if (file) {
const formData = new FormData();
formData.append("files", file);
const response = await fetch("http://localhost:8000/extract", {
method: "POST",
body: formData,
});
const results = await response.json();
console.log(results[0].content);
}
```
* Rust
Rust
```rust
use std::path::Path;
#[tokio::main]
async fn main() -> Result<(), Box> {
let client = reqwest::Client::new();
let bytes = tokio::fs::read("document.pdf").await?;
let file_name = Path::new("document.pdf")
.file_name()
.and_then(|n| n.to_str())
.unwrap_or("document.pdf");
let part = reqwest::multipart::Part::bytes(bytes)
.file_name(file_name.to_string())
.mime_str("application/pdf")?;
let form = reqwest::multipart::Form::new().part("file", part);
let response = client
.post("http://localhost:8000/extract")
.multipart(form)
.send()
.await?;
let result: serde_json::Value = response.error_for_status()?.json().await?;
println!("{}", result["content"].as_str().unwrap_or(""));
Ok(())
}
```
* Go
Go
```go
package main
import (
"bytes"
"io"
"log"
"mime/multipart"
"net/http"
"os"
)
func main() {
file, err := os.Open("document.pdf")
if err != nil {
log.Fatalf("failed to open file: %v", err)
}
defer file.Close()
body := &bytes.Buffer{}
writer := multipart.NewWriter(body)
part, _ := writer.CreateFormFile("files", "document.pdf")
io.Copy(part, file)
writer.Close()
resp, err := http.Post("http://localhost:8000/extract", writer.FormDataContentType(), body)
if err != nil {
log.Fatalf("request failed: %v", err)
}
defer resp.Body.Close()
io.Copy(os.Stdout, resp.Body)
}
```
* Java
Java
```java
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpResponse;
import java.net.URI;
import java.nio.file.Files;
import java.nio.file.Paths;
HttpClient client = HttpClient.newHttpClient();
try (var fileStream = Files.newInputStream(Paths.get("document.pdf"))) {
byte[] content = fileStream.readAllBytes();
var request = HttpRequest.newBuilder()
.uri(URI.create("http://localhost:8000/extract"))
.header("Content-Type", "application/octet-stream")
.POST(HttpRequest.BodyPublishers.ofByteArray(content))
.build();
HttpResponse response = client.send(request, HttpResponse.BodyHandlers.ofString());
System.out.println(response.body());
}
```
* C#
C#
```csharp
using System;
using System.IO;
using System.Net.Http;
var client = new HttpClient();
using (var fileStream = File.OpenRead("document.pdf"))
{
using (var content = new MultipartFormDataContent())
{
content.Add(new StreamContent(fileStream), "files", "document.pdf");
var response = await client.PostAsync("http://localhost:8000/extract", content);
var json = await response.Content.ReadAsStringAsync();
Console.WriteLine(json);
}
}
```
* Ruby
Ruby
```ruby
require 'net/http'
require 'json'
uri = URI('http://localhost:8000/extract')
http = Net::HTTP.new(uri.host, uri.port)
request = Net::HTTP::Post.new(uri)
File.open('document.pdf', 'rb') do |file|
body = file.read
request['Content-Type'] = 'application/octet-stream'
request.body = body
response = http.request(request)
if response.is_a?(Net::HTTPSuccess)
data = JSON.parse(response.body)
puts JSON.pretty_generate(data)
else
puts "Error: #{response.code} #{response.message}"
end
end
```
### Error Handling
[Section titled “Error Handling”](#error-handling)
Error response
```json
{
"error_type": "ValidationError",
"message": "Invalid file format",
"status_code": 400
}
```
| Status | Error type | Meaning |
| ------ | -------------------------- | ----------------- |
| 400 | `ValidationError` | Invalid input |
| 422 | `ParsingError`, `OcrError` | Processing failed |
| 500 | Internal errors | Server errors |
* Python
Python
```python
import httpx
try:
with httpx.Client() as client:
with open("document.pdf", "rb") as f:
files: dict = {"files": f}
response: httpx.Response = client.post(
"http://localhost:8000/extract", files=files
)
response.raise_for_status()
results: list = response.json()
print(f"Extracted {len(results)} documents")
except httpx.HTTPStatusError as e:
error: dict = e.response.json()
error_type: str = error.get("error_type", "Unknown")
message: str = error.get("message", "No message")
print(f"Error: {error_type}: {message}")
```
* TypeScript
TypeScript
```typescript
/// {
const formData = new FormData();
const fileData = readFileSync("document.pdf");
formData.append("files", new Blob([fileData]), "document.pdf");
try {
const response = await fetch("http://localhost:8000/extract", {
method: "POST",
body: formData,
});
if (!response.ok) {
const error = await response.json();
console.error(`Error: ${error.error_type}: ${error.message}`);
return;
}
const results = await response.json();
console.log(`Extracted ${results.length} documents`);
} catch (error: unknown) {
if (error instanceof Error) {
console.error(`Request failed: ${error.message}`);
}
}
}
extractDocument();
```
* Rust
Rust
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, XbergError, Result};
async fn extract_text(bytes: &[u8], mime_type: &str) -> Result {
let config = ExtractionConfig::default();
let output = extract(
ExtractInput::from_bytes(bytes.to_vec(), mime_type, Some("document.pdf".to_string())),
&config,
)
.await?;
Ok(output
.results
.first()
.map(|document| document.content.clone())
.unwrap_or_default())
}
#[tokio::main]
async fn main() {
let bytes = std::fs::read("document.pdf").unwrap_or_default();
match extract_text(&bytes, "application/pdf").await {
Ok(text) => println!("Extracted {} chars", text.len()),
Err(XbergError::UnsupportedFormat(mime)) => {
eprintln!("Format not supported: {mime}");
}
Err(XbergError::Ocr { message, .. }) => {
eprintln!("OCR failed: {message}");
}
Err(e) => eprintln!("Error: {e}"),
}
}
```
* Go
Go
```go
package main
import (
"bytes"
"encoding/json"
"io"
"log"
"mime/multipart"
"net/http"
"os"
)
func main() {
file, err := os.Open("document.pdf")
if err != nil {
log.Fatalf("failed to open file: %v", err)
}
defer file.Close()
body := &bytes.Buffer{}
writer := multipart.NewWriter(body)
part, _ := writer.CreateFormFile("files", "document.pdf")
io.Copy(part, file)
writer.Close()
resp, err := http.Post("http://localhost:8000/extract", writer.FormDataContentType(), body)
if err != nil {
log.Fatalf("request failed: %v", err)
}
defer resp.Body.Close()
if resp.StatusCode != http.StatusOK {
var errResp map[string]string
json.NewDecoder(resp.Body).Decode(&errResp)
log.Fatalf("error: %s: %s", errResp["error_type"], errResp["message"])
}
var result map[string]interface{}
json.NewDecoder(resp.Body).Decode(&result)
println("Success:", result["content"].(string))
}
```
* Java
Java
```java
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpResponse;
import java.net.URI;
import java.nio.file.Files;
import java.nio.file.Paths;
import com.fasterxml.jackson.databind.ObjectMapper;
HttpClient client = HttpClient.newHttpClient();
byte[] fileBytes = Files.readAllBytes(Paths.get("document.pdf"));
var request = HttpRequest.newBuilder()
.uri(URI.create("http://localhost:8000/extract"))
.header("Content-Type", "application/octet-stream")
.POST(HttpRequest.BodyPublishers.ofByteArray(fileBytes))
.build();
HttpResponse response = client.send(request, HttpResponse.BodyHandlers.ofString());
if (response.statusCode() != 200) {
ObjectMapper mapper = new ObjectMapper();
var error = mapper.readTree(response.body());
System.err.println("Error: " + error.get("error_type").asText() + " - " + error.get("message").asText());
} else {
System.out.println("Success: " + response.body());
}
```
* C#
C#
```csharp
using System;
using System.IO;
using System.Net.Http;
using System.Text.Json;
var client = new HttpClient();
try
{
using (var fileStream = File.OpenRead("document.pdf"))
{
using (var content = new MultipartFormDataContent())
{
content.Add(new StreamContent(fileStream), "files", "document.pdf");
var response = await client.PostAsync("http://localhost:8000/extract", content);
if (!response.IsSuccessStatusCode)
{
var errorJson = await response.Content.ReadAsStringAsync();
var errorDoc = JsonDocument.Parse(errorJson);
var errorType = errorDoc.RootElement.GetProperty("error_type").GetString();
var message = errorDoc.RootElement.GetProperty("message").GetString();
Console.WriteLine($"Error: {errorType}: {message}");
return;
}
var json = await response.Content.ReadAsStringAsync();
Console.WriteLine($"Success: {json}");
}
}
}
catch (HttpRequestException e)
{
Console.WriteLine($"Request failed: {e.Message}");
}
```
* Ruby
Ruby
```ruby
require 'xberg'
begin
pdf_bytes = File.read('document.pdf')
config = Xberg::ExtractionConfig.new
input = Xberg::ExtractInput.from_bytes(pdf_bytes, 'application/pdf')
output = Xberg.extract(input, config)
result = output.results.first
puts "Extracted #{result.content.length} characters"
rescue RuntimeError => e
# All extraction errors are raised as RuntimeError
# Check error message for details
case e.message
when /parse|parsing/i
puts "Failed to parse document: #{e.message}"
when /ocr/i
puts "OCR processing failed: #{e.message}"
when /validation|invalid/i
puts "Invalid configuration: #{e.message}"
else
puts "Extraction error: #{e.message}"
end
end
```
A client reads the error body from any non-2xx response. This Node example uploads a file, prints `error_type` and `message` when the request fails, and prints the content when it succeeds:
TypeScript
```typescript
/// > {
let config = ExtractionConfig::discover()?.unwrap_or_default();
start_mcp_server_with_config(config).await?;
Ok(())
}
```
* Go
Go
```go
package main
import (
"fmt"
"os"
"os/exec"
)
func main() {
cmd := exec.Command("xberg", "mcp")
cmd.Stdout = os.Stdout
cmd.Stderr = os.Stderr
if err := cmd.Run(); err != nil {
fmt.Fprintf(os.Stderr, "Failed to start MCP server: %v\n", err)
}
}
```
* Java
Java
```java
import java.io.IOException;
public class McpServer {
public static void main(String[] args) {
try {
// Start MCP server using CLI
ProcessBuilder pb = new ProcessBuilder("xberg", "mcp");
pb.inheritIO();
Process process = pb.start();
process.waitFor();
} catch (IOException | InterruptedException e) {
System.err.println("Failed to start MCP server: " + e.getMessage());
}
}
}
```
* C#
C#
```csharp
using System;
using System.Diagnostics;
using System.Threading.Tasks;
var processInfo = new ProcessStartInfo
{
FileName = "xberg",
Arguments = "mcp",
UseShellExecute = false,
RedirectStandardOutput = true,
RedirectStandardError = true
};
var mcpProcess = Process.Start(processInfo);
Console.WriteLine($"MCP server started with PID: {mcpProcess?.Id}");
await Task.Delay(1000);
Console.WriteLine("Server is running, listening for connections");
mcpProcess?.WaitForExit();
```
* Ruby
Ruby
```ruby
require 'open3'
begin
Open3.popen3('xberg', 'mcp') do |stdin, stdout, stderr, wait_thr|
puts stdout.read
wait_thr.join
end
rescue => e
puts "Failed to start MCP server: #{e.message}"
end
```
### Tools
[Section titled “Tools”](#tools)
The MCP server exposes `extract`, `extract_batch`, `detect_mime_type`, `list_formats`, `get_version`, and the `cache_*` tools. See the [MCP Reference](/reference/mcp/) for the full tool list, parameters, and schemas.
All extraction tools accept an optional `config` object. URI and byte payload details live in `ExtractInput` as `kind = "uri"` or `kind = "bytes"`.
### Batch Extraction
[Section titled “Batch Extraction”](#batch-extraction)
* Python
Python
```python
import asyncio
import json
from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
async def main() -> None:
server_params: StdioServerParameters = StdioServerParameters(
command="xberg", args=["mcp"]
)
inputs: list[dict[str, str]] = [
{"kind": "uri", "uri": "file1.pdf"},
{"kind": "uri", "uri": "file2.docx"},
{"kind": "uri", "uri": "notes.md"},
]
config: dict[str, bool] = {"use_cache": True}
async with stdio_client(server_params) as (read, write):
async with ClientSession(read, write) as session:
await session.initialize()
result = await session.call_tool(
"extract_batch",
arguments={"inputs": inputs, "config": config},
)
payload_text: str = result.content[0].text
batch: dict = json.loads(payload_text)
print(f"Extracted {batch['summary']['results']} files")
for index, item in enumerate(batch["results"], start=1):
mime_type: str | None = item.get("mime_type")
preview: str = item["content"][:80].replace("\n", " ")
print(f" [{index}] {mime_type or 'unknown'}: {preview}...")
asyncio.run(main())
```
### AI Agent Integration
[Section titled “AI Agent Integration”](#ai-agent-integration)
* Claude Desktop
Add to `~/Library/Application Support/Claude/claude_desktop_config.json`:
```json
{
"mcpServers": {
"xberg": {
"command": "xberg",
"args": ["mcp"]
}
}
}
```
* Python
Python
```python
import asyncio
from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
async def main() -> None:
server_params: StdioServerParameters = StdioServerParameters(
command="xberg", args=["mcp"]
)
async with stdio_client(server_params) as (read, write):
async with ClientSession(read, write) as session:
await session.initialize()
tools = await session.list_tools()
tool_names: list[str] = [t.name for t in tools.tools]
print(f"Available tools: {tool_names}")
result = await session.call_tool(
"extract", arguments={"path": "document.pdf", "async": True}
)
print(result)
asyncio.run(main())
```
* Python (HTTP)
Python
```python
import asyncio
import httpx
from mcp import ClientSession
from mcp.client.streamable_http import streamable_http_client
MCP_URL = "http://127.0.0.1:8001/mcp"
async def main() -> None:
# Requires MCP server running with HTTP transport:
# xberg mcp --transport http --host 127.0.0.1 --port 8001
async with httpx.AsyncClient(follow_redirects=True) as http_client:
async with streamable_http_client(MCP_URL, http_client=http_client) as (
read,
write,
):
async with ClientSession(read, write) as session:
await session.initialize()
tools = await session.list_tools()
tool_names: list[str] = [t.name for t in tools.tools]
print(f"Available tools: {tool_names}")
result = await session.call_tool(
"extract",
arguments={"path": "document.pdf"},
)
print(result)
asyncio.run(main())
```
* LangChain
Python
```python
from langchain.agents import initialize_agent, AgentType
from langchain.tools import Tool
from langchain_openai import ChatOpenAI
import subprocess
import json
mcp_process = subprocess.Popen(
["xberg", "mcp"],
stdin=subprocess.PIPE,
stdout=subprocess.PIPE,
stderr=subprocess.PIPE,
)
def extract(path: str) -> str:
request: dict = {
"method": "tools/call",
"params": {
"name": "extract",
"arguments": {"path": path, "async": True},
},
}
mcp_process.stdin.write(json.dumps(request).encode() + b"\n")
mcp_process.stdin.flush()
response = mcp_process.stdout.readline()
return json.loads(response)["result"]["content"]
tools: list[Tool] = [
Tool(name="extract_document", func=extract, description="Extract")
]
llm = ChatOpenAI(temperature=0)
agent = initialize_agent(
tools, llm, agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION
)
```
* TypeScript
TypeScript
```typescript
/// > {
let mut child = Command::new("xberg")
.arg("mcp")
.stdin(Stdio::piped())
.stdout(Stdio::piped())
.spawn()?;
{
let stdin = child.stdin.as_mut().ok_or("Failed to open stdin")?;
let request = json!({
"method": "tools/call",
"params": {
"name": "extract",
"arguments": {
"path": "document.pdf",
"async": true
}
}
});
stdin.write_all(request.to_string().as_bytes())?;
stdin.write_all(b"\n")?;
}
let stdout = child.stdout.take().ok_or("Failed to open stdout")?;
let reader = BufReader::new(stdout);
for line in reader.lines() {
if let Ok(line) = line {
println!("{}", line);
break;
}
}
child.wait()?;
Ok(())
}
```
* Go
Go
```go
package main
import (
"bufio"
"encoding/json"
"fmt"
"log"
"os/exec"
)
type MCPRequest struct {
Method string `json:"method"`
Params MCPParams `json:"params"`
}
type MCPParams struct {
Name string `json:"name"`
Arguments map[string]interface{} `json:"arguments"`
}
func main() {
cmd := exec.Command("xberg", "mcp")
stdin, err := cmd.StdinPipe()
if err != nil {
log.Fatalf("create stdin pipe: %v", err)
}
stdout, err := cmd.StdoutPipe()
if err != nil {
log.Fatalf("create stdout pipe: %v", err)
}
if err := cmd.Start(); err != nil {
log.Fatalf("start command: %v", err)
}
request := MCPRequest{
Method: "tools/call",
Params: MCPParams{
Name: "extract",
Arguments: map[string]interface{}{
"path": "document.pdf",
"async": true,
},
},
}
data, err := json.Marshal(request)
if err != nil {
log.Fatalf("marshal request: %v", err)
}
fmt.Fprintf(stdin, "%s\n", string(data))
scanner := bufio.NewScanner(stdout)
if scanner.Scan() {
fmt.Println(scanner.Text())
}
if err := cmd.Wait(); err != nil {
log.Fatalf("wait for command: %v", err)
}
}
```
* Java
Java
```java
import com.fasterxml.jackson.databind.ObjectMapper;
import java.io.BufferedReader;
import java.io.BufferedWriter;
import java.io.IOException;
import java.io.InputStreamReader;
import java.io.OutputStreamWriter;
import java.util.Map;
public class McpClient implements AutoCloseable {
private final Process mcpProcess;
private final BufferedWriter stdin;
private final BufferedReader stdout;
private final ObjectMapper mapper = new ObjectMapper();
public McpClient() throws IOException {
ProcessBuilder pb = new ProcessBuilder("xberg", "mcp");
mcpProcess = pb.start();
stdin = new BufferedWriter(new OutputStreamWriter(mcpProcess.getOutputStream()));
stdout = new BufferedReader(new InputStreamReader(mcpProcess.getInputStream()));
}
// Note: This is a custom RPC client method, not Xberg.extract() API
public String extract(String path) throws IOException {
Map request = Map.of(
"method", "tools/call",
"params", Map.of(
"name", "extract",
"arguments", Map.of("path", path, "async", true)
)
);
stdin.write(mapper.writeValueAsString(request));
stdin.newLine();
stdin.flush();
String response = stdout.readLine();
@SuppressWarnings("unchecked")
Map result = mapper.readValue(response, Map.class);
@SuppressWarnings("unchecked")
Map resultData = (Map) result.get("result");
return (String) resultData.get("content");
}
public void close() throws IOException {
stdin.close();
stdout.close();
mcpProcess.destroy();
}
public static void main(String[] args) {
try (McpClient client = new McpClient()) {
String content = client.extract("contract.pdf");
System.out.println("Extracted content: " + content);
} catch (IOException e) {
System.err.println("Error: " + e.getMessage());
}
}
}
```
* C#
C#
```csharp
using System;
using System.Diagnostics;
using System.IO;
using System.Threading.Tasks;
var processInfo = new ProcessStartInfo
{
FileName = "xberg",
Arguments = "mcp",
UseShellExecute = false,
RedirectStandardInput = true,
RedirectStandardOutput = true,
RedirectStandardError = true
};
var process = Process.Start(processInfo)
?? throw new InvalidOperationException("Failed to start the xberg MCP server process");
var clientInput = process.StandardInput;
var clientOutput = process.StandardOutput;
// Initialize session by sending initialize request
var initRequest = new
{
jsonrpc = "2.0",
id = 1,
method = "initialize",
parameters = new { }
};
await clientInput.WriteLineAsync(System.Text.Json.JsonSerializer.Serialize(initRequest));
await clientInput.FlushAsync();
var initResponse = await clientOutput.ReadLineAsync();
Console.WriteLine($"Init response: {initResponse}");
// List available tools
var listRequest = new
{
jsonrpc = "2.0",
id = 2,
method = "tools/list"
};
await clientInput.WriteLineAsync(System.Text.Json.JsonSerializer.Serialize(listRequest));
await clientInput.FlushAsync();
var listResponse = await clientOutput.ReadLineAsync();
Console.WriteLine($"Available tools: {listResponse}");
process?.WaitForExit();
```
* Ruby
Ruby
```ruby
require 'json'
require 'open3'
Open3.popen3('xberg', 'mcp') do |stdin, stdout, stderr, wait_thr|
request = {
method: 'tools/call',
params: {
name: 'extract',
arguments: { path: 'document.pdf', async: true }
}
}
stdin.puts JSON.generate(request)
stdin.close_write
response = stdout.gets
result = JSON.parse(response)
puts JSON.pretty_generate(result)
end
```
***
For container deployment, see the [Docker Guide](/guides/docker/).
# Text Chunking
Split extracted text into overlapping, structure-aware chunks ready to embed and index for RAG. Four strategies support different document types — text splits on whitespace/punctuation, Markdown preserves structure and code blocks, YAML maintains section hierarchy, and semantic chunking uses embeddings to detect topic shifts.
## Strategies
[Section titled “Strategies”](#strategies)
* **Text** — splits on whitespace/punctuation boundaries
* **Markdown** — structure-aware; preserves headings, lists, and code blocks
* **YAML** — section-aware; preserves YAML document structure
* **Semantic** — topic-aware; splits at natural document boundaries
## Semantic Chunking
[Section titled “Semantic Chunking”](#semantic-chunking)
Set `chunker_type` to `"semantic"`. Uses an embedding model for topic detection when one is configured; otherwise falls back to structural heuristics.
```python
config = ExtractionConfig(
chunking=ChunkingConfig(chunker_type="semantic")
)
```
**Behavior:**
* **Without embeddings** — Uses structural heuristics: detects headers (ALL CAPS, numbered sections) and paragraph boundaries
* **With embeddings** — Compares consecutive paragraphs via embeddings to detect topic shifts, merging paragraphs below the `topic_threshold` (default: 0.75)
Use `topic_threshold` to control sensitivity: lower values (0.1–0.3) detect more topic boundaries (more, smaller chunks); higher values (0.7–0.9) detect fewer (fewer, larger chunks). Only applies when an embedding model is configured.
## Markdown Tables
[Section titled “Markdown Tables”](#markdown-tables)
When `chunker_type` is `"markdown"`, set `table_chunking` to control how tables that exceed the chunk size are split:
* **`split`** (default) — split at row boundaries; continuation chunks do not repeat the header
* **`repeat_header`** — prepend the header row and separator to every continuation chunk so each chunk is self-contained
## Configuration
[Section titled “Configuration”](#configuration)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, ExtractionConfig, ChunkingConfig, extract
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
max_characters=1000,
overlap=200,
)
)
result = await extract(ExtractInput(uri="document.pdf"), config)
chunks = result.results[0].chunks or []
print(f"Chunks: {len(chunks)}")
for chunk in chunks:
print(f"Length: {len(chunk.content)}")
asyncio.run(main())
```
Python - Markdown with Heading Context
```python
import asyncio
from xberg import ExtractInput, ExtractionConfig, ChunkingConfig, extract, ChunkSizing
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
chunker_type="markdown",
max_characters=500,
overlap=50,
sizing=ChunkSizing.tokenizer(model="Xenova/gpt-4o"),
)
)
result = await extract(ExtractInput(uri="document.md"), config)
for chunk in result.results[0].chunks or []:
heading_context = chunk.metadata.heading_context
if heading_context:
for h in heading_context.headings:
print(f"Heading L{h.level}: {h.text}")
print(f"Content: {chunk.content[:100]}...")
asyncio.run(main())
```
Python - Semantic
```python
import asyncio
from xberg import ExtractInput, ExtractionConfig, ChunkingConfig, extract
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(chunker_type="semantic")
)
result = await extract(ExtractInput(uri="document.pdf"), config)
for chunk in result.results[0].chunks or []:
print(f"Content: {chunk.content[:100]}...")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
chunking: {
maxCharacters: 1000,
overlap: 200,
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
console.log(`Total chunks: ${output.results?.[0]?.chunks?.length ?? 0}`);
```
TypeScript - Markdown with Heading Context
```typescript
import { ChunkerType, ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
chunking: {
chunkerType: ChunkerType.Markdown,
maxCharacters: 500,
overlap: 50,
sizing: { type: "tokenizer", model: "Xenova/gpt-4o", cacheDir: "~/.cache/xberg/tokenizers" },
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.md" }, config);
const [first] = output.results ?? [];
for (const chunk of first?.chunks ?? []) {
const headings = chunk.metadata?.headingContext?.headings ?? [];
for (const heading of headings) {
console.log(`Heading L${heading.level}: ${heading.text}`);
}
console.log(`Content: ${chunk.content.slice(0, 100)}...`);
}
```
TypeScript - Semantic
```typescript
import { ChunkerType, ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
chunking: {
chunkerType: ChunkerType.Semantic,
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
const [first] = output.results ?? [];
for (const chunk of first?.chunks ?? []) {
console.log(`Content: ${chunk.content.slice(0, 100)}...`);
}
```
* Rust
Rust
```rust
use xberg::{ExtractionConfig, ChunkingConfig};
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
max_characters: 1000,
overlap: 200,
embedding: None,
..Default::default()
}),
..Default::default()
};
```
Rust - Semantic
```rust
use xberg::{ExtractionConfig, ChunkingConfig, ChunkerType};
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
chunker_type: ChunkerType::Semantic,
..Default::default()
}),
..Default::default()
};
```
* Go
Go
```go
package main
import (
"fmt"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(1000)
overlap := uint(200)
config := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
},
}
fmt.Printf("Config: MaxCharacters=%d, Overlap=%d\n",
*config.Chunking.MaxCharacters, *config.Chunking.Overlap)
}
```
Go - Markdown with Heading Context
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(500)
overlap := uint(50)
model := "Xenova/gpt-4o"
chunkerType := xberg.ChunkerTypeMarkdown
config := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
ChunkerType: &chunkerType,
Sizing: xberg.ChunkSizingTokenizer{Model: model},
},
}
input := xberg.ExtractInputFromURI("document.md")
result, err := xberg.Extract(*input, config)
if err != nil {
log.Fatalf("extract failed: %v", err)
}
for _, chunk := range result.Results[0].Chunks {
if chunk.Metadata.HeadingContext != nil {
for _, heading := range chunk.Metadata.HeadingContext.Headings {
fmt.Printf("Heading L%d: %s\n", heading.Level, heading.Text)
}
}
fmt.Printf("Content: %.100s...\n", chunk.Content)
}
}
```
Go - Use Heading Context
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(500)
overlap := uint(50)
chunkerType := xberg.ChunkerTypeMarkdown
config := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
ChunkerType: &chunkerType,
},
}
input := xberg.ExtractInputFromURI("document.md")
result, err := xberg.Extract(*input, config)
if err != nil {
log.Fatalf("extract failed: %v", err)
}
for _, chunk := range result.Results[0].Chunks {
if chunk.Metadata.HeadingContext != nil {
fmt.Printf("Heading depth: %d\n", len(chunk.Metadata.HeadingContext.Headings))
}
fmt.Printf("Content: %.100s...\n", chunk.Content)
}
}
```
* Java
Java
```java
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ChunkingConfig;
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withMaxCharacters(1000L)
.withOverlap(200L)
.build())
.build();
```
Java - Markdown with Heading Context
```java
import io.xberg.Xberg;
import io.xberg.ExtractInput;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ChunkingConfig;
import io.xberg.ChunkerType;
import io.xberg.ChunkSizing;
import io.xberg.HeadingContext;
import java.util.Optional;
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withChunkerType(ChunkerType.Markdown)
.withMaxCharacters(500L)
.withOverlap(50L)
.withSizing(new ChunkSizing.Tokenizer("Xenova/gpt-4o", Optional.empty()))
.build())
.build();
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("document.md").build(),
config
);
ExtractedDocument result = output.results().get(0);
result.chunks().forEach(chunk -> {
HeadingContext headingContext = chunk.metadata().headingContext();
if (headingContext != null) {
System.out.println("Headings:");
headingContext.headings().forEach(heading ->
System.out.println(" Level " + heading.level() + ": " + heading.text())
);
}
});
```
* C#
C#
```csharp
using Xberg;
class Program
{
static async Task Main()
{
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 1000,
Overlap = 200,
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("all-minilm-l6-v2"),
Normalize = true,
BatchSize = 32
}
}
};
try
{
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri(
"document.pdf"), config
)).Results[0];
// Chunks is null unless chunking is configured, as it is above.
var chunks = result.Chunks ?? [];
Console.WriteLine($"Chunks: {chunks.Count}");
foreach (var chunk in chunks)
{
Console.WriteLine($"Content length: {chunk.Content.Length}");
if (chunk.Embedding != null)
{
Console.WriteLine($"Embedding dimensions: {chunk.Embedding.Count}");
}
}
}
catch (XbergException ex)
{
Console.WriteLine($"Error: {ex.Message}");
}
}
}
```
C# - Markdown with Heading Context
```csharp
using Xberg;
class Program
{
static async Task Main()
{
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 500,
Overlap = 50,
Sizing = new ChunkSizing.Tokenizer("Xenova/gpt-4o", null)
}
};
try
{
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri(
"document.md"), config
)).Results[0];
foreach (var chunk in result.Chunks ?? [])
{
// Heading context lives on the chunk's metadata.
var headingContext = chunk.Metadata.HeadingContext;
if (headingContext != null)
{
Console.WriteLine("Headings:");
foreach (var heading in headingContext.Headings)
{
Console.WriteLine($" Level {heading.Level}: {heading.Text}");
}
}
}
}
catch (XbergException ex)
{
Console.WriteLine($"Error: {ex.Message}");
}
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
max_characters: 1000,
overlap: 200
)
)
```
Ruby - Markdown with Heading Context
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
chunker_type: "markdown",
max_characters: 500,
overlap: 50,
sizing_type: "tokenizer",
sizing_model: "Xenova/gpt-4o"
)
)
input = Xberg::ExtractInput.new(uri: "document.md")
result = Xberg.extract(input, config)
result.results.first.chunks.each do |chunk|
if chunk.metadata.heading_context
puts "Headings:"
chunk.metadata.heading_context.headings.each do |heading|
puts " #{' ' * (heading.level - 1) * 2}Level #{heading.level}: #{heading.text}"
end
end
end
```
* Wasm
WASM
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const config = {
chunking: {
max_characters: 1000,
overlap: 100,
},
};
const buffer = await fetch("document.pdf").then((response) => response.arrayBuffer());
const bytes = new Uint8Array(buffer);
const result = await extract({ kind: "bytes", bytes, mimeType: "application/pdf" }, config);
result.results[0].chunks?.forEach((chunk, idx) => {
console.log(`Chunk ${idx}: ${chunk.content.substring(0, 50)}...`);
console.log(`Tokens: ${chunk.metadata?.tokenCount}`);
});
```
WASM - Markdown with Heading Context
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const config = {
chunking: {
chunker_type: "markdown",
max_characters: 2000,
// Note: Token-based sizing is not available in WASM builds.
// Use character-based sizing instead.
},
};
const buffer = await fetch("document.md").then((response) => response.arrayBuffer());
const bytes = new Uint8Array(buffer);
const result = await extract({ kind: "bytes", bytes, mimeType: "text/markdown" }, config);
result.results[0].chunks?.forEach((chunk, idx) => {
console.log(`Chunk ${idx}: ${chunk.content.substring(0, 50)}...`);
if (chunk.metadata?.headingContext?.headings) {
console.log("Headings:");
chunk.metadata.headingContext.headings.forEach((h: any) => {
console.log(` Level ${h.level}: ${h.text}`);
});
}
});
```
## Chunk Output
[Section titled “Chunk Output”](#chunk-output)
Each chunk in `result.chunks` contains:
| Field | Description |
| --------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| `content` | Chunk text |
| `metadata.byte_start` / `byte_end` | Byte offsets in the original text |
| `metadata.chunk_index` / `total_chunks` | Position in sequence |
| `metadata.token_count` | Token count (when embeddings enabled) |
| `metadata.heading_context` | Active heading hierarchy (Markdown chunker only) |
| `metadata.heading_path` | Flattened RAG-shaped heading breadcrumb (e.g., `["Title", "Section", "Subsection"]`) for vector database retrieval and context. |
| `metadata.page_spans` | Per-page coordinates the chunk covers — see [Per-Page Chunk Coordinates](#per-page-chunk-coordinates) below. |
| `metadata.node_ids` | Ids of the covered `document.nodes[]` entries — see [Linking Chunks to Document Nodes](#linking-chunks-to-document-nodes) below. |
| `metadata.classifications` | Multi-label classification result — see [Chunk Classification](#chunk-classification) below. |
| `embedding` | Embedding vector (when configured) |
Chunks can be sized by token count instead of characters — enable the `chunking-tokenizers` feature and set `sizing` to `tokenizer`.
## Per-Page Chunk Coordinates
[Section titled “Per-Page Chunk Coordinates”](#per-page-chunk-coordinates)
`metadata.page_spans` is a list of `{ page, bbox? }` entries, one per page the chunk overlaps, in page order — the first and last entries’ `page` fields equal `metadata.first_page`/`metadata.last_page`. Use it to drive viewer highlighting (draw a box on the source page for a given chunk) without re-deriving page geometry from `content` offsets.
* Populated whenever page-boundary provenance is available — the same condition under which `first_page`/`last_page` are populated.
* `bbox` on each entry is additionally populated when `include_document_structure` is enabled, as the union of that page’s body-layer node bounding boxes found within the chunk.
* Empty (and omitted from JSON output) when page-boundary provenance is unavailable.
chunk with page\_spans
```json
{
"content": "...",
"metadata": {
"first_page": 2,
"last_page": 3,
"page_spans": [
{ "page": 2, "bbox": { "x0": 72.0, "y0": 120.5, "x1": 540.0, "y1": 640.2 } },
{ "page": 3 }
]
}
}
```
Cross-page fragment stitching for `page_spans` mirrors the same-page-only scope of [table identity](/guides/output-formats/#table-identity-and-anchors) — each page’s span is reported independently.
## Linking Chunks to Document Nodes
[Section titled “Linking Chunks to Document Nodes”](#linking-chunks-to-document-nodes)
`metadata.node_ids` is a list of the `id` values of the `document.nodes[]` (DocumentStructure) entries whose text the chunk covers, deduplicated and in document node-traversal order. Join `chunk.metadata.node_ids` against `document.nodes[].id` to trace a chunk back to the structural nodes it came from.
* Populated only when document structure is available (the PDF extraction path) — plain-text and structure-less documents get an empty `node_ids`.
* Membership is a best-effort verbatim-text-containment check (a node’s text found within the chunk), gated on a minimum node-text length, so very short nodes may not be linked. It is not a byte-exact mapping.
## Chunk Classification
[Section titled “Chunk Classification”](#chunk-classification)
Classify each chunk against a caller-supplied, description-backed label set — the chunk-level analogue of [Page Classification](/guides/page-classification/). Set `ExtractionConfig.chunk_classification` to a `ChunkClassificationConfig`:
| Field | Type | Default | Description |
| ----------------- | ---------------------------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `definitions` | `list[{label, description}]` | — | Label taxonomy. Unlike page classification’s bare label list, every label carries a `description` injected into the prompt, so the model can disambiguate similarly named labels in large taxonomies. Must contain at least one entry. |
| `llm` | `LlmConfig` | — | LLM configuration used for classification. |
| `batch_size` | `int` | `10` | Number of chunks grouped into a single classification request. Larger batches amortize the fixed cost of the definitions block (repeated verbatim per request) across more chunks, at the risk of exceeding context limits for large taxonomies. |
| `max_concurrency` | `int` | `4` | Maximum number of in-flight batch requests, bounded to avoid rate-limiting the configured LLM provider. |
| `prompt_template` | `str \| None` | `None` | Minijinja template. Receives `{{ definitions }}` (rendered label + description list) and `{{ chunks }}` (numbered chunk texts in the batch). `None` uses the built-in default. |
Unlike page classification, chunk classification is always multi-label — a chunk may match zero, one, or many definitions. Leaving `chunk_classification` unset (the default) disables the post-processor entirely and makes no LLM calls.
* Python
chunk\_classification.py
```python
from xberg import (
ChunkClassificationConfig,
ChunkClassificationDefinition,
ChunkingConfig,
ExtractInput,
ExtractionConfig,
LlmConfig,
extract,
)
config = ExtractionConfig(
chunking=ChunkingConfig(chunker_type="markdown"),
chunk_classification=ChunkClassificationConfig(
definitions=[
ChunkClassificationDefinition(
label="pricing",
description="Discusses cost, fees, or subscription tiers.",
),
ChunkClassificationDefinition(
label="liability",
description="Discusses indemnification, warranties, or limitation of liability.",
),
],
llm=LlmConfig(model="openai/gpt-4o-mini"),
batch_size=10,
max_concurrency=4,
),
)
output = await extract(ExtractInput(kind="uri", uri="contract.pdf"), config=config)
result = output.results[0]
for chunk in result.chunks or []:
for label in chunk.metadata.classifications:
print(label.label, label.confidence)
```
* Rust
chunk\_classification.rs
```rust
use xberg::{
ChunkClassificationConfig, ChunkClassificationDefinition, ChunkingConfig, ExtractInput,
ExtractionConfig, LlmConfig, extract,
};
let config = ExtractionConfig {
chunking: Some(ChunkingConfig { chunker_type: "markdown".into(), ..Default::default() }),
chunk_classification: Some(ChunkClassificationConfig {
prompt_template: None,
definitions: vec![
ChunkClassificationDefinition {
label: "pricing".into(),
description: "Discusses cost, fees, or subscription tiers.".into(),
},
ChunkClassificationDefinition {
label: "liability".into(),
description: "Discusses indemnification, warranties, or limitation of liability.".into(),
},
],
llm: LlmConfig { model: "openai/gpt-4o-mini".into(), ..Default::default() },
batch_size: 10,
max_concurrency: 4,
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("contract.pdf"), &config).await?;
let result = &output.results[0];
for chunk in result.chunks.iter().flatten() {
for label in &chunk.metadata.classifications {
println!("{} {:?}", label.label, label.confidence);
}
}
```
* TOML
xberg.toml
```toml
[chunking]
chunker_type = "markdown"
[[chunk_classification.definitions]]
label = "pricing"
description = "Discusses cost, fees, or subscription tiers."
[[chunk_classification.definitions]]
label = "liability"
description = "Discusses indemnification, warranties, or limitation of liability."
[chunk_classification.llm]
model = "openai/gpt-4o-mini"
batch_size = 10
max_concurrency = 4
```
Feature gate
Requires the `classification` Cargo feature. Included in `full`.
## Token Sizing with Your Own Tokenizer (Plugin Variant)
[Section titled “Token Sizing with Your Own Tokenizer (Plugin Variant)”](#token-sizing-with-your-own-tokenizer-plugin-variant)
Token budgets only protect the embedder when they are counted with the tokenizer the embedder actually uses. When that tokenizer isn’t available as a HuggingFace `tokenizer.json` (llama.cpp/GGUF vocabularies, SentencePiece models, custom vocabs), plug it in — Xberg calls back into the registered backend to count tokens instead of loading one from the Hub. The `chunking-tokenizers` feature is still required (it gates the `tokenizer` sizing variant itself); language bindings ship with it enabled.
1. Register the backend once at startup via `xberg::plugins::register_tokenizer_backend(Arc::new(MyTokenizer))`. The backend implements `TokenizerBackend` (a `Plugin`-inheriting trait with a synchronous `count_tokens(text) -> usize` — it runs inside the splitter’s boundary search, so keep it cheap).
2. Reference it by name in the chunking config: `{ "sizing": { "type": "tokenizer", "model": "my-tokenizer" } }`. A registered name takes precedence over a HuggingFace id; unregistered names fall back to the Hub as before.
3. `max_characters` is then the chunk budget in that backend’s tokens.
Language bindings register through the same API — implement the trait’s methods (`name`, `initialize`, `shutdown`, `count_tokens`) on a host-language object and pass it to `register_tokenizer_backend`.
## RAG Pipeline Example
[Section titled “RAG Pipeline Example”](#rag-pipeline-example)
* Python
Python
```python
import asyncio
from xberg import (
ExtractInput,
extract,
ExtractionConfig,
ChunkingConfig,
EmbeddingConfig,
EmbeddingModelType,
)
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
max_characters=500,
overlap=50,
embedding=EmbeddingConfig(
model=EmbeddingModelType.preset("balanced"),
normalize=True,
batch_size=16
)
)
)
result = await extract(ExtractInput(uri="research_paper.pdf"), config)
chunks_with_embeddings: list = []
for chunk in result.results[0].chunks or []:
if chunk.embedding:
chunks_with_embeddings.append({
"content": chunk.content[:100],
"embedding_dims": len(chunk.embedding)
})
print(f"Chunks with embeddings: {len(chunks_with_embeddings)}")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
chunking: {
maxCharacters: 500,
overlap: 50,
embedding: {
model: { type: "preset", name: "balanced" },
},
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "research_paper.pdf" }, config);
const [result] = output.results ?? [];
if (result?.chunks) {
for (const chunk of result.chunks) {
console.log(`Chunk ${chunk.metadata.chunkIndex + 1}/${chunk.metadata.totalChunks}`);
console.log(`Position: ${chunk.metadata.byteStart}-${chunk.metadata.byteEnd}`);
console.log(`Content: ${chunk.content.slice(0, 100)}...`);
if (chunk.embedding) {
console.log(`Embedding: ${chunk.embedding.length} dimensions`);
}
}
}
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, ChunkingConfig, EmbeddingConfig, EmbeddingModelType};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
max_characters: 500,
overlap: 50,
embedding: Some(EmbeddingConfig {
model: EmbeddingModelType::Preset { name: "balanced".to_string() },
normalize: true,
..Default::default()
}),
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("research_paper.pdf"), &config).await?;
let result = &output.results[0];
if let Some(chunks) = &result.chunks {
for chunk in chunks {
println!("Chunk {}/{}",
chunk.metadata.chunk_index + 1,
chunk.metadata.total_chunks
);
println!("Position: {}-{}",
chunk.metadata.byte_start,
chunk.metadata.byte_end
);
println!("Content: {}...", &chunk.content[..100.min(chunk.content.len())]);
if let Some(embedding) = &chunk.embedding {
println!("Embedding: {} dimensions", embedding.len());
}
}
}
Ok(())
}
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(500)
overlap := uint(50)
normalize := true
batchSize := uint(16)
cfg := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
Embedding: &xberg.EmbeddingConfig{
Model: xberg.EmbeddingModelTypePreset{Name: "quality"},
Normalize: &normalize,
BatchSize: &batchSize,
},
},
}
input := xberg.ExtractInputFromURI("research_paper.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
log.Fatalf("RAG extraction failed: %v", err)
}
chunks := result.Results[0].Chunks
fmt.Printf("Found %d chunks for RAG pipeline\n", len(chunks))
for i := 0; i < len(chunks) && i < 3; i++ {
chunk := chunks[i]
content := chunk.Content
if len(content) > 80 {
content = content[:80]
}
fmt.Printf("Chunk %d: %s...\n", i, content)
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInput;
import io.xberg.ChunkingConfig;
import io.xberg.Chunk;
import io.xberg.EmbeddingConfig;
import io.xberg.EmbeddingModelType;
import java.util.List;
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withMaxCharacters(500L)
.withOverlap(50L)
.withEmbedding(EmbeddingConfig.builder()
.withModel(new EmbeddingModelType.Preset("all-mpnet-base-v2"))
.withNormalize(true)
.withBatchSize(16L)
.build())
.build())
.build();
try {
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("research_paper.pdf").build(),
config
);
ExtractedDocument result = output.results().get(0);
List chunks = result.chunks() != null ? result.chunks() : List.of();
System.out.println("Found " + chunks.size() + " chunks for RAG pipeline");
for (int i = 0; i < Math.min(3, chunks.size()); i++) {
Chunk chunk = chunks.get(i);
System.out.println("Chunk " + i + ": " + chunk.content().substring(0, Math.min(80, chunk.content().length())) + "...");
}
} catch (Exception ex) {
System.err.println("RAG extraction failed: " + ex.getMessage());
}
```
* C#
C#
```csharp
using Xberg;
using System.Collections.Generic;
using System.Linq;
class RagPipelineExample
{
static async Task Main()
{
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 500,
Overlap = 50,
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("all-mpnet-base-v2"),
Normalize = true,
BatchSize = 16
}
}
};
try
{
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri(
"research_paper.pdf"), config
)).Results[0];
var vectorStore = await BuildVectorStoreAsync(result.Chunks ?? new List())
.ConfigureAwait(false);
var query = "machine learning optimization";
var relevantChunks = await SearchAsync(vectorStore, query)
.ConfigureAwait(false);
Console.WriteLine($"Found {relevantChunks.Count} relevant chunks");
foreach (var chunk in relevantChunks.Take(3))
{
Console.WriteLine($"Content: {chunk.Content[..80]}...");
Console.WriteLine($"Similarity: {chunk.Similarity:F3}\n");
}
}
catch (XbergException ex)
{
Console.WriteLine($"Error: {ex.Message}");
}
}
static async Task> BuildVectorStoreAsync(
IEnumerable chunks)
{
return await Task.Run(() =>
{
return chunks.Select(c => new VectorEntry
{
Content = c.Content,
Embedding = c.Embedding?.ToArray() ?? Array.Empty(),
Similarity = 0f
}).ToList();
}).ConfigureAwait(false);
}
static async Task> SearchAsync(
List store,
string query)
{
return await Task.Run(() =>
{
return store
.OrderByDescending(e => e.Similarity)
.ToList();
}).ConfigureAwait(false);
}
class VectorEntry
{
public string Content { get; set; } = string.Empty;
public float[] Embedding { get; set; } = Array.Empty();
public float Similarity { get; set; }
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
max_characters: 500,
overlap: 50,
embedding: Xberg::EmbeddingConfig.new(
model: Xberg::EmbeddingModelType.new(
type: 'preset',
name: 'all-mpnet-base-v2'
),
normalize: true,
batch_size: 16
)
)
)
input = Xberg::ExtractInput.new(uri: 'research_paper.pdf')
result = Xberg.extract(input, config)
vector_store = build_vector_store(result.results.first.chunks)
query = 'machine learning optimization'
relevant_chunks = search_vector_store(vector_store, query)
puts "Found #{relevant_chunks.length} relevant chunks"
relevant_chunks.take(3).each do |chunk|
puts "Content: #{chunk[:content][0..80]}..."
puts "Similarity: #{chunk[:similarity]&.round(3)}\n"
end
def build_vector_store(chunks)
chunks.map.with_index do |chunk, idx|
{
id: idx,
content: chunk.content,
embedding: chunk.embedding,
similarity: 0.0
}
end
end
def search_vector_store(store, query)
store.sort_by { |entry| entry[:similarity] }.reverse
end
```
## See also
[Section titled “See also”](#see-also)
* [Embeddings](/guides/embeddings/) — generate vectors for semantic search
* [Page Classification](/guides/page-classification/) — the page-level analogue of chunk classification
* [Output Formats](/guides/output-formats/#table-identity-and-anchors) — table identity and anchor markers
* [Configuration Reference](/reference/configuration/#chunkingconfig) — all chunking options
# Code Intelligence
Xberg integrates [tree-sitter-language-pack](https://docs.tree-sitter-language-pack.xberg.io) (TSLP) to parse source code files. When you extract a source code file, Xberg detects the programming language, parses it with tree-sitter, and emits the source as content split at semantic boundaries – functions, classes, and modules – rather than fixed line counts.
Language support covers **371 programming languages** via tree-sitter grammars. See the [TSLP documentation](https://docs.tree-sitter-language-pack.xberg.io) for the full language list.
Not available in the WASM build
Code intelligence is **excluded from the WebAssembly build** (`@xberg-io/xberg-wasm`). The statically linked tree-sitter grammar pack for all 371 languages pushes the browser `.wasm` binary well past the 50 MB per-file limit imposed by public CDNs such as jsDelivr. Source files still extract as plain text in WASM, but they are not parsed or split at semantic boundaries. Use a native binding (Rust, Python, Node, Go, etc.) when you need code intelligence.
See the [TreeSitterConfig reference](/reference/configuration/#treesitterconfig) for all configuration options.
## What You Get
[Section titled “What You Get”](#what-you-get)
Extracting a source code file produces:
* **`content`** – the source text, split into code segments at tree-sitter chunk boundaries and rendered in the configured output format. When chunking is enabled, each segment is preceded by a heading naming its enclosing function, class, or module. With chunking disabled (the default), the whole source is emitted as a single code block.
* **`metadata.format`** – tagged as `code` (`format_type: "code"`), carrying the structural `chunks` and, when data extraction is enabled, the hierarchical `data` tree.
* **`code_intelligence`** – tree-sitter’s full analysis as an opaque JSON object: language, metrics, structure, imports, exports, comments, docstrings, symbols, diagnostics, chunks, and the data tree. It is populated for source files when the `tree-sitter` feature is enabled, and `null` otherwise.
`code_intelligence` is the serialized `tree_sitter_language_pack::ProcessResult`. It is deliberately untyped so every binding (Go, Java, C#, …) can read it as a raw JSON object; deserialize it against TSLP’s own schema if you need typed access.
## Getting Started
[Section titled “Getting Started”](#getting-started)
Code extraction is enabled by default when the `tree-sitter` feature flag is active. Extract a source code file and read `content`:
* Rust
basic.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
let config = ExtractionConfig::default();
let output = extract(ExtractInput::from_uri("app.py"), &config).await?;
let result = &output.results[0];
// The rendered source is in the content field.
println!("{}", result.content);
// metadata.format is tagged as Code and carries the structural chunks.
if let Some(xberg::types::FormatMetadata::Code(code)) = &result.metadata.format {
println!("Detected a source code file with {} chunks", code.chunks.len());
}
// The full tree-sitter analysis is an opaque JSON value.
if let Some(intelligence) = &result.code_intelligence {
println!("{intelligence}");
}
```
* Python
basic.py
```python
import json
import xberg
config = xberg.ExtractionConfig()
output = await xberg.extract(xberg.ExtractInput(kind="uri", uri="app.py"), config=config)
result = output.results[0]
# The rendered source is in the content field.
print(result.content)
# metadata["format"] is tagged as code and carries the structural chunks.
fmt = result.metadata.get("format")
if fmt and fmt.get("format_type") == "code":
print(f"Detected a source code file with {len(fmt['chunks'])} chunks")
# The full tree-sitter analysis is a JSON string in the Python binding.
if result.code_intelligence is not None:
print(json.loads(result.code_intelligence)["symbols"])
```
* TypeScript
basic.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "app.ts",
});
const result = output.results[0];
// The rendered source is in the content field.
console.log(result.content);
// metadata.format is tagged "code" and carries the structural chunks.
const fmt = result.metadata?.format;
if (fmt?.formatType === "code") {
console.log(`Detected a source code file with ${fmt.chunks.length} chunks`);
}
// The full tree-sitter analysis is an unknown-typed JSON object.
if (result.codeIntelligence) {
console.log(result.codeIntelligence);
}
```
* Go
basic.go
```go
result, err := xberg.Extract("app.py", nil)
if err != nil {
log.Fatal(err)
}
fmt.Println(result.Content)
// result.Metadata.Format is tagged "code" for source files, and
// result.CodeIntelligence carries the full tree-sitter analysis as raw JSON.
```
## Configuration
[Section titled “Configuration”](#configuration)
Use `TreeSitterConfig` to control tree-sitter processing. Set `enabled: false` to skip code intelligence entirely. `chunk_max_size` controls where the source is split into segments; when unset (the default), the whole file is emitted as a single block.
Which fields each toggle affects
`enabled` and `chunk_max_size` shape `content` and `metadata.format`. The `structure`, `imports`, `exports`, `comments`, `docstrings`, `symbols`, and `diagnostics` toggles are passed through to tree-sitter and decide which sections of `code_intelligence` are populated; they do not change `content`.
* Rust
config.rs
```rust
use xberg::{ExtractionConfig, TreeSitterConfig, TreeSitterProcessConfig};
let config = ExtractionConfig {
tree_sitter: Some(TreeSitterConfig {
process: TreeSitterProcessConfig {
chunk_max_size: Some(4096), // split source at chunk boundaries
..Default::default()
},
..Default::default()
}),
..Default::default()
};
```
* Python
config.py
```python
import xberg
config = xberg.ExtractionConfig(
tree_sitter={
"process": {
"chunk_max_size": 4096,
}
}
)
```
* TypeScript
config.ts
```typescript
import { ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
treeSitter: {
process: {
chunkMaxSize: 4096,
},
},
};
```
* TOML
xberg.toml
```toml
[tree_sitter.process]
chunk_max_size = 4096
```
### Configuration Fields
[Section titled “Configuration Fields”](#configuration-fields)
See [`TreeSitterConfig`](/reference/configuration/#treesitterconfig) and [`TreeSitterProcessConfig`](/reference/configuration/#treesitterprocessconfig) for all fields.
## Chunked Content
[Section titled “Chunked Content”](#chunked-content)
With `chunk_max_size` set, tree-sitter splits the source at function, class, and module boundaries and Xberg emits each chunk as a separate code segment in `content`, preceded by a heading naming its enclosing scope:
chunked.py
```python
import xberg
config = xberg.ExtractionConfig(
tree_sitter={"process": {"chunk_max_size": 2048}}
)
output = await xberg.extract(
xberg.ExtractInput(kind="uri", uri="large_module.py"), config=config
)
result = output.results[0]
# Chunk boundaries are reflected in the layout of result.content.
print(result.content)
```
Structured per-chunk data is also available without parsing `content`: each entry of `metadata.format.chunks` carries the chunk `text`, its `context_path` (enclosing scopes), the tree-sitter `node_types`, and the `byte_start`/`byte_end` offsets into the source. For general-purpose text chunking across all formats – for example, in a RAG pipeline – use Xberg’s [chunking pipeline](/guides/chunking/) instead.
## Language Detection
[Section titled “Language Detection”](#language-detection)
Xberg detects the programming language in two ways:
1. **File extension** (fast path) – when using `extract`, the extension is matched against 248 known language extensions
2. **Shebang line** (fallback) – when the extension is missing or ambiguous, the first line is checked for `#!/usr/bin/env python`, `#!/bin/bash`, and so on.
If neither method identifies the language, extraction returns an `UnsupportedFormat` error. The detected language drives parsing and is reported in `code_intelligence`.
## Language Support
[Section titled “Language Support”](#language-support)
Tree-sitter-language-pack supports 371 programming languages, including Python, Rust, TypeScript, JavaScript, Go, Java, C/C++, Ruby, PHP, C#, Swift, Kotlin, and Elixir. For the full list, see the [TSLP language reference](https://docs.tree-sitter-language-pack.xberg.io).
## Related Documentation
[Section titled “Related Documentation”](#related-documentation)
* [Configuration Reference](/reference/configuration/#treesitterconfig) – TreeSitterConfig and TreeSitterProcessConfig fields
* [Chunking Guide](/guides/chunking/) – programmatic chunking with offsets and metadata
* [tree-sitter-language-pack documentation](https://docs.tree-sitter-language-pack.xberg.io) – Full language support reference
# Concurrency & Scaling
> How Xberg sizes its thread pools, why the default caps at 8, and when adding CPU cores does not help.
Xberg derives one thread budget per process and shares it across every internal thread pool: the global Rayon pool, ONNX Runtime intra-op threads, and the batch worker count. This page explains how that budget is chosen, why it does not automatically scale past 8 threads, and when it will not help even after you raise it.
## The default: `min(cpu_cores, 8)`
[Section titled “The default: min(cpu\_cores, 8)”](#the-default-mincpu_cores-8)
Without an explicit configuration, the effective thread budget is `min(detected_cpu_cores, 8)`. This is a deliberate ceiling for serverless and shared-tenant defaults, not a scaling limit of the underlying pipelines. On a 16-core or 64-core host, the default configuration still uses only 8 threads.
This budget is the ceiling for everything:
* The global Rayon thread pool size
* ONNX Runtime intra-op thread count
* The batch worker count — batch extraction divides the total budget between document workers so nested per-document parallelism cannot multiply the process-wide CPU budget (`workers * thread_budget <= total_budget`)
## Raising the cap: `max_threads`
[Section titled “Raising the cap: max\_threads”](#raising-the-cap-max_threads)
`ConcurrencyConfig::max_threads` is the escape hatch. It must be set explicitly to use more than 8 threads on a bare-metal or VM host with no CPU quota; when unset, the default never scales past 8 on its own.
* CLI
Terminal
```bash
xberg batch documents/*.pdf --max-concurrent 4 --max-threads 16
```
* Config file
xberg.toml
```toml
[concurrency]
max_threads = 16
```
* Rust
```rust
use xberg::core::config::ConcurrencyConfig;
let config = ConcurrencyConfig {
max_threads: Some(16),
};
```
`max_threads` takes priority over both the host core count and any detected cgroup CPU quota.
## Containers: cgroup v2 CPU quota is honoured
[Section titled “Containers: cgroup v2 CPU quota is honoured”](#containers-cgroup-v2-cpu-quota-is-honoured)
When the process runs under a Linux cgroup CPU quota (containers, Kubernetes `resources.limits.cpu`) and `max_threads` is unset, Xberg reads the quota from cgroup v2’s `cpu.max` (falling back to cgroup v1’s `cpu.cfs_quota_us` / `cpu.cfs_period_us`) and uses it as the ceiling **instead of** the hardcoded 8 — not in addition to it. A quota above 8 cores is honoured in full; a quota below 8 cores is used as-is. The quota is clamped so it never exceeds the actual host core count, and it is read at most once per process since it cannot change while the process is running.
This means a container with `resources.limits.cpu: "24"` gets a 24-thread budget with no configuration required, while the same code running unconfigured on a bare-metal 24-core host with no cgroup quota still caps at 8.
An unset or “unlimited” quota (`max` in cgroup v2, `-1` in cgroup v1) is treated the same as “no quota found,” falling back to the default cap.
## Layout inference: adding cores will not help
[Section titled “Layout inference: adding cores will not help”](#layout-inference-adding-cores-will-not-help)
The largest scaling caveat applies to batches that run native PDF layout detection. The layout model (RT-DETR) is itself multi-threaded, so running multiple documents through it concurrently oversubscribes the CPU rather than speeding anything up:
* A batch where **every** input is a PDF using layout inference gets a single document worker with the full thread budget (`MAX_NATIVE_LAYOUT_BATCH_WORKERS = 1`). RT-DETR inference does not scale enough across multiple half-budget sessions to justify the additional resident memory.
* A batch with **mixed or uncertain** layout usage is capped at two document workers (`MAX_MIXED_LAYOUT_BATCH_WORKERS = 2`).
* Batches with no layout inference use the normal worker ceiling — up to the full thread budget, one worker per document, subject to `--max-concurrent`.
For an all-layout-PDF batch, raising `max_threads` still increases the per-document thread budget (more intra-op threads for that one worker), but it will not add more concurrent documents. Throughput for these batches is bound by single-document layout inference speed, not by core count.
A cores-vs-throughput benchmark that sweeps `max_threads` against a non-layout batch (expected to scale with cores) and an all-layout-PDF batch (expected to flatten) lives at `crates/xberg/benches/concurrency_scaling.rs`:
Terminal
```bash
cargo bench --bench concurrency_scaling --features pdf,layout-detection,ocr
```
## How do I tell if I’m hitting the default cap?
[Section titled “How do I tell if I’m hitting the default cap?”](#how-do-i-tell-if-im-hitting-the-default-cap)
A one-time `WARN`-level log fires the first time the thread budget is resolved, when the host has more than 8 cores, no cgroup CPU quota was found, and `max_threads` is unset. It names the detected core count and the applied cap:
```text
detected 16 CPU cores but no `max_threads` is configured and no cgroup CPU
quota was found; capping the thread budget at 8 (min(cpu_cores, 8)). Set
`ConcurrencyConfig::max_threads` above 8 to use the remaining cores.
```
The warning fires at most once per process, not once per extraction.
## Concurrent calls from your own code
[Section titled “Concurrent calls from your own code”](#concurrent-calls-from-your-own-code)
Your application can start several extractions at once with the concurrency primitives of its language. These calls share the same process-wide thread budget, so the budget still bounds the total CPU use:
* C#
C#
```csharp
using Xberg;
class Program {
static async Task Main() {
try {
var config = new ExtractionConfig();
var result = (await XbergConverter.ExtractAsync(
ExtractInput.FromUri("document.pdf"), config))
.Results[0];
Console.WriteLine($"Content length: {result.Content.Length}");
Console.WriteLine($"MIME type: {result.MimeType}");
var tasks = new[] {
XbergConverter.ExtractAsync(ExtractInput.FromUri("file1.pdf"), config),
XbergConverter.ExtractAsync(ExtractInput.FromUri("file2.pdf"), config),
XbergConverter.ExtractAsync(ExtractInput.FromUri("file3.pdf"), config)
};
var results = await Task.WhenAll(tasks);
foreach (var r in results) {
var document = r.Results[0];
Console.WriteLine($"Extracted {document.Content.Length} characters");
}
} catch (XbergException ex) {
Console.WriteLine($"Extraction failed: {ex.Message}");
}
}
}
```
* Wasm
Wasm
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
async function extractDocuments(files: Uint8Array[], mimeTypes: string[]) {
await init();
const results = await Promise.all(
files.map((bytes, index) => extract({ kind: "bytes", bytes, mimeType: mimeTypes[index] }, undefined)),
);
return results.map((r) => ({
content: r.results[0].content,
metadata: r.results[0].metadata,
}));
}
const fileBytes = [new Uint8Array([1, 2, 3])];
const mimes = ["application/pdf"];
extractDocuments(fileBytes, mimes)
.then((results) => console.log(results))
.catch(console.error);
```
For a fixed list of documents, prefer `extract_batch`. It divides the budget between document workers for you. See [Batch Processing](/guides/extraction/#batch-processing).
## See Also
[Section titled “See Also”](#see-also)
* [CLI Reference](/reference/cli/) - `--max-threads` and `--max-concurrent` flags
* [Configuration Reference](/reference/configuration/) - `ConcurrencyConfig` and `max_concurrent_extractions`
* [Docker Deployment](/guides/docker/)
* [Kubernetes Deployment](/guides/kubernetes/)
# Configuration Guide
All extraction behavior is controlled through `ExtractionConfig`. Pass it directly in code or load it from a TOML/YAML/JSON file. Every field is optional. For per-field documentation, see the [Configuration Reference](/reference/configuration/).
## Quick Start
[Section titled “Quick Start”](#quick-start)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig
async def main() -> None:
config = ExtractionConfig(
use_cache=True,
enable_quality_processing=True
)
result = await extract(ExtractInput(uri="document.pdf"), config)
print(result.results[0].content)
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
useCache: true,
enableQualityProcessing: true,
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
console.log(output.results?.[0]?.content);
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig {
use_cache: true,
enable_quality_processing: true,
..Default::default()
};
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
println!("{}", output.results[0].content);
Ok(())
}
```
* Go
Go
```go
package main
import (
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
useCache := true
enableQP := true
cfg := xberg.ExtractionConfig{
UseCache: &useCache,
EnableQualityProcessing: &enableQP,
}
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
log.Fatalf("extract failed: %v", err)
}
log.Println("content length:", len(result.Results[0].Content))
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInput;
ExtractionConfig config = ExtractionConfig.builder()
.withUseCache(true)
.withEnableQualityProcessing(true)
.build();
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("document.pdf").build(),
config
);
ExtractedDocument result = output.results().get(0);
```
* C#
C#
```csharp
using Xberg;
var config = new ExtractionConfig
{
UseCache = true,
EnableQualityProcessing = true
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
Console.WriteLine(result.Content);
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
use_cache: true,
enable_quality_processing: true
)
input = Xberg::ExtractInput.new(uri: 'document.pdf')
result = Xberg.extract(input, config)
```
## Configuration Files
[Section titled “Configuration Files”](#configuration-files)
Three formats are supported. TOML is recommended.
Xberg rejects unrecognized keys in its extraction configuration tables. A misspelled nested setting fails loading instead of being ignored; use the [Configuration Reference](/reference/configuration/) for the authoritative wire names. Settings inside `url.crawl` follow crawlberg’s configuration schema.
* TOML (Recommended)
xberg.toml
```toml
use_cache = true
enable_quality_processing = true
[ocr]
backend = "tesseract"
language = "eng"
```
* YAML
xberg.yaml
```yaml
use_cache: true
enable_quality_processing: true
ocr:
backend: tesseract
language: eng
```
* JSON
xberg.json
```json
{
"use_cache": true,
"enable_quality_processing": true,
"ocr": {
"backend": "tesseract",
"language": "eng"
}
}
```
### Automatic Discovery
[Section titled “Automatic Discovery”](#automatic-discovery)
When no `--config` path is supplied, Xberg walks up from the current working directory looking for `xberg.toml` and uses the first match. If no project-local file is found, it falls back to a per-user global config at `xberg/xberg.{toml,yaml,yml,json}` in the platform config directory — `$XDG_CONFIG_HOME` (or `~/.config`) on Linux, `~/Library/Application Support` on macOS, and `%APPDATA%` on Windows. In the project walk, YAML and JSON files are supported only when passed explicitly via `--config`. If nothing is found, defaults are used.
* Python
Python
```python
import asyncio
from xberg import ExtractInput, ExtractionConfig, extract
async def main() -> None:
config: ExtractionConfig = ExtractionConfig()
result = await extract(ExtractInput(uri="document.pdf"), config)
content: str = result.results[0].content
content_preview: str = content[:100]
print(f"Content preview: {content_preview}")
print(f"Total length: {len(content)}")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
// Note: the Node binding has no config-file discovery helper. Build the
// config object directly (or load `xberg.toml`/`xberg.yaml`/`xberg.json`
// yourself and parse it) and pass it to `extract`.
const config: ExtractionConfig = {
useCache: true,
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
console.log(output.results?.[0]?.content);
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig::discover()?.unwrap_or_default();
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
println!("{}", output.results[0].content);
Ok(())
}
```
* Go
Go
```go
package main
import (
"log"
"os"
"os/exec"
)
func main() {
command := exec.Command("xberg", "extract", "document.pdf")
command.Stdout = os.Stdout
command.Stderr = os.Stderr
if err := command.Run(); err != nil {
log.Fatalf("extract with automatically discovered config: %v", err)
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInput;
// Note: the Java binding has no config-file discovery helper. Build the
// config object directly (or load `xberg.toml`/`xberg.yaml`/`xberg.json`
// yourself and parse it) and pass it to `extract`.
ExtractionConfig config = ExtractionConfig.builder().build();
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("document.pdf").build(),
config
);
ExtractedDocument result = output.results().get(0);
```
* C#
C#
```csharp
using Xberg;
var config = new ExtractionConfig();
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
Console.WriteLine(result.Content[..Math.Min(100, result.Content.Length)]);
Console.WriteLine($"Total length: {result.Content.Length}");
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.discover
input = Xberg::ExtractInput.new(uri: 'document.pdf')
result = Xberg.extract(input, config)
```
* Wasm
WASM
```typescript
import init, { extract } from "@xberg-io/xberg-wasm";
await init();
const config = {
use_cache: true,
enable_quality_processing: true,
ocr: {
backend: "tesseract",
language: ["eng"],
},
};
const buffer = await fetch("document.pdf").then((response) => response.arrayBuffer());
const bytes = new Uint8Array(buffer);
const result = await extract({ kind: "bytes", bytes, mimeType: "application/pdf" }, config);
console.log(result.results[0].content);
```
Automatic discovery is a CLI and server feature. The Node binding has no discovery helper, so read the file yourself and pass the parsed object as `config`:
config\_discovery.ts
```typescript
/// { "eng", "fra" },
TesseractConfig = new TesseractConfig { Psm = 3 }
}
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
Console.WriteLine(result.Content);
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
ocr: Xberg::OcrConfig.new(
backend: 'tesseract',
language: 'eng+fra',
tesseract_config: Xberg::TesseractConfig.new(psm: 3)
)
)
```
For backend selection and language packs, see [OCR Guide](/guides/ocr/). For fine-grained Tesseract tuning, see [TesseractConfig Reference](/reference/configuration/#tesseractconfig).
For Sceptre, use the backend name `sceptre` and place its sections directly in `backend_options`:
xberg.toml
```toml
[ocr]
backend = "sceptre"
language = ["eng", "deu"]
[ocr.backend_options.recognition]
batch_size = 4
[ocr.backend_options.concurrency]
max_threads = 2
```
Do not nest these options under `backend_options.sceptre`. Custom Rust builds use `sceptre-ocr` for the ONNX Runtime desktop/server backend or `sceptre-ocr-tract` for Android and iOS. WebAssembly support uses the opt-in Sceptre worker build/API because the model and tract runtime size are not part of the default `wasm-target` bundle. Use `ocr.language` for language selection; it overrides `backend_options.model.languages`. Leave `backend_options.model.backend` unset so Xberg can select ORT or tract for the target. The supported option paths are `backend_options.detection.*`, `backend_options.recognition.*`, `backend_options.concurrency.max_threads`, `backend_options.model.cache_dir`, `backend_options.model.registry_owner`, `backend_options.model.detector_path`, and `backend_options.model.recognizer_path`. `cache_dir` and automatic model download apply only to desktop/server ORT builds. Android and iOS exclude the downloader; both model paths are required and must reference application-resolved bundle or asset files.
### Chunking for RAG
[Section titled “Chunking for RAG”](#chunking-for-rag)
* Python
Python
```python
from xberg import (
ExtractionConfig,
ChunkingConfig,
EmbeddingConfig,
EmbeddingModelType,
)
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
max_characters=1500,
overlap=200,
embedding=EmbeddingConfig(
model=EmbeddingModelType.preset("balanced")
),
)
)
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
chunking: {
maxCharacters: 1500,
overlap: 200,
embedding: {
model: { type: "preset", name: "quality" },
},
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
console.log(`Chunks created: ${output.results?.[0]?.chunks?.length ?? 0}`);
```
* Rust
Rust
```rust
use xberg::{ChunkingConfig, EmbeddingConfig, EmbeddingModelType, ExtractionConfig};
fn main() {
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
max_characters: 1500,
overlap: 200,
embedding: Some(EmbeddingConfig {
model: EmbeddingModelType::Preset {
name: "text-embedding-all-minilm-l6-v2".to_string(),
},
..Default::default()
}),
..Default::default()
}),
..Default::default()
};
println!("{:?}", config.chunking);
}
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(1000)
overlap := uint(200)
cfg := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
},
}
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
log.Fatalf("extract failed: %v", err)
}
for i, chunk := range result.Results[0].Chunks {
// Byte offsets (UTF-8 valid boundaries) into the original document text.
fmt.Printf("Chunk %d/%d (%d-%d)\n", i+1, chunk.Metadata.TotalChunks, chunk.Metadata.ByteStart, chunk.Metadata.ByteEnd)
fmt.Printf("%s...\n", chunk.Content[:min(len(chunk.Content), 100)])
}
}
func min(a, b int) int {
if a < b {
return a
}
return b
}
```
* Java
Java
```java
import io.xberg.ChunkingConfig;
import io.xberg.EmbeddingConfig;
import io.xberg.EmbeddingModelType;
import io.xberg.ExtractionConfig;
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withMaxCharacters(1500L)
.withOverlap(200L)
.withEmbedding(EmbeddingConfig.builder()
.withModel(new EmbeddingModelType.Preset("text-embedding-all-minilm-l6-v2"))
.build())
.build())
.build();
```
* C#
C#
```csharp
using Xberg;
using System;
using System.Collections.Generic;
using System.Threading.Tasks;
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 512,
Overlap = 50,
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("balanced"),
Normalize = true,
BatchSize = 32,
ShowDownloadProgress = false
}
}
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
var chunks = result.Chunks ?? new List();
foreach (var (index, chunk) in chunks.WithIndex())
{
var chunkId = $"doc_chunk_{index}";
Console.WriteLine($"Chunk {chunkId}: {chunk.Content[..Math.Min(50, chunk.Content.Length)]}");
if (chunk.Embedding != null)
{
Console.WriteLine($" Embedding dimensions: {chunk.Embedding.Count}");
}
}
internal static class EnumerableExtensions
{
public static IEnumerable<(int Index, T Item)> WithIndex(
this IEnumerable items)
{
var index = 0;
foreach (var item in items)
{
yield return (index++, item);
}
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
max_characters: 1500,
overlap: 200,
embedding: Xberg::EmbeddingConfig.new(
model: Xberg::EmbeddingModelType.new(
type: 'preset',
name: 'text-embedding-all-minilm-l6-v2'
)
)
)
)
```
### Concurrency and Thread Limits
[Section titled “Concurrency and Thread Limits”](#concurrency-and-thread-limits)
`ConcurrencyConfig.max_threads` caps every internal thread pool at once: the global Rayon pool, ONNX Runtime intra-op threads, and the combined document/worker budget used by batch extraction.
**When `max_threads` is left unset, the effective budget is `min(detected_cpu_cores, 8)` — not “use all available cores”.** This 8-core ceiling is a deliberate serverless/shared-tenant default, not an auto-scaling target. On a host with more than 8 cores, the extra cores go unused by default:
* **Bare metal / VM with no CPU quota**: `max_threads` must be set explicitly above 8 to use more than 8 cores. There is no other way to exceed the default ceiling on this class of host.
* **Linux containers under a cgroup CPU quota** (e.g. Kubernetes `resources.limits.cpu`): the quota is used as the ceiling instead of the hardcoded 8, since the quota already reflects a deliberately-configured resource limit. This applies automatically; no configuration is needed.
If none of the above applies and the host has more than 8 cores, a one-time `WARN`-level log is emitted the first time the thread budget is resolved, naming the detected core count and the applied cap — so the ceiling is discoverable without reading source.
```toml
[concurrency]
max_threads = 32
```
## All Configuration Categories
[Section titled “All Configuration Categories”](#all-configuration-categories)
* [ExtractionConfig](/reference/configuration/#extractionconfig) — top-level options
* [OcrConfig](/reference/configuration/#ocrconfig) — OCR backend, language, acceleration
* [TesseractConfig](/reference/configuration/#tesseractconfig) — Tesseract PSM, confidence, table detection
* [ChunkingConfig](/reference/configuration/#chunkingconfig) — chunk size, overlap
* [TokenReductionConfig](/reference/configuration/#tokenreductionconfig) — LLM prompt token reduction
* [ContentFilterConfig](/reference/configuration/#contentfilterconfig) — header/footer/watermark filtering
* [PageConfig](/reference/configuration/#pageconfig) — page tracking and markers
* [AccelerationConfig](/reference/configuration/#accelerationconfig) — ONNX Runtime execution provider
* [ConcurrencyConfig](#concurrency-and-thread-limits) — thread pool caps (`max_threads`); not in the auto-generated reference below, see the section above
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Extraction Basics](/guides/extraction/) — core extraction API and supported formats
* [OCR Guide](/guides/ocr/) — backend installation and language setup
* [Embeddings](/guides/embeddings/) — semantic vectors for search
* [Language Detection](/guides/language-detection/) — multilingual document analysis
* [Chunking](/guides/chunking/) — split text for RAG with page tracking
* [Plugins Guide](/guides/plugins/) — custom post-processors and validators
# Development Workflow
Everything you need to build, test, and debug Xberg locally. This guide assumes you’ve already followed the [Contributing Guide](/contributing/) to fork and clone the repository.
***
## The Task Runner
[Section titled “The Task Runner”](#the-task-runner)
Xberg uses [Task](https://taskfile.dev/) for all build and test workflows. One command to bootstrap everything:
Terminal
```bash
task setup
```
That installs all toolchains and dependencies. Safe to re-run anytime — it’s idempotent.
### Core Tasks
[Section titled “Core Tasks”](#core-tasks)
Top-level tasks operate on the Rust core:
Terminal
```bash
task build # Build the Rust core (debug)
task build:release # Build the Rust core (release)
task test # Run Rust core tests
task check # Lint + format check across the whole repo
```
The Rust namespace exposes the finer-grained variants:
Terminal
```bash
task rust:build:dev # Debug build (faster compile, no optimizations)
task rust:build:release # Release build (slow compile, fast binary)
task rust:test # Run all Rust tests
task rust:test:ci # Same tests, with CI diagnostics (tessdata setup)
task rust:test:quick # Fast unit tests only
```
Language bindings are generated and compiled by Alef, so they do not each get a `:build`/`:test` pair. Build and test them through the aggregate tasks below, or via the per-language e2e and native-test tasks (see [End-to-end Test Suites](#end-to-end-test-suites)).
### Bulk Operations
[Section titled “Bulk Operations”](#bulk-operations)
Terminal
```bash
task build:all # Build core + every binding
task build:bindings # Build every binding (via Alef)
task test:all # Run all tests (core + bindings)
task test:bindings # Run binding test suites only
task test:cov # All tests with coverage
task check # Lint + format check across the whole repo
```
***
## Testing Locally
[Section titled “Testing Locally”](#testing-locally)
### Rust
[Section titled “Rust”](#rust)
The core lives in `crates/xberg/`. Most changes start here.
Terminal
```bash
task rust:test
cargo test -p xberg test_pdf_extraction -- --nocapture
RUST_LOG=debug cargo test -p xberg test_name -- --nocapture
```
### Bindings
[Section titled “Bindings”](#bindings)
Bindings are generated and compiled by Alef. Build them all, then run their tests:
Terminal
```bash
task build:bindings # Compile every binding
task test:bindings # Run every binding test suite
```
A few native bindings expose their own unit-test task:
Terminal
```bash
task swift:test
task zig:test
task dart:test
task kotlin-android:test
```
For all other languages the cross-language check is the e2e suite — `task python:e2e`, `task node:e2e`, `task go:e2e`, and so on (see [End-to-end Test Suites](#end-to-end-test-suites)).
The `RUST_LOG` env var propagates into every binding — the Rust core logs through the host process’s stderr:
Terminal
```bash
RUST_LOG=debug task python:e2e
```
### Testing the live browser demo
[Section titled “Testing the live browser demo”](#testing-the-live-browser-demo)
The demo at `docs-site/public/demo.html` loads `@xberg-io/xberg-wasm` from a CDN. To test local changes against it, use:
Terminal
```bash
task demo:dev
```
This builds the Wasm binary and TypeScript dist, patches the demo with local URLs, and starts two servers:
| Server | URL | Role |
| ------ | ----------------------- | ---------------------------------- |
| Docs | `http://localhost:8001` | Serves the patched `demo-dev.html` |
| Assets | `http://localhost:9000` | Serves the local Wasm package |
Open **`http://localhost:8001/demo-dev.html`** — no manual edits needed. The patched file (`docs-site/public/demo-dev.html`) is gitignored and regenerated on every run. The two different ports reproduce the cross-origin setup the CDN creates in production.
To skip the slow Rust build when you’ve only changed TypeScript:
Terminal
```bash
SKIP_WASM_BUILD=1 task demo:dev
```
***
## Working with Alef Bindings
[Section titled “Working with Alef Bindings”](#working-with-alef-bindings)
Every language binding — the crates under `crates/xberg-*`, the packages under `packages/`, the READMEs, and the e2e suites — is generated by [Alef](https://github.com/xberg-io/alef) from the Rust source and `alef.toml`. Do not hand-edit generated output; it is overwritten on the next regeneration.
To change a binding, edit the Rust source, README templates, fixtures, or `alef.toml`, then regenerate:
Terminal
```bash
task alef:generate # Regenerate all Alef-managed output (alef all --clean, formatting via poly, no build)
task alef:build # Compile the bindings (same as build:bindings)
task alef:sync # Sync the version from Cargo.toml to every manifest
task alef:verify # Check that generated output is up to date
```
`task alef:generate` regenerates and formats (via `poly`) without compiling. Commit the generator inputs and regenerated output together in one change.
***
## End-to-end Test Suites
[Section titled “End-to-end Test Suites”](#end-to-end-test-suites)
End-to-end tests guarantee that every language binding produces identical results for the same document. They live in `e2e/` as shared fixtures — test inputs paired with expected outputs.
### Run end-to-end Tests
[Section titled “Run end-to-end Tests”](#run-end-to-end-tests)
Each language runs its suite with `task :e2e`:
| Language | Directory | Run with |
| -------------------- | --------------------- | ------------------------- |
| Python | `e2e/python/` | `task python:e2e` |
| TypeScript / Node.js | `e2e/node/` | `task node:e2e` |
| Rust | `e2e/rust/` | `task rust:e2e` |
| Go | `e2e/go/` | `task go:e2e` |
| Java | `e2e/java/` | `task java:e2e` |
| .NET | `e2e/csharp/` | `task csharp:e2e` |
| Ruby | `e2e/ruby/` | `task ruby:e2e` |
| PHP | `e2e/php/` | `task php:e2e` |
| Elixir | `e2e/elixir/` | `task elixir:e2e` |
| Swift | `e2e/swift/` | `task swift:e2e` |
| Zig | `e2e/zig/` | `task zig:e2e` |
| Dart | `e2e/dart/` | `task dart:e2e` |
| Kotlin / Android | `e2e/kotlin_android/` | `task kotlin-android:e2e` |
| WebAssembly | `e2e/wasm/` | `task wasm:e2e` |
Or run one suite by name with `task e2e:lang E2E_LANG=python`.
### Regenerate end-to-end Tests
[Section titled “Regenerate end-to-end Tests”](#regenerate-end-to-end-tests)
E2E suites are generated from shared fixtures by Alef. Generation is repo-wide, not per-language. The canonical tasks are:
Terminal
```bash
task e2e:generate # Regenerate all suites from fixtures
task e2e:build # Build the bindings the suites link against
task e2e:test # Run every suite
task e2e:all # Generate, build, and run in one pass
```
Verify the checked-in suites are current with `task e2e:verify`.
***
## Benchmarking
[Section titled “Benchmarking”](#benchmarking)
Measure extraction performance with the benchmark harness in `tools/benchmark-harness/`. Use it to track regressions, compare against alternatives, and identify bottlenecks with flamegraphs.
### Quick Start
[Section titled “Quick Start”](#quick-start)
Terminal
```bash
task benchmark:run FRAMEWORK=xberg MODE=single-file
task benchmark:run FRAMEWORK=xberg MODE=batch
```
### Common Modes
[Section titled “Common Modes”](#common-modes)
| Mode | What it measures |
| ------------- | --------------------------------------- |
| `single-file` | Latency — one file at a time |
| `batch` | Throughput — multiple files in parallel |
### With Profiling
[Section titled “With Profiling”](#with-profiling)
Generate flamegraphs to see where time is spent:
Terminal
```bash
task benchmark:profile
```
This builds with the `profiling` profile (release plus debug symbols) and runs the pipeline benchmark. Results appear under `flamegraphs//` as interactive SVGs.
View live benchmark results at .
***
## Linting and Pre-commit
[Section titled “Linting and Pre-commit”](#linting-and-pre-commit)
Terminal
```bash
task lint # Lint all code via poly
task format # Format all code via poly
task check # Format + lint check, no modifications (CI-equivalent)
```
`poly` handles Python (ruff), JS/TS (oxc), TOML, and Markdown directly, so those languages have no dedicated lint task. Compiled bindings expose a native linter:
Terminal
```bash
task rust:lint # cargo fmt + clippy (auto-fix); rust:lint:check for check-only
task go:lint # golangci-lint
task ruby:lint # rubocop + steep
task php:lint # mago
task csharp:lint # dotnet format
task swift:lint # swift format lint
task zig:lint # zig fmt --check
```
The repository uses pre-commit hooks that enforce conventional commit messages, code formatting, and linter rules. If a commit is rejected, the hook output tells you exactly what to fix.
***
## Working with Documentation
[Section titled “Working with Documentation”](#working-with-documentation)
Docs are an Astro Starlight site under `docs-site/`.
### Building Locally
[Section titled “Building Locally”](#building-locally)
Terminal
```bash
task docs:build # pnpm install + astro build
task docs:serve # pnpm install + astro dev (live reload)
```
### How Snippets Work
[Section titled “How Snippets Work”](#how-snippets-work)
Documentation examples have two source paths:
* Prefer fixture-backed examples for public APIs shared across languages. Add or update the JSON fixture under `fixtures/`, run `task e2e:generate`, and render its generated snippets with `ApiSnippetGroup`. The generated files under `docs-site/src/snippets-generated/` are Alef output; never edit them directly.
* Use maintained snippets under `docs-site/src/snippets/` only for examples that do not map to an E2E fixture, such as deployment, server, or language-specific workflows. Import these Markdown files into the relevant `.mdx` page as Astro components.
A fixture-backed example renders every available language without one import per binding:
```mdx
import ApiSnippetGroup from "../../../components/ApiSnippetGroup.astro";
.
***
# Diagram DOT Output
Vector diagrams — SVG and vector PDF — already contain the node/edge structure a raster diagram would need a detection model to infer: boxes are closed outlines, connectors are open strokes, and labels are text drawn on top. Xberg recovers that structure deterministically from the geometry and can render it as [Graphviz DOT](https://graphviz.org/doc/info/lang.html) via `output_format="dot"`.
## Quick Start
[Section titled “Quick Start”](#quick-start)
* Python
diagram\_dot\_output.py
```python
from xberg import ExtractInput, ExtractionConfig, extract
config = ExtractionConfig(output_format="dot")
output = await extract(ExtractInput(kind="uri", uri="architecture.svg"), config=config)
result = output.results[0]
print(result.content) # Graphviz DOT, or "" if no diagram was recovered
```
* Rust
diagram\_dot\_output.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, OutputFormat};
let config = ExtractionConfig {
// "dot" is not a first-class `OutputFormat` variant (unlike `DocTags`); it is
// reached through the renderer registry via `OutputFormat::Custom`.
output_format: OutputFormat::Custom("dot".to_string()),
..Default::default()
};
let output = extract(ExtractInput::from_uri("architecture.svg"), &config).await?;
let result = &output.results[0];
println!("{}", result.content);
```
`output_format="dot"` **replaces** `result.content` with the DOT text — it does not append to or accompany the normal extracted content. If no diagram is recovered from the source, `content` is the **empty string**, not an error and not the document’s ordinary text. A caller relying on `content` for anything other than the recovered diagram must check `output_format` first.
The CLI’s `--content-format` flag does not currently expose registry renderers such as `dot` (it accepts `plain`, `markdown`, `djot`, `html`, `json`, `doctags`); use a language binding or the Rust API for DOT output today.
## What Gets Recovered
[Section titled “What Gets Recovered”](#what-gets-recovered)
A vector drawing is not necessarily a diagram. Recovery requires at least one connector resolving to a pair of distinct shapes — a page of prose, a logo, or a bar chart yields no diagram and `content` comes back empty. When a diagram is found, each recovered node carries:
* its outline shape, mapped onto Graphviz’s `shape` attribute (`box`, `ellipse`, `diamond`, or `polygon` for anything else),
* the text drawn inside it, joined with `\n` in reading order,
* fill and stroke colour (when they are a flat colour rather than a gradient or pattern),
* stroke width and whether the outline is dashed.
Each recovered edge carries its direction (from the arrowhead, or from the connector’s own point order when it draws none), an optional label, and its own stroke colour and dash style. Recovery is deterministic: nodes are ordered top to bottom then left to right, edges are ordered by their endpoints, and duplicates of both are collapsed.
A source can draw more than one diagram — most often one per page of a vector PDF. Xberg recovers a diagram for every page that draws one; the DOT output emits one `digraph` block per recovered diagram, separated by a blank line.
## Corpus-Verified Producers
[Section titled “Corpus-Verified Producers”](#corpus-verified-producers)
Recovery is tested against real output from these tools, not hand-authored SVG:
* **Graphviz** — `dot` and `neato` layouts, `shape=record`, `doublecircle`, clusters, self-loops, orthogonal routing, undirected graphs, bidirectional edges
* **Mermaid** (11.16.0) — flowcharts, including HTML labels in `` and edge labels drawn on an opaque background box
* **PlantUML** (1.2026.0) — activity diagrams and swimlanes
* **LibreOffice Draw** (26.2.5.2) — `draw:custom-shape` enhanced geometry and glued connectors
## What Recovery Rejects
[Section titled “What Recovery Rejects”](#what-recovery-rejects)
Recovery is deliberately conservative. It returns nothing for:
* **Charts** — a bar chart’s axes and gridlines look like connectors joining closed regions, but there is no arrowhead or shape-to-shape relationship to recover. A pie chart’s leader lines connecting a slice to its label look like edges to unlabelled decoration, not to another node.
* **Ruled tables** — a table drawn with ruling lines has the same signature as a diagram: closed rectangular regions with text inside, joined by straight strokes running from one region to the next. Recovery distinguishes the two by whether an outline’s text is laid out as a grid (multiple rows *and* multiple columns); a table is rejected as a node candidate without disabling recovery for a genuine diagram elsewhere on the same page.
* **Edgeless drawings** — icons, illustrations, and any collection of shapes with no connector between them. At least one connector resolving to two distinct shapes is required before anything is reported; an edgeless list of outlines is noise dressed up as structure, not a diagram.
Container shapes — Graphviz clusters, BPMN pools, PlantUML swimlanes — are recognized and dropped rather than reported as nodes, since a connector between two boxes inside a cluster is drawn to the boxes, not the cluster border around them.
## See Also
[Section titled “See Also”](#see-also)
* [Output Formats](/guides/output-formats/) — built-in content formats (`Plain`, `Markdown`, `Djot`, `Html`, `Json`, `DocTags`)
* [DocTags Output](/guides/doctags-output/) — another format that replaces `content` with a different vocabulary
* [Configuration Reference](/reference/configuration/) — full `ExtractionConfig` field list
# Docker Deployment
Official Docker images built on the Rust core with Debian 13 (Trixie). Each image supports three execution modes: API server (default), command-line tool, and MCP server.
## Quick Start
[Section titled “Quick Start”](#quick-start)
### Pull and Run
[Section titled “Pull and Run”](#pull-and-run)
* API Server
Bash
```bash
# Start API server (default mode)
docker run -p 8000:8000 ghcr.io/xberg-io/xberg:latest
# Test the API
curl -F "files=@document.pdf" http://localhost:8000/extract
```
* CLI Mode
Bash
```bash
# Extract a single file
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
extract /data/document.pdf
# Batch process multiple files
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
batch /data/*.pdf --output-format json
# Detect MIME type
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
detect /data/unknown-file.bin
```
* MCP Server
Bash
```bash
# Start MCP server
docker run ghcr.io/xberg-io/xberg:latest mcp
```
### Pull Image
[Section titled “Pull Image”](#pull-image)
* Core
Bash
```bash
docker pull ghcr.io/xberg-io/xberg:core
```
* Full
Bash
```bash
docker pull ghcr.io/xberg-io/xberg:latest
```
## Image Variants
[Section titled “Image Variants”](#image-variants)
| | **Core** | **Full** |
| ----------------- | ------------------------------ | ------------------------------- |
| **Image** | `ghcr.io/xberg-io/xberg:core` | `ghcr.io/xberg-io/xberg:latest` |
| **Size** | \~1.0–1.3 GB | \~1.5–2.1 GB |
| **Tesseract OCR** | 12 languages | 12 languages |
| **Modern Office** | DOCX, PPTX, XLSX | DOCX, PPTX, XLSX |
| **Legacy Office** | DOC, PPT, XLS (native OLE/CFB) | DOC, PPT, XLS (native OLE/CFB) |
| **Startup** | \~1s | \~1s |
**Core** is optimized for production deployments where image size matters. Both images support all major formats — choose based on deployment constraints.
All images include: Tesseract OCR (eng, spa, fra, deu, ita, por, chi-sim, chi-tra, jpn, ara, rus, hin), PDF (xberg-native-pdf), images, HTML, email, and archives.
CPU only
All published Docker images (Core, Full, and CLI) run ONNX Runtime on CPU. There is no published GPU/CUDA image. GPU acceleration is available, but requires building from source with the `cuda` feature against a CUDA-enabled ONNX Runtime — the prebuilt ORT binaries these images ship with do not include CUDA support. See [GPU Acceleration](/getting-started/installation/#gpu-acceleration).
## Execution Modes
[Section titled “Execution Modes”](#execution-modes)
### API Server (Default)
[Section titled “API Server (Default)”](#api-server-default)
Terminal
```bash
docker run -p 8000:8000 ghcr.io/xberg-io/xberg:latest
# Custom port and CORS
docker run -p 9000:9000 \
-e XBERG_CORS_ORIGINS="https://myapp.com" \
ghcr.io/xberg-io/xberg:latest \
serve --host 0.0.0.0 --port 9000
# With config file
docker run -p 8000:8000 \
-v $(pwd)/xberg.toml:/config/xberg.toml \
ghcr.io/xberg-io/xberg:latest \
serve --config /config/xberg.toml
```
See [API Server Guide](/guides/api-server/) for endpoint documentation.
### CLI Mode
[Section titled “CLI Mode”](#cli-mode)
Terminal
```bash
# Extract a file
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
extract /data/document.pdf
# Extract with OCR
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
extract /data/scanned.pdf --ocr true
# Batch processing
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
batch /data/*.pdf --format json
# MIME detection
docker run -v $(pwd):/data ghcr.io/xberg-io/xberg:latest \
detect /data/unknown-file.bin
```
### MCP Server
[Section titled “MCP Server”](#mcp-server)
Terminal
```bash
docker run ghcr.io/xberg-io/xberg:latest mcp
# With config
docker run \
-v $(pwd)/xberg.toml:/config/xberg.toml \
ghcr.io/xberg-io/xberg:latest \
mcp --config /config/xberg.toml
```
See [API Server Guide - MCP Section](/guides/api-server/#mcp-server) for integration details.
## Environment Variables
[Section titled “Environment Variables”](#environment-variables)
| Variable | Default | Description |
| --------------------------------- | ------------------------- | ------------------------------------------------------------------------------------------------ |
| `XBERG_MAX_REQUEST_BODY_BYTES` | `104857600` | Max request body size in bytes |
| `XBERG_MAX_MULTIPART_FIELD_BYTES` | `104857600` | Max multipart field (upload) size in bytes |
| `XBERG_CORS_ORIGINS` | `*` | Comma-separated allowed origins |
| `RUST_LOG` | `info` | Log level: `error`, `warn`, `info`, `debug`, `trace` |
| `XBERG_CACHE_DIR` | `/app/.xberg` | Cache directory (set explicitly in Docker; outside containers defaults to platform global cache) |
| `HF_HOME` | `/app/.xberg/huggingface` | HuggingFace model cache |
Host and port are set via CLI args: `serve --host 0.0.0.0 --port 8000`.
## Volume Mounts
[Section titled “Volume Mounts”](#volume-mounts)
Terminal
```bash
# Cache persistence (embedding models, OCR cache)
docker run -p 8000:8000 \
-v xberg-cache:/app/.xberg \
ghcr.io/xberg-io/xberg:latest
# Config file
docker run -p 8000:8000 \
-v $(pwd)/xberg.toml:/config/xberg.toml \
ghcr.io/xberg-io/xberg:latest \
serve --config /config/xberg.toml
# Documents (read-only)
docker run -v $(pwd)/documents:/data:ro \
ghcr.io/xberg-io/xberg:latest \
extract /data/document.pdf
```
Model Downloads
Embedding models download on first use (\~90 MB – 1.2 GB depending on preset). Use a persistent volume for `/app/.xberg` in production to avoid re-downloading on container restart. Outside Docker, models are cached in the platform-specific global cache directory (for example, `~/.cache/xberg/` on Linux, `~/Library/Caches/xberg/` on macOS).
## Docker Compose
[Section titled “Docker Compose”](#docker-compose)
docker-compose.yaml
```yaml
services:
xberg-api:
image: ghcr.io/xberg-io/xberg:latest
ports:
- "8000:8000"
environment:
- XBERG_CORS_ORIGINS=https://myapp.com
- XBERG_MAX_REQUEST_BODY_BYTES=524288000
- RUST_LOG=info
volumes:
- ./config:/config
- cache-data:/app/.xberg
command: serve --host 0.0.0.0 --port 8000 --config /config/xberg.toml
restart: unless-stopped
healthcheck:
test: ["CMD", "xberg", "--version"]
interval: 30s
timeout: 10s
retries: 3
start_period: 5s
volumes:
cache-data:
```
## Security
[Section titled “Security”](#security)
Images run as non-root user `xberg` (UID 1000). For hardened deployments:
Terminal
```bash
docker run --security-opt no-new-privileges \
--read-only \
--tmpfs /tmp \
-p 8000:8000 \
ghcr.io/xberg-io/xberg:latest
```
Ensure mounted volumes have correct permissions:
Terminal
```bash
chown -R 1000:1000 /path/to/mounted/directory
```
## Resource Allocation
[Section titled “Resource Allocation”](#resource-allocation)
| Workload | Memory | CPU | Notes |
| -------- | ------ | --------- | --------------------------------------- |
| Light | 512 MB | 0.5 cores | Small documents, low concurrency |
| Medium | 1 GB | 1 core | Typical documents, moderate concurrency |
| Heavy | 2 GB+ | 2+ cores | Large documents, OCR, high concurrency |
Terminal
```bash
docker run -p 8000:8000 --memory=1g --cpus=1 \
ghcr.io/xberg-io/xberg:latest
```
## Building Custom Images
[Section titled “Building Custom Images”](#building-custom-images)
* Core Image
Bash
```bash
docker build -f docker/Dockerfile.core -t xberg:core .
```
* Full Image
Bash
```bash
docker build -f docker/Dockerfile.full -t xberg:full .
```
Custom Dockerfile
```dockerfile
FROM ghcr.io/xberg-io/xberg:latest
USER root
RUN apt-get update && \
apt-get install -y --no-install-recommends your-package-here && \
apt-get clean && rm -rf /var/lib/apt/lists/*
USER xberg
COPY xberg.toml /app/xberg.toml
CMD ["serve", "--config", "/app/xberg.toml"]
```
## Other Image Variants
[Section titled “Other Image Variants”](#other-image-variants)
The published Core and Full images cover most use cases. For specialized needs, the `docker/` directory has additional Dockerfiles:
| Dockerfile | What it builds |
| ------------------------- | --------------------------------------------------------------------------------- |
| `Dockerfile.cli` | Minimal image with just the `xberg` binary — good for CI pipelines and batch jobs |
| `Dockerfile.musl-build` | Fully static Linux binaries via MUSL — runs on any distro, no dynamic libs |
| `Dockerfile.musl-ffi` | Static C FFI library for language bindings (Go, Ruby, PHP, Elixir) |
| `Dockerfile.musl-rustler` | MUSL-based Rustler NIF for Elixir |
### CLI Image
[Section titled “CLI Image”](#cli-image)
A stripped-down image with only the CLI binary. No server, no API — just extraction:
Terminal
```bash
docker build -f docker/Dockerfile.cli -t xberg-cli .
docker run -v $(pwd):/data xberg-cli extract /data/document.pdf
docker run -v $(pwd):/data xberg-cli batch /data/*.pdf --format json
docker run -v $(pwd):/data xberg-cli detect /data/unknown-file.bin
```
### MUSL Static Builds
[Section titled “MUSL Static Builds”](#musl-static-builds)
These produce binaries with zero dynamic library dependencies. A single file that runs on any Linux — Alpine, scratch containers, bare EC2 instances, whatever.
Terminal
```bash
docker build -f docker/Dockerfile.musl-build -t xberg-musl-build .
docker build -f docker/Dockerfile.musl-ffi -t xberg-musl-ffi .
```
The FFI variant builds a shared library used by the Go, Ruby, PHP, and Elixir bindings for portable cross-platform distribution.
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
Container won’t start
Check logs with `docker logs `. Common causes: port conflict (change `-p` mapping), insufficient memory (increase `--memory`), volume permission errors.
Permission errors on mounted volumes
Images run as UID 1000. Fix with: `chown -R 1000:1000 /path/to/mounted/directory`
Large file processing fails
Increase memory limit (`--memory=4g`) and upload size (`-e XBERG_MAX_MULTIPART_FIELD_BYTES=1048576000`).
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Kubernetes Deployment](/guides/kubernetes/) — deploy on a cluster with the Helm chart
* [API Server Guide](/guides/api-server/) — endpoint documentation
* [Configuration](/guides/configuration/) — all configuration options
# DocTags Output
DocTags is the tag-stream vocabulary used by [Docling](https://github.com/docling-project/docling) and the SmolDocling / Granite-Docling vision-language models. Xberg can both render its internal document model to DocTags and parse DocTags back in, so it works as an interchange format with that ecosystem.
DocTags is **not** a markdown-like format. It has no headings-with-`#`, no inline emphasis markup, and no escaping mechanism. Every element in the document is wrapped in its own tag, one element per line, and the whole stream is wrapped in `... `.
## Quick Start
[Section titled “Quick Start”](#quick-start)
* CLI
Terminal
```bash
xberg extract report.pdf --content-format doctags
```
* Python
doctags\_output.py
```python
from xberg import ExtractInput, ExtractionConfig, extract
config = ExtractionConfig(output_format="doctags")
output = await extract(ExtractInput(kind="uri", uri="report.pdf"), config=config)
result = output.results[0]
print(result.content) # DocTags stream
```
* Rust
doctags\_output.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, OutputFormat};
let config = ExtractionConfig {
output_format: OutputFormat::DocTags,
..Default::default()
};
let output = extract(ExtractInput::from_uri("report.pdf"), &config).await?;
let result = &output.results[0];
println!("{}", result.content);
```
Xberg also accepts DocTags as **input**, parsing it back into its internal document model, so it round-trips through xberg’s own pipeline — reranking, chunking, redaction and so on all work on parsed DocTags the same as on any other source format.
Detection is by the `.doctags` extension or the `text/vnd.docling.doctags` MIME type (`application/vnd.docling.doctags` is accepted as an alias). Note that DocTags has no registered IANA media type and its files are conventionally named `*.doctags.txt` — that double extension resolves to plain text, so for those files you must pass the MIME type explicitly rather than relying on extension detection.
## Example
[Section titled “Example”](#example)
A one-page PDF (US Letter, 612 × 792pt) with a title and a body paragraph renders to:
```text
<loc_50><loc_0><loc_250><loc_250>Report
Body text. ` tokens (left, top, right, bottom) appear only when the element carries both a bounding box and a page with recorded dimensions — in practice that means the PDF path today. Formats with no geometry (Markdown, HTML, plain text sources, etc.) render the same elements with no `` tokens at all; this is a deliberate degradation, not a bug.
## The 0–500 Location Grid
[Section titled “The 0–500 Location Grid”](#the-0500-location-grid)
`` values are not page points — they are normalized onto a fixed **0–500 integer grid** per page, following Docling’s own convention. A box that spans the full width of the page renders as `` … `` regardless of whether the page is US Letter or A4.
The PDF `BoundingBox` type has a bottom-left origin (`y0` is the bottom edge, following PDF user space), while DocTags counts from the **top-left**. The renderer flips the vertical axis when converting, and the parser flips it back when reading DocTags in. A box near the top of the page has a *small* second `` value; a box near the bottom has a *large* one.
Because the grid — not the true page size — is what’s encoded, the original page dimensions are **not recoverable** from a DocTags stream. When xberg parses DocTags, it reconstructs each page as a 500×500 square rather than the source page’s real dimensions. This is intentional: using the grid itself as the reconstructed page means re-rendering a parsed document reproduces the exact same `` tokens it started with, even though the “page size” it’s built against is fictional.
## Tables: OTSL
[Section titled “Tables: OTSL”](#tables-otsl)
Tables render as OTSL (the table markup Docling defines), nested inside `... `:
```text
NameAgeAlice30 ` — header cell (first row)
* `` — filled (body) cell
* `` — empty cell (also used to pad ragged rows out to a rectangular grid)
* `` — row separator
**Merge tokens are asymmetric between read and write.** OTSL also defines `` (continues the cell to its left), `` (continues the cell above), and `` (continues either), used to represent row/column-spanning cells. Xberg’s **parser** expands these when reading DocTags produced elsewhere — a merged cell becomes duplicate content in each of the grid positions it spanned. Xberg’s **renderer** never emits them: `Table::cells` is a flat `Vec>` with no span information, so there is nothing to encode a merge from. A table with spanning cells that round-trips through xberg (DocTags in → xberg internal model → DocTags out) loses the span and comes back as literal, repeated cell values instead of merge tokens.
## No Escaping
[Section titled “No Escaping”](#no-escaping)
DocTags has no escaping mechanism, matching Docling’s own serializer: `&` and `<` in source prose are written **literally**, and only recognized tag names (`text`, `title`, `otsl`, `loc_*`, and so on) are treated as markup — anything else, including a stray `<`, is content.
```python
result.content # e.g. "results & performance for a < b "
```
If your source document’s prose contains `results & performance for a < b`, that string appears in the DocTags output byte-for-byte — it is not turned into `&` or `<`. This is required for compatibility with real Docling output, which does the same thing (the vendored corpus includes a caption that literally discusses `' < td > '`).
## Checkboxes
[Section titled “Checkboxes”](#checkboxes)
`` and `` wrap their label text rather than standing alone, matching real Docling output, e.g. `Confirmed ` element. Parsing that back does not reconstruct it as an admonition — it becomes an ordinary paragraph. The admonition’s distinct body content is also not preserved separately: xberg stores only one string for an admonition (title-or-kind), so there was nothing else to lose here, but the *admonition-ness* itself does not survive a round trip.
* **Comments** have no DocTags tag either. A `CommentDefinition` renders through whatever content layer it was tagged with — `` if marked as a footnote, `` otherwise — rather than being dropped, so the text survives, but it is indistinguishable from an ordinary footnote or paragraph on the way back in. A `CommentRef` (the inline marker pointing at the comment) carries no content of its own and is dropped entirely; only the resolved comment body is emitted.
* **Metadata blocks** are exploded into one `` element per `key: value` entry (e.g. `Author: Alice `, `Date: 2026 `). Parsing DocTags back in reads these as ordinary paragraphs — the “this was one metadata block with N entries” structure does not survive.
* **Orphaned captions.** If a caption’s target element didn’t end up rendering — for example a table with no cells or no columns, which the renderer drops silently — the caption doesn’t vanish with it. It falls back to rendering as a plain `` element instead of a nested ``. This avoids silently losing caption text, but the caption-to-table relationship is lost.
* **Page dimensions**, as noted above, are never recoverable from a parsed stream; only the 0–500 grid is preserved.
Everything else — element ordering, list nesting (ordered/unordered), tables without spanning cells, code language tokens, formulas, footnote text, page header/footer classification — round-trips exactly: parsing xberg’s own DocTags output and re-rendering it reproduces the identical stream.
## See Also
[Section titled “See Also”](#see-also)
* [Output Formats](/guides/output-formats/) — other content formats (`Plain`, `Markdown`, `Djot`, `Html`, `Json`)
* [Document Structure](/guides/output-formats/#document-structure) — xberg’s own hierarchical tree representation
* [Configuration Reference](/reference/configuration/) — full `ExtractionConfig` field list
# Document Splitting
> Split a multi-document PDF into logical sub-documents and extract each from a single parse, using caller-supplied page ranges or heuristic boundary detection.
A single PDF often concatenates several logical documents — a scanned batch of invoices, a bundle of letters, a stack of forms. Use `split_and_extract` to detect sub-document boundaries and return one `ExtractedDocument` per segment from a **single parse**. You do not slice the PDF externally and re-parse each slice; the whole file is parsed once and partitioned by page attribution.
Core-Rust only
`split_and_extract` is not part of the language-binding surface. It is excluded from the generated bindings (`split_and_extract` is listed in `alef.toml`), so it is available from Rust only. It also requires the `pdf` feature.
## When to Use It
[Section titled “When to Use It”](#when-to-use-it)
Reach for splitting when one input file holds multiple independent documents that you want to process, store, or route separately, and you want to avoid parsing the PDF once per boundary. The single-parse guarantee matters when parsing is expensive (OCR, layout detection). Page, table, and image attribution is preserved in the original page coordinate system, so each segment reports its own counts and page numbers.
PDF is the only supported format today — it is the only page-addressable one. Any other MIME type returns `XbergError::UnsupportedFormat`.
## Strategies
[Section titled “Strategies”](#strategies)
`SplitStrategy` selects how the document is partitioned.
```rust
pub enum SplitStrategy {
/// Heuristic boundary detection. Requires the `heuristics` feature.
Auto,
/// Caller-supplied 1-indexed, inclusive page ranges.
PageRanges(Vec>),
}
```
* **`PageRanges`** — Deterministic. Supply 1-indexed inclusive page ranges when you already know the boundaries. Ranges are validated: each must satisfy `1 <= start <= end <= total_pages`, and the list must be non-empty. An out-of-bounds or reversed range returns `XbergError::Validation`.
* **`Auto`** (default) — Heuristic boundary detection via page-one markers, letterhead resets, and text-density shifts. Requires the `heuristics` feature; without it, `Auto` returns a `Validation` error directing you to `PageRanges`. A cohesive document with no boundary signals yields a single segment spanning all pages.
## Configuration
[Section titled “Configuration”](#configuration)
```rust
pub struct SplitConfig {
/// Boundary-detection strategy.
pub strategy: SplitStrategy,
/// Extraction config applied to every segment.
pub extraction: ExtractionConfig,
}
```
`SplitConfig::default()` uses `SplitStrategy::Auto` and a default `ExtractionConfig`. Construct with struct-update syntax to override the strategy. Per-page content extraction is forced on internally regardless of what `extraction` specifies — that is how segments are partitioned without a re-parse.
## Returned Segments
[Section titled “Returned Segments”](#returned-segments)
Each detected segment is a `SplitSegment`:
```rust
pub struct SplitSegment {
/// 1-indexed inclusive page range in the original document.
pub page_range: RangeInclusive,
/// The sub-document extracted from `page_range`.
pub document: ExtractedDocument,
}
```
The `document` is a normal `ExtractedDocument` scoped to its pages:
* `content` is reassembled from the segment’s pages (blank pages skipped), not copied from the whole document.
* `tables`, `images`, and `pages` are filtered to those falling in `page_range`, with original page numbers preserved.
* `counts` (`DocumentCounts { pages, tables, images }`) and `metadata.pages.total_count` are recomputed for the segment.
## Example
[Section titled “Example”](#example)
```rust
use std::ops::RangeInclusive;
use xberg::{split_and_extract, SplitConfig, SplitStrategy, ExtractionConfig};
# async fn run(bytes: &[u8]) -> xberg::Result<()> {
// Deterministic: three known sub-documents in a 5-page batch.
let config = SplitConfig {
strategy: SplitStrategy::PageRanges(vec![1..=2, 3..=3, 4..=5]),
extraction: ExtractionConfig::default(),
};
let segments = split_and_extract(bytes, &config).await?;
for segment in &segments {
let range: &RangeInclusive = &segment.page_range;
let counts = &segment.document.counts;
println!(
"pages {}..={}: {} pages, {} tables, {} images",
range.start(),
range.end(),
counts.pages,
counts.tables,
counts.images,
);
// segment.document.content holds the reassembled text for this sub-document.
}
# Ok(())
# }
```
For heuristic splitting, take the default strategy (requires the `heuristics` feature):
```rust
# use xberg::{split_and_extract, SplitConfig};
# async fn run(bytes: &[u8]) -> xberg::Result<()> {
let segments = split_and_extract(bytes, &SplitConfig::default()).await?;
# let _ = segments;
# Ok(())
# }
```
## Errors
[Section titled “Errors”](#errors)
* `XbergError::UnsupportedFormat` — input is not a PDF.
* `XbergError::Validation` — empty document, invalid or reversed page range, an empty `PageRanges` list, or `Auto` requested without the `heuristics` feature.
* Any error propagated from the underlying single-document extraction.
## See also
[Section titled “See also”](#see-also)
* [Rust Core API](/guides/rust-core-api/) — the wider Rust-only surface, including `ExtractedDocument` fields
* [Extraction Basics](/guides/extraction/) — the two-function extraction API mirrored by the bindings
# Embeddings
Turn extracted text into vectors for semantic search and RAG, using local ONNX models or a registered backend — no external API calls. Enable the `embeddings` feature to use in-process embedding backends.
| Preset | Model | Dimensions | Chunk Size (chars) | Use Case |
| -------------- | ---------------------------- | ---------- | ------------------ | ------------------------------------------------------- |
| `fast` | all-MiniLM-L6-v2 (quantized) | 384 | 512 | Quick prototyping, development, resource-constrained |
| `balanced` | BGE-base-en-v1.5 | 768 | 1024 | General-purpose RAG, production deployments, English |
| `quality` | BGE-large-en-v1.5 | 1024 | 2000 | Complex documents, maximum accuracy, sufficient compute |
| `multilingual` | multilingual-e5-base | 768 | 1024 | International documents, mixed-language content |
The chunk-size column is the preset’s target chunk size in characters (its `chunk_size`), not a token limit.
## Model Types
[Section titled “Model Types”](#model-types)
Select the embedding source via the `model` field of `EmbeddingConfig`. `EmbeddingModelType` has four variants, tagged by `type`:
* `preset` — a bundled ONNX model configuration by `name` (see the preset table above). Recommended default.
* `custom` — any ONNX embedding model from HuggingFace, given its `model_id` and output `dimensions`.
* `llm` — a provider-hosted embedding model through liter-llm, configured by a nested `llm` (`LlmConfig`), e.g. `openai/text-embedding-3-small`.
* `plugin` — an in-process backend registered by `name` via the plugin system (see below).
## In-Process Embedding Backends (Plugin Variant)
[Section titled “In-Process Embedding Backends (Plugin Variant)”](#in-process-embedding-backends-plugin-variant)
Plug a caller-managed embedder (e.g. `llama-cpp-python`, `sentence-transformers`) into Xberg via the `Plugin` variant of `EmbeddingModelType` — Xberg calls back into the registered backend instead of running its own ONNX model.
1. Register the backend once at startup via `xberg::plugins::register_embedding_backend(Arc::new(MyEmbedder))`. The backend implements `EmbeddingBackend` (a `Plugin`-inheriting async trait with `dimensions()` and `embed(texts) -> Vec>`).
2. Reference it by name in `EmbeddingConfig`: `{ "model": { "type": "plugin", "name": "my-embedder" } }`.
3. Optional: set `EmbeddingConfig.max_embed_duration_secs` (default 60) to bound the wait on a hung backend; `None` disables the timeout.
Rust extraction configuration and `XBERG_EMBEDDING_PLUGIN_NAME` accept the Plugin variant once a backend is registered.
**Fork-safety**: Python callers running under `multiprocessing`, `gunicorn`’s prefork worker, or Celery prefork must re-register the backend in each child process — native-backed embedders (including `llama-cpp-python`) aren’t fork-safe. Use `os.register_at_fork(after_in_child=reregister_fn)` to automate the re-registration.
## Configuration
[Section titled “Configuration”](#configuration)
* Python
Python
```python
from xberg import (
ExtractionConfig,
ChunkingConfig,
EmbeddingConfig,
EmbeddingModelType,
)
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
max_characters=1024,
overlap=100,
embedding=EmbeddingConfig(
model=EmbeddingModelType.preset("balanced"),
normalize=True,
batch_size=32,
show_download_progress=False,
),
)
)
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
chunking: {
maxCharacters: 1024,
overlap: 100,
embedding: {
model: { type: "preset", name: "balanced" },
},
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
console.log(`Chunks: ${output.results?.[0]?.chunks?.length ?? 0}`);
```
* Rust
Rust
```rust
use xberg::{ExtractionConfig, ChunkingConfig, EmbeddingConfig, EmbeddingModelType};
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
max_characters: 1024,
overlap: 100,
embedding: Some(EmbeddingConfig {
model: EmbeddingModelType::Preset { name: "balanced".to_string() },
normalize: true,
batch_size: 32,
show_download_progress: false,
..Default::default()
}),
..Default::default()
}),
..Default::default()
};
```
* Go
Go
```go
package main
import (
"fmt"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
maxChars := uint(512)
overlap := uint(50)
normalize := true
batchSize := uint(32)
showProgress := false
cfg := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
Embedding: &xberg.EmbeddingConfig{
Model: xberg.EmbeddingModelTypePreset{Name: "balanced"},
Normalize: &normalize,
BatchSize: &batchSize,
ShowDownloadProgress: showProgress,
},
},
}
input := xberg.ExtractInputFromURI("document.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
fmt.Printf("Error: %v\n", err)
return
}
for index, chunk := range result.Results[0].Chunks {
chunkID := fmt.Sprintf("doc_chunk_%d", index)
content := chunk.Content
if len(content) > 50 {
content = content[:50]
}
fmt.Printf("Chunk %s: %s\n", chunkID, content)
if chunk.Embedding != nil && len(chunk.Embedding) > 0 {
fmt.Printf(" Embedding dimensions: %d\n", len(chunk.Embedding))
}
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInput;
import io.xberg.ChunkingConfig;
import io.xberg.Chunk;
import io.xberg.EmbeddingConfig;
import io.xberg.EmbeddingModelType;
import java.util.List;
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withMaxCharacters(512L)
.withOverlap(50L)
.withEmbedding(EmbeddingConfig.builder()
.withModel(new EmbeddingModelType.Preset("balanced"))
.withNormalize(true)
.withBatchSize(32L)
.withShowDownloadProgress(false)
.build())
.build())
.build();
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("document.pdf").build(),
config
);
ExtractedDocument result = output.results().get(0);
List chunks = result.chunks() != null ? result.chunks() : List.of();
for (int index = 0; index < chunks.size(); index++) {
Chunk chunk = chunks.get(index);
String chunkId = "doc_chunk_" + index;
System.out.println("Chunk " + chunkId + ": " + chunk.content().substring(0, Math.min(50, chunk.content().length())));
List embedding = chunk.embedding();
if (embedding != null) {
System.out.println(" Embedding dimensions: " + embedding.size());
}
}
```
* C#
C#
```csharp
using Xberg;
using System;
using System.Collections.Generic;
using System.Threading.Tasks;
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 512,
Overlap = 50,
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("balanced"),
Normalize = true,
BatchSize = 32,
ShowDownloadProgress = false
}
}
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
var chunks = result.Chunks ?? new List();
foreach (var (index, chunk) in chunks.WithIndex())
{
var chunkId = $"doc_chunk_{index}";
Console.WriteLine($"Chunk {chunkId}: {chunk.Content[..Math.Min(50, chunk.Content.Length)]}");
if (chunk.Embedding != null)
{
Console.WriteLine($" Embedding dimensions: {chunk.Embedding.Count}");
}
}
internal static class EnumerableExtensions
{
public static IEnumerable<(int Index, T Item)> WithIndex(
this IEnumerable items)
{
var index = 0;
foreach (var item in items)
{
yield return (index++, item);
}
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
max_characters: 512,
overlap: 50,
embedding: Xberg::EmbeddingConfig.new(
model: Xberg::EmbeddingModelType.new(
type: 'preset',
name: 'balanced'
),
normalize: true,
batch_size: 32,
show_download_progress: false
)
)
)
input = Xberg::ExtractInput.new(uri: 'document.pdf')
result = Xberg.extract(input, config)
chunks = result.results.first.chunks || []
chunks.each_with_index do |chunk, idx|
chunk_id = "doc_chunk_#{idx}"
puts "Chunk #{chunk_id}: #{chunk.content[0...50]}"
if chunk.embedding
puts " Embedding dimensions: #{chunk.embedding.length}"
end
end
```
## Standalone Embedding
[Section titled “Standalone Embedding”](#standalone-embedding)
Call `embed_texts` (or `embed_texts_async`) to embed a list of strings directly with an `EmbeddingConfig`, bypassing extraction and chunking. Each input string maps to one output vector.
This entry point is Rust-only. The language bindings expose no standalone “embed arbitrary text” call — in Python, TypeScript, Go, Java, C#, and Ruby, embeddings are produced during extraction and attached per chunk via `ExtractionConfig.chunking.embedding` (see [Configuration](#configuration) above).
* Rust
Rust
```rust
use xberg::{EmbeddingConfig, EmbeddingModelType, embed_texts};
fn main() -> xberg::Result<()> {
let config = EmbeddingConfig {
model: EmbeddingModelType::Preset { name: "balanced".to_string() },
normalize: true,
..Default::default()
};
let texts = vec!["Hello, world!".to_string(), "Xberg is fast".to_string()];
let embeddings = embed_texts(texts, &config)?;
assert_eq!(embeddings.len(), 2);
assert_eq!(embeddings[0].len(), 768);
Ok(())
}
```
* C#
C#
```csharp
using Xberg;
using System;
using System.Linq;
// NOTE: The C# binding has no standalone "embed arbitrary text" client —
// there is no public EmbedSync/EmbedAsync entry point. Embeddings are only
// produced as part of extraction, attached per chunk, via
// ExtractionConfig.Chunking.Embedding.
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("balanced"),
Normalize = true
}
}
};
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
var chunksWithEmbeddings = result.Chunks?.Where(c => c.Embedding != null).ToList() ?? new();
Console.WriteLine(chunksWithEmbeddings.Count);
Console.WriteLine(chunksWithEmbeddings.FirstOrDefault()?.Embedding?.Count);
```
## Vector Database Integration
[Section titled “Vector Database Integration”](#vector-database-integration)
* Python
Python
```python
import asyncio
from xberg import (
ExtractInput,
extract,
ExtractionConfig,
ChunkingConfig,
EmbeddingConfig,
EmbeddingModelType,
)
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
chunking=ChunkingConfig(
max_characters=512,
overlap=50,
embedding=EmbeddingConfig(
model=EmbeddingModelType.preset("balanced"), normalize=True
),
)
)
result = await extract(ExtractInput(uri="document.pdf"), config)
chunks = result.results[0].chunks or []
for i, chunk in enumerate(chunks):
chunk_id: str = f"doc_chunk_{i}"
print(f"Chunk {chunk_id}: {chunk.content[:50]}")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract, type ExtractionConfig } from "@xberg-io/xberg";
const config: ExtractionConfig = {
chunking: {
maxCharacters: 512,
overlap: 50,
embedding: {
model: { type: "preset", name: "balanced" },
},
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
const [result] = output.results ?? [];
if (result?.chunks) {
for (const chunk of result.chunks) {
console.log(`Chunk: ${chunk.content.slice(0, 100)}...`);
if (chunk.embedding) {
console.log(`Embedding dims: ${chunk.embedding.length}`);
}
}
}
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, ChunkingConfig, EmbeddingConfig};
struct VectorRecord {
id: String,
content: String,
embedding: Vec,
metadata: std::collections::HashMap,
}
async fn extract_and_vectorize(
document_path: &str,
document_id: &str,
) -> Result, Box> {
let config = ExtractionConfig {
chunking: Some(ChunkingConfig {
max_characters: 512,
overlap: 50,
embedding: Some(EmbeddingConfig {
model: xberg::EmbeddingModelType::Preset {
name: "balanced".to_string(),
},
normalize: true,
batch_size: 32,
..Default::default()
}),
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri(document_path), &config).await?;
let result = &output.results[0];
let mut records = Vec::new();
if let Some(chunks) = &result.chunks {
for (index, chunk) in chunks.iter().enumerate() {
if let Some(embedding) = &chunk.embedding {
let mut metadata = std::collections::HashMap::new();
metadata.insert("document_id".to_string(), document_id.to_string());
metadata.insert("chunk_index".to_string(), index.to_string());
metadata.insert("content_length".to_string(), chunk.content.len().to_string());
records.push(VectorRecord {
id: format!("{}_chunk_{}", document_id, index),
content: chunk.content.clone(),
embedding: embedding.clone(),
metadata,
});
}
}
}
Ok(records)
}
```
* Go
Go
```go
package main
import (
"fmt"
"github.com/xberg-io/xberg/packages/go"
)
type VectorRecord struct {
ID string
Embedding []float32
Content string
Metadata map[string]string
}
func extractAndVectorize(documentPath string, documentID string) ([]VectorRecord, error) {
maxChars := uint(512)
overlap := uint(50)
normalize := true
batchSize := uint(32)
cfg := xberg.ExtractionConfig{
Chunking: &xberg.ChunkingConfig{
MaxCharacters: &maxChars,
Overlap: &overlap,
Embedding: &xberg.EmbeddingConfig{
Model: xberg.EmbeddingModelTypePreset{Name: "balanced"},
Normalize: &normalize,
BatchSize: &batchSize,
},
},
}
input := xberg.ExtractInputFromURI(documentPath)
result, err := xberg.Extract(*input, cfg)
if err != nil {
return nil, err
}
var vectorRecords []VectorRecord
for index, chunk := range result.Results[0].Chunks {
record := VectorRecord{
ID: fmt.Sprintf("%s_chunk_%d", documentID, index),
Content: chunk.Content,
Embedding: chunk.Embedding,
Metadata: map[string]string{
"document_id": documentID,
"chunk_index": fmt.Sprintf("%d", index),
"content_length": fmt.Sprintf("%d", len(chunk.Content)),
},
}
vectorRecords = append(vectorRecords, record)
}
storeInVectorDatabase(vectorRecords)
return vectorRecords, nil
}
func storeInVectorDatabase(records []VectorRecord) {
for _, record := range records {
if len(record.Embedding) > 0 {
fmt.Printf("Storing %s: %d chars, %d dims\n",
record.ID, len(record.Content), len(record.Embedding))
}
}
}
func main() {
if _, err := extractAndVectorize("document.pdf", "document-1"); err != nil {
fmt.Printf("Extraction failed: %v\n", err)
}
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractInput;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ChunkingConfig;
import io.xberg.Chunk;
import io.xberg.EmbeddingConfig;
import io.xberg.EmbeddingModelType;
import java.util.HashMap;
import java.util.List;
import java.util.Map;
public class VectorDatabaseIntegration {
public static class VectorRecord {
public String id;
public float[] embedding;
public String content;
public Map metadata;
}
public static List extractAndVectorize(String documentPath, String documentId) throws Exception {
ExtractionConfig config = ExtractionConfig.builder()
.withChunking(ChunkingConfig.builder()
.withMaxCharacters(512L)
.withOverlap(50L)
.withEmbedding(EmbeddingConfig.builder()
.withModel(new EmbeddingModelType.Preset("balanced"))
.withNormalize(true)
.withBatchSize(32L)
.build())
.build())
.build();
ExtractionResult output = Xberg.extract(ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri(documentPath).build(), config);
ExtractedDocument result = output.results().get(0);
List chunks = result.chunks() != null ? result.chunks() : List.of();
List vectorRecords = new java.util.ArrayList<>();
for (int index = 0; index < chunks.size(); index++) {
Chunk chunk = chunks.get(index);
VectorRecord record = new VectorRecord();
record.id = documentId + "_chunk_" + index;
record.metadata = new HashMap<>();
record.metadata.put("document_id", documentId);
record.metadata.put("chunk_index", String.valueOf(index));
record.content = chunk.content();
if (chunk.embedding() != null) {
List embedding = chunk.embedding();
record.embedding = new float[embedding.size()];
for (int i = 0; i < embedding.size(); i++) {
record.embedding[i] = embedding.get(i);
}
}
record.metadata.put("content_length", String.valueOf(record.content.length()));
vectorRecords.add(record);
}
storeInVectorDatabase(vectorRecords);
return vectorRecords;
}
private static void storeInVectorDatabase(List records) {
for (VectorRecord record : records) {
if (record.embedding != null && record.embedding.length > 0) {
System.out.println("Storing " + record.id + ": " + record.content.length()
+ " chars, " + record.embedding.length + " dims");
}
}
}
}
```
* C#
C#
```csharp
using Xberg;
using System;
using System.Collections.Generic;
using System.Linq;
using System.Threading.Tasks;
var integration = new VectorDatabaseIntegration();
var records = await integration.ExtractAndVectorize("research_paper.pdf", "doc-1");
Console.WriteLine($"Vectorized {records.Count} chunks");
public class VectorDatabaseIntegration
{
public class VectorRecord
{
public string Id { get; set; } = string.Empty;
public float[] Embedding { get; set; } = Array.Empty();
public string Content { get; set; } = string.Empty;
public Dictionary Metadata { get; set; } = new();
}
public async Task> ExtractAndVectorize(
string documentPath,
string documentId)
{
var config = new ExtractionConfig
{
Chunking = new ChunkingConfig
{
MaxCharacters = 512,
Overlap = 50,
Embedding = new EmbeddingConfig
{
Model = new EmbeddingModelType.Preset("balanced"),
Normalize = true,
BatchSize = 32
}
}
};
var result = await XbergConverter.ExtractAsync(ExtractInput.FromUri(documentPath), config);
var chunks = result.Results[0].Chunks ?? new List();
var vectorRecords = chunks
.Select((chunk, index) => new VectorRecord
{
Id = $"{documentId}_chunk_{index}",
Content = chunk.Content,
Embedding = chunk.Embedding?.ToArray() ?? Array.Empty(),
Metadata = new Dictionary
{
{ "document_id", documentId },
{ "chunk_index", index.ToString() },
{ "content_length", chunk.Content.Length.ToString() }
}
})
.ToList();
await StoreInVectorDatabase(vectorRecords);
return vectorRecords;
}
private async Task StoreInVectorDatabase(List records)
{
foreach (var record in records)
{
if (record.Embedding != null && record.Embedding.Length > 0)
{
Console.WriteLine(
$"Storing {record.Id}: {record.Content.Length} chars, " +
$"{record.Embedding.Length} dims");
}
}
await Task.CompletedTask;
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
class VectorDatabaseIntegration
VectorRecord = Struct.new(:id, :embedding, :content, :metadata, keyword_init: true)
def extract_and_vectorize(document_path, document_id)
config = Xberg::ExtractionConfig.new(
chunking: Xberg::ChunkingConfig.new(
max_characters: 512,
overlap: 50,
embedding: Xberg::EmbeddingConfig.new(
model: Xberg::EmbeddingModelType.new(
type: 'preset',
name: 'balanced'
),
normalize: true,
batch_size: 32
)
)
)
output = Xberg.extract(Xberg::ExtractInput.new(kind: "uri", uri: document_path), config)
result = output.results.first
chunks = result.chunks || []
vector_records = chunks.map.with_index do |chunk, idx|
VectorRecord.new(
id: "#{document_id}_chunk_#{idx}",
content: chunk.content,
embedding: chunk.embedding,
metadata: {
document_id: document_id,
chunk_index: idx,
content_length: chunk.content.length
}
)
end
store_in_vector_database(vector_records)
vector_records
end
private
def store_in_vector_database(records)
records.each do |record|
if record.embedding&.any?
puts "Storing #{record.id}: #{record.content.length} chars, #{record.embedding.length} dims"
end
end
end
end
```
## See also
[Section titled “See also”](#see-also)
* [Chunking](/guides/chunking/) — split documents before embedding for RAG
* [Retrieval](/guides/retrieval/) — combine dense embeddings with sparse and full-text arms
* [Retrieval Modes](/concepts/retrieval/) — when to reach for dense, sparse, late-interaction or reranking
* [Configuration Reference](/reference/configuration/#embeddingconfig) — all embedding options
* [LLM Integration](/guides/llm-integration/) — use embeddings with LLMs
# Extraction Basics
Extract text, metadata, and structure from 107 file formats — PDFs, Office documents, images, email, HTML, archives, and more. Single files or batches, from local paths or in-memory bytes, with per-document configuration overrides and built-in content filtering.
See the [Configuration Reference](/reference/configuration/) for all extraction settings and the [Supported Formats](/reference/formats/) reference for format-specific options.
## Entry Points
[Section titled “Entry Points”](#entry-points)
Two extraction functions are the public entry points:
| Function | Input model | Purpose |
| --------------- | ---------------- | ----------------------------------------- |
| `extract` | `ExtractInput` | Extract one URI or in-memory byte payload |
| `extract_batch` | `ExtractInput[]` | Extract multiple URI and byte inputs |
`ExtractInput` uses `kind = "uri"` for local paths, `file://` URIs, and HTTP(S) URLs. Use `kind = "bytes"` for in-memory payloads. `extract` and `extract_batch` return an `ExtractionResult` envelope with `results`, `errors`, `summary`, and optional crawl metadata.
Beyond local paths and bytes, HTTP(S) URIs are fetched and can be crawled — see [`UrlExtractionConfig`](/reference/configuration/#urlextractionconfig) and [`CrawlConfig`](/reference/configuration/#crawlconfig). Embedded images and their preprocessing are controlled by [`ImageExtractionConfig`](/reference/configuration/#imageextractionconfig).
## Extract One Input
[Section titled “Extract One Input”](#extract-one-input)
* Python
extract\_one.py
```python
from xberg import ExtractInput, extract
output = await extract(ExtractInput(kind="uri", uri="document.pdf"))
print(output.results[0].content)
```
* TypeScript
extract-one.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
});
console.log(output.results[0].content);
```
* Rust
extract\_one.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
let config = ExtractionConfig::default();
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
println!("{}", output.results[0].content);
```
### Read the Result
[Section titled “Read the Result”](#read-the-result)
Every entry in `results` carries the text plus the structures found in the document. Read the content, the tables, and the format metadata from the same document:
* Python
Tests URI extraction API
Python
```python
import asyncio
from xberg import extract, ExtractInput
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
result = await extract(input)
print(result.results[0].content)
asyncio.run(main())
```
* TypeScript / Node.js
Tests URI extraction API
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const result = await extract(input);
console.log(result.results?.[0]?.content);
}
void main();
```
* WebAssembly
Tests URI extraction API
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, undefined);
console.log(result.results[0].content);
}
void main();
```
* Rust
Tests URI extraction API
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config = Default::default();
let result = extract(input, &config).await.expect("call failed");
println!("{:?}", result.results[0].content);
}
```
* Go
Tests URI extraction API
Go
```go
package main
import (
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
fmt.Printf("%+v\n", result.Results[0].Content)
}
```
* Java
Tests URI extraction API
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var result = Xberg.extract(input, ExtractionConfig.builder().build());
System.out.println(result.results().get(0).content());
}
}
```
* Kotlin (Android)
Tests URI extraction API
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val configDefault = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, configDefault)
println(result.results.first().content)
}
```
* C#
Tests URI extraction API
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig());
Console.WriteLine(result.Results[0].Content);
```
* Swift
Tests URI extraction API
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}")
debugPrint(result.results()[0].content())
```
* Ruby
Tests URI extraction API
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'))
puts result.results[0].content.inspect
```
* PHP
Tests URI extraction API
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, null);
var_dump($result->getResults()[0]->content);
```
* Elixir
Tests URI extraction API
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value)
IO.inspect(Enum.at(result.results, 0).content)
```
* Dart
Tests URI extraction API
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result.results[0].content);
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests URI extraction API
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests URI extraction API
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle result = xberg_extract(input_handle, 0);
xberg_extract_input_free(input_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
## Extract from Bytes
[Section titled “Extract from Bytes”](#extract-from-bytes)
When content is already loaded in memory, pass bytes through `ExtractInput` with an explicit MIME type.
* Python
extract\_from\_bytes.py
```python
from xberg import ExtractInput, extract
with open("document.pdf", "rb") as file:
data = file.read()
output = await extract(
ExtractInput(
kind="bytes",
bytes=data,
mime_type="application/pdf",
filename="document.pdf",
)
)
```
* TypeScript
extract-bytes.ts
```typescript
import { readFile } from "node:fs/promises";
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const data = await readFile("document.pdf");
const output = await extract({
kind: ExtractInputKind.Bytes,
bytes: data,
mimeType: "application/pdf",
filename: "document.pdf",
});
```
* Rust
extract\_from\_bytes.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig};
let data = std::fs::read("document.pdf")?;
let config = ExtractionConfig::default();
let output = extract(
ExtractInput::from_bytes(data, "application/pdf", Some("document.pdf".to_string())),
&config,
)
.await?;
```
### Browser File Input
[Section titled “Browser File Input”](#browser-file-input)
The Wasm package has no filesystem access, so a browser upload always goes through bytes. Read the `File` from the input element and pass its bytes and MIME type:
Wasm
```typescript
import init, { WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function setupFileInput() {
await init();
const fileInput = document.getElementById("file-input") as HTMLInputElement;
fileInput.addEventListener("change", async (event) => {
const file = (event.target as HTMLInputElement).files?.[0];
if (!file) return;
try {
const bytes = new Uint8Array(await file.arrayBuffer());
const output = await extract({
kind: "bytes",
bytes,
mimeType: file.type || "application/octet-stream",
filename: file.name,
}, undefined);
console.log("Extracted text:", output.results[0].content);
displayResults(output.results[0]);
} catch (error) {
console.error("Extraction failed:", error);
}
});
}
function displayResults(result: any) {
const output = document.getElementById("output");
if (output) {
output.textContent = `${result.content?.substring(0, 500) ?? ""}...`;
}
}
setupFileInput().catch(console.error);
```
## Batch Processing
[Section titled “Batch Processing”](#batch-processing)
`extract_batch` accepts a list of `ExtractInput` values. Mix URI and byte inputs in one request when a pipeline receives documents from multiple sources.
* Python
extract\_batch over URI inputs
Python
```python
import asyncio
from xberg import extract_batch
async def main() -> None:
inputs = [{"kind": "uri", "uri": "https://example.com/pdf/fake_memo.pdf"}, {"kind": "uri", "uri": "https://example.com/text/fake_text.txt"}]
result = await extract_batch(inputs)
for result in result.results:
print(result.content)
asyncio.run(main())
```
* TypeScript / Node.js
extract\_batch over URI inputs
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, extractBatch } from "@xberg-io/xberg";
async function main() {
const result = await extractBatch([{ kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" } as ExtractInput, { kind: ExtractInputKind.Uri, uri: "https://example.com/text/fake_text.txt" } as ExtractInput]);
for (const item of result.results ?? []) {
console.log(item.content);
}
}
void main();
```
* WebAssembly
extract\_batch over URI inputs
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extractBatch } from "@xberg-io/xberg-wasm";
async function main() {
const result = await extractBatch([(() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })(), (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/text/fake_text.txt"; return _u0; })()], undefined);
for (const item of result.results) {
console.log(item.content);
}
}
void main();
```
* Rust
extract\_batch over URI inputs
Rust
```rust
use xberg::extract_batch;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let inputs_json: serde_json::Value = serde_json::from_str(r#"[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]"#).unwrap();
let inputs = serde_json::from_value::>(inputs_json).unwrap();
let config = Default::default();
let result = extract_batch(inputs, &config).await.expect("call failed");
for result in result.results.iter() {
println!("{}", result.content);
}
}
```
* Go
extract\_batch over URI inputs
Go
```go
package main
import (
"encoding/json"
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func main() {
var inputs []xberg.ExtractInput
if err := json.Unmarshal([]byte(`[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]`), &inputs); err != nil {
panic(fmt.Sprintf("config parse failed: %v", err))
}
config := xberg.ExtractionConfig{}
result, err := xberg.ExtractBatch(inputs, config)
if err != nil {
panic(err)
}
for _, result := range result.Results {
fmt.Printf("%v\n", result.Content)
}
}
```
* Java
extract\_batch over URI inputs
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var result = Xberg.extractBatch(java.util.Arrays.asList(JsonUtil.fromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput.class), JsonUtil.fromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ExtractInput.class)), ExtractionConfig.builder().build());
for (var item : result.results()) {
System.out.println(item.content());
}
}
}
```
* Kotlin (Android)
extract\_batch over URI inputs
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val configDefault = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extractBatch(listOf(mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java), mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ExtractInput::class.java)), configDefault)
for (result in result.results) {
println(result.content)
}
}
```
* C#
extract\_batch over URI inputs
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractBatchAsync(new List() { JsonSerializer.Deserialize("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ConfigOptions)!, JsonSerializer.Deserialize("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}", ConfigOptions)! }, new ExtractionConfig());
foreach (var resultItem in result.Results)
{
Console.WriteLine(resultItem.Content);
}
```
* Swift
extract\_batch over URI inputs
Swift
```swift
import Xberg
let _item_inputsArray_0 = try Xberg.extractInputFromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
let _item_inputsArray_1 = try Xberg.extractInputFromJson("{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}")
let inputsArray = [_item_inputsArray_0, _item_inputsArray_1]
let configObj = try Xberg.extractionConfigFromJson("{}")
let result = try await Xberg.extractBatch(inputs: inputsArray, config: configObj)
for result in result.results() {
print(result.content())
}
```
* Ruby
extract\_batch over URI inputs
Ruby
```ruby
require "xberg"
result = Xberg.extract_batch([{ 'kind' => 'uri', 'uri' => 'https://example.com/pdf/fake_memo.pdf' }, { 'kind' => 'uri', 'uri' => 'https://example.com/text/fake_text.txt' }])
result.results.each do |result|
puts result.content
end
```
* PHP
extract\_batch over URI inputs
PHP
```php
getResults() as $result) {
echo $result->getContent(), PHP_EOL;
}
```
* Elixir
extract\_batch over URI inputs
Elixir
```elixir
result = Xberg.extract_batch_async([%{"kind" => "uri", "uri" => "https://example.com/pdf/fake_memo.pdf"}, %{"kind" => "uri", "uri" => "https://example.com/text/fake_text.txt"}])
Enum.each(result.results, fn result ->
IO.puts(result.content)
end)
```
* Dart
extract\_batch over URI inputs
Dart
```dart
import 'dart:convert';
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final inputs = await Future.wait((jsonDecode(r'[{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"},{"kind":"uri","uri":"https://example.com/text/fake_text.txt"}]') as List).map((element) => createExtractInputFromJson(json: jsonEncode(element))));
final result = await XbergBridge.extractBatch(inputs);
for (final result in result.results) {
stdout.writeln(result.content);
}
} finally {
RustLib.dispose();
}
}
```
* Zig
extract\_batch over URI inputs
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract_batch("[{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"},{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}]", "{}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
extract\_batch over URI inputs
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle result = xberg_extract_batch("[{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"},{\"kind\":\"uri\",\"uri\":\"https://example.com/text/fake_text.txt\"}]", 0);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
### Per-Input Configuration
[Section titled “Per-Input Configuration”](#per-input-configuration)
When a batch contains a mix of document types that need different settings, attach per-input overrides to `ExtractInput` while sharing a common batch config.
* Python
mixed\_batch.py
```python
from xberg import (
ExtractionConfig,
ExtractInput,
FileExtractionConfig,
extract_batch,
)
config = ExtractionConfig(output_format="markdown")
inputs = [
ExtractInput(kind="uri", uri="report.pdf"),
ExtractInput(
kind="uri",
uri="scan.tiff",
config=FileExtractionConfig(force_ocr=True),
),
ExtractInput(
kind="uri",
uri="notes.html",
config=FileExtractionConfig(output_format="plain"),
),
]
output = await extract_batch(inputs, config)
```
* TypeScript
mixed\_batch.ts
```typescript
import { ExtractInputKind, extractBatch } from "@xberg-io/xberg";
const output = await extractBatch(
[
{ kind: ExtractInputKind.Uri, uri: "report.pdf" },
{
kind: ExtractInputKind.Uri,
uri: "scan.tiff",
config: { forceOcr: true },
},
{
kind: ExtractInputKind.Uri,
uri: "notes.html",
config: { outputFormat: "plain" },
},
],
{ outputFormat: "markdown" },
);
```
* Rust
mixed\_batch.rs
```rust
use xberg::{
extract_batch, ExtractInput, ExtractInputKind, ExtractionConfig,
FileExtractionConfig, OutputFormat,
};
let config = ExtractionConfig {
output_format: OutputFormat::Markdown,
..Default::default()
};
let inputs = vec![
ExtractInput::from_uri("report.pdf"),
ExtractInput {
kind: ExtractInputKind::Uri,
uri: Some("scan.tiff".to_string()),
config: Some(FileExtractionConfig {
force_ocr: Some(true),
..Default::default()
}),
..Default::default()
},
ExtractInput {
kind: ExtractInputKind::Uri,
uri: Some("notes.html".to_string()),
config: Some(FileExtractionConfig {
output_format: Some(OutputFormat::Plain),
..Default::default()
}),
..Default::default()
},
];
let output = extract_batch(inputs, &config).await?;
```
Fields set to `None` in `FileExtractionConfig` inherit the batch default. Batch-level concerns like `max_concurrent_extractions`, `use_cache`, and `security_limits` cannot be overridden per input. See the [Configuration Reference](/reference/configuration/#fileextractionconfig) for the full list of overridable fields.
## Archive and XML Bomb Protections
[Section titled “Archive and XML Bomb Protections”](#archive-and-xml-bomb-protections)
Every archive-bearing format (`.zip`, `.docx`, `.pptx`, `.xlsx`, `.odt`, `.ods`, `.odp`, `.epub`, `.hwpx`, and the iWork formats `.pages`/`.key`/`.numbers`) and every XML-bearing format is checked against `SecurityLimits` before or during parsing. These checks exist to stop a hostile input from exhausting memory or CPU rather than to validate document correctness — a legitimate large document should never come close to the defaults below.
| Limit | Defends against | Default |
| ----------------------- | --------------------------------------------------------------------------------------------------------------------- | ------------ |
| `max_archive_size` | ZIP bombs — declared uncompressed size accumulated across entries | 500 MiB |
| `max_compression_ratio` | ZIP bombs — a single entry or the archive total expanding beyond a sane ratio | 100:1 |
| `max_files_in_archive` | Archives with an unreasonable number of member files | 10,000 |
| `max_nesting_depth` | Deeply nested containers (nested archives, iWork protobuf messages) | 1,024 levels |
| `max_xml_depth` | Deeply nested XML elements | 1,024 levels |
| `max_entity_length` | Billion-laughs-class attacks — a single XML entity/attribute/token expanding to hundreds of MB | 1 MiB |
| `max_content_size` | Aggregate text growth across a whole document (catches long-tail expansion that `max_entity_length` alone would miss) | 100 MB |
| `max_iterations` | Infinite or near-infinite parser loops (XML token loop, HTML tokenizer, JSON parser) | 10,000,000 |
| `max_table_cells` | Documents claiming an unreasonable aggregate number of table cells (CSV, XLSX, HTML tables) | 100,000 |
| `max_pages` | Excessive per-page OCR, layout, and rendering work | Unlimited |
When both `max_nesting_depth` and `max_xml_depth` apply to the same parse, the tighter of the two wins — lowering either one alone is enough to clamp nesting.
Archive-specific checks (`max_archive_size`, `max_compression_ratio`, `max_files_in_archive`) are enforced by `ZipBombValidator` against the ZIP central directory before any entry is decompressed, so an oversized or over-compressed archive is rejected without ever running the decompressor.
### Configuring limits
[Section titled “Configuring limits”](#configuring-limits)
`SecurityLimits` is set on `ExtractionConfig.security_limits` and applies to the whole extraction (it cannot be overridden per file in a batch).
* Python
security\_limits.py
```python
from xberg import ExtractInput, ExtractionConfig, SecurityLimits, extract
config = ExtractionConfig(
security_limits=SecurityLimits(
max_archive_size=100 * 1024 * 1024, # 100 MiB
max_files_in_archive=1_000,
max_pages=250,
),
max_embedded_file_bytes=20 * 1024 * 1024,
extraction_timeout_secs=120,
)
output = await extract(ExtractInput(kind="uri", uri="archive.zip"), config=config)
```
* TypeScript
security-limits.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract(
{ kind: ExtractInputKind.Uri, uri: "archive.zip" },
{
securityLimits: {
maxArchiveSize: 100 * 1024 * 1024, // 100 MiB
maxFilesInArchive: 1_000,
maxPages: 250,
},
maxEmbeddedFileBytes: 20 * 1024 * 1024,
extractionTimeoutSecs: 120,
},
);
```
* Rust
security\_limits.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, SecurityLimits};
let config = ExtractionConfig {
security_limits: Some(SecurityLimits {
max_archive_size: 100 * 1024 * 1024, // 100 MiB
max_files_in_archive: 1_000,
max_pages: Some(250),
..Default::default()
}),
max_embedded_file_bytes: Some(20 * 1024 * 1024),
extraction_timeout_secs: Some(120),
..Default::default()
};
let output = extract(ExtractInput::from_uri("archive.zip"), &config).await?;
```
* WebAssembly
security-limits-wasm.js
```javascript
import { ExtractionConfig, SecurityLimits } from "@xberg-io/xberg-wasm";
const config = new ExtractionConfig();
config.securityLimits = new SecurityLimits(
100 * 1024 * 1024, // maxArchiveSize
undefined, // maxCompressionRatio
1_000, // maxFilesInArchive
// ...remaining fields fall back to defaults when undefined
);
```
* C
security\_limits.c
```c
// Build a SecurityLimits handle from JSON and read a field back.
XBERGSecurityLimits *limits = xberg_security_limits_from_json(
"{\"max_archive_size\":104857600,\"max_files_in_archive\":1000}"
);
size_t max_files = xberg_security_limits_max_files_in_archive(limits);
xberg_security_limits_free(limits);
```
Any field left unset falls back to the `SecurityLimits::default()` value shown in the table above.
The `max_table_cells` default is intentionally conservative. For a trusted large CSV, XLSX, or HTML input, raise `security_limits.max_table_cells` to a known workload bound; doing so permits proportionally more parsing work and output allocation. Limit errors report both the observed cell count and the configured value.
`max_pages` is enforced before per-page work for PDF, PPTX, Keynote, ODP, and multi-frame TIFF when OCR is enabled. It is not a universal document-page cap: DOCX, ODT, XLSX, legacy Office files, Pages, Numbers, and TIFF without OCR do not expose a reliable page count before extraction. Keep the byte, archive, embedded-file, and timeout limits enabled even when you set `max_pages`.
**PHP note:** construct `SecurityLimits`, then apply it with `ExtractionConfig::setSecurityLimits()`; the generated constructor does not take `securityLimits` directly.
### What happens when a limit is hit
[Section titled “What happens when a limit is hit”](#what-happens-when-a-limit-is-hit)
All of these checks raise the same error family:
* **Rust** — `XbergError::Security { message, source }`, where `source` is a boxed `SecurityError` (`ZipBombDetected`, `ArchiveTooLarge`, `TooManyFiles`, `NestingTooDeep`, `ContentTooLarge`, `EntityTooLong`, `TooManyIterations`, `XmlDepthExceeded`, `TooManyCells`, or `UnreadableEntry` for an archive entry whose header could not be read at all).
* **Python** — a `xberg.SecurityError` exception (subclass of `xberg.XbergError`).
* **Other bindings** — an error/result whose kind/name is `"Security"` (or the language’s equivalent typed error), carrying the same human-readable message.
The extraction is aborted for that input; it does not silently truncate or return partial content for a security violation the way a format-parsing warning would.
## PDF Reading Order Repair
[Section titled “PDF Reading Order Repair”](#pdf-reading-order-repair)
Native PDF text extraction reads glyphs in the order they were written into the content stream, not the order a human reads the page. For multi-column layouts (academic papers, magazines, dense reports) that order can jump between columns mid-sentence. Xberg can repair this by projecting text spans onto layout-detected regions, grouping them into columns, and re-emitting them top-to-bottom within each column, left-to-right across columns.
This repair is **off by default**. Enable it with `ExtractionConfig.pdf_options.reading_order = true` (`PdfConfig::reading_order` in Rust, default `false`).
* Python
pdf\_reading\_order.py
```python
from xberg import ExtractInput, ExtractionConfig, PdfOptions, extract
config = ExtractionConfig(
pdf_options=PdfOptions(reading_order=True),
)
output = await extract(
ExtractInput(kind="uri", uri="two_column_paper.pdf"),
config=config,
)
```
* TypeScript
pdf-reading-order.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract(
{ kind: ExtractInputKind.Uri, uri: "two_column_paper.pdf" },
{
pdfOptions: {
readingOrder: true,
},
},
);
```
* Rust
pdf\_reading\_order.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, PdfConfig};
let config = ExtractionConfig {
pdf_options: Some(PdfConfig {
reading_order: true,
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("two_column_paper.pdf"), &config).await?;
```
**Requirements:** this option only takes effect when the `layout-detection` feature is compiled in and layout hints were produced for the page (the page must have a layout model pass run over it). Without layout hints, the flag is a no-op and extraction falls back silently to native text order.
**What it fixes:** the flowing body text of multi-column pages — the case where native extraction interleaves column A and column B mid-paragraph.
**What it does not fix:** reading order only reorders text spans, not table cells. A page containing a rotated or scrambled table is unaffected by this option — that class of problem lives in the table extraction path, not the span-reordering pass, and setting `reading_order` will not repair it.
**Cost:** reordering only runs when layout hints are already available, so it adds span-projection and column-detection work on top of an existing layout-detection pass rather than triggering a new one on its own. There is no published benchmark number for the added latency; measure it against your own corpus before enabling it in a latency-sensitive pipeline.
## Content Filtering
[Section titled “Content Filtering”](#content-filtering)
Xberg strips running headers, footers, watermarks, and cross-page repeating text by default so downstream RAG and LLM pipelines see clean body content. `ContentFilterConfig` lets you opt back in when those regions carry useful text.
By default headers, footers, and watermarks are stripped and cross-page repeating text is deduplicated; see [ContentFilterConfig](/reference/configuration/#contentfilterconfig) for field-level defaults and per-format behavior.
* Python
keep\_headers\_footers.py
```python
from xberg import (
ContentFilterConfig,
ExtractionConfig,
ExtractInput,
extract,
)
config = ExtractionConfig(
content_filter=ContentFilterConfig(
include_headers=True,
include_footers=True,
),
)
output = await extract(
ExtractInput(kind="uri", uri="contract.pdf"),
config=config,
)
```
* TypeScript
disable\_repeating\_text.ts
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract(
{ kind: ExtractInputKind.Uri, uri: "brochure.pdf" },
{
contentFilter: {
stripRepeatingText: false,
},
},
);
```
* Rust
content\_filter.rs
```rust
use xberg::{extract, ContentFilterConfig, ExtractInput, ExtractionConfig};
let config = ExtractionConfig {
content_filter: Some(ContentFilterConfig {
include_headers: true,
include_footers: true,
strip_repeating_text: true,
include_watermarks: false,
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("contract.pdf"), &config).await?;
```
When a layout-detection model is active, it can independently classify regions as page headers or footers and strip them per page. Setting `include_headers=True` / `include_footers=True` also disables that per-page stripping. See the [reference page](/reference/configuration/#contentfilterconfig) for the full field semantics and per-format behavior.
## Jupyter Notebook Cells
[Section titled “Jupyter Notebook Cells”](#jupyter-notebook-cells)
Choose whether `.ipynb` extraction includes code-cell source, saved outputs, or both. Xberg never executes notebook cells; output modes expose only data already stored in the notebook. Markdown cells and structural metadata are unaffected.
* Python
```python
from xberg import ExtractionConfig, JupyterCellRendering
config = ExtractionConfig(jupyter_cell_rendering=JupyterCellRendering.SOURCE)
```
* Rust
```rust
use xberg::{ExtractionConfig, JupyterCellRendering};
let config = ExtractionConfig {
jupyter_cell_rendering: JupyterCellRendering::Source,
..Default::default()
};
```
* CLI
```bash
xberg extract notebook.ipynb --jupyter-cell-rendering source
```
Use `source`, `outputs`, or `both` (the default).
## Supported Formats
[Section titled “Supported Formats”](#supported-formats)
Xberg supports 107 file formats across 140 unique file extensions and accepts 53 compatibility MIME aliases:
| Category | Example extensions | Notes |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------- |
| **PDF** | `.pdf` | Native text + OCR for scanned pages |
| **Images** | `.png`, `.jpg`, `.jpeg`, `.tiff`, `.bmp`, `.webp`, `.heic`, `.heics`, `.heif`, `.heifs`, `.hif`, `.avif` | OCR backend; HEIC/HEIF/AVIF need `heic` feature + libheif |
| **Office** | `.docx`, `.pptx`, `.xlsx`, `.odt`, `.ods`, `.odp` | Modern + OpenDocument via native parsers |
| **Legacy Office** | `.doc`, `.ppt`, `.pps`, `.wpd`, `.wp`, `.wp5`, `.wp6` | Native OLE/CFB parsing; WordPerfect via libwpd |
| **Email** | `.eml`, `.msg`, `.pst` | Full support including attachments |
| **Web** | `.html`, `.htm`, `.xhtml`, `.xht` | Converted to Markdown with metadata |
| **Text and data** | `.md`, `.txt`, `.xml`, `.json`, `.geojson`, `.kml`, `.yaml`, `.toml`, `.csv`, `.sqlite`, `.sqlite3`, `.db`, `.gpkg`, `.gpkx` | Direct, geospatial, and bounded database extraction |
| **Archives** | `.zip`, `.tar`, `.tgz`, `.gz`, `.7z` | Recursive extraction |
### Image metadata and EXIF
[Section titled “Image metadata and EXIF”](#image-metadata-and-exif)
For every supported image format — JPEG, PNG, TIFF, WebP, BMP, GIF, JPEG 2000, HEIC, HEIF, AVIF — Xberg returns an `ImageMetadata` block on `metadata.format` containing:
* **`width`** / **`height`** in pixels
* **`format`** — uppercase format tag (e.g. `JPEG`, `PNG`, `HEIF`)
* **`exif`** — a key/value map of EXIF tags
EXIF extraction is powered by the pure-Rust `nom-exif` integration and covers camera identity (Make, Model, LensModel, LensSpecification, Software), timestamps (DateTimeOriginal, CreateDate, OffsetTime, SubSecTime), full exposure parameters (ExposureTime, FNumber, ISO, ApertureValue, ShutterSpeedValue, ExposureProgram, ExposureMode, MeteringMode, Flash, SceneCaptureType), the complete GPS block (GPSLatitude, GPSLongitude, GPSAltitude, GPSTimeStamp, GPSDateStamp, GPSSpeed, GPSImgDirection, GPSMapDatum, GPSProcessingMethod), color space, thumbnail offsets, and provenance fields (Copyright, ImageDescription, ImageUniqueID).
EXIF works on every target, including `wasm-target` and `android-target`, because `nom-exif` is pure Rust. HEIC / HEIF / AVIF pixel decoding requires the `heic` Cargo feature and the system `libheif` library, and is therefore **native-only** — see the [installation guide](/getting-started/installation/#heif--heic--avif-support).
When the `heic` feature is enabled, HEIC / HEIF / AVIF inputs are decoded to RGBA via `libheif`, re-encoded as PNG, and then flow through the standard OCR / layout pipeline. EXIF is read from the original HEIC bytes before the PNG re-encode so no metadata is lost.
## Page Tracking
[Section titled “Page Tracking”](#page-tracking)
Xberg can track page boundaries and extract per-page content. Page tracking availability depends on the format:
* **PDF** — Full byte-accurate page tracking with O(1) lookup
* **PPTX** — Slide boundary tracking (each slide = one page)
* **DOCX** — Best-effort detection using explicit `(input_json).unwrap();
let config_json: serde_json::Value = serde_json::from_str(r#"{}"#).unwrap();
let config = serde_json::from_value(config_json).unwrap();
let result = extract(input, &config).await;
match result {
Ok(value) => println!("{:?}", value),
Err(error) => println!("{error}"),
}
}
```
* Go
Error when extracting with unsupported MIME type
Go
```go
package main
import (
"errors"
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
"os"
)
func ptr[T any](value T) *T { return &value }
func mustReadFile(path string) []byte {
content, err := os.ReadFile(path)
if err != nil {
panic(err)
}
return content
}
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindBytes),
Bytes: mustReadFile(`text/plain.txt`),
MimeType: ptr(`application/x-nonexistent`),
Filename: ptr(`plain.txt`),
Config: &xberg.FileExtractionConfig{},
}
config := xberg.ExtractionConfig{}
_, err := xberg.Extract(input, config)
var typedError xberg.Error
if errors.As(err, &typedError) {
fmt.Fprintf(os.Stderr, "%T: %v\n", typedError, typedError)
}
}
```
* Java
Error when extracting with unsupported MIME type
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
try {
var inputFile0 = java.util.Base64.getEncoder().encodeToString(
java.nio.file.Files.readAllBytes(java.nio.file.Path.of("text/plain.txt"))
);
var inputJson = "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}";
inputJson = inputJson.replace("__ALEF_DOC_FILE_0__", inputFile0);
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var configJson = "{}";
var config = JsonUtil.fromJson(configJson, ExtractionConfig.class);
var result = Xberg.extract(input, config);
System.out.println(result);
} catch (XbergRsException error) {
System.err.println(error.getClass().getSimpleName() + ": " + error.getMessage());
}
}
}
```
* Kotlin (Android)
Error when extracting with unsupported MIME type
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
try {
val inputFile0 = java.util.Base64.getEncoder().encodeToString(java.nio.file.Files.readAllBytes(java.nio.file.Path.of("text/plain.txt")))
val input = mapper.readValue("{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}".replace("__ALEF_DOC_FILE_0__", inputFile0), ExtractInput::class.java)
val config = mapper.readValue("{\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, config)
} catch (error: Exception) {
System.err.println("${error::class.simpleName}: ${error.message}")
}
}
```
* C#
Error when extracting with unsupported MIME type
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
try
{
var result = await XbergConverter.ExtractAsync(new ExtractInput { Bytes = System.IO.File.ReadAllBytes("text/plain.txt"), Config = new FileExtractionConfig(), Filename = "plain.txt", Kind = JsonSerializer.Deserialize("\"bytes\"", ConfigOptions)!, MimeType = "application/x-nonexistent" }, new ExtractionConfig());
}
catch (Exception error)
{
Console.Error.WriteLine($"{error.GetType().Name}: {error.Message}");
}
```
* Swift
Error when extracting with unsupported MIME type
Swift
```swift
import Xberg
do {
_ = try await Xberg.extract("{\"bytes\":\"text/plain.txt\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}", "{}")
} catch {
print("\(type(of: error)): \(error)")
}
```
* Ruby
Error when extracting with unsupported MIME type
Ruby
```ruby
require "xberg"
begin
result = Xberg.extract(Xberg::ExtractInput.new(bytes: File.binread('text/plain.txt').bytes, config: { }, filename: 'plain.txt', kind: 'bytes', mime_type: 'application/x-nonexistent'), { })
rescue StandardError => error
warn "#{error.class}: #{error.message}"
end
```
* PHP
Error when extracting with unsupported MIME type
PHP
```php
"text/plain.txt", "config" => [], "filename" => "plain.txt", "kind" => "bytes", "mimeType" => "application/x-nonexistent"]));
try {
Xberg::extract($input, []);
} catch (Throwable $error) {
echo $error::class . ': ' . $error->getMessage() . "\n";
}
```
* Elixir
Error when extracting with unsupported MIME type
Elixir
```elixir
try do
input_value = %Xberg.ExtractInput{bytes: :binary.bin_to_list(File.read!("text/plain.txt")), config: %{}, filename: "plain.txt", kind: "bytes", mime_type: "application/x-nonexistent"}
result = Xberg.extract_async(input_value, "{}")
rescue
error -> IO.puts(:stderr, "#{inspect(error.__struct__)}: #{Exception.message(error)}")
end
```
* Dart
Error when extracting with unsupported MIME type
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
try {
final input = await createExtractInputFromJson(json: '{"bytes":"text/plain.txt","config":{},"filename":"plain.txt","kind":"bytes","mime_type":"application/x-nonexistent"}');
final config = await createExtractionConfigFromJson(json: '{}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result);
} on XbergError catch (error) {
stderr.writeln('${error.runtimeType}: $error');
}
} finally {
RustLib.dispose();
}
}
```
* Zig
Error when extracting with unsupported MIME type
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
var gpa: std.heap.DebugAllocator(.{}) = .init;
defer _ = gpa.deinit();
const allocator = gpa.allocator();
var input_file_0_threaded = std.Io.Threaded.init(allocator, .{});
defer input_file_0_threaded.deinit();
const input_file_0_io = input_file_0_threaded.io();
const input_file_0 = try std.Io.Dir.cwd().readFileAlloc(input_file_0_io, "text/plain.txt", allocator, .unlimited);
defer allocator.free(input_file_0);
const input_file_0_json = try std.json.Stringify.valueAlloc(allocator, input_file_0, .{ .emit_strings_as_arrays = true });
defer allocator.free(input_file_0_json);
const input_json_0 = try std.mem.replaceOwned(u8, allocator, "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}", "\"__ALEF_DOC_FILE_0__\"", input_file_0_json);
defer allocator.free(input_json_0);
if (xberg.extract(input_json_0, "{}")) |_| {
return error.TestUnexpectedResult;
} else |err| { std.debug.print("call failed as expected: {s}\n", .{@errorName(err)}); }
}
```
* C
Error when extracting with unsupported MIME type
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
const char *input_json_base = "{\"bytes\":\"__ALEF_DOC_FILE_0__\",\"config\":{},\"filename\":\"plain.txt\",\"kind\":\"bytes\",\"mime_type\":\"application/x-nonexistent\"}";
FILE *input_file_0 = fopen("text/plain.txt", "rb");
if (input_file_0 == NULL) return EXIT_FAILURE;
fseek(input_file_0, 0, SEEK_END);
long input_size_0 = ftell(input_file_0);
if (input_size_0 < 0) { fclose(input_file_0); return EXIT_FAILURE; }
rewind(input_file_0);
uint8_t *input_bytes_0 = malloc(input_size_0 > 0 ? (size_t)input_size_0 : 1);
if (input_bytes_0 == NULL) { fclose(input_file_0); return EXIT_FAILURE; }
if (fread(input_bytes_0, 1, (size_t)input_size_0, input_file_0) != (size_t)input_size_0) { free(input_bytes_0); fclose(input_file_0); return EXIT_FAILURE; }
fclose(input_file_0);
char *input_bytes_json_0 = malloc((size_t)input_size_0 * 4 + 3);
if (input_bytes_json_0 == NULL) { free(input_bytes_0); return EXIT_FAILURE; }
size_t input_offset_0 = 0;
input_bytes_json_0[input_offset_0++] = '[';
for (long i = 0; i < input_size_0; ++i) {
input_offset_0 += (size_t)snprintf(input_bytes_json_0 + input_offset_0, 5, "%s%u", i == 0 ? "" : ",", input_bytes_0[i]);
}
input_bytes_json_0[input_offset_0++] = ']';
input_bytes_json_0[input_offset_0] = '\0';
free(input_bytes_0);
const char *input_marker_0 = "\"__ALEF_DOC_FILE_0__\"";
const char *input_position_0 = strstr(input_json_base, input_marker_0);
if (input_position_0 == NULL) { free(input_bytes_json_0); return EXIT_FAILURE; }
size_t input_prefix_0 = (size_t)(input_position_0 - input_json_base);
size_t input_json_size_0 = strlen(input_json_base) - strlen(input_marker_0) + strlen(input_bytes_json_0) + 1;
char *input_json_0 = malloc(input_json_size_0);
if (input_json_0 == NULL) { free(input_bytes_json_0); return EXIT_FAILURE; }
snprintf(input_json_0, input_json_size_0, "%.*s%s%s", (int)input_prefix_0, input_json_base, input_bytes_json_0, input_position_0 + strlen(input_marker_0));
free(input_bytes_json_0);
XBERGAlefHandle input_handle = xberg_extract_input_from_json(input_json_0);
free(input_json_0);
XBERGAlefHandle config_handle = xberg_extraction_config_from_json("{}");
XBERGAlefHandle result = xberg_extract(input_handle, config_handle);
if (result != 0) { return EXIT_FAILURE; }
xberg_extract_input_free(input_handle);
xberg_extraction_config_free(config_handle);
return EXIT_SUCCESS;
}
```
System Errors
`OSError` (Python), `IOException` (Rust), and system-level errors always propagate through. These indicate real system problems (permissions, disk space, etc.) that your application should handle.
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Configuration](/guides/configuration/) — all configuration options and file formats
* [OCR Guide](/guides/ocr/) — set up optical character recognition
* [Chunking](/guides/chunking/) — split text for RAG
* [Language Detection](/guides/language-detection/) — multilingual document analysis
* [Embeddings](/guides/embeddings/) — semantic vectors for search
* [Element-Based Output](/guides/output-formats/#element-based-output) — structured element arrays for RAG
* [Document Structure](/guides/output-formats/#document-structure) — hierarchical tree output
# HTML Output
Render extracted document content as styled HTML with semantic `kb-*` CSS classes, configurable themes, and full CSS customization. See the [HtmlOutputConfig reference](/reference/configuration/#htmloutputconfig) for all options.
## Quick Start
[Section titled “Quick Start”](#quick-start)
* CLI
Terminal
```bash
xberg extract doc.pdf --html-theme github
```
* Python
html\_output.py
```python
from xberg import ExtractInput, ExtractionConfig, HtmlOutputConfig, HtmlTheme, extract
config = ExtractionConfig(
output_format="html",
html_output=HtmlOutputConfig(theme=HtmlTheme.GitHub),
)
output = await extract(ExtractInput(kind="uri", uri="doc.pdf"), config=config)
result = output.results[0]
print(result.content) # styled HTML string
```
* TypeScript
html\_output.ts
```typescript
import { ExtractInputKind, HtmlTheme, extract } from '@xberg-io/xberg';
const output = await extract(
{ kind: ExtractInputKind.Uri, uri: 'doc.pdf' },
{
outputFormat: 'html',
htmlOutput: { theme: HtmlTheme.GitHub },
},
);
const result = output.results[0];
console.log(result.content);
```
* Rust
html\_output.rs
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, HtmlOutputConfig, HtmlTheme};
let config = ExtractionConfig {
output_format: "html".to_string(),
html_output: Some(HtmlOutputConfig {
theme: HtmlTheme::GitHub,
..Default::default()
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("doc.pdf"), &config).await?;
let result = &output.results[0];
println!("{}", result.content);
```
## Built-in Themes
[Section titled “Built-in Themes”](#built-in-themes)
| Theme | Description |
| -------------------- | -------------------------------------------------------------------------------------- |
| `unstyled` (default) | No built-in CSS. Only structural markup with `kb-*` classes. Use your own style sheet. |
| `default` | System font stack, neutral colours, 72ch max width. All CSS custom properties defined. |
| `github` | GitHub Markdown-inspired palette, border-bottom headings, 80ch max width. |
| `dark` | Dark background (#0d1117), light text. Good for terminal/IDE integrations. |
| `light` | Minimal light theme with generous spacing. |
## Configuration
[Section titled “Configuration”](#configuration)
See [HtmlOutputConfig](/reference/configuration/#htmloutputconfig) for detailed field documentation.
* Python
html\_config.py
```python
from xberg import ExtractionConfig, HtmlOutputConfig, HtmlTheme
config = ExtractionConfig(
output_format="html",
html_output=HtmlOutputConfig(
theme=HtmlTheme.Dark,
css="body { padding: 2rem; }",
class_prefix="kb-",
embed_css=True,
),
)
```
* TypeScript
html\_config.ts
```typescript
import { HtmlTheme } from '@xberg-io/xberg';
const config = {
outputFormat: 'html',
htmlOutput: {
theme: HtmlTheme.Dark,
css: 'body { padding: 2rem; }',
classPrefix: 'kb-',
embedCss: true,
},
};
```
* Rust
html\_config.rs
```rust
use xberg::{ExtractionConfig, HtmlOutputConfig, HtmlTheme};
let config = ExtractionConfig {
output_format: "html".to_string(),
html_output: Some(HtmlOutputConfig {
theme: HtmlTheme::Dark,
css: Some("body { padding: 2rem; }".to_string()),
class_prefix: "kb-".to_string(),
embed_css: true,
..Default::default()
}),
..Default::default()
};
```
## CLI Flags
[Section titled “CLI Flags”](#cli-flags)
| Flag | Description |
| ------------------------------ | -------------------------------------------------------------------------------------------------- |
| `--html-theme ` | Built-in theme: `default`, `github`, `dark`, `light`, `unstyled`. Implies `--content-format html`. |
| `--html-css ` | Inline CSS string appended after the theme stylesheet. |
| `--html-css-file ` | Path to CSS file loaded at render time (max 1 MiB). |
| `--html-class-prefix ` | CSS class prefix; default: `"kb-"`. Alphanumeric, hyphens, underscores only. |
| `--html-no-embed-css` | Suppress the `` sequences are stripped from user CSS - `css_file` is limited to 1 MiB - When serving HTML to untrusted users, sanitize CSS at the application layer
## See Also
[Section titled “See Also”](#see-also)
* [Configuration](/guides/configuration/) – all configuration options
* [Extraction Basics](/guides/extraction/) – core extraction API and supported formats
* [Element-Based Output](/guides/output-formats/#element-based-output) – structured element output as an alternative to HTML
* [Document Structure](/guides/output-formats/#document-structure) – how Xberg models document structure
# VLM Image Captions
Caption every extracted image with a vision-language model to add alt-text, feed into retrieval pipelines, or describe diagrams and charts for downstream LLMs. See the [CaptioningConfig reference](/reference/configuration/#captioningconfig) for all options.
Feature gate
Requires the `captioning` Cargo feature. Included in `full`. Requires `liter-llm` and a vision-capable provider.
## When to Use
[Section titled “When to Use”](#when-to-use)
* You need alt-text for accessibility-compliant exports
* You need searchable text descriptions per image to feed into a retrieval pipeline alongside the document body
* You need diagrams, charts, or photos described for LLM downstream consumption
## When Not to Use
[Section titled “When Not to Use”](#when-not-to-use)
* You only need OCR’d text from images — use [OCR](/guides/ocr/) for text extraction from images
* You’re processing high-volume batches where API spend is a concern — captioning calls an LLM per image
* Images are mostly decorative or structural elements
## Configuration
[Section titled “Configuration”](#configuration)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig, CaptioningConfig, LlmConfig
async def main() -> None:
config = ExtractionConfig(
captioning=CaptioningConfig(
llm=LlmConfig(model="openai/gpt-4o-mini"),
min_image_area=0,
),
)
result = await extract(ExtractInput(uri="report.pdf"), config)
for image in result.results[0].images or []:
if image.caption:
print(image.caption)
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "report.pdf",
}, {
captioning: {
llm: { model: "openai/gpt-4o-mini" },
minImageArea: 1000,
},
});
const [first] = output.results ?? [];
for (const image of first?.images ?? []) {
if (image.caption) {
console.log(image.caption);
}
}
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, CaptioningConfig, LlmConfig};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig {
captioning: Some(CaptioningConfig {
llm: LlmConfig {
model: "openai/gpt-4o-mini".to_string(),
..Default::default()
},
prompt: None,
min_image_area: 1000,
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("report.pdf"), &config).await?;
for image in output.results[0].images.iter().flatten() {
if let Some(caption) = &image.caption {
println!("{caption}");
}
}
Ok(())
}
```
* TOML
xberg.toml
```toml
[captioning]
min_image_area = 1000
[captioning.llm]
model = "openai/gpt-4o-mini"
```
## Custom Prompt
[Section titled “Custom Prompt”](#custom-prompt)
Override the built-in caption prompt:
* Python
Python
```python
from xberg import ExtractionConfig, CaptioningConfig, LlmConfig
config = ExtractionConfig(
captioning=CaptioningConfig(
llm=LlmConfig(model="openai/gpt-4o-mini"),
prompt="Describe this figure in one sentence suitable for alt-text.",
min_image_area=4000,
),
)
```
The prompt is sent alongside each image as a single VLM request. The model sees the image plus the prompt; the response becomes the caption verbatim.
## Filtering Small Images
[Section titled “Filtering Small Images”](#filtering-small-images)
`min_image_area` is in pixels (width × height). Icons, bullets, and decorative glyphs below the threshold are skipped — their `caption` field stays `None`. The default `1000` excludes 32×32 icons but admits typical inline figures. Raise the threshold to skip thumbnails; lower it to caption everything.
## Output Shape
[Section titled “Output Shape”](#output-shape)
```json
{
"images": [
{
"image_kind": "diagram",
"page_number": 3,
"caption": "A flowchart showing the data ingestion pipeline: source → cleaner → indexer → retrieval API.",
"bounding_box": { "x0": 72.0, "y0": 144.0, "x1": 540.0, "y1": 456.0 }
},
{
"image_kind": "icon",
"caption": null
}
]
}
```
`bounding_box` uses PDF coordinates (`x0`=left, `y0`=bottom, `x1`=right, `y1`=top) and is only populated for PDF-extracted images when the extractor reports position data; it is omitted otherwise. `page_number` is a sibling field on the image, not part of the box.
## Supported Providers
[Section titled “Supported Providers”](#supported-providers)
Any vision-capable liter-llm provider works (see the [VLM OCR provider table](/guides/llm-integration/#supported-providers)). For batch captioning, `gpt-4o-mini`, `claude-3-5-haiku`, and `google/gemini-2.0-flash` are typically the cheapest options.
API-key precedence chain matches [LLM Integration](/guides/llm-integration/#api-key-configuration):
1. `CaptioningConfig.llm.api_key`
2. `XBERG_LLM_API_KEY`
3. Per-provider env var
Local engines (Ollama, LM Studio with a VLM, vLLM) need no key.
## Related
[Section titled “Related”](#related)
* [LLM Integration](/guides/llm-integration/) — provider matrix, local engines, VLM OCR
* [OCR](/guides/ocr/) — text-from-image extraction
* [Configuration Reference](/reference/configuration/#captioningconfig)
# Keyword Extraction
Extract ranked keywords and key phrases from document text for search indexing, topic detection, and content summarization. Choose between YAKE (best for single terms and multilingual content) or RAKE (best for multi-word phrases in technical documents).
| Algorithm | Scoring | Best for |
| --------- | -------------------------------------- | --------------------------------------------- |
| **YAKE** | Higher score = more relevant (0.0–1.0) | General documents, single terms, multilingual |
| **RAKE** | Higher score = more relevant (0.0–1.0) | Multi-word phrases, technical docs |
## Quick Start
[Section titled “Quick Start”](#quick-start)
* Python
Tests keyword extraction via YAKE algorithm
Python
```python
import asyncio
from xberg import extract, ExtractInput
from xberg._xberg import ExtractionConfig
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
config = ExtractionConfig.from_json("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
result = await extract(input, config)
for keyword in result.results[0].extracted_keywords or []:
print(keyword.text)
print(keyword.score)
asyncio.run(main())
```
* TypeScript / Node.js
Tests keyword extraction via YAKE algorithm
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, ExtractionConfig, KeywordAlgorithm, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const config: ExtractionConfig = { keywords: { algorithm: KeywordAlgorithm.Yake, maxKeywords: 10 } };
const result = await extract(input, config);
const [first] = result.results ?? [];
for (const keyword of first?.extractedKeywords ?? []) {
console.log(keyword.text);
console.log(keyword.score);
}
}
void main();
```
* WebAssembly
Tests keyword extraction via YAKE algorithm
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, { keywords: { algorithm: "yake", maxKeywords: 10 } });
const [first] = result.results ?? [];
for (const keyword of first?.extractedKeywords ?? []) {
console.log(keyword.text);
console.log(keyword.score);
}
}
void main();
```
* Rust
Tests keyword extraction via YAKE algorithm
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config_json: serde_json::Value = serde_json::from_str(r#"{"keywords":{"algorithm":"yake","max_keywords":10}}"#).unwrap();
let config = serde_json::from_value(config_json).unwrap();
let result = extract(input, &config).await.expect("call failed");
for keyword in result.results[0].extracted_keywords.iter().flatten() {
println!("{}", keyword.text);
println!("{}", keyword.score);
}
}
```
* Go
Tests keyword extraction via YAKE algorithm
Go
```go
package main
import (
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{
Keywords: &xberg.KeywordConfig{
Algorithm: xberg.KeywordAlgorithmYake,
MaxKeywords: ptr(uint(10)),
},
}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
for _, keyword := range result.Results[0].ExtractedKeywords {
fmt.Printf("%v\n", keyword.Text)
fmt.Printf("%v\n", keyword.Score)
}
}
```
* Java
Tests keyword extraction via YAKE algorithm
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var configJson = "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}";
var config = JsonUtil.fromJson(configJson, ExtractionConfig.class);
var result = Xberg.extract(input, config);
for (var keyword : result.results().get(0).extractedKeywords()) {
System.out.println(keyword.text());
System.out.println(keyword.score());
}
}
}
```
* Kotlin (Android)
Tests keyword extraction via YAKE algorithm
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val config = mapper.readValue("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10},\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, config)
for (keyword in result.results.first().extractedKeywords.orEmpty()) {
println(keyword.text)
println(keyword.score)
}
}
```
* C#
Tests keyword extraction via YAKE algorithm
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig { Keywords = new KeywordConfig { Algorithm = JsonSerializer.Deserialize("\"yake\"", ConfigOptions)!, MaxKeywords = 10 } });
foreach (var keyword in result.Results[0].ExtractedKeywords!)
{
Console.WriteLine(keyword.Text);
Console.WriteLine(keyword.Score);
}
```
* Swift
Tests keyword extraction via YAKE algorithm
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
print(result)
```
* Ruby
Tests keyword extraction via YAKE algorithm
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'), { 'keywords' => { 'algorithm' => 'yake', 'max_keywords' => 10 } })
(result.results[0].extracted_keywords || []).each do |keyword|
puts keyword.text
puts keyword.score
end
```
* PHP
Tests keyword extraction via YAKE algorithm
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, ["keywords" => ["algorithm" => "yake", "max_keywords" => 10]]);
foreach ($result->getResults()[0]->getExtractedKeywords() ?? [] as $keyword) {
echo $keyword->text, PHP_EOL;
echo $keyword->score, PHP_EOL;
}
```
* Elixir
Tests keyword extraction via YAKE algorithm
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value, "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
Enum.each(Enum.at(result.results, 0).extracted_keywords || [], fn keyword ->
IO.puts(keyword.text)
IO.puts(keyword.score)
end)
```
* Dart
Tests keyword extraction via YAKE algorithm
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{"keywords":{"algorithm":"yake","max_keywords":10}}');
final result = await XbergBridge.extract(input, config: config);
for (final keyword in result.results[0].extractedKeywords ?? []) {
stdout.writeln(keyword.text);
stdout.writeln(keyword.score);
}
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests keyword extraction via YAKE algorithm
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests keyword extraction via YAKE algorithm
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle config_handle = xberg_extraction_config_from_json("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}");
XBERGAlefHandle result = xberg_extract(input_handle, config_handle);
xberg_extract_input_free(input_handle);
xberg_extraction_config_free(config_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
Keywords are returned in `result.extracted_keywords` as objects with `text` and `score` fields.
## Configuration
[Section titled “Configuration”](#configuration)
See [KeywordConfig reference](/reference/configuration/#keywordconfig) for all configuration options.
* Python
Tests keyword extraction via YAKE algorithm
Python
```python
import asyncio
from xberg import extract, ExtractInput
from xberg._xberg import ExtractionConfig
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
config = ExtractionConfig.from_json("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
result = await extract(input, config)
for keyword in result.results[0].extracted_keywords or []:
print(keyword.text)
print(keyword.score)
asyncio.run(main())
```
* TypeScript / Node.js
Tests keyword extraction via YAKE algorithm
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, ExtractionConfig, KeywordAlgorithm, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const config: ExtractionConfig = { keywords: { algorithm: KeywordAlgorithm.Yake, maxKeywords: 10 } };
const result = await extract(input, config);
const [first] = result.results ?? [];
for (const keyword of first?.extractedKeywords ?? []) {
console.log(keyword.text);
console.log(keyword.score);
}
}
void main();
```
* WebAssembly
Tests keyword extraction via YAKE algorithm
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, { keywords: { algorithm: "yake", maxKeywords: 10 } });
const [first] = result.results ?? [];
for (const keyword of first?.extractedKeywords ?? []) {
console.log(keyword.text);
console.log(keyword.score);
}
}
void main();
```
* Rust
Tests keyword extraction via YAKE algorithm
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config_json: serde_json::Value = serde_json::from_str(r#"{"keywords":{"algorithm":"yake","max_keywords":10}}"#).unwrap();
let config = serde_json::from_value(config_json).unwrap();
let result = extract(input, &config).await.expect("call failed");
for keyword in result.results[0].extracted_keywords.iter().flatten() {
println!("{}", keyword.text);
println!("{}", keyword.score);
}
}
```
* Go
Tests keyword extraction via YAKE algorithm
Go
```go
package main
import (
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{
Keywords: &xberg.KeywordConfig{
Algorithm: xberg.KeywordAlgorithmYake,
MaxKeywords: ptr(uint(10)),
},
}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
for _, keyword := range result.Results[0].ExtractedKeywords {
fmt.Printf("%v\n", keyword.Text)
fmt.Printf("%v\n", keyword.Score)
}
}
```
* Java
Tests keyword extraction via YAKE algorithm
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var configJson = "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}";
var config = JsonUtil.fromJson(configJson, ExtractionConfig.class);
var result = Xberg.extract(input, config);
for (var keyword : result.results().get(0).extractedKeywords()) {
System.out.println(keyword.text());
System.out.println(keyword.score());
}
}
}
```
* Kotlin (Android)
Tests keyword extraction via YAKE algorithm
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val config = mapper.readValue("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10},\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, config)
for (keyword in result.results.first().extractedKeywords.orEmpty()) {
println(keyword.text)
println(keyword.score)
}
}
```
* C#
Tests keyword extraction via YAKE algorithm
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig { Keywords = new KeywordConfig { Algorithm = JsonSerializer.Deserialize("\"yake\"", ConfigOptions)!, MaxKeywords = 10 } });
foreach (var keyword in result.Results[0].ExtractedKeywords!)
{
Console.WriteLine(keyword.Text);
Console.WriteLine(keyword.Score);
}
```
* Swift
Tests keyword extraction via YAKE algorithm
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
print(result)
```
* Ruby
Tests keyword extraction via YAKE algorithm
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'), { 'keywords' => { 'algorithm' => 'yake', 'max_keywords' => 10 } })
(result.results[0].extracted_keywords || []).each do |keyword|
puts keyword.text
puts keyword.score
end
```
* PHP
Tests keyword extraction via YAKE algorithm
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, ["keywords" => ["algorithm" => "yake", "max_keywords" => 10]]);
foreach ($result->getResults()[0]->getExtractedKeywords() ?? [] as $keyword) {
echo $keyword->text, PHP_EOL;
echo $keyword->score, PHP_EOL;
}
```
* Elixir
Tests keyword extraction via YAKE algorithm
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value, "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}")
Enum.each(Enum.at(result.results, 0).extracted_keywords || [], fn keyword ->
IO.puts(keyword.text)
IO.puts(keyword.score)
end)
```
* Dart
Tests keyword extraction via YAKE algorithm
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{"keywords":{"algorithm":"yake","max_keywords":10}}');
final result = await XbergBridge.extract(input, config: config);
for (final keyword in result.results[0].extractedKeywords ?? []) {
stdout.writeln(keyword.text);
stdout.writeln(keyword.score);
}
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests keyword extraction via YAKE algorithm
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests keyword extraction via YAKE algorithm
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle config_handle = xberg_extraction_config_from_json("{\"keywords\":{\"algorithm\":\"yake\",\"max_keywords\":10}}");
XBERGAlefHandle result = xberg_extract(input_handle, config_handle);
xberg_extract_input_free(input_handle);
xberg_extraction_config_free(config_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
## YAKE Score Tuning
[Section titled “YAKE Score Tuning”](#yake-score-tuning)
Use `min_score` as a lower-bound cutoff. Higher YAKE scores = higher relevance:
| `min_score` | Effect |
| ----------- | ------------------- |
| `0.1` | Keeps most keywords |
| `0.3` | Main topics only |
| `0.5` | Core concepts only |
`yake_params.window_size` controls co-occurrence context: `1–2` for narrow domains, `2–3` for general (default: `2`), `3–4` for discussion-heavy content.
## RAKE Score Tuning
[Section titled “RAKE Score Tuning”](#rake-score-tuning)
Use `min_score` as a lower-bound cutoff. Higher RAKE scores = higher relevance:
| `min_score` | Effect |
| ----------- | ---------------------------- |
| `0.1` | Keeps most keywords |
| `0.3` | Main phrases only |
| `0.5` | Only highly specific phrases |
`rake_params.min_word_length` (default: `1`) and `rake_params.max_words_per_phrase` (default: `3`) control phrase boundaries.
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
* **Too few keywords** — Lower `min_score`, check `result.content` is non-empty, set `language` to match the document or `None` to disable stopword filtering
* **Too many irrelevant keywords** — Raise `min_score`, set `language` for stopword filtering, reduce `ngram_range` upper bound
* **Multi-word phrases missing (YAKE)** — Switch to RAKE or confirm `ngram_range` upper bound is >= 2
* **Keywords don’t match content** — Verify text was extracted (`result.content`) and `language` matches the document
See the [KeywordConfig reference](/reference/configuration/#keywordconfig) for the full parameter list.
# Kubernetes Deployment
> Deploy the Xberg extraction server on Kubernetes with the official Helm chart.
Deploy the Xberg REST API server (`xberg serve`) on Kubernetes with the official Helm chart. The chart is a single-service deployment — one stateless workload plus an optional cache, ingress, and autoscaler. For a distributed, governed platform with team support, see [Xberg Enterprise](https://xberg.io).
## Install
[Section titled “Install”](#install)
The chart is published as an OCI artifact to GitHub Container Registry:
Terminal
```bash
helm install xberg oci://ghcr.io/xberg-io/charts/xberg --version 1.0.14
```
This runs the full image (`ghcr.io/xberg-io/xberg`) in API-server mode on port 8000, exposed through a ClusterIP `Service` on port 80.
The chart is also listed on [Artifact Hub](https://artifacthub.io/packages/helm/xberg-core/xberg), where you can browse every version, its values, and the generated values schema.
## Verify the chart
[Section titled “Verify the chart”](#verify-the-chart)
Every published chart is signed with [cosign](https://docs.sigstore.dev/) using keyless signing (Sigstore OIDC + the Rekor transparency log). Verify a release before installing:
Terminal
```bash
cosign verify \
ghcr.io/xberg-io/charts/xberg:1.0.14 \
--certificate-identity-regexp '^https://github.com/xberg-io/xberg/.github/workflows/publish-helm.yaml@.*$' \
--certificate-oidc-issuer https://token.actions.githubusercontent.com
```
The identity certificate ties each signature to the `publish-helm.yaml` workflow in this repository, so a successful verification proves the chart was built and pushed by Xberg’s release pipeline.
## Configure
[Section titled “Configure”](#configure)
Override defaults with a `values.yaml` file:
values.yaml
```yaml
image:
# Empty tag defaults to the chart appVersion. Use "core" for the minimal
# image (no pre-downloaded models) or "latest" for the full image.
tag: ""
xberg:
logLevel: "info"
ocrLanguage: "eng"
resources:
requests:
memory: "1Gi"
cpu: "1000m"
limits:
memory: "4Gi"
cpu: "2000m"
ingress:
enabled: true
className: "nginx"
hosts:
- host: xberg.example.com
paths:
- path: /
pathType: Prefix
tls:
- secretName: xberg-tls
hosts:
- xberg.example.com
autoscaling:
enabled: true
minReplicas: 1
maxReplicas: 10
targetCPUUtilizationPercentage: 80
```
Terminal
```bash
helm install xberg oci://ghcr.io/xberg-io/charts/xberg \
--version 1.0.14 \
-f values.yaml
```
## Cache and replicas
[Section titled “Cache and replicas”](#cache-and-replicas)
Embedding and OCR models range from \~90 MB to 1.2 GB and are re-downloaded on every pod restart without a cache. The chart enables a `ReadWriteOnce` PVC (`cache.enabled: true`) mounted at `/app/.xberg` (with `HF_HOME` under it) to persist them.
Caution
A `ReadWriteOnce` volume can only attach to one node, so the chart defaults to `replicaCount: 1` with a `Recreate` strategy. To run multiple replicas, either switch the cache to `ReadWriteMany` storage or set `cache.enabled: false` (each pod then re-downloads models into an ephemeral volume).
## Upgrade and uninstall
[Section titled “Upgrade and uninstall”](#upgrade-and-uninstall)
Terminal
```bash
helm upgrade xberg oci://ghcr.io/xberg-io/charts/xberg --version 1.0.14 -f values.yaml
helm uninstall xberg
```
The cache PVC carries `helm.sh/resource-policy: keep`, so it survives an uninstall — delete it manually if you no longer need the cached models.
## What’s included
[Section titled “What’s included”](#whats-included)
| Resource | Description | Conditional |
| ----------------------- | --------------------------------------------------------------------------------------- | ----------------------------- |
| Deployment | API server with health probes and a hardened, non-root, read-only-root security context | Always |
| Service | ClusterIP on port 80 → container 8000 | Always |
| ServiceAccount | Dedicated service account | `serviceAccount.create` |
| PersistentVolumeClaim | Cache for models and downloaded assets | `cache.enabled` |
| Ingress | HTTP(S) ingress with optional TLS | `ingress.enabled` |
| HorizontalPodAutoscaler | CPU/memory-based autoscaling | `autoscaling.enabled` |
| PodDisruptionBudget | Availability during voluntary disruptions | `podDisruptionBudget.enabled` |
All values are documented in the chart’s [`values.yaml`](https://github.com/xberg-io/xberg/blob/main/charts/xberg/values.yaml) and validated on install against the bundled [`values.schema.json`](https://github.com/xberg-io/xberg/blob/main/charts/xberg/values.schema.json), so a malformed override fails fast with a clear error.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Docker Deployment](/guides/docker/) — image variants and execution modes
* [API Server](/guides/api-server/) — endpoint reference
* [OCR](/guides/ocr/) — backends and language configuration
# Language Detection
Detect languages in extracted text using [`whatlang`](https://crates.io/crates/whatlang) — supports 60+ languages with ISO 639-3 codes. Set `detect_multiple: true` to chunk the text into 200-character segments and return all detected languages sorted by prevalence.
Set `min_confidence` (`0.0`–`1.0`, default `0.8`) to the lowest whatlang confidence a detection must reach to be reported. In single-language mode, the primary detection is dropped and no language is returned when it scores below the threshold. In `detect_multiple` mode, the threshold is applied to each 200-character chunk; chunks below it are discarded, and if no chunk clears it, detection falls back to single-language mode. Per-chunk confidence runs lower than whole-document confidence, so a high threshold can suppress multi-language results.
## Configuration
[Section titled “Configuration”](#configuration)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, ExtractionConfig, LanguageDetectionConfig, extract
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
language_detection=LanguageDetectionConfig(
enabled=True,
min_confidence=0.85,
detect_multiple=False
)
)
result = await extract(ExtractInput(uri="document.pdf"), config)
if result.results[0].detected_languages:
print(f"Primary language: {result.results[0].detected_languages[0]}")
print(f"Content length: {len(result.results[0].content)} chars")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
languageDetection: {
enabled: true,
minConfidence: 0.8,
detectMultiple: false,
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "document.pdf" }, config);
const result = output.results?.[0];
if (result?.detectedLanguages) {
console.log(`Detected languages: ${result.detectedLanguages.join(", ")}`);
}
```
* Rust
Rust
```rust
use xberg::{ExtractionConfig, LanguageDetectionConfig};
let config = ExtractionConfig {
language_detection: Some(LanguageDetectionConfig {
enabled: true,
min_confidence: 0.8,
detect_multiple: false,
}),
..Default::default()
};
```
* Go
Go
```go
package main
import (
"fmt"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
enabled := true
minConfidence := 0.8
config := &xberg.ExtractionConfig{
LanguageDetection: &xberg.LanguageDetectionConfig{
Enabled: &enabled,
MinConfidence: &minConfidence,
DetectMultiple: false,
},
}
fmt.Printf("Language detection enabled: %v\n", *config.LanguageDetection.Enabled)
fmt.Printf("Min confidence: %f\n", *config.LanguageDetection.MinConfidence)
}
```
* Java
Java
```java
import io.xberg.ExtractionConfig;
import io.xberg.LanguageDetectionConfig;
ExtractionConfig config = ExtractionConfig.builder()
.withLanguageDetection(LanguageDetectionConfig.builder()
.withEnabled(true)
.withMinConfidence(0.8)
.build())
.build();
```
* C#
C#
```csharp
using Xberg;
class Program
{
static async Task Main()
{
var config = new ExtractionConfig
{
LanguageDetection = new LanguageDetectionConfig
{
Enabled = true,
MinConfidence = 0.8,
DetectMultiple = false
}
};
try
{
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("document.pdf"), config)).Results[0];
if (result.DetectedLanguages?.Count > 0)
{
Console.WriteLine($"Detected Language: {result.DetectedLanguages[0]}");
}
else
{
Console.WriteLine("No language detected");
}
Console.WriteLine($"Content length: {result.Content.Length} characters");
}
catch (XbergException ex)
{
Console.WriteLine($"Extraction failed: {ex.Message}");
}
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
language_detection: Xberg::LanguageDetectionConfig.new(
enabled: true,
min_confidence: 0.8,
detect_multiple: false
)
)
```
## Multilingual Example
[Section titled “Multilingual Example”](#multilingual-example)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig, LanguageDetectionConfig
async def main() -> None:
config: ExtractionConfig = ExtractionConfig(
language_detection=LanguageDetectionConfig(
enabled=True,
min_confidence=0.7,
detect_multiple=True
)
)
result = await extract(ExtractInput(uri="multilingual_document.pdf"), config)
languages: list[str] = result.results[0].detected_languages or []
print(f"Detected {len(languages)} languages: {languages}")
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
languageDetection: {
enabled: true,
minConfidence: 0.8,
detectMultiple: true,
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "multilingual_document.pdf" }, config);
const result = output.results?.[0];
if (result?.detectedLanguages) {
console.log(`Detected languages: ${result.detectedLanguages.join(", ")}`);
}
```
* Rust
Rust
```rust
use xberg::{extract, ExtractionConfig, ExtractInput, LanguageDetectionConfig};
#[tokio::main]
async fn main() -> xberg::Result<()> {
let config = ExtractionConfig {
language_detection: Some(LanguageDetectionConfig {
enabled: true,
min_confidence: 0.8,
detect_multiple: true,
}),
..Default::default()
};
let output = extract(ExtractInput::from_uri("multilingual_document.pdf"), &config).await?;
println!("Detected languages: {:?}", output.results[0].detected_languages);
Ok(())
}
```
* Go
Go
```go
package main
import (
"fmt"
"log"
"strings"
"github.com/xberg-io/xberg/packages/go"
)
func main() {
enabled := true
detectMultiple := true
minConfidence := 0.8
cfg := xberg.ExtractionConfig{
LanguageDetection: &xberg.LanguageDetectionConfig{
Enabled: &enabled,
MinConfidence: &minConfidence,
DetectMultiple: detectMultiple,
},
}
input := xberg.ExtractInputFromURI("multilingual_document.pdf")
result, err := xberg.Extract(*input, cfg)
if err != nil {
log.Fatalf("Processing failed: %v", err)
}
languages := result.Results[0].DetectedLanguages
if len(languages) > 0 {
fmt.Printf("Detected %d language(s): %s\n", len(languages), strings.Join(languages, ", "))
} else {
fmt.Println("No languages detected")
}
fmt.Printf("Total content: %d characters\n", len(result.Results[0].Content))
fmt.Printf("MIME type: %s\n", result.Results[0].MimeType)
}
```
* Java
Java
```java
import io.xberg.Xberg;
import io.xberg.ExtractInputKind;
import io.xberg.ExtractionResult;
import io.xberg.ExtractedDocument;
import io.xberg.ExtractionConfig;
import io.xberg.ExtractInput;
import io.xberg.LanguageDetectionConfig;
import java.util.List;
ExtractionConfig config = ExtractionConfig.builder()
.withLanguageDetection(LanguageDetectionConfig.builder()
.withEnabled(true)
.withMinConfidence(0.8)
.withDetectMultiple(true)
.build())
.build();
try {
ExtractionResult output = Xberg.extract(
ExtractInput.builder().withKind(ExtractInputKind.Uri).withUri("multilingual_document.pdf").build(),
config
);
ExtractedDocument result = output.results().get(0);
List languages = result.detectedLanguages() != null
? result.detectedLanguages()
: List.of();
if (!languages.isEmpty()) {
System.out.println("Detected " + languages.size() + " language(s): " + String.join(", ", languages));
} else {
System.out.println("No languages detected");
}
System.out.println("Total content: " + result.content().length() + " characters");
System.out.println("MIME type: " + result.mimeType());
} catch (Exception ex) {
System.err.println("Processing failed: " + ex.getMessage());
}
```
* C#
C#
```csharp
using Xberg;
class Program
{
static async Task Main()
{
var config = new ExtractionConfig
{
LanguageDetection = new LanguageDetectionConfig
{
Enabled = true,
MinConfidence = 0.8,
DetectMultiple = true
}
};
try
{
var result = (await XbergConverter.ExtractAsync(ExtractInput.FromUri("multilingual_document.pdf"), config)).Results[0];
var languages = result.DetectedLanguages ?? new List();
if (languages.Count > 0)
{
Console.WriteLine($"Detected {languages.Count} language(s): {string.Join(", ", languages)}");
}
else
{
Console.WriteLine("No languages detected");
}
Console.WriteLine($"Total content: {result.Content.Length} characters");
Console.WriteLine($"MIME type: {result.MimeType}");
}
catch (XbergException ex)
{
Console.WriteLine($"Processing failed: {ex.Message}");
}
}
}
```
* Ruby
Ruby
```ruby
require 'xberg'
config = Xberg::ExtractionConfig.new(
language_detection: Xberg::LanguageDetectionConfig.new(
enabled: true,
min_confidence: 0.8,
detect_multiple: true
)
)
input = Xberg::ExtractInput.new(uri: 'multilingual_document.pdf')
result = Xberg.extract(input, config)
first_result = result.results.first
languages = first_result.detected_languages || []
if languages.any?
puts "Detected #{languages.length} language(s): #{languages.join(', ')}"
else
puts "No languages detected"
end
puts "Total content: #{first_result.content.length} characters"
puts "MIME type: #{first_result.mime_type}"
```
## See also
[Section titled “See also”](#see-also)
* [Configuration Reference](/reference/configuration/#languagedetectionconfig) — all detection options
* [Chunking](/guides/chunking/) — split text before language detection for per-section analysis
# Layout Detection
Detect document layout regions (tables, figures, headers, text blocks, etc.) in PDFs using ONNX-based deep learning models. Enables table extraction, figure isolation, reading-order reconstruction, and selective OCR.
See the [LayoutDetectionConfig reference](/reference/configuration/#layoutdetectionconfig) for all configuration options.
Feature gate
Requires the `layout-detection` Cargo feature. Not included in the default feature set.
## Model
[Section titled “Model”](#model)
Layout detection uses the **RT-DETR v2** model, an ONNX-based deep learning model that detects document layout regions. Regions are labeled with one of 18 `LayoutClass` categories: text blocks, tables, figures, charts, headers, footers, captions, code, lists, sections, formulas, footnotes, page headers/footers, titles, checkboxes, key-value regions, and document indices.
Layout detection now populates `ExtractedDocument.formulas` for formula regions and supports chart understanding via `enable_chart_understanding`.
With the opt-in `formula-recognition` cargo feature, formula regions can also run through a dedicated LaTeX recognition model. Set `formula_model = "latex_ocr"` in the layout configuration (or pass `--layout-formula-model latex_ocr`) to convert each detected formula region’s image to LaTeX; the region’s plain OCR text stays as the fallback whenever recognition yields nothing. This covers scanned pages too: when the OCR backend emits plain text only, each detected formula region still becomes an entry in `ExtractedDocument.formulas`, with its bounding box in PDF points. The feature is in no default build profile, so it needs a build with `--features formula-recognition`.
### When to Enable
[Section titled “When to Enable”](#when-to-enable)
**Recommended for:** complex multi-column PDFs, scanned documents, academic papers, business forms, and any document where layout understanding improves extraction accuracy.
**Less beneficial for:** simple single-column text documents, high-throughput pipelines where latency is critical (consider GPU acceleration), or documents already well-handled by PDF structure trees.
### Performance Impact
[Section titled “Performance Impact”](#performance-impact)
| Pipeline | Structure F1 | Text F1 | Avg time/doc |
| -------- | ------------ | ------- | ------------ |
| Baseline | 33.9% | 87.4% | 447 ms |
| Layout | 41.1% | 90.1% | 1500 ms |
*171-document PDF corpus, CPU only. GPU acceleration significantly reduces the time penalty.*
Layout Detection Model
Xberg uses only the RT-DETR v2 model for layout detection. The `preset` field is not available in `LayoutDetectionConfig`. Configure table structure recognition separately via `table_model` — see “Table Structure Models” below.
Pure-Rust inference engine
RT-DETR also runs through xberg’s pure-Rust `tract` engine (no native ONNX Runtime library, CPU-only), matching ONNX Runtime within 5e-3 on its outputs. This brings layout detection to targets that cannot link native ONNX Runtime: it is enabled on WASM and the Android x86\_64 emulator via the `layout-tract` feature (on WASM, weights are streamed in through the `detectLayout` export). PP-DocLayout-V3, TATR, and SLANeXT table structure models remain ONNX Runtime-only.
## Configuration
[Section titled “Configuration”](#configuration)
* Python
```python
from xberg import ExtractInput, ExtractionConfig, LayoutDetectionConfig, extract
config = ExtractionConfig(
layout=LayoutDetectionConfig(
confidence_threshold=0.5,
apply_heuristics=True,
table_model="tatr",
)
)
output = await extract(ExtractInput(kind="uri", uri="document.pdf"), config=config)
```
* TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
}, {
layout: {
confidenceThreshold: 0.5,
applyHeuristics: true,
tableModel: "tatr",
},
});
```
* Rust
```rust
use xberg::core::{ExtractionConfig, LayoutDetectionConfig};
let config = ExtractionConfig {
layout: Some(LayoutDetectionConfig {
confidence_threshold: Some(0.5),
apply_heuristics: true,
table_model: Some("tatr".to_string()),
..Default::default()
}),
..Default::default()
};
```
* TOML
xberg.toml
```toml
[layout]
apply_heuristics = true
# table_model = "tatr"
```
* CLI
Terminal
```bash
# Enable layout detection with default settings
xberg extract document.pdf --layout --content-format markdown
# Custom confidence threshold
xberg extract document.pdf --layout-confidence 0.5 --content-format markdown
# Specific table model
xberg extract document.pdf --layout --layout-table-model slanet_wired
# Adaptive page selection: run the model only on pages that can benefit
xberg extract document.pdf --layout --layout-strategy auto
# Combined with GPU acceleration
xberg extract document.pdf --layout --acceleration coreml
```
See [LayoutDetectionConfig](/reference/configuration/#layoutdetectionconfig) for all fields.
### Layout-Informed Markdown
[Section titled “Layout-Informed Markdown”](#layout-informed-markdown)
`use_layout_for_markdown` feeds detected regions into the non-OCR PDF markdown pipeline to drive heading, table, list, and figure detection that would otherwise rely on font-clustering heuristics alone. It is a top-level `ExtractionConfig` field — set it alongside `layout`, not inside `LayoutDetectionConfig`.
Enabling it improves structural F1 at the cost of inference latency (\~150-300 ms/page CPU, \~20-50 ms/page GPU). Default: `false`. Requires the `layout-detection` feature and a set `layout` config; it is skipped when `force_ocr` is enabled. On the CLI, pass `--use-layout-for-markdown`.
### Layout Detection and Output Format
[Section titled “Layout Detection and Output Format”](#layout-detection-and-output-format)
Layout detection is a *structure signal*, not an output format: it feeds the same heading, table, list, and figure classification that the font-clustering heuristic produces, and both are discarded when `output_format` is `Plain` (the default), because `Plain` emits raw text with no structural markup to carry the result. Pair layout detection with a structured `output_format` — `Markdown`, `Djot`, `Html`, or `DocTags` — or the inference cost of running the model is spent for no visible effect on `content`. `output_format` and `layout` are independent config fields; enabling one does not change the other’s default.
## Page Selection Strategy
[Section titled “Page Selection Strategy”](#page-selection-strategy)
`LayoutDetectionConfig.strategy` controls which pages the layout model runs on:
* `always` (default): every page is rendered and inferred, the historical behavior.
* `auto`: a cheap per-page pre-screen runs first, and the model only processes pages likely to benefit: multi-column text, table geometry, ruled grids, heavy graphics, form widgets, sparse or absent text layers, or pages whose signals could not be gathered.
The pre-screen reads geometry the PDF already carries (text-span boxes, straight lines, image and path bounding boxes, annotations) without decoding any pixels, so it costs a small fraction of one model pass. It is recall-biased: an ambiguous page always runs the model. A skipped page is processed exactly like a page where the model ran and found no regions, and on plain single-column prose that output is identical at a fraction of the cost.
Two behaviors to know:
* On the OCR path the pre-screen skips inference only; page rasters are still produced because OCR consumes them.
* Skipped pages are auditable: `metadata.format.layout_gated_pages` lists them (1-indexed), and `metadata.format.layout_gate_reasons` records each page’s decision reason (`multi_column`, `table_grid`, `plain_text`, and so on). The `format` object is tagged `format_type: "pdf"`.
Note that `auto` trades the model’s per-paragraph refinements on skipped pages (heading promotion, code and formula tagging) for throughput; content and reading order are unchanged. Keep `always` when you need the model’s classification on every page.
## Table Structure Models
[Section titled “Table Structure Models”](#table-structure-models)
When layout detection identifies a table region, a table structure model analyzes rows, columns, headers, and spanning cells. Set `LayoutDetectionConfig.table_model` to one of:
| Value | Notes |
| ----------------- | ------------------------------------------------------------ |
| `tatr` | Default. Fast (\~30 MB). General-purpose. |
| `slanet_wired` | Higher accuracy for bordered/gridlined tables (\~365 MB). |
| `slanet_wireless` | Higher accuracy for borderless tables (\~365 MB). |
| `slanet_auto` | Auto-classifies per page (\~737 MB). Slowest. |
| `slanet_plus` | Smallest (\~7.78 MB). For resource-constrained environments. |
| `disabled` | Skip table structure recognition. |
Model Download
SLANeXT models are not downloaded by default. Use `cache warm --all-table-models` to pre-download, or they download automatically on first use.
## GPU Acceleration
[Section titled “GPU Acceleration”](#gpu-acceleration)
Layout detection uses ONNX Runtime with automatic provider selection:
| Provider | Platform | Notes |
| -------- | -------------- | ----------------------------- |
| CPU | All | Default, no setup needed |
| CUDA | Linux, Windows | Requires CUDA toolkit + cuDNN |
| CoreML | macOS | Automatic on Apple Silicon |
| TensorRT | Linux | Requires TensorRT |
To override:
```python
config = ExtractionConfig(
layout=LayoutDetectionConfig(),
acceleration=AccelerationConfig(provider="cuda", device_id=0)
)
```
See [AccelerationConfig reference](/reference/configuration/#accelerationconfig) for details.
## Layout Classes
[Section titled “Layout Classes”](#layout-classes)
The `LayoutClass` taxonomy defines 18 classes. Each `LayoutRegion.class_name` is one of:
`caption`, `chart`, `footnote`, `formula`, `list_item`, `page_footer`, `page_header`, `picture`, `section_header`, `table`, `text`, `title`, `document_index`, `code`, `checkbox_selected`, `checkbox_unselected`, `form`, `key_value_region`.
See [`LayoutRegion`](/reference/types/) in the types reference for the full field shape.
## Accessing Layout Regions
[Section titled “Accessing Layout Regions”](#accessing-layout-regions)
When layout detection is enabled AND page extraction is enabled, each page in the result includes `layout_regions` — a list of detected regions with class, confidence score, bounding box, and area fraction. This enables programmatic filtering and analysis of specific layout elements.
* Python
```python
from xberg import ExtractInput, extract, ExtractionConfig, LayoutDetectionConfig, PageConfig
output = await extract(
ExtractInput(kind="uri", uri="document.pdf"),
config=ExtractionConfig(
layout=LayoutDetectionConfig(),
pages=PageConfig(extract_pages=True),
),
)
result = output.results[0]
for page in result.pages:
if page.layout_regions:
for region in page.layout_regions:
if region.class_name == "picture" and region.confidence > 0.9:
print(f"Page {page.page_number}: diagram detected "
f"(confidence={region.confidence:.2f}, "
f"area={region.area_fraction:.0%})")
```
* TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract({
kind: ExtractInputKind.Uri,
uri: "document.pdf",
}, {
layout: {},
pages: { extractPages: true },
});
const result = output.results[0];
for (const page of result.pages ?? []) {
if (page.layoutRegions) {
for (const region of page.layoutRegions) {
if (region.className === "picture" && region.confidence > 0.9) {
console.log(
`Page ${page.pageNumber}: diagram detected ` +
`(confidence=${region.confidence.toFixed(2)}, ` +
`area=${(region.areaFraction * 100).toFixed(0)}%)`
);
}
}
}
}
```
* Rust
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, LayoutDetectionConfig, PageConfig};
let config = ExtractionConfig {
layout: Some(LayoutDetectionConfig::default()),
pages: Some(PageConfig {
extract_pages: true,
..Default::default()
}),
..Default::default()
};
let output = extract(
ExtractInput::from_uri("document.pdf"),
&config,
).await?;
let result = &output.results[0];
for page in &result.pages {
if let Some(regions) = &page.layout_regions {
for region in regions {
if region.class_name == "picture" && region.confidence > 0.9 {
println!(
"Page {}: diagram detected (confidence={:.2}, area={:.0}%)",
page.page_number,
region.confidence,
region.area_fraction * 100.0
);
}
}
}
}
```
### Tips
[Section titled “Tips”](#tips)
* Use `confidence` to filter low-confidence detections — typically ≥ 0.8–0.9 for downstream operations
* Use `area_fraction` to distinguish between inline images and full-page diagrams (e.g., `area_fraction > 0.1` for significant figures)
* Regions are independent of page extraction — enable both to access both content and layout structure
* Available across all bindings (Python, TypeScript, Rust, Ruby, Java, Go, Elixir, C#, PHP)
## Acknowledgments
[Section titled “Acknowledgments”](#acknowledgments)
* **[Docling](https://github.com/DS4SD/docling)** — RT-DETR v2 model and layout classification approach
* **[TATR](https://github.com/microsoft/table-transformer)** — Table structure recognition with ONNX
* **[PaddleOCR](https://github.com/PaddlePaddle/PaddleOCR)** — SLANeXT table structure and PP-LCNet classifier models
## Related
[Section titled “Related”](#related)
* [Configuration Reference](/reference/configuration/#layoutdetectionconfig) — full field reference
* [Element-Based Output](/guides/output-formats/#element-based-output) — using layout-aware results
# LLM Integration
Xberg integrates with 165 LLM providers (including local inference engines) via [liter-llm](https://github.com/xberg-io/liter-llm) for three capabilities: VLM OCR, structured extraction, and provider-hosted embeddings.
Feature gate
Requires the `liter-llm` Cargo feature. Not included in the default feature set.
## VLM OCR
[Section titled “VLM OCR”](#vlm-ocr)
Use vision-language models as an OCR backend by rendering document pages as images and sending them to the VLM for text extraction.
### When to Use
[Section titled “When to Use”](#when-to-use)
* Low-quality scanned documents where traditional OCR struggles
* Handwritten text recognition
* Arabic, Farsi, and other scripts with poor Tesseract/PaddleOCR support
* Complex layouts where traditional OCR fails (mixed tables, forms, diagrams)
* When you need higher accuracy and can accept higher latency and API costs
### Configuration
[Section titled “Configuration”](#configuration)
* Python
Python
```python
import asyncio
from xberg import ExtractInput, extract, ExtractionConfig, OcrConfig, LlmConfig
async def main() -> None:
config = ExtractionConfig(
force_ocr=True,
ocr=OcrConfig(
backend="vlm",
vlm_config=LlmConfig(model="openai/gpt-4o-mini"),
),
)
result = await extract(ExtractInput(uri="scan.pdf"), config)
print(result.results[0].content)
asyncio.run(main())
```
* TypeScript
TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const config = {
forceOcr: true,
ocr: {
backend: "vlm",
vlmConfig: {
model: "openai/gpt-4o-mini",
},
},
};
const output = await extract({ kind: ExtractInputKind.Uri, uri: "scan.pdf" }, config);
console.log(output.results?.[0]?.content);
```
* Rust
Rust
```rust
use xberg::{extract, ExtractInput, ExtractionConfig, OcrConfig, LlmConfig};
let config = ExtractionConfig {
force_ocr: true,
ocr: Some(OcrConfig {
backend: "vlm".to_string(),
vlm_config: Some(LlmConfig {
model: "openai/gpt-4o-mini".to_string(),
..Default::default()
}),
..Default::default()
}),
..Default::default()
};
let result = extract(ExtractInput::from_uri("scan.pdf"), &config).await?;
```
* CLI
Terminal
```bash
xberg extract scan.pdf --force-ocr true \
--vlm-model openai/gpt-4o-mini
```
* TOML
xberg.toml
```toml
force_ocr = true
[ocr]
backend = "vlm"
[ocr.vlm_config]
model = "openai/gpt-4o-mini"
```
* Environment Variables
Terminal
```bash
export XBERG_VLM_OCR_MODEL=openai/gpt-4o-mini
export OPENAI_API_KEY=sk-...
```
### Custom VLM Prompt
[Section titled “Custom VLM Prompt”](#custom-vlm-prompt)
Override the default prompt template for VLM OCR:
Python
```python
from xberg import ExtractionConfig, OcrConfig, LlmConfig
config = ExtractionConfig(
force_ocr=True,
ocr=OcrConfig(
backend="vlm",
vlm_config=LlmConfig(model="openai/gpt-4o-mini"),
vlm_prompt="Extract all text from this document image. Preserve formatting.",
),
)
```
### Supported Providers
[Section titled “Supported Providers”](#supported-providers)
Any liter-llm vision-capable provider works as a VLM OCR backend:
| Provider | Example Model |
| ----------------- | -------------------------------------- |
| OpenAI | `openai/gpt-4o`, `openai/gpt-4o-mini` |
| Anthropic | `anthropic/claude-3-5-sonnet-20241022` |
| Google | `google/gemini-2.0-flash` |
| Groq | `groq/llama-3.2-90b-vision-preview` |
| Ollama (local) | `ollama/llama3.2-vision` |
| LM Studio (local) | `lmstudio/llava-1.5` |
| vLLM (local) | `vllm/llava-next` |
## Structured Extraction
[Section titled “Structured Extraction”](#structured-extraction)
Extract structured JSON data from documents by providing a schema; the document text is sent to an LLM for conforming extraction.
### Basic Usage
[Section titled “Basic Usage”](#basic-usage)
* Python
Tests structured extraction via liter-llm with JSON schema
Python
```python
import asyncio
from xberg import extract, ExtractInput
from xberg._xberg import ExtractionConfig
async def main() -> None:
input = ExtractInput.from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}")
config = ExtractionConfig.from_json("{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}")
result = await extract(input, config)
print(result.results[0].structured_output)
asyncio.run(main())
```
* TypeScript / Node.js
Tests structured extraction via liter-llm with JSON schema
TypeScript
```typescript
import { ExtractInput, ExtractInputKind, ExtractionConfig, extract } from "@xberg-io/xberg";
async function main() {
const input: ExtractInput = { kind: ExtractInputKind.Uri, uri: "https://example.com/pdf/fake_memo.pdf" };
const config: ExtractionConfig = { structuredExtraction: { llm: { model: "openai/gpt-4o" }, schema: { properties: { date: { type: "string" }, summary: { type: "string" }, title: { type: "string" } }, required: ["title"], type: "object" }, schemaName: "memo_data", strict: true } };
const result = await extract(input, config);
console.log(result.results?.[0]?.structuredOutput);
}
void main();
```
* WebAssembly
Tests structured extraction via liter-llm with JSON schema
WebAssembly
```typescript
import { WasmExtractInput, WasmExtractInputKind, extract } from "@xberg-io/xberg-wasm";
async function main() {
const input: WasmExtractInput = (() => { const _u0 = WasmExtractInput.default(); _u0.kind = WasmExtractInputKind.Uri; _u0.uri = "https://example.com/pdf/fake_memo.pdf"; return _u0; })();
const result = await extract(input, { structuredExtraction: { llm: { model: "openai/gpt-4o" }, schema: { properties: { date: { type: "string" }, summary: { type: "string" }, title: { type: "string" } }, required: ["title"], type: "object" }, schemaName: "memo_data", strict: true } });
console.log(result.results[0].structuredOutput);
}
void main();
```
* Rust
Tests structured extraction via liter-llm with JSON schema
Rust
```rust
use xberg::extract;
use xberg::ExtractInput;
#[tokio::main]
async fn main() {
let input_json: serde_json::Value = serde_json::from_str(r#"{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}"#).unwrap();
let input = serde_json::from_value::(input_json).unwrap();
let config_json: serde_json::Value = serde_json::from_str(r#"{"structured_extraction":{"llm":{"model":"openai/gpt-4o"},"schema":{"properties":{"date":{"type":"string"},"summary":{"type":"string"},"title":{"type":"string"}},"required":["title"],"type":"object"},"schema_name":"memo_data","strict":true}}"#).unwrap();
let config = serde_json::from_value(config_json).unwrap();
let result = extract(input, &config).await.expect("call failed");
println!("{:?}", result.results[0].structured_output);
}
```
* Go
Tests structured extraction via liter-llm with JSON schema
Go
```go
package main
import (
"encoding/json"
"fmt"
xberg "github.com/xberg-io/xberg/packages/go"
)
func ptr[T any](value T) *T { return &value }
func main() {
input := xberg.ExtractInput{
Kind: ptr(xberg.ExtractInputKindURI),
URI: ptr(`https://example.com/pdf/fake_memo.pdf`),
}
config := xberg.ExtractionConfig{
StructuredExtraction: &xberg.StructuredExtractionConfig{
Schema: json.RawMessage(`{"properties":{"date":{"type":"string"},"summary":{"type":"string"},"title":{"type":"string"}},"required":["title"],"type":"object"}`),
SchemaName: ptr(`memo_data`),
Strict: true,
Llm: &xberg.LlmConfig{
Model: `openai/gpt-4o`,
},
},
}
result, err := xberg.Extract(input, config)
if err != nil {
panic(err)
}
fmt.Printf("%+v\n", result.Results[0].StructuredOutput)
}
```
* Java
Tests structured extraction via liter-llm with JSON schema
Java
```java
import io.xberg.*;
public final class Example {
public static void main(String[] args) throws Exception {
var inputJson = "{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}";
var input = JsonUtil.fromJson(inputJson, ExtractInput.class);
var configJson = "{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}";
var config = JsonUtil.fromJson(configJson, ExtractionConfig.class);
var result = Xberg.extract(input, config);
System.out.println(result.results().get(0).structuredOutput());
}
}
```
* Kotlin (Android)
Tests structured extraction via liter-llm with JSON schema
Kotlin (Android)
```kotlin
import io.xberg.*
import com.fasterxml.jackson.module.kotlin.jacksonObjectMapper
fun main() = kotlinx.coroutines.runBlocking {
val mapper = jacksonObjectMapper().setPropertyNamingStrategy(com.fasterxml.jackson.databind.PropertyNamingStrategies.SNAKE_CASE)
val input = mapper.readValue("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", ExtractInput::class.java)
val config = mapper.readValue("{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true},\"url\":{\"crawl\":{\"ssrf\":{}}}}", ExtractionConfig::class.java)
val result = Xberg.extract(input, config)
println(result.results.first().structuredOutput)
}
```
* C#
Tests structured extraction via liter-llm with JSON schema
C#
```csharp
using System;
using System.Text.Json;
using Xberg;
var ConfigOptions = new JsonSerializerOptions { PropertyNameCaseInsensitive = true };
var result = await XbergConverter.ExtractAsync(new ExtractInput { Kind = JsonSerializer.Deserialize("\"uri\"", ConfigOptions)!, Uri = "https://example.com/pdf/fake_memo.pdf" }, new ExtractionConfig { StructuredExtraction = new StructuredExtractionConfig { Llm = new LlmConfig { Model = "openai/gpt-4o" }, Schema = JsonSerializer.Deserialize("{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"}", ConfigOptions)!, SchemaName = "memo_data", Strict = true } });
Console.WriteLine(result.Results[0].StructuredOutput);
```
* Swift
Tests structured extraction via liter-llm with JSON schema
Swift
```swift
import Xberg
let result = try await Xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}")
debugPrint(result.results()[0].structuredOutput() as Any)
```
* Ruby
Tests structured extraction via liter-llm with JSON schema
Ruby
```ruby
require "xberg"
result = Xberg.extract(Xberg::ExtractInput.new(kind: 'uri', uri: 'https://example.com/pdf/fake_memo.pdf'), { 'structured_extraction' => { 'llm' => { 'model' => 'openai/gpt-4o' }, 'schema' => { 'properties' => { 'date' => { 'type' => 'string' }, 'summary' => { 'type' => 'string' }, 'title' => { 'type' => 'string' } }, 'required' => ['title'], 'type' => 'object' }, 'schema_name' => 'memo_data', 'strict' => true } })
puts result.results[0].structured_output.inspect
```
* PHP
Tests structured extraction via liter-llm with JSON schema
PHP
```php
"uri", "uri" => "https://example.com/pdf/fake_memo.pdf"]));
$result = Xberg::extract($input, ["structured_extraction" => ["llm" => ["model" => "openai/gpt-4o"], "schema" => ["properties" => ["date" => ["type" => "string"], "summary" => ["type" => "string"], "title" => ["type" => "string"]], "required" => ["title"], "type" => "object"], "schema_name" => "memo_data", "strict" => true]]);
var_dump($result->getResults()[0]->getStructuredOutput());
```
* Elixir
Tests structured extraction via liter-llm with JSON schema
Elixir
```elixir
input_value = %Xberg.ExtractInput{kind: "uri", uri: "https://example.com/pdf/fake_memo.pdf"}
result = Xberg.extract_async(input_value, "{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}")
IO.inspect(Enum.at(result.results, 0).structured_output)
```
* Dart
Tests structured extraction via liter-llm with JSON schema
Dart
```dart
import 'dart:io';
import 'package:xberg/xberg.dart';
import 'package:xberg/src/xberg_bridge_generated/frb_generated.dart' show RustLib;
Future main() async {
await RustLib.init();
try {
final input = await createExtractInputFromJson(json: '{"kind":"uri","uri":"https://example.com/pdf/fake_memo.pdf"}');
final config = await createExtractionConfigFromJson(json: '{"structured_extraction":{"llm":{"model":"openai/gpt-4o"},"schema":{"properties":{"date":{"type":"string"},"summary":{"type":"string"},"title":{"type":"string"}},"required":["title"],"type":"object"},"schema_name":"memo_data","strict":true}}');
final result = await XbergBridge.extract(input, config: config);
stdout.writeln(result.results[0].structuredOutput);
} finally {
RustLib.dispose();
}
}
```
* Zig
Tests structured extraction via liter-llm with JSON schema
Zig
```zig
const std = @import("std");
const xberg = @import("xberg");
pub fn main() !void {
const _result_json = try xberg.extract("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}", "{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}");
defer std.heap.c_allocator.free(_result_json);
std.debug.print("{s}\n", .{_result_json});
}
```
* C
Tests structured extraction via liter-llm with JSON schema
C
```c
#include
#include
#include
#include
#include
#include "xberg.h"
int main(void) {
XBERGAlefHandle input_handle = xberg_extract_input_from_json("{\"kind\":\"uri\",\"uri\":\"https://example.com/pdf/fake_memo.pdf\"}");
XBERGAlefHandle config_handle = xberg_extraction_config_from_json("{\"structured_extraction\":{\"llm\":{\"model\":\"openai/gpt-4o\"},\"schema\":{\"properties\":{\"date\":{\"type\":\"string\"},\"summary\":{\"type\":\"string\"},\"title\":{\"type\":\"string\"}},\"required\":[\"title\"],\"type\":\"object\"},\"schema_name\":\"memo_data\",\"strict\":true}}");
XBERGAlefHandle result = xberg_extract(input_handle, config_handle);
xberg_extract_input_free(input_handle);
xberg_extraction_config_free(config_handle);
xberg_extraction_result_free(result);
return EXIT_SUCCESS;
}
```
For CLI and configuration-file usage:
* CLI
Terminal
```bash
xberg extract paper.pdf --config structured-extraction.toml --format json
```
* TOML
xberg.toml
```toml
[structured_extraction]
schema_name = "paper_metadata"
strict = true
[structured_extraction.schema]
type = "object"
[structured_extraction.schema.properties.title]
type = "string"
[structured_extraction.schema.properties.date]
type = "string"
[structured_extraction.llm]
model = "openai/gpt-4o-mini"
```
### Custom Prompts (Jinja2)
[Section titled “Custom Prompts (Jinja2)”](#custom-prompts-jinja2)
Override the default extraction prompt with a Jinja2 template:
Python
```python
from xberg import ExtractionConfig, StructuredExtractionConfig, LlmConfig
config = ExtractionConfig(
structured_extraction=StructuredExtractionConfig(
schema={"type": "object", "properties": {"title": {"type": "string"}}},
llm=LlmConfig(model="openai/gpt-4o-mini"),
prompt=(
"Analyze this document and extract key metadata.\n\n"
"Document:\n{{ content }}\n\n"
"Schema: {{ schema }}"
),
),
)
```
Available template variables:
| Variable | Description |
| -------------------------- | ----------------------------------------- |
| `{{ content }}` | The extracted document text |
| `{{ schema }}` | The JSON schema as a formatted string |
| `{{ schema_name }}` | The schema name (default: `"extraction"`) |
| `{{ schema_description }}` | The schema description (may be empty) |
### Cross-Provider Compatibility
[Section titled “Cross-Provider Compatibility”](#cross-provider-compatibility)
Structured extraction handles provider differences automatically:
* **OpenAI**: Full strict mode with `additionalProperties` enforcement
* **Anthropic/Gemini**: `additionalProperties` automatically stripped (not supported by these providers)
* **All providers**: Markdown code fence wrapping in responses is automatically handled
### Strict Mode
[Section titled “Strict Mode”](#strict-mode)
When `strict=True`, the LLM is instructed to produce output that exactly matches the schema. This enables OpenAI’s structured output mode and adds validation on the response.
## VLM Embeddings
[Section titled “VLM Embeddings”](#vlm-embeddings)
Use provider-hosted embedding models when you need to match your vector database model or local ONNX models are unavailable.
### Configuration
[Section titled “Configuration”](#configuration-1)
* Python
Python
```python
# NOTE: The Python binding has no standalone embed() entry point — only
# embedding-backend registration (register_embedding_backend,
# list_embedding_backends, unregister_embedding_backend) and the EmbeddingConfig
# type are exposed. The `embed` name in the type stubs is a METHOD on the
# EmbeddingBackend protocol you implement, not a module-level function, so
# `from xberg import embed` fails at import time. VLM/LLM embeddings are produced
# per chunk during extraction by attaching this config to
# ExtractionConfig.chunking — see the Rust tab for the standalone dispatcher.
from xberg import EmbeddingConfig, EmbeddingModelType, LlmConfig
config = EmbeddingConfig(
model=EmbeddingModelType.llm(
LlmConfig(model="openai/text-embedding-3-small")
),
normalize=True,
)
```
* TypeScript
TypeScript
```typescript
// NOTE: The Node/TypeScript binding has no standalone embed()/embedSync() entry
// point — only embedding-backend registration (registerEmbeddingBackend,
// listEmbeddingBackends, unregisterEmbeddingBackend) and the EmbeddingConfig type
// are exposed. VLM/LLM embeddings are available through EmbeddingConfig attached to
// ExtractionConfig.chunking, produced per chunk during extraction — see the Rust
// tab below for the standalone dispatcher this configures.
import type { EmbeddingConfig } from '@xberg-io/xberg';
const config: EmbeddingConfig = {
model: {
modelType: 'llm',
value: 'openai/text-embedding-3-small',
},
normalize: true,
};
```
* Rust
Rust
```rust
use xberg::{embed_texts, EmbeddingConfig, EmbeddingModelType, LlmConfig};
let config = EmbeddingConfig {
model: EmbeddingModelType::Llm {
llm: LlmConfig {
model: "openai/text-embedding-3-small".to_string(),
..Default::default()
},
},
normalize: true,
..Default::default()
};
let embeddings = embed_texts(vec!["Hello world".to_string()], &config)?;
```
* CLI
Terminal
```bash
xberg embed \
--provider llm \
--model openai/text-embedding-3-small \
--text "Hello world"
```
### Available Models
[Section titled “Available Models”](#available-models)
| Model | Dimensions | Provider |
| ---------------------------------------- | ---------- | -------- |
| `openai/text-embedding-3-small` | 1536 | OpenAI |
| `openai/text-embedding-3-large` | 3072 | OpenAI |
| `mistral/mistral-embed` | 1024 | Mistral |
| Any liter-llm embedding-capable provider | Varies | Various |
## Local LLM Support
[Section titled “Local LLM Support”](#local-llm-support)
Run local LLM inference engines via [liter-llm](https://github.com/xberg-io/liter-llm)’s provider routing; point to your local server without needing an API key.
### Supported Local Engines
[Section titled “Supported Local Engines”](#supported-local-engines)
| Engine | Prefix | Default URL | Install |
| ------------------------------------------------------ | ------------ | --------------------------- | --------------------- |
| [Ollama](https://ollama.com) | `ollama/` | `http://localhost:11434/v1` | `brew install ollama` |
| [LM Studio](https://lmstudio.ai) | `lmstudio/` | `http://localhost:1234/v1` | Desktop app |
| [vLLM](https://vllm.ai) | `vllm/` | `http://localhost:8000/v1` | `pip install vllm` |
| [llama.cpp](https://github.com/ggerganov/llama.cpp) | `llamacpp/` | `http://localhost:8080/v1` | Build from source |
| [LocalAI](https://localai.io) | `localai/` | `http://localhost:8080/v1` | Docker |
| [llamafile](https://github.com/Mozilla-Ocho/llamafile) | `llamafile/` | `http://localhost:8080/v1` | Single binary |
### Example: Ollama
[Section titled “Example: Ollama”](#example-ollama)
* CLI
```bash
# Start Ollama and pull a model
ollama pull llama3.2-vision
# Use it for VLM OCR (no API key needed)
xberg extract scan.pdf --force-ocr true \
--vlm-model ollama/llama3.2-vision
# Use it for structured extraction
xberg extract doc.pdf --config structured-extraction.toml --format json
# Use it for embeddings
xberg embed --provider llm \
--model ollama/all-minilm \
--text "Hello world"
```
* Python
```python
from xberg import ExtractInput, ExtractionConfig, LlmConfig, StructuredExtractionConfig, extract
config = ExtractionConfig(
structured_extraction=StructuredExtractionConfig(
schema={"type": "object", "properties": {"title": {"type": "string"}}},
llm=LlmConfig(model="ollama/llama3.2"), # No api_key needed
),
)
result = await extract(ExtractInput.from_uri("doc.pdf"), config)
```
* TOML Config
```toml
[structured_extraction.llm]
model = "ollama/llama3.2"
# No api_key needed for local providers
```
Custom Base URL
If your local server runs on a non-default port, use `base_url`:
```python
LlmConfig(model="ollama/llama3.2", base_url="http://localhost:11435/v1")
```
## LLM Usage Tracking
[Section titled “LLM Usage Tracking”](#llm-usage-tracking)
Every LLM call made during extraction is tracked in the `llm_usage` field of `ExtractedDocument`. Each entry records the model used, token counts, estimated cost, and why the model stopped generating.
* Python
```python
from xberg import ExtractInput, extract
output = await extract(ExtractInput(kind="uri", uri="document.pdf"), config)
result = output.results[0]
if result.get("llm_usage"):
for usage in result["llm_usage"]:
print(f"{usage['source']}: {usage['input_tokens']} in, {usage['output_tokens']} out, ${usage['estimated_cost']:.4f}")
```
* TypeScript
```typescript
import { ExtractInputKind, extract } from "@xberg-io/xberg";
const output = await extract(
{ kind: ExtractInputKind.Uri, uri: "document.pdf" },
config,
);
const result = output.results[0];
for (const usage of result.llmUsage ?? []) {
console.log(`${usage.source}: ${usage.inputTokens} in, ${usage.outputTokens} out, $${usage.estimatedCost?.toFixed(4)}`);
}
```
* Rust
```rust
use xberg::{extract, ExtractInput};
let output = extract(ExtractInput::from_uri("document.pdf"), &config).await?;
let result = &output.results[0];
if let Some(usages) = &result.llm_usage {
for usage in usages {
println!("{}: {} in, {} out", usage.source, usage.input_tokens.unwrap_or(0), usage.output_tokens.unwrap_or(0));
}
}
```
The `source` field indicates which pipeline stage triggered the call: `"vlm_ocr"`, `"structured_extraction"`, or `"embeddings"`.
## API Key Configuration
[Section titled “API Key Configuration”](#api-key-configuration)
This guide is the canonical reference for LLM API-key precedence.
When Xberg builds an LLM client, the key is resolved in this order (highest priority first):
1. `api_key` field on the feature’s `LlmConfig` (VLM OCR `vlm_config`, `structured_extraction.llm`, or the embedding `LlmConfig`). If set, it is used verbatim.
2. Provider standard env var (`OPENAI_API_KEY`, `ANTHROPIC_API_KEY`, `GOOGLE_API_KEY`, etc.), resolved by liter-llm when `api_key` is unset.
The `XBERG_LLM_API_KEY` env var is not a general per-provider fallback. It is read only during CLI/server config loading and populates `structured_extraction.llm.api_key`. Because it fills the `api_key` field, it overrides a config-file value and takes precedence over the provider standard env var for structured extraction. The same env var (along with `XBERG_LLM_BASE_URL`) is also forwarded onto `ocr.vlm_config.api_key` / `ocr.vlm_config.base_url` when a VLM OCR backend is already configured (issue #1339) — it never enables the VLM path on its own. Embeddings have no Xberg-specific key env var; set `api_key` directly on the embedding `LlmConfig` or rely on the provider standard env var.
Local providers skip API key lookup
Local inference engines (Ollama, LM Studio, vLLM, llama.cpp, LocalAI, llamafile) do not require an API key. If you use a local provider prefix (for example, `ollama/`), the API key fields are ignored.
Python
```python
from xberg import LlmConfig
# Explicit API key
config = LlmConfig(model="openai/gpt-4o", api_key="sk-...")
# Custom base URL (e.g., Azure OpenAI, local proxy)
config = LlmConfig(
model="openai/gpt-4o",
base_url="https://my-proxy.example.com/v1",
)
```
## LlmConfig Reference
[Section titled “LlmConfig Reference”](#llmconfig-reference)
| Field | Type | Default | Description |
| ------------------- | ---------------------------- | ---------- | ----------------------------------------------------------------------- |
| `model` | `str` | *required* | Provider/model in liter-llm format (for example, `"openai/gpt-4o"`) |
| `api_key` | `str \| None` | `None` | API key (falls back to env vars) |
| `base_url` | `str \| None` | `None` | Custom endpoint URL |
| `timeout_secs` | `int \| None` | `60` | Request timeout in seconds (300s default for VLM OCR) |
| `max_retries` | `int \| None` | `3` | Maximum retry attempts |
| `temperature` | `float \| None` | `None` | Sampling temperature |
| `max_tokens` | `int \| None` | `None` | Maximum tokens to generate |
| `load_env` | `bool \| None` | `None` | Whether liter-llm loads provider credentials from environment vars |
| `headers` | `dict[str, str] \| None` | `None` | Extra HTTP headers sent with every request |
| `providers` | `list[LlmProviderConfig]` | `None` | Custom OpenAI-compatible providers, routed by model prefix — see below |
| `cache` | `LlmCacheConfig \| None` | `None` | Response cache settings — requires liter-llm’s `tower` feature |
| `budget` | `LlmBudgetConfig \| None` | `None` | Spend limits and enforcement — requires liter-llm’s `tower` feature |
| `rate_limit` | `LlmRateLimitConfig \| None` | `None` | Requests/tokens per minute — requires liter-llm’s `tower` feature |
| `cost_tracking` | `bool \| None` | `None` | Per-request cost tracking — requires liter-llm’s `tower` feature |
| `tracing` | `bool \| None` | `None` | OpenTelemetry-compatible spans — requires liter-llm’s `tower` feature |
| `cooldown_secs` | `int \| None` | `None` | Cooldown after transient errors — requires liter-llm’s `tower` feature |
| `health_check_secs` | `int \| None` | `None` | Background health check interval — requires liter-llm’s `tower` feature |
| `bedrock` | `BedrockConfig \| None` | `None` | AWS region/credentials for `bedrock/`-prefixed models |
Full field-by-field descriptions, including `LlmProviderConfig`, `LlmCacheConfig`, `LlmBudgetConfig`, `LlmRateLimitConfig`, and `BedrockConfig`, are in the [Configuration Reference](/reference/configuration/#llmconfig).
### Fields That Require liter-llm’s `tower` Feature
[Section titled “Fields That Require liter-llm’s tower Feature”](#fields-that-require-liter-llms-tower-feature)
`cache`, `budget`, `rate_limit`, `cost_tracking`, `tracing`, `cooldown_secs`, and `health_check_secs` are passed straight through to liter-llm’s `client::LlmConfig`. They only take effect when liter-llm is compiled with its `tower` feature. Without it, Xberg accepts and round-trips the values (TOML load, JSON serialization, every language binding) but liter-llm ignores them — no error, no warning.
xberg.toml
```toml
[structured_extraction.llm]
model = "openai/gpt-4o"
cost_tracking = true
tracing = true
cooldown_secs = 30
health_check_secs = 60
[structured_extraction.llm.cache]
max_entries = 512
ttl_seconds = 600
backend = "memory"
[structured_extraction.llm.budget]
global_limit = 100.0
enforcement = "hard"
[structured_extraction.llm.budget.model_limits]
"openai/gpt-4o" = 25.0
[structured_extraction.llm.rate_limit]
rpm = 60
tpm = 100000
window_seconds = 60
```
### Custom Providers
[Section titled “Custom Providers”](#custom-providers)
`LlmConfig.providers` registers custom OpenAI-compatible endpoints and routes models to them by prefix. Every entry is registered with liter-llm when Xberg builds a client, so any model whose name starts with one of the declared `model_prefixes` is sent to that provider’s `base_url`.
xberg.toml
```toml
[structured_extraction.llm]
model = "my-provider/llama-3.1-70b"
api_key = "..."
[[structured_extraction.llm.providers]]
name = "my-provider"
base_url = "https://my-llm.example.com/v1"
auth_header = "X-Api-Key"
model_prefixes = ["my-provider/"]
```
`auth_header` is the header name carrying the key. Leave it unset (or set it to `Authorization`) for `Authorization: Bearer `; any other name sends the raw key under that header, with no scheme prefix.
Registration failures surface as a validation error rather than being ignored. The liter-llm registry is process-global and keyed by `name`, so the most recently built client wins for a given provider name — use distinct names across every `LlmConfig` in one process.
For a single custom or self-hosted endpoint that needs no prefix routing, set `base_url` on `LlmConfig` directly instead (see [Custom Base URL](#local-llm-support) above).
### Credentials Are Redacted in Debug, Not in Serialized Output
[Section titled “Credentials Are Redacted in Debug, Not in Serialized Output”](#credentials-are-redacted-in-debug-not-in-serialized-output)
`api_key` and the Bedrock credential fields (`access_key_id`, `secret_access_key`, `session_token`) never appear in `Debug` output or logs. They **do** appear in serialized TOML/JSON — that’s how a config file persists them across runs. This is by design, not a defect. If you write a config file containing these fields, handle it like any other secrets file: restrictive permissions, never world-readable, never committed.
## REST API And MCP
[Section titled “REST API And MCP”](#rest-api-and-mcp)
Use the unified `/extract` endpoint or `extract` MCP tool with a `structured_extraction` config object. LLM-hosted embeddings are Rust-only for now and can be wired into extraction through `EmbeddingConfig`.
## Related
[Section titled “Related”](#related)
* [OCR](/guides/ocr/) — OCR backends including VLM OCR
* [Configuration Reference](/guides/configuration/) — full field reference for all config types
* [Chunking](/guides/chunking/) — split text for RAG
* [Language Detection](/guides/language-detection/) — multilingual document analysis
* [Embeddings](/guides/embeddings/) — semantic vectors for search
* [API Server](/guides/api-server/) — REST API endpoints
# MCP Integration
Xberg speaks [Model Context Protocol](https://modelcontextprotocol.io/). That means any AI agent — Claude, Cursor, a custom LangChain pipeline — can extract documents, generate embeddings, and manage caches through a standard tool interface without writing extraction code.
Prebuilt binaries (Homebrew, install.sh, Docker) include the MCP server. To get started:
Terminal
```bash
xberg mcp
```
If building from source:
Terminal
```bash
cargo install xberg-cli --features mcp
xberg mcp
```
That’s it. You now have an MCP server running over stdio, ready for any compatible client.
## Bundled with the coding-agent plugin
[Section titled “Bundled with the coding-agent plugin”](#bundled-with-the-coding-agent-plugin)
If you install the [Xberg coding-agent plugin](/guides/ai-coding-assistants/), you already have this MCP server — no separate install. The plugin ships an `.mcp.json` that registers a server named `xberg`:
plugin .mcp.json
```json
{
"mcpServers": {
"xberg": {
"command": "./scripts/mcp-launch.sh",
"args": ["mcp", "--transport", "stdio"]
}
}
}
```
`mcp-launch.sh` resolves the CLI at runtime — a cached or on-`PATH` `xberg` first, then `npx -y @xberg-io/xberg-cli@latest`, `uvx --from xberg-cli xberg`, Homebrew, or a prebuilt release archive — so the server runs with no manual install. Override the strategy with `XBERG_LAUNCHER` (`auto` default, or `npx`, `uvx`, `brew`, `download`).
To wire the same launcher into a client yourself without the CLI on `PATH`, point at either package directly:
MCP client config (npx)
```json
{
"mcpServers": {
"xberg": {
"command": "npx",
"args": ["-y", "@xberg-io/xberg-cli@latest", "mcp", "--transport", "stdio"]
}
}
}
```
MCP client config (uvx)
```json
{
"mcpServers": {
"xberg": {
"command": "uvx",
"args": ["--from", "xberg-cli", "xberg", "mcp", "--transport", "stdio"]
}
}
}
```
***
## How It Works
[Section titled “How It Works”](#how-it-works)
The MCP server wraps Xberg’s extraction engine behind standard tools, running as a child process over stdin/stdout with JSON-RPC messages — no HTTP ports or configuration needed.
```mermaid
flowchart LR
A["AI Agent\n(Claude, Cursor, etc.)"] -->|"JSON-RPC\nover stdio"| B["xberg mcp"]
B --> C["Extraction Engine"]
B --> D["Embedding Engine"]
B --> E["Cache Layer"]
```
***
## Server Modes
[Section titled “Server Modes”](#server-modes)
### Stdio (Default)
[Section titled “Stdio (Default)”](#stdio-default)
The standard mode for local AI tools. The agent spawns `xberg mcp` as a subprocess and communicates over pipes.
Terminal
```bash
xberg mcp
xberg mcp --config xberg.toml
```
This is what Claude Desktop, Cursor, and most MCP clients expect.
### HTTP Transport
[Section titled “HTTP Transport”](#http-transport)
Feature flag: `mcp-http`
HTTP transport requires the `mcp-http` feature flag at build time.
For remote deployments or multi-client setups where stdio doesn’t work — shared servers, team environments, cloud-hosted agents — HTTP transport exposes the same tool interface over the network:
Terminal
```bash
xberg mcp --transport http --host 127.0.0.1 --port 8001
```
Configure in Claude Desktop or Cursor:
```json
{
"mcpServers": {
"xberg": {
"command": "xberg",
"args": ["mcp", "--transport", "http", "--host", "127.0.0.1", "--port", "8001"]
}
}
}
```
#### Allowed hosts behind a reverse proxy
[Section titled “Allowed hosts behind a reverse proxy”](#allowed-hosts-behind-a-reverse-proxy)
The HTTP transport validates the inbound `Host` header and, by default, only accepts loopback hosts (`localhost`, `127.0.0.1`, `::1`) to guard against DNS-rebinding attacks. If Xberg sits behind a reverse proxy or ingress that forwards requests using a different hostname (e.g. `xberg.internal.example.com`), add that hostname to the allowlist. Supplied hosts *extend* the loopback default — they never replace it, so local health checks keep working.
Precedence (highest to lowest):
1. `--allowed-host ` CLI flag (repeatable)
2. `XBERG_MCP_ALLOWED_HOSTS` environment variable (comma-separated)
3. `[mcp] allowed_hosts` key in the config file passed via `--config` (not applied to an auto-discovered config file)
4. Default: loopback only
Terminal
```bash
xberg mcp --transport http --host 0.0.0.0 --port 8001 \
--allowed-host xberg.internal.example.com --allowed-host xberg.internal.example.com:8001
```
Terminal (env var)
```bash
export XBERG_MCP_ALLOWED_HOSTS="xberg.internal.example.com,xberg.internal.example.com:8001"
xberg mcp --transport http --host 0.0.0.0 --port 8001
```
xberg.toml
```toml
[mcp]
allowed_hosts = ["xberg.internal.example.com", "xberg.internal.example.com:8001"]
```
***
## Tools
[Section titled “Tools”](#tools)
Xberg exposes MCP tools for extraction, cache operations, and metadata. All extraction tools accept an optional `config` object to override defaults:
**Extraction:** `extract`, `extract_batch`, `detect_mime_type` **Cache:** `cache_stats`, `cache_clear`, `cache_manifest`, `cache_warm` **Metadata:** `list_formats`, `get_version`
`extract` takes a unified `input` object — `{"kind": "uri", "uri": "